[
{
"id": 155,
"name": "Insight Data Science",
"slug": "insight-data-science",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/e2887e0f0ad9804a54eb3d6ed6cb6b819dfed068.png",
"website": "http://insightdatascience.com",
"all_locations": "San Francisco, CA, USA; Palo Alto, CA, USA",
"long_description": "The Insight Data Science Fellows Program is an intensive seven week post-doctoral training fellowship bridging the gap to new careers in Data Science, Data Engineering, Health Data, and AI in Silicon Valley, New York City, Boston, Seattle and across the US with our Remote program. Insight is a Palo Alto based education startup, funded by Y Combinator and SV Angel, with 1000 alumni at hundreds of companies including Facebook, Netflix, LinkedIn, Twitter, The New York Times, Apple, Airbnb, Microsoft, Capital One, NBC, Memorial Sloan Kettering, and many others.",
"one_liner": "Turning PhDs & engineers into data scientists & data engineers",
"team_size": 11,
"industry": "Education",
"subindustry": "Education",
"launched_at": 1326789868,
"tags": [
"Data Science",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2011",
"status": "Inactive",
"industries": [
"Education"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/insight-data-science",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2011/insight-data-science.json",
"year_founded": null,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/insight-data-science/",
"x_url": "https://twitter.com/InsightFellows",
"fb_url": "https://www.facebook.com/InsightDataScience/",
"cb_url": "https://www.crunchbase.com/organization/insight-data-science",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/e2887e0f0ad9804a54eb3d6ed6cb6b819dfed068.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 5803,
"full_name": "Jake Klamka",
"title": "Founder/CEO",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jakeklamka",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/75887246e48a0c08ab7f6ddb10cfeaebc3c9ebaa.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 291,
"name": "BackType",
"slug": "backtype",
"former_names": [
"Backtype"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/0ec00079f2609a11308b0e89a7e2ed64081516db.png",
"website": "http://backtype.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "",
"one_liner": "BackType was an analytics company acquired by Twitter in 2011",
"team_size": 0,
"industry": "B2B",
"subindustry": "B2B -> Marketing",
"launched_at": 1326791016,
"tags": [
"SaaS",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2008",
"status": "Acquired",
"industries": [
"B2B",
"Marketing"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/backtype",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2008/backtype.json",
"year_founded": 2008,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/backtype",
"x_url": "https://twitter.com/backtype",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/backtype",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/0ec00079f2609a11308b0e89a7e2ed64081516db.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 17628,
"full_name": "Christopher Golda",
"title": "Founder",
"founder_bio": "General Partner at Y Combinator. Previously, investor in Benchling, Coinbase, Stoke Space, Supabase, 100+ more. Founded BackType (S08, sold to Twitter). Launched Twitter Ads and ran Ads Center at Twitter until 2014.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/christophergolda/",
"x_url": "https://x.com/golda",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/03d7e18a25be1b9001048495bc939b6a91eaacf7.jpg"
},
{
"user_id": 17629,
"full_name": "Mike Montano",
"title": "Founder",
"founder_bio": "Investor in Benchling, Ollama, and dozens of YC cos. Partner at True Ventures. Former Head of Engineering at Twitter. Founded BackType, acquired by Twitter. YCS08",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/mikemontano",
"x_url": "https://twitter.com/michaelmontano",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/6992a2ba1ccfa22ce753102057d79bc3b967144e.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 473,
"name": "Scuba",
"slug": "interana",
"former_names": [
"Interana"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/75095731e25d34e505b54386e1fbac0016ef69ea.png",
"website": "https://www.scuba.io",
"all_locations": "",
"long_description": "Scuba is the fast and scalable event-based analytics solution to answer critical business questions about how customers behave and products are used. Interana allows users to analyze and explore the key business metrics that matter most in a data-driven world – such as growth, retention, conversion and engagement – in seconds, rather than the hours or days it often takes with existing solutions. Interana allows customers to discover and investigate these key insights easily through its visual and interactive interface, which makes data analysis a natural extension of everyone’s workflow.",
"one_liner": "Analytics for impatient people.",
"team_size": 51,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1354492621,
"tags": [
"Analytics",
"Big Data",
"Data Engineering",
"Data Visualization"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2013",
"status": "Acquired",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"Remote",
"Partly Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": [
{
"question": "What is your company going to make? Please describe your product and what it does or will do.",
"answer": "An analytics service with an easy to use web interface, able to answer large queries in seconds. Think of it as MS Excel for giant data, or a much faster hadoop for non-programmers. "
}
],
"question_answers": null,
"url": "https://www.ycombinator.com/companies/interana",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2013/interana.json",
"year_founded": 2013,
"city": null,
"country": null,
"linkedin_url": "https://www.linkedin.com/company/scubaanalytics/",
"x_url": "https://x.com/scuba_inc?s=21",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/interana",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/75095731e25d34e505b54386e1fbac0016ef69ea.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 55790,
"full_name": "Ann Johnson",
"title": "Founder/CEO",
"founder_bio": null,
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/annstimmlerjohnson",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/96f1b36a95e57b64bf8681c87c3d4371455212f5.jpg"
},
{
"user_id": 55789,
"full_name": "Bobby Johnson",
"title": "Founder/CTO",
"founder_bio": null,
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/bobby-johnson-2362201a6",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/5e694d0dcfaf80d818df840f3cc79bb837d1fb58.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 482,
"name": "Fivetran",
"slug": "fivetran",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/d6b5710a13038fe1daa1421a986e1f4a7839a65a.png",
"website": "http://fivetran.com",
"all_locations": "San Francisco, CA, USA; Oakland, CA, USA",
"long_description": "Fivetran automates data movement out of, into and across cloud data platforms. We automate the most time-consuming parts of the ELT process from extracts to schema drift handling to transformations, so data engineers can focus on higher-impact projects with total pipeline peace of mind. With 99.9% uptime and self-healing pipelines, Fivetran enables hundreds of leading brands across the globe, including Autodesk, Conagra Brands, JetBlue, Lionsgate, Morgan Stanley, and Ziff Davis, to accelerate data-driven decisions and drive business growth. Fivetran is headquartered in Oakland, California, with offices around the world. ",
"one_liner": "The leader in automated data movement",
"team_size": 1200,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1354492705,
"tags": [
"SaaS",
"B2B",
"Analytics",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": true,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2013",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/fivetran",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2013/fivetran.json",
"year_founded": 2012,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/fivetran/",
"x_url": "https://twitter.com/fivetran",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/fivetran",
"github_url": "https://github.com/fivetran",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/d6b5710a13038fe1daa1421a986e1f4a7839a65a.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/1a0a6c160addcde911628a76edddc4ee4907aefe.png",
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/ce551dc35f43a920a1c178d26717e4f8d680ba78.png"
],
"primary_partner": null,
"founders": [
{
"user_id": 55910,
"full_name": "Taylor Brown",
"title": "Founder/COO",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/taylorwcbrown",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/09daf1c815be78f9e0fb8b0fb8d6477895b8fbe3.jpg"
},
{
"user_id": 41378,
"full_name": "George Fraser",
"title": "Founder",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/george-fraser-a0219230",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/8f4e87039c444842f237f647d870ed322d56f5a8.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Fivetran launches a managed data lake service",
"url": "https://techcrunch.com/2024/06/04/fivetran-launches-a-managed-data-lake-service/",
"date": "Jun 04, 2024"
},
{
"title": "Monte Carlo embraces Fivetran, enables end-to-end observability for data pipelines | VentureBeat",
"url": "https://venturebeat.com/data-infrastructure/monte-carlo-embraces-fivetran-enables-end-to-end-observability-for-data-pipelines%EF%BF%BC/",
"date": "Apr 04, 2023"
},
{
"title": "Fivetran’s metadata API pushes data pipelines toward transparency | VentureBeat",
"url": "https://venturebeat.com/data-infrastructure/fivetrans-metadata-api-pushes-data-pipelines-towards-transparency/",
"date": "Sep 21, 2022"
},
{
"title": "The $5.6 Billion Internet Plumbers",
"url": "https://www.forbes.com/sites/kenrickcai/2022/08/08/the-56-billion-internet-plumbers/?sh=54beba235226",
"date": "Aug 08, 2022"
},
{
"title": "Fivetran Innovates Data Integration Tools Market",
"url": "https://www.forbes.com/sites/brucerogers/2022/01/11/fivetran-innovates-data-integration-tools-market/",
"date": "Jan 11, 2022"
}
],
"launches": []
},
{
"id": 488,
"name": "Etleap",
"slug": "etleap",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/07c9b19241da3d7897596f5f34b6c9baa7c7518e.png",
"website": "https://etleap.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "Etleap is an ETL solution for creating perfect data pipelines from day one. Unlike other enterprise solutions, Etleap doesn’t require extensive engineering work to set up, maintain, and scale. It automates most ETL setup and maintenance work, and simplifies the rest into 10-minute tasks that analysts can own.",
"one_liner": "Etleap is an ETL solution for creating perfect data pipelines. ",
"team_size": 11,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1354492752,
"tags": [
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2013",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/etleap",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2013/etleap.json",
"year_founded": null,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/etleap/",
"x_url": "",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/etleap",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/07c9b19241da3d7897596f5f34b6c9baa7c7518e.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 42820,
"full_name": "Christian Romming",
"title": "Founder/CEO",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/cromming",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/5266c153a37288482bc5f446d32855df66a66161.jpg"
}
],
"jobs": [
{
"id": 44751,
"title": "Software Engineer - Integrations South America (remote)",
"url": "https://www.ycombinator.com/companies/etleap/jobs/UQuf3oX-software-engineer-integrations-south-america-remote",
"location": "BR / Remote (BR)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Backend",
"salary_range": "$35K - $60K",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizenship/visa not required",
"skills": [
"Java"
]
},
{
"id": 65200,
"title": "DevOps Engineer Latin America (remote)",
"url": "https://www.ycombinator.com/companies/etleap/jobs/lrNVGB2-devops-engineer-latin-america-remote",
"location": "BR / AR / CL / PE / UY / CO / VE / EC / GY / BO / PY / Remote (BR; AR; CL; PE; UY; CO; VE; EC; GY; BO; PY)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Devops",
"salary_range": "$40K - $70K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizenship/visa not required",
"skills": [
"Amazon Web Services (AWS)",
"Python"
]
},
{
"id": 65587,
"title": "Account Executive",
"url": "https://www.ycombinator.com/companies/etleap/jobs/QwEj2EQ-account-executive",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Sales",
"role_type": null,
"salary_range": "$220K - $260K",
"equity_range": "",
"experience": "6+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 75532,
"title": "Senior Software Engineer - San Francisco (Onsite) ",
"url": "https://www.ycombinator.com/companies/etleap/jobs/opfyPGo-senior-software-engineer-san-francisco-onsite",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Backend",
"salary_range": "$130K - $220K",
"equity_range": "",
"experience": "3+ years",
"visa": "Will sponsor",
"skills": [
"Java",
"Distributed Systems",
"Software Architecture"
]
}
],
"news": [],
"launches": []
},
{
"id": 749,
"name": "Mezmo",
"slug": "mezmo",
"former_names": [
"PushMarket",
"LogDNA"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/f3a71ea034c7bfc9aef393b47b27829a3413f0b3.png",
"website": "https://www.mezmo.com/",
"all_locations": "San Francisco, CA, USA; Mountain View, CA, USA; Remote",
"long_description": "Mezmo, formerly LogDNA, is an observability platform to manage and take action on your data. It ingests, processes, and routes log data to fuel enterprise-level application development and delivery, security, and compliance use cases.\r\n\r\nMezmo was brought to life by three-time co-founders Chris Nguyen and Lee Liu and included in the Winter 2015 batch of Y Combinator. In 2018 the company partnered with tech giant, IBM, to become the sole logging provider for IBM Cloud.\r\n\r\nMezmo is on a mission to empower people who build solutions that shape the world. We’re doing this by delivering a platform that enables enterprises to get more value from their observability data in real time, regardless of source, destination, use case, or scale. We’re not the only ones working on this problem but we have a few things the others don’t.\r\n\r\nWe’re cloud-native and know how to make the most of modern technology like Kubernetes.\r\nWe have scaled a solution from zero to petabyte scale in a short amount of time, while supporting thousands of active users across multiple environments.\r\nWe are hungry for change and are surrounded by enterprises telling us they’re hungry, too.\r\nWe have a kick-ass group of people who are thinking about the problem analytically and are excited to change the observability world for the better.\r\nMezmo has helped some of the world’s most innovative companies transform how they manage their systems and applications. Still, we know that we can help them get more value from their observability data by providing more flexibility and control over how they use it. This will enable teams to spend less time switching between data silos so they can focus on shipping better, more resilient, and secure products.\r\n\r\nWe have momentum on our side. Last year we saw triple digit revenue growth and added 800 new customers to our roster. Recent accolades include being named to YC’s Top Companies, CRN’s 10 Hottest DevOps Startups, and EMA’s Top 3 Observability Platforms.\r\n",
"one_liner": "Observability platform to control all of your log data",
"team_size": 172,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1416218667,
"tags": [
"Developer Tools",
"DevSecOps",
"SaaS",
"Kubernetes",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2015",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/mezmo",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2015/mezmo.json",
"year_founded": 2015,
"city": "San Francisco",
"country": "US",
"linkedin_url": "",
"x_url": "https://twitter.com/mezmo",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/logdna",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/f3a71ea034c7bfc9aef393b47b27829a3413f0b3.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 64734,
"full_name": "Lee Liu",
"title": "Founder",
"founder_bio": "Co-founder at Minicart",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/leeliu",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b67b6b2dc43e9082bea3220a4154ced25456abdb.jpg"
},
{
"user_id": 64730,
"full_name": "Chris Nguyen",
"title": "Founder",
"founder_bio": "Co-founder at Minicart",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/christophernguyen",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/16eaca1cd282dee20753e6adebb5fe133973f7e8.jpg"
}
],
"jobs": [],
"news": [
{
"title": "LogDNA raises $50M to bring 'full power' of observability data to security | VentureBeat",
"url": "https://venturebeat.com/2021/12/06/logdna-raises-50m-to-bring-full-power-of-observability-data-to-security/",
"date": "Dec 06, 2021"
}
],
"launches": []
},
{
"id": 799,
"name": "Yhat",
"slug": "yhat",
"former_names": [],
"small_logo_thumb_url": "/company/thumb/missing.png",
"website": "https://www.yhat.com",
"all_locations": "New York City, NY, USA; New York, NY, USA; Remote",
"long_description": " Yhat (YC W15, pronounced y-hat) was an end-to-end data science platform. Acquired by Alteryx (NYSE:AYX)",
"one_liner": "End-to-end data science lifecycle management platform. ",
"team_size": 17,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1416222882,
"tags": [
"Machine Learning",
"Enterprise",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2015",
"status": "Acquired",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": true,
"app_answers": [
{
"question": "How long have each of you been working on this? How much of that has been full-time? Please explain.\n",
"answer": "30k for ScienceOps; 15k for ScienceBox; 15k for Other"
},
{
"question": "What is your company going to make? Please describe your product and what it does or will do.\n",
"answer": "Yhat makes tools and systems for enterprise data science teams. Like Adobe's creative suite for designers, we provide solutions to data scientists biggest problems. \r\n\r\nWe currently have 2 products:\r\n\r\n1) ScienceOps: A platform to convert data science routines into APIs reliably and fast\r\n2) ScienceBox: An analytics server for performing, managing, and automating your data analysis. Preloaded with hundreds of well-known packages, environment management system, workflow and job scheduling, and a UI to tie it together."
}
],
"question_answers": null,
"url": "https://www.ycombinator.com/companies/yhat",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2015/yhat.json",
"year_founded": 2013,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/yhat-inc-",
"x_url": "",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/yhat",
"github_url": null,
"logo_url": null,
"app_video_url": null,
"dday_video_url": "https://bookface-images.s3.us-west-2.amazonaws.com/video_event/10/1427154425833-xs1dvp40smunmi-0a6d218ddbe0167bb45fb27e2d9ff45a/c8f60844c7de1cf5a2914b8d70917c72.mp4?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=AKIAQC4NIECABPQ2AHNW%2F20261020%2Fus-west-2%2Fs3%2Faws4_request&X-Amz-Date=20261020T022629Z&X-Amz-Expires=3600&X-Amz-SignedHeaders=host&X-Amz-Signature=c62798023ce82766db2ac47c152bf43b61ff5212739becd854b8cef2430150da",
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/8dc65d5474866705a492e7e5500744436a313b82.png"
],
"primary_partner": null,
"founders": [
{
"user_id": 8719,
"full_name": "Austin Ogilvie",
"title": "Founder/CEO",
"founder_bio": "Founder @ Thoropass. Fmr CEO @ Yhat (W15) (acq by Alteryx NYSE:AYX)",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/austinogilvie",
"x_url": "https://twitter.com/austinogilvie",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ef33a74ed042791f448b28853b30f6cf89e5e428.jpg"
},
{
"user_id": 781,
"full_name": "Greg Lamp",
"title": "Founder",
"founder_bio": null,
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/glamp",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9ca6cefbe648cc6722b37449955d1801e9c815ce.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 952,
"name": "TetraScience",
"slug": "tetrascience",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/ddb32b2efdb22265a0c610b84a66c92b4e545b61.png",
"website": "https://www.tetrascience.com",
"all_locations": "Boston, MA, USA; Remote",
"long_description": "TetraScience provides the world’s first and only R&D Data Cloud, with a mission to transform life sciences R&D, accelerate discovery, and improve human life. Scientists at global pharma and biotech organizations rely on our innovative Tetra Data Platform for easy access to centralized, harmonized, and actionable scientific data to accelerate their digital lab transformation. With best-in-class SaaS performance, a team of industry innovators, and excellent product/market fit, Tetra is positioned to become an iconic life sciences software company.",
"one_liner": "The only R&D data cloud for life sciences",
"team_size": 100,
"industry": "Healthcare",
"subindustry": "Healthcare -> Healthcare IT",
"launched_at": 1430204716,
"tags": [
"SaaS",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2015",
"status": "Active",
"industries": [
"Healthcare",
"Healthcare IT"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/tetrascience",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2015/tetrascience.json",
"year_founded": null,
"city": "Boston",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/tetrascience/",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/tetrascience",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/ddb32b2efdb22265a0c610b84a66c92b4e545b61.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 87039,
"full_name": "Siping Wang",
"title": "Founder/CTO",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/pub/siping-wang/47/A32/205",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ebdf59e7914214d043c1e39d73552505336719ac.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 1051,
"name": "Gecko Robotics",
"slug": "gecko-robotics",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/eb7bd253bc194c1e1245a6c643b86e65d530a53f.png",
"website": "https://www.geckorobotics.com",
"all_locations": "Pittsburgh, PA, USA; Austin, TX, USA",
"long_description": "Gecko Robotics is the pioneer of AI + Robotics [AIR technology], transforming how the world builds, operates, and maintains its most critical infrastructure for a more reliable and sustainable future. Using fixed sensors and robots that climb, crawl, swim, and fly, we combine first-order data layers with the predictive power of AI into a single source of truth for the physical world. Cantilever™ is our operating platform, powered by AIR technology, that empowers teams to achieve operational excellence through actionable data for immediate and long-term planning.",
"one_liner": "AI + Robotics for the Built World",
"team_size": 230,
"industry": "Industrials",
"subindustry": "Industrials -> Manufacturing and Robotics",
"launched_at": 1447653915,
"tags": [
"Robotics",
"Energy",
"Big Data",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2016",
"status": "Active",
"industries": [
"Industrials",
"Manufacturing and Robotics"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": [
{
"question": "How did your company get started? (i.e., How did the founders meet? How did you come up with the idea? How did you decide to be a founder?)",
"answer": "Troy and Jake met in at Grove City College outside of Pittsburgh. They lived in the same dorm, played sports together and enjoyed frequent conversations about the world. After initially bootstrapping Gecko, Jake and Troy reconnected and saw the same vision of building a robotics company to solve real challenges in the built world."
},
{
"question": "How did you decide to apply to Y Combinator? What was your experience applying, going through the batch, and fundraising at demo day?",
"answer": "Jake was unfamiliar with YC before they applied. In the fall of 2016, Troy learned that Kevin Hale was scheduled to be in Pittsburgh promoting the next cohort. Jake and Troy met him and talked through the vision for how Gecko could scale. At the time Gecko was making money but wasn’t yet focused on raising money or the traction it would take to turn the company into a scalable business. Kevin, Jake and Troy talked through that path and Jake and Troy turned in their application almost immediately afterwards. Going through the batch was formative for helping Jake and Troy chart Gecko’s path forward. As the batch was starting they were weighing an acquisition offer but, thanks in large part to the advice they were getting at YC, they decided to reject the offer and build the company together."
},
{
"question": "How have you kept in touch with the YC community and continued to use YC resources & programs since the batch ended?",
"answer": "Yes. Mostly through interactions with Kevin Hale, Jared Friedman, Sam Altman and Jon Levy. "
},
{
"question": "What's the history of your company from getting started until the present day? What were the big inflection points?",
"answer": "Jake built the world’s first wall-climbing ultrasonic testing robot in 2012. Soon after we were making money but weren’t sure on the path to scale. Going though YC was a key inflection point that lead us to our model for scaling Gecko. The decision to turn down early acquisition attempts and investments in favor of building the company we wanted build to was another key inflection point. Gecko turned down offers right before demo day from investors in favor of walking. Fast forward to today and Gecko is closing deals with some of the biggest energy providers on the planet as well as global institutions like the U.S. Air Force and U.S. Navy."
},
{
"question": "What is the core problem you are solving? Why is this a big problem? What made you decide to work on it?",
"answer": "Jake visited a power plant while in college. The owner talked about how assets at the plant just fail and the plant shuts down regularly and that was seen as just the cost of doing business. That seemed wrong to Jake. It made him think about the importance of the built world and how much we rely on physical assets to provide power, water, safety and other critical services. Yet at the same time they are aging and starting to breakdown - Jake thought he had found a problem hiding in plain sight. Jake and Troy talked a lot about that in the early days of Gecko and committed the company on a path to deploy advanced robotics to solve this critical problem that no one else seemed to be working on."
},
{
"question": "What is your long-term vision? If you truly succeed, what will be different about the world?",
"answer": "The long-term vision for Gecko Robotics is to transform the world’s most important industries that have been left behind in the digitalization movement. Gecko aims to be one of the first truly impactful robotics companies and prove that the best way to build incredible hardware and software is around solving real world problems and creating impactful outcomes for customers. "
}
],
"url": "https://www.ycombinator.com/companies/gecko-robotics",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2016/gecko-robotics.json",
"year_founded": 2016,
"city": "Pittsburgh",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/geckorobotics/",
"x_url": "https://www.twitter.com/geckorobotics",
"fb_url": "https://www.facebook.com/geckorobotics",
"cb_url": "https://www.crunchbase.com/organization/gecko-robotics",
"github_url": "https://github.com/GeckoRobotics",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/eb7bd253bc194c1e1245a6c643b86e65d530a53f.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Jared Friedman",
"url": "https://www.ycombinator.com/people/jared-friedman"
},
"founders": [
{
"user_id": 111094,
"full_name": "Jake Loosararian",
"title": "Founder/CEO",
"founder_bio": "Co-Founder and CEO of Gecko Robotics\n",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/profile/preview?locale=en_US&trk=prof-0-sb-preview-primary-button",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/57090e5c44a679e435831ce506c281bf8a3b5d4b.jpg"
},
{
"user_id": 109506,
"full_name": "Troy Demmer",
"title": "Founder/COO",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/profile/view?id=AAIAAAVknjQBfe-5mD0s-nYSWNXnFY_7rEl6whA&trk=nav_responsive_tab_profile",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/2c82ea0566fb3fe9a95995dbf02762d1ce0a2e48.jpg"
}
],
"jobs": [
{
"id": 92020,
"title": "Software Engineer | Government",
"url": "https://www.ycombinator.com/companies/gecko-robotics/jobs/ze67ohK-software-engineer-government",
"location": "New York, NY, US / Boston, MA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$180K - $235K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"Amazon Web Services (AWS)",
"Microsoft Azure",
"Google Cloud",
"Python",
"React",
"TypeScript",
"Design systems"
]
}
],
"news": [
{
"title": "US Navy Awards Contract to Gecko Robotics to Inspect Ships - Bloomberg",
"url": "https://www.bloomberg.com/news/articles/2026-03-17/us-navy-awards-contract-to-gecko-robotics-to-inspect-ships",
"date": "Mar 17, 2026"
},
{
"title": "Gecko Robotics raises $125 million surpassing billion-dollar valuation",
"url": "https://www.cnbc.com/2025/06/12/gecko-robotics-raises-125-million-surpassing-billion-dollar-valuation.html",
"date": "Jun 12, 2025"
},
{
"title": "Exclusive: Gecko Robotics to expand its U.S. Navy gigs",
"url": "https://www.axios.com/2024/09/04/gecko-robotics-navy-columbia",
"date": "Sep 04, 2024"
},
{
"title": "These wall-climbing robots are finding flaws in D grade infrastructure",
"url": "https://www.cnbc.com/2024/05/15/these-wall-climbing-robots-are-finding-flaws-in-d-grade-infrastructure.html",
"date": "May 15, 2024"
},
{
"title": "Pittsburgh Robotics Firm Lands Major Middle East Oil Contract - Blue Sky News",
"url": "https://blueskypit.com/pittsburgh-robotics-firm-lands-middle-east-oil-contract/",
"date": "May 13, 2024"
}
],
"launches": []
},
{
"id": 1671,
"name": "Sourceress",
"slug": "sourceress",
"former_names": [
"Sourceress",
"Generally Intelligent",
"Imbue (formerly Generally Intelligent",
"YC17)",
"Imbue (formerly Generally Intelligent)"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/cd298ab7cc0e50b44f16100129fb3d4a93dcabc0.png",
"website": "http://sourceress.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Sourceress is an AI recruiter that is reinventing how people find jobs. With tailor-made machine learning models, we rigorously define what a company is looking for in a role, identify great candidates, and engage candidates with highly personalized introductions. Our process creates a stream of interested candidates that hiring managers are excited about more than 85% of the time.",
"one_liner": "",
"team_size": 35,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1493860914,
"tags": [
"Machine Learning",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2017",
"status": "Active",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/sourceress",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2017/sourceress.json",
"year_founded": 2017,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/sourceress",
"x_url": "https://twitter.com/sourceress",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/cd298ab7cc0e50b44f16100129fb3d4a93dcabc0.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 110720,
"full_name": "Kanjun Qiu",
"title": "Founder/CEO",
"founder_bio": "Empowering ~humans~ in an age of AI. CEO at Imbue, support founders at Outset Capital",
"is_active": false,
"linkedin_url": "http://www.linkedin.com/in/kanjun",
"x_url": "https://twitter.com/kanjun",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/44537cb8a7355f2809fe47ebc11162904b29f68a.jpg"
},
{
"user_id": 47452,
"full_name": "Josh Albrecht",
"title": "Founder",
"founder_bio": null,
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/joshalbrecht",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/84331d6d5f3477f76c5d7c4a61cb4a3185d27cbb.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Imbue raises $200M to build AI models that can 'robustly reason' | TechCrunch",
"url": "https://techcrunch.com/2023/09/07/imbue-raises-200m-to-build-ai-models-that-can-robustly-reason",
"date": "Sep 07, 2023"
}
],
"launches": []
},
{
"id": 1945,
"name": "LabelFlow",
"slug": "labelflow",
"former_names": [
"Sterblue"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/799423cdb14bc1fbe4eb1d647eedf74d0a22e8c7.png",
"website": "https://labelflow.ai/",
"all_locations": "Nantes, Pays de la Loire, France; Remote",
"long_description": "At LabelFlow, we build GitHub for visual data. Our mission is to facilitate and accelerate the development of AI at scale thanks to top-notch labeling tools and a dataset marketplace.",
"one_liner": "GitHub for visual data",
"team_size": 6,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1525147499,
"tags": [
"Computer Vision",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2018",
"status": "Inactive",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"France",
"Europe",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/labelflow",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2018/labelflow.json",
"year_founded": 2018,
"city": "Nantes",
"country": "FR",
"linkedin_url": "https://www.linkedin.com/company/labelflow",
"x_url": "https://twitter.com/LabelflowAI",
"fb_url": "https://www.facebook.com/Labelflow/",
"cb_url": "https://www.crunchbase.com/organization/labelflow",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/799423cdb14bc1fbe4eb1d647eedf74d0a22e8c7.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 192442,
"full_name": "Geoffrey Vancassel",
"title": "Founder/CEO",
"founder_bio": "LabelFlow, GitHub for visual data (now) // Sterblue, software for drones to inspect energy infrastructures // Airbus, Design Engineer",
"is_active": true,
"linkedin_url": "https://fr.linkedin.com/in/geoffrey-vancassel-80b2aa12",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/2cfd8da516c0f480d129cb10d3b65e9dfee30544.jpg"
},
{
"user_id": 252638,
"full_name": "Nicolas Draber",
"title": "Founder/CPO",
"founder_bio": "Aerospace Engineer, Co-founder of Sterblue and LabelFlow",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/nicolasdraber/",
"x_url": "https://twitter.com/ndraber",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/cfe313a73008c291f4aee24b4f5e4172f0241447.jpg"
},
{
"user_id": 116604,
"full_name": "Vincent Lecrubier",
"title": "Founder/Chief Technical Officer",
"founder_bio": "Olympic Finalist, Computer Science PhD, Aerospace Engineer, Co-funder of Sterblue YC S18",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/crubier/",
"x_url": "https://twitter.com/VLecrubier",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9c482f082d557d1e0ffe1bd20186864f22793853.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 11955,
"name": "DevFlight",
"slug": "devflight",
"former_names": [],
"small_logo_thumb_url": "/company/thumb/missing.png",
"website": "https://devflight.com",
"all_locations": "Boston, MA, USA; Somerville, MA, USA; Remote",
"long_description": "",
"one_liner": "Managed equipment data pipelines for manufacturers",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1541122481,
"tags": [
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2019",
"status": "Inactive",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/devflight",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2019/devflight.json",
"year_founded": 2018,
"city": "Boston",
"country": "US",
"linkedin_url": "",
"x_url": "",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/devflight",
"github_url": "https://github.com/DevFlight",
"logo_url": null,
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 244218,
"full_name": "Tony Mastrorio",
"title": "Founder",
"founder_bio": "I've been a founder, engineer and PM.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/tonymastrorio/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/22dbbafc270cdbf3d56972c093641cfa4166b35c.jpg"
},
{
"user_id": 278824,
"full_name": "Victor Bordo",
"title": "Founder",
"founder_bio": "",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/victorbordo/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/61f147928caa97fc86d2dd1a7615be1adf8aef2c.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 12258,
"name": "Datamode",
"slug": "datamode",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/028000b4921cd21235c9b7b837cd86a36f92a101.png",
"website": "http://www.datamode.com",
"all_locations": "Seattle, WA, USA",
"long_description": "We're building a tool to help data engineers diagnose problems in their data pipelines. Datamode integrates with the technologies you use to provide a single place to start investigating problems and reduce the mean time to diagnosis. This means higher data quality and improved reliability for the business.",
"one_liner": "Datamode (datamode.com) is a tool for engineers to instantly diagnose…",
"team_size": 1,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1543978906,
"tags": [
"Analytics",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2019",
"status": "Inactive",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/datamode",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2019/datamode.json",
"year_founded": null,
"city": "Seattle",
"country": "US",
"linkedin_url": "",
"x_url": "",
"fb_url": "https://www.facebook.com/Datamode-393613441387780/?modal=admin_todo_tour",
"cb_url": "https://www.crunchbase.com/organization/datamode",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/028000b4921cd21235c9b7b837cd86a36f92a101.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 303103,
"full_name": "Andrew Kim",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/andrewakim",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/0aae1ba1b059019eca1d1aa44f4c74c3cc0a2f40.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 12549,
"name": "Symplex",
"slug": "symplex",
"former_names": [
"Symplex",
"Demigod",
"Violet",
"communion",
"violet",
"demigod",
"symplex",
"demigod"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/33294c2e2a853eb8b88c2102faadf92348a869e3.png",
"website": "",
"all_locations": "New York City, NY, USA",
"long_description": "• Acquired by Scale AI\r\n\r\n\r\n",
"one_liner": "Applied Reinforcement Learning Research Laboratory",
"team_size": 8,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1556077735,
"tags": [
"Data Engineering",
"AI",
"AI Assistant"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2019",
"status": "Acquired",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": true,
"demo_day_video_public": true,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/symplex",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2019/symplex.json",
"year_founded": null,
"city": "New York City",
"country": "US",
"linkedin_url": "",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/33294c2e2a853eb8b88c2102faadf92348a869e3.png",
"app_video_url": "https://bookface-images.s3.us-west-2.amazonaws.com/bf-public_profile/12621/app_video.mp4?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=ASIAQC4NIECAPVLLM2EU%2F20261020%2Fus-west-2%2Fs3%2Faws4_request&X-Amz-Date=20261020T022643Z&X-Amz-Expires=60&X-Amz-Security-Token=IQoJb3JpZ2luX2VjEHEaCXVzLXdlc3QtMiJGMEQCIERmcK8Cf9%2Btw509DI59PWqE38RRTAlvZa4J3JDwHNfvAiAayM%2BKkNtOvjgd758WgPB4q6%2BUu3dhFEeIBKJdEEYmHirlAwg5EAAaDDAwNjIwMTgxMTA3MiIMT2KDc6%2BsqQRelJt7KsIDHKXozlWP2zRm6TyaI63cZu7UdMNJI84LhfrBVoBzKOZrazhBds2e6DhqALWGgEHuhaH96sBW1vGKF0SZPA8JEf%2FhnbI%2B0LPups6efXBWO1aKfnU6HWjkfPemBseL1V1dBRWh3MHmM%2BS0wsfJmaYaFWTcHaaVraOkFgeuvtIGQt%2FnimlcxYe9MQMOeYiPnm5yfGLPkCnGOvHZGDepzR19xj6ZjRi9QZRcX734o%2BDyXGZIQOACA5etqDAXBP7fbW8udzjKK9cHEGPamT7IlaTLAWBWnDjL2T9zw8ZCXoeolYzeaw3DTEK0tdnm9pXjkPGWxrNUNlecD6CiG7M3gr2Lm8eody0o9pj5Ec9BIcJ09i9djYQp%2F9Qt3RQagWspbZEm0RIM98ukXmmQO%2Br5NwFl2BqP7h04EVZMR4%2FxuoUkyMfNGipkzTdDAKGOV2wo7LqFqinznpZBKbguQ%2Fg6wWy40kCNyoPguBPf8GYzzIvusP5x6bf1QHvMlXyb8ElzS4lScRKm7v5GhARAJq%2BveXuxU3aR2lwL84TF9HIpOZ6loG5wOggyMO5KqHtaunl14wjKV3M6InDmt6%2F5NLTGbL6N0P36MOn92tYGOqYB%2B%2FclWb0gxQJ%2FmXWJ%2FID3oboHUM%2BqcRMUObsJl1yosDN9kekbLFwXPJS0wjujDnQuGXhjbEK0yPyr8Dgq35lBDPMlxWRQ8upAxHpp%2F0cruekkJPyONG5qpVv25DqS52YxtylQ0pbERuY6rX1AFi5Hwd5%2FQJgU8TuncKO5FjbC0OPiim0nrZjMnv3t4R3u06MVK4%2FRj2yhCS4qwhYGeOsJdP79%2BCqZqQ%3D%3D&X-Amz-SignedHeaders=host&X-Amz-Signature=64f218dc599b1836690f867f1e3f1ef97fa49a0f940e4b2360ae8c862a9c86e5",
"dday_video_url": "https://bookface-images.s3.us-west-2.amazonaws.com/video_event/45/1566339403030-93tupe4s4as-43db43432b5134b893a40c7759ed463d/44b66b4475100b3b7b18ae54da912ce5.mp4?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=AKIAQC4NIECABPQ2AHNW%2F20261020%2Fus-west-2%2Fs3%2Faws4_request&X-Amz-Date=20261020T022643Z&X-Amz-Expires=3600&X-Amz-SignedHeaders=host&X-Amz-Signature=ee8c23c58ac61c28faa76bf127446df8f4d6b00c984732438cbc8f453563a4dd",
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/19bb896a7bf92d41106b302479512861c7de6dc6.png"
],
"primary_partner": null,
"founders": [
{
"user_id": 327088,
"full_name": "Gokul Prabhakaran",
"title": "Founder",
"founder_bio": ".",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/gokul-prabha/",
"x_url": "https://twitter.com/richhomiegokul",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/f175feabd14a88b45df214be613a8951ede0bcef.jpg"
},
{
"user_id": 267658,
"full_name": "Dhanush Radhakrishnan",
"title": "Founder",
"founder_bio": "I'm Co-founder & CEO at Clone, where we build musculoskeletal, superintelligent androids.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/dhanush-rad-66609a71/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/03a9c280d7077920728f90443b2452cf7bf6c6cd.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 12598,
"name": "Narrator",
"slug": "narrator",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/18139ce5e1ad199f99ea66921af1fd68a63f6e95.png",
"website": "https://www.narratordata.com/",
"all_locations": "New York City, NY, USA; New York, NY, USA; Remote",
"long_description": "Narrator is an end-to-end platform built on top of the data standard, the Activity Schema and starting at $500/mo. Data analyst are able to build their definitions of their user journey, and use that journey to answer any question that comes up. From there, data can be visualized in a dashboard, used to build a story like analysis, exported and more. \r\n\r\nThe biggest values of Narrator is Speed and Cost reduction. Small teams are able to move fast and answer questions in minutes allowing them to preform the work of very large data teams. All while Narrator is optimized to minimize compute cost of the warehouse.",
"one_liner": "The only platform that can prep data to answer EVERY question you…",
"team_size": 8,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1556223953,
"tags": [
"Analytics",
"Big Data",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2019",
"status": "Inactive",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/narrator",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2019/narrator.json",
"year_founded": 2017,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/narratorai",
"x_url": "",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/ai-narrator",
"github_url": "https://github.com/narratorai",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/18139ce5e1ad199f99ea66921af1fd68a63f6e95.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 55256,
"full_name": "Cedric Dussud",
"title": "Founder",
"founder_bio": "Former cofounder at Narrator.ai. Previously engineering director at WeWork and senior engineer at Microsoft",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/cedricd",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/a6951a56e2a66c5a219358a1c82473181324e3d5.jpg"
},
{
"user_id": 318063,
"full_name": "Ahmed Elsamadisi",
"title": "Founder",
"founder_bio": "A data expert transforming the field of data analysis with his groundbreaking Activity Schema. Beginning his career with self-driving cars and AI for missile defense, Ahmed’s deep technical expertise took him to WeWork, where he founded and led their data team. In 2019, he was honored as one of Forbes’ 30 Under 30 in Enterprise Technology. Today, Ahmed focuses on developing AI systems built on hierarchical agentic frameworks, demonstrating his dedication to advancing the future of AI.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/elsamadisi/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/84a056472f3200c8def2ff21d0dabf06c82e6043.jpg"
},
{
"user_id": 350456,
"full_name": "Mike Nason",
"title": "Founder",
"founder_bio": "",
"is_active": false,
"linkedin_url": "https://linkedin.com/in/michaelnason/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/d1ee5d0963eab4c7472c3ef058d8faa2926add96.jpg"
},
{
"user_id": 350455,
"full_name": "Matt Star",
"title": "Founder",
"founder_bio": "",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/mattjstar/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/7038bd86068a8eb974c11c3249e52b6150e38c2d.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Narrator raises $6.2M for a new approach to data modelling that replaces star schema – TechCrunch",
"url": "https://techcrunch.com/2020/09/17/narrator-raises-6-2m-for-a-new-approach-to-data-modelling-that-replaces-star-schema/",
"date": "Sep 17, 2020"
},
{
"title": "Y Combinator-backed Narrator wants to become the operating system for data science – TechCrunch",
"url": "https://techcrunch.com/2019/08/16/y-combinator-backed-narrator-wants-to-become-the-operating-system-for-data-science/",
"date": "Aug 16, 2019"
}
],
"launches": []
},
{
"id": 12608,
"name": "TRM Labs",
"slug": "trm-labs",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/19aa5130e3a0a349d200e7510f0c2fe8439a646f.png",
"website": "https://trmlabs.com/",
"all_locations": "San Francisco, CA, USA; Remote",
"long_description": "TRM is on a mission to build a safer world for billions of people. \r\n\r\nAI is extending the capability gap between attackers and defenders. The fundamental unit of scale has shifted from humans to AI tokens. \r\n\r\nTRM combines proprietary data, with an AI investigations platform to build a system of action for crime fighters. Think Claude CoWork for mission critical investigations. \r\n\r\nWe believe AI scale crime deserves AI scale defense. \r\n\r\nJoin our mission ➔ www.trmlabs.com/careers",
"one_liner": "TRM is building a safer world for billions of people.",
"team_size": 400,
"industry": "B2B",
"subindustry": "B2B -> Security",
"launched_at": 1556572947,
"tags": [
"Fintech",
"Machine Learning",
"GovTech",
"Cybersecurity",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Summer 2019",
"status": "Active",
"industries": [
"B2B",
"Security"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/trm-labs",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2019/trm-labs.json",
"year_founded": 2018,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/trmlabs/",
"x_url": "https://twitter.com/trmlabs",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/trm-labs",
"github_url": "https://github.com/trmlabs",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/19aa5130e3a0a349d200e7510f0c2fe8439a646f.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 182800,
"full_name": "Esteban Castaño",
"title": "Founder",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ecastano/",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/f30ed5d0c98a481c2748ef4df723efad5018bc7b.jpg"
},
{
"user_id": 253026,
"full_name": "Rahul Raina",
"title": "Founder",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/rahulr0609/",
"x_url": "https://twitter.com/rahulr0609",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9759364f37d0fa64a091b6496b181d7ae6a3a814.jpg"
}
],
"jobs": [
{
"id": 76585,
"title": "New Product Lead",
"url": "https://www.ycombinator.com/companies/trm-labs/jobs/Bt9p7XS-new-product-lead",
"location": "US / Remote (US)",
"type": "Full-time",
"role": "Product",
"role_type": null,
"salary_range": "$175K - $200K",
"equity_range": "",
"experience": "6+ years",
"visa": "US citizen/visa only",
"skills": []
}
],
"news": [
{
"title": "TRM Labs’ Financial-Service Backers Come Back For More In $70 Million Series B Expansion",
"url": "https://www.forbes.com/sites/mitchellmartin/2022/11/09/trm-labs-financial-service-backers-come-back-for-more-in-70-million-series-b-expansion/",
"date": "Nov 16, 2022"
},
{
"title": "JPMorgan Chase Strategically Invests in Blockchain-focused TRM Labs",
"url": "https://blockworks.co/jpmorgan-chase-strategically-invests-in-blockchain-focused-trm-labs/",
"date": "Mar 03, 2022"
},
{
"title": "TRM Labs Raises $60M as Visa, Amex Play Catch-Up on Crypto Tracking",
"url": "https://www.coindesk.com/business/2021/12/07/trm-labs-raises-60m-as-visa-amex-play-catchup-on-crypto-tracking/",
"date": "Dec 07, 2021"
},
{
"title": "TRM Labs Raises $14M as Crypto Tracking Steps Into Spotlight - CoinDesk",
"url": "https://www.coindesk.com/trm-labs-raises-14m-as-crypto-tracking-steps-into-spotlight",
"date": "Jun 17, 2021"
}
],
"launches": []
},
{
"id": 12618,
"name": "Embrace",
"slug": "embrace",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/6c5df7e755694ec01e6b16cfc307e0ddf5712e43.png",
"website": "https://embrace.io",
"all_locations": "Los Angeles, CA, USA; Remote",
"long_description": "*S19 and YCG F21*\r\nEngineering teams shouldn’t be in the dark when it comes to the performance of their web and mobile apps and user experiences. With our industry-leading observability technology, Embrace aims to give SRE and DevOps teams better insight into what matters most – their users – by tying performance data to backend observability insights.\r\n\r\nAs the only user-focused, use-focused observability solution built on OpenTelemetry, Embrace delivers crucial insights across both DevOps and frontend teams to illuminate real customer impact – not just server impact – to deliver the best app experiences. Customers like The New York Times, Marriott, Warby Parker, Masterclass, Home Depot, and Cameo love Embrace’s observability platform because it makes extremely complicated and voluminous data actionable.",
"one_liner": "Modern user-focused observability built on OpenTelemetry",
"team_size": 62,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1556659657,
"tags": [
"SaaS",
"Open Source",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2019",
"status": "Acquired",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": true,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/embrace",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2019/embrace.json",
"year_founded": 2016,
"city": "Los Angeles",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/embrace.io",
"x_url": "https://twitter.com/embracemobile",
"fb_url": "https://www.facebook.com/embracemobile/",
"cb_url": "https://www.crunchbase.com/organization/embrace-io",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/6c5df7e755694ec01e6b16cfc307e0ddf5712e43.png",
"app_video_url": null,
"dday_video_url": "https://bookface-images.s3.us-west-2.amazonaws.com/video_event/45/1566324294196-jcvcpfakqzn-406513f653b48df0d4827634c62f95a1/7e2654787b9808dbcdd923e84612b188.mp4?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=AKIAQC4NIECABPQ2AHNW%2F20261020%2Fus-west-2%2Fs3%2Faws4_request&X-Amz-Date=20261020T022644Z&X-Amz-Expires=3600&X-Amz-SignedHeaders=host&X-Amz-Signature=9ce6ad6fae11b1f6d8ece2f263af48c24aeb6270e5d22d8d9dc3e06628f96b39",
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 330918,
"full_name": "Eric Futoran",
"title": "Founder/CEO",
"founder_bio": " Founder of Embrace, the only observability platform purpose-built for web and mobile. We proactively discover errors and instantly resolve issues for UX and Engineers, while delivering 100% of sessions and enriched data for Data Science.\n\nPreviously founder of Scopely, the #1 mobile games publisher with Yahtzee, Walking Dead, and Star Trek. Built the first DMP at Aggregate Knowledge. First job was at Trilogy.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/futoran/",
"x_url": "https://twitter.com/efutoran",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/41f94d6224a1f7d0b4d5a5ef2390d94fd8e9feb3.jpg"
},
{
"user_id": 330923,
"full_name": "Fredric Newberg",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/fredricnewberg/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/94ba87fa78563ee710bd6db83c6cd86e00cf5959.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Palo Alto Networks to Extend Leading Observability Platform with Innovative Digital Experience Monitoring - Palo Alto Networks",
"url": "https://investors.paloaltonetworks.com/news-releases/news-release-details/palo-alto-networks-extend-leading-observability-platform",
"date": "Jul 21, 2026"
},
{
"title": "Embrace grabs a new funding round amid unveiling of new mobile data intelligence software – TechCrunch",
"url": "https://techcrunch.com/2021/10/20/embrace-grabs-a-new-funding-round-amid-unveiling-of-new-mobile-data-intelligence-software/",
"date": "Oct 20, 2021"
}
],
"launches": []
},
{
"id": 12669,
"name": "Data Mechanics",
"slug": "data-mechanics",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/041cd41aaf413fd601a958566433246e70084357.png",
"website": "https://www.datamechanics.co",
"all_locations": "Paris, Île-de-France, France",
"long_description": "Data Mechanics was acquired by NetApp in 2021 and integrated in the Spot.io product portfolio. Our managed Spark-on-Kubernetes platform is live and running under the name Ocean for Apache Spark: https://spot.io/products/ocean-apache-spark/",
"one_liner": "Spark-on-Kubernetes Data Engineering Platform",
"team_size": 25,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1556782113,
"tags": [
"SaaS",
"B2B",
"Open Source",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2019",
"status": "Acquired",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"France",
"Europe",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/data-mechanics",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2019/data-mechanics.json",
"year_founded": 2019,
"city": "Paris",
"country": "FR",
"linkedin_url": "https://www.linkedin.com/company/datamechanics",
"x_url": "https://twitter.com/DataMechanics_",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/041cd41aaf413fd601a958566433246e70084357.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/04f4226cdd01aeb6649b636052b051381bb1c69f.png"
],
"primary_partner": {
"name": "Gustaf Alstromer",
"url": "https://www.ycombinator.com/people/gustaf-alstromer"
},
"founders": [
{
"user_id": 321583,
"full_name": "Jean Yves Stephan",
"title": "Founder",
"founder_bio": "2019-2021: Co-Founder & CEO at Data Mechanics (YC S19 Batch, B2B Data Engineering Platform). Acquired by Spot in 2021, worked as a PM there until September 2022. \n\nNow working on something new, with a special interest in climate tech, sustainability, environmental and social impact. Also getting involved as a BA or startup advisor, whenever I can add value. Reach out to me :)!",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jystephan/",
"x_url": "https://twitter.com/JyStephan",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/3090ba8d739e09068880d967f57dc389ffcbc310.jpg"
},
{
"user_id": 333012,
"full_name": "Julien Dumazert",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/julien-dumazert-5b46a485/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/bb6eb8fb7834859ba34dd487ef9e199a378ff16a.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 12724,
"name": "Chaos Genius",
"slug": "chaos-genius",
"former_names": [
"GoodHealth"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/c4d680463f8fee3408726becdad9bccd8e14c8a1.png",
"website": "http://www.chaosgenius.io",
"all_locations": "Bengaluru, KA, India; San Francisco, CA, USA; Remote",
"long_description": "Chaos Genius is a DataOps Observability platform for Snowflake. Enable Snowflake Observability to reduce Snowflake costs and optimize query performance.",
"one_liner": "DataOps Observability Platform for Snowflake",
"team_size": 10,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1600455323,
"tags": [
"Cloud Workload Protection",
"Machine Learning",
"Analytics",
"Open Source",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2020",
"status": "Acquired",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"India",
"United States of America",
"South Asia",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/chaos-genius",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2020/chaos-genius.json",
"year_founded": 2021,
"city": "Bengaluru",
"country": "IN",
"linkedin_url": "https://www.linkedin.com/company/chaosgenius",
"x_url": "https://twitter.com/ChaosGenius",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/chaos-genius",
"github_url": "https://github.com/chaos-genius",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/c4d680463f8fee3408726becdad9bccd8e14c8a1.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 341507,
"full_name": "Preeti Shrimal",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/pshrimal/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/f8123b419b4475c7bc0f3c22a5e3eb993168bdd4.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Snowflake spend on the rise? How to tackle the ‘chaos’ | VentureBeat",
"url": "https://venturebeat.com/data-infrastructure/chaos-genius-to-reduce-snowflake-spending/",
"date": "Jan 09, 2023"
},
{
"title": "Data observability startup Chaos Genius raises $3.3M to help companies optimize Snowflake costs - SiliconANGLE",
"url": "https://siliconangle.com/2023/01/03/data-observability-startup-chaos-genius-raises-3-3m-help-companies-optimize-snowflake-costs/",
"date": "Jan 03, 2023"
}
],
"launches": []
},
{
"id": 13088,
"name": "Polytomic",
"slug": "polytomic",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/4767968ca9a72ca160b394cd0fb3eba2f5602eb7.png",
"website": "https://www.polytomic.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "Polytomic is a no-code web app to sync data between your internal databases, business systems (e.g. Stripe, Salesforce, etc), data warehouses, spreadsheets, and even HTTP APIs. ",
"one_liner": "No-code data syncing between your systems",
"team_size": 7,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1612396813,
"tags": [
"SaaS",
"B2B",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2020",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/polytomic",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2020/polytomic.json",
"year_founded": 2019,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/polytomic/",
"x_url": "https://twitter.com/polytomic",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/polytomic",
"github_url": "https://github.com/polytomic",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/4767968ca9a72ca160b394cd0fb3eba2f5602eb7.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 16364,
"full_name": "Ghalib Suleiman",
"title": "Founder",
"founder_bio": "Polytomic CEO",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ghalibs",
"x_url": "https://www.twitter.com/ghalib",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/0d4d9f3518e981623664735db3ae05c07d7ec6bd.jpg"
},
{
"user_id": 416540,
"full_name": "Nathan Yergler",
"title": "Founder",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/nathanyergler/",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/2a28dee9f318ba8788d9c081243a3f6f18d0ccc9.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 13185,
"name": "Operator.io",
"slug": "operatorio",
"former_names": [
"Atana",
"Atana Health",
"Trimwire",
"Operator",
"Operator Labs",
"Operator"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/ddad5e732e1515ab69da4100f7fa6d3a5d491e82.png",
"website": "http://operator.io",
"all_locations": "New York City, NY, USA",
"long_description": "Operator.io is the easiest way to set up an OpenClaw agent and connect it to 1000+ different applications like Gmail, Notion, Stripe, and more. Onboard an AI executive assistant that tackles the tasks you know need to be done that you don't have bandwidth for.",
"one_liner": "Operator.io is OpenClaw that just works ",
"team_size": 6,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1583870881,
"tags": [
"Generative AI",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2020",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/operatorio",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2020/operatorio.json",
"year_founded": null,
"city": "New York City",
"country": "US",
"linkedin_url": "",
"x_url": "https://x.com/operator_io",
"fb_url": null,
"cb_url": null,
"github_url": "github.com/operatorlabs",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/ddad5e732e1515ab69da4100f7fa6d3a5d491e82.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 372784,
"full_name": "Kevin Joo",
"title": "Founder",
"founder_bio": "founder at operator.io",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/kevinjoo/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/10d6118d506f6cd2f443ff0fcc2e81e02b6be678.jpg"
},
{
"user_id": 352651,
"full_name": "David Shi",
"title": "Founder",
"founder_bio": "building protocols for distributed intelligence",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/davidzshi",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/bc8b54604ea18d8a81453d1cc1e2f62453a865d3.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 13205,
"name": "Logarithm Labs",
"slug": "logarithm-labs",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/71c1fab536511f29e3d68a7aa3cadd96e12f41f2.png",
"website": "http://www.logarithmlabs.com",
"all_locations": "San Francisco, CA, USA; Foster City, CA, USA",
"long_description": "Easy button to use data for your daily operations. Power your business workflows with quality data.\r\n\r\nLogarithm Labs helps you turn manual data wrangling and ad-hoc scripts into repeatable pipelines for your operational workflows. Power your workflows with quality data.\r\n\r\nOur product and team of experts do the heavy lifting so that can focus on the business logic that drives your organization.\r\n\r\nTo learn more, contact us at hello@logarithmlabs.com.",
"one_liner": "Easy button to use data for your daily operations",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1584126560,
"tags": [
"Developer Tools",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2020",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/logarithm-labs",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2020/logarithm-labs.json",
"year_founded": 2019,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/logarithmlabs/",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/71c1fab536511f29e3d68a7aa3cadd96e12f41f2.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 419715,
"full_name": "Puneet Jagralapudi",
"title": "Founder",
"founder_bio": "Ex-Product Manager; Led solutions & GTM at Google Cloud for compute, storage, analytics, and vertical solutions, M&A and strategy at LSI CTO's office",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jrpuneet/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/aa9136871846488d10ac494db6114778bf9a7e59.jpg"
},
{
"user_id": 61514,
"full_name": "Avishek Panigrahi",
"title": "Founder",
"founder_bio": "I have ~20 years of experience in chip design, compute/data infrastructure, and CAD/automation working at Google, Xilinx, Samsung MIPS.\n\nAt Logarithm Labs, we accelerate complex engineering development by making engineering data usable and actionable. We're starting with chip design.\n\n",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/avishek-panigrahi/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/1326d0a1b18e47758c838bd9c603c5529c115fcc.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 13211,
"name": "Metaplane",
"slug": "metaplane",
"former_names": [
"Quantifai"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/aa2c854ed688cf4ff0f5cf7f48786c533f00b943.png",
"website": "https://metaplane.dev",
"all_locations": "New York City, NY, USA",
"long_description": "Metaplane ensures everyone trusts the data that powers your business. Data teams at Bose, Ramp, and Klaviyo use our data observability platform to prevent and detect data issues — before the CEO pings them about weird revenue numbers.\r\n\r\nWe do this with ML-based anomaly detection, end-to-end column-level lineage, and tools to help prevent incidents before they occur. You can monitor your entire data stack within 30 minutes.\r\n\r\nThe company is backed by Khosla Ventures, Y Combinator, and the founders of Okta, HubSpot, and Vercel.",
"one_liner": "Data observability for modern data teams",
"team_size": 32,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1614011784,
"tags": [
"Developer Tools",
"SaaS",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2020",
"status": "Acquired",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/metaplane",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2020/metaplane.json",
"year_founded": 2019,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/74044167/",
"x_url": "https://twitter.com/metaplane",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/metaplane",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/aa2c854ed688cf4ff0f5cf7f48786c533f00b943.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Aaron Epstein",
"url": "https://www.ycombinator.com/people/aaron-epstein"
},
"founders": [
{
"user_id": 97158,
"full_name": "Guru Mahendran",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "http://www.linkedin.com/in/gurubavan",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/1b86abe051d4ce9b1ebdadd0a0b009dec371b3af.jpg"
},
{
"user_id": 107059,
"full_name": "Kevin Hu",
"title": "Founder",
"founder_bio": "CEO of Metaplane (acquired by Datadog)",
"is_active": true,
"linkedin_url": "http://linkedin.com/in/kevinzenghu",
"x_url": "https://twitter.com/kevinzenghu",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/7a36d02cb0e899b30b9efcf50578e17fbd9b9d9b.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Exclusive: Metaplane nets $13M to detect data anomalies with AI | VentureBeat",
"url": "https://venturebeat.com/data-infrastructure/exclusive-metaplane-nets-13m-to-detect-data-anomalies-with-ai/",
"date": "Mar 05, 2024"
},
{
"title": "Data observability startup Metaplane lands investment from YC, others • TechCrunch",
"url": "https://techcrunch.com/2023/01/10/data-observability-startup-metaplane-lands-investment-from-yc-others/",
"date": "Jan 10, 2023"
}
],
"launches": []
},
{
"id": 13405,
"name": "Zumo Labs",
"slug": "zumo-labs",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/a53f5d4e5c3734ef65ff0417ad276ccdd20cafdd.png",
"website": "https://zumolabs.ai/",
"all_locations": "San Francisco, CA, USA; Remote",
"long_description": "At Zumo Labs, we generate synthetic training data for computer vision models.\r\n\r\nComputer vision is the essential technology that powers the products of the future: autonomous vehicles, smart retail, robotics, smart fitness, security and vision-based analytics. These algorithms require huge amounts of training data. This data is currently collected and labeled manually; a slow, imprecise, expensive process that is rife with bias and privacy issues. \r\n\r\nZumo Labs solves all of these problems (and more!) by creating feature rich synthetic training data in the cloud: cheaper, faster to generate and iterate on, covers all the edge cases, and has no bias or privacy issues. \r\n",
"one_liner": "We generate synthetic data for computer vision models.",
"team_size": 7,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1584126960,
"tags": [
"Machine Learning",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2020",
"status": "Inactive",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/zumo-labs",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2020/zumo-labs.json",
"year_founded": 2020,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/28375665",
"x_url": "https://twitter.com/ZumoLabs",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/a53f5d4e5c3734ef65ff0417ad276ccdd20cafdd.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 453541,
"full_name": "Norman Ponte",
"title": "Founder",
"founder_bio": "normanponte.io",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/norman-ponte-476279104/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/0b8dccee73b380e5825f60d6d88a931e169681b7.jpg"
},
{
"user_id": 409034,
"full_name": "Elena Ponte",
"title": "Founder",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/elenaponte",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/e9f46bbfd0768ee51a706f5c81a1b370bb92cc07.jpg"
},
{
"user_id": 407002,
"full_name": "Hugo Ponte",
"title": "Founder",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/hugo-ponte-9b385765",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/d03d44407ec7955327c3ee19ee514b571f95879d.jpg"
},
{
"user_id": 453543,
"full_name": "Kory Stiger",
"title": "Founder",
"founder_bio": null,
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/kory-stiger-24560682/",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/6e5662f29dc35559f7357216f926115cdb5426b3.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 13549,
"name": "Airbyte",
"slug": "airbyte",
"former_names": [
"Daxtarity",
"Dataline"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/fc4c9a8bb7a853c14be4dac967fb9717f36fca1c.png",
"website": "https://airbyte.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Airbyte Agents is the context layer your AI agents query before they act. Features the Context Store, which unifies entities across Salesforce, Stripe, Zendesk and more. Use it from the UI, your LLM via MCP, or our SDK. 40% fewer tool calls, up to 80% fewer tokens.\r\n\r\nAirbyte Data Replication is the leading open data movement platform that empowers data teams in the AI era by transforming raw data into actionable intelligence. \r\n\r\nhttps://github.com/airbytehq/",
"one_liner": "Context layer for production-grade AI agents",
"team_size": 90,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1584288236,
"tags": [
"Developer Tools",
"Open Source",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2020",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/airbyte",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2020/airbyte.json",
"year_founded": 2020,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/airbytehq/",
"x_url": "https://twitter.com/AirbyteHQ",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/airbyte-b3bb",
"github_url": "https://github.com/airbytehq",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/fc4c9a8bb7a853c14be4dac967fb9717f36fca1c.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 413863,
"full_name": "Michel Tricot",
"title": "Founder/CEO",
"founder_bio": "Co-founder & CEO of Airbyte.\n\nI’ve been working in data since 2007. In 2011 I join LiveRamp where I was Head of Integrations and Director of Engineering. My team built and scaled over 1,000 data ingestion and distribution connectors to replicate hundreds of TB of data every day. \n\nAfter LiveRamp’s acquisition and later IPO (NYSE:RAMP), I joined rideOS as Director of Engineering, again deep in data. There, I realized that all companies are trying to solve the same problem.\n\nAirbyte was born.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/micheltricot/",
"x_url": "https://twitter.com/MichelTricot",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/276edcf2c0db7757143437c26c39ae86039ff745.jpg"
},
{
"user_id": 407884,
"full_name": "Jean Lafleur",
"title": "Founder/COO",
"founder_bio": "- Co-founder of Airbyte, the leading open-source data integration platform. \n- Serial entrepreneur (4 startups incl. 2 acquired, 1 failure, 1 ongoing),\n- 10+ years been developing strong teams building successful products\n- Big believer in people, data and telling a story.\n- Love building new products with the right GTM and messaging. But love even more building and growing teams that do so.\n- Write for SDTimes, TheNewStack, Linux.com, DevOps.com, Dzone, Product Coalition...",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jeanhenrilafleur/",
"x_url": "https://twitter.com/JeanLafleur",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/f32e3c407c2bb0f75b523cc45b0f2ca2759a9dcb.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Data platform Airbyte can now create API connectors by reading the docs | TechCrunch",
"url": "https://techcrunch.com/2024/09/24/data-platform-airbyte-can-now-create-api-connectors-by-reading-the-docs/",
"date": "Sep 24, 2024"
},
{
"title": "A $150M Series-B to Power the Movement of Data | Airbyte",
"url": "https://airbyte.io/blog/a-150m-series-b-to-power-the-movement-of-data",
"date": "Dec 20, 2021"
},
{
"title": "Data Startup Airbyte Is Set To Become A Unicorn, Intensifying Showdown With Rival Company Fivetran",
"url": "https://www.forbes.com/sites/kenrickcai/2021/12/17/data-startup-airbyte-is-set-to-become-a-unicorn-intensifying-showdown-with-rival-company-fivetran/",
"date": "Dec 18, 2021"
}
],
"launches": []
},
{
"id": 19932,
"name": "Jitsu",
"slug": "jitsu",
"former_names": [
"kSense"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/d2a6bc92874bce104c70f6971a040465116e2321.png",
"website": "https://jitsu.com",
"all_locations": "New York City, NY, USA; Remote",
"long_description": "Jitsu is the fastest, most durable way to collect event data from every source - web, app, email, chatbot, CRM - into your data warehouse. 100% open-source. Purpose built, secure and ready in minutes.",
"one_liner": "Open-Source CDP (acquired by Helium Ventures)",
"team_size": 4,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1597695723,
"tags": [
"SaaS",
"B2B",
"Open Source",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2020",
"status": "Acquired",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/jitsu",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2020/jitsu.json",
"year_founded": 2020,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/jitsucom",
"x_url": "https://twitter.com/jitsucom",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/jitsucom",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/d2a6bc92874bce104c70f6971a040465116e2321.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 356016,
"full_name": "Vladimir Klimontovich",
"title": "Founder",
"founder_bio": "Vladimir is currently co-founder and CTO of Jitsu. Prior to Jitsu he was COO and co-founder of GetIntent, a high-performance AI-powered ad-tech platform.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/klimontovich/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b5c7e9b487f69abfa26a171aab55030ace3ede75.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 21781,
"name": "Datafold",
"slug": "datafold",
"former_names": [
"Datafold",
"datafold"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/196898f11a9311436ed24d99e2972511f8433f5d.png",
"website": "https://datafold.com",
"all_locations": "New York City, NY, USA; Remote",
"long_description": "Datafold automates manual work in data engineering. \r\n\r\nWe leverage agentic AI to automate both day-to-day tasks, such as testing and code reviews, and massive one-off projects, such as data platform code migrations. Companies from Perplexity to Disney use Datafold to unlock more value from their data by freeing up their data teams from manual work, accelerating developer velocity, and ensuring data quality.",
"one_liner": "Automating manual and repetitive data engineering tasks with AI",
"team_size": 30,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1599762606,
"tags": [
"SaaS",
"Analytics",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Summer 2020",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/datafold",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2020/datafold.json",
"year_founded": 2020,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/datafold",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/datafold",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/196898f11a9311436ed24d99e2972511f8433f5d.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Aaron Epstein",
"url": "https://www.ycombinator.com/people/aaron-epstein"
},
"founders": [
{
"user_id": 483323,
"full_name": "Gleb Mezhanskiy",
"title": "Founder",
"founder_bio": "In the past five years, I’ve designed and built data platforms for three very different companies: Autodesk, Lyft & Phantom Auto, a mature public corporation, an exponentially growing marketplace, and a seed-stage startup at the time respectively. I've experienced first-hand the challenges of having poor data quality and observability in a data-driven environment and built multiple internal tools for data monitoring, data cataloging, and lineage.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/glebmezh/",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/efa007907845a82845a6818225cbcc3bbe66af59.jpg"
},
{
"user_id": 492816,
"full_name": "Alex Morozov",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/alex-morozov-54b5081aa",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ebf7f31e2b1778e9afd0a71e7d31a66da7d83ad9.jpg"
}
],
"jobs": [
{
"id": 96703,
"title": "Forward Deployed Data Engineer",
"url": "https://www.ycombinator.com/companies/datafold/jobs/bQ2v5i2-forward-deployed-data-engineer",
"location": "New York, NY, US / Remote (US; NL; DE; AT; HR; PL; FI; EE; LV; LT; FR; GB; CY; BG; CZ; DK; GR; HU; RO; LU; MT; PT; ES; SK; SI; SE)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$110K - $200K",
"equity_range": "0.10% - 0.20%",
"experience": "3+ years",
"visa": "Will sponsor",
"skills": []
}
],
"news": [
{
"title": "Data reliability platform Datafold raises $20M | VentureBeat",
"url": "https://venturebeat.com/2021/11/09/data-reliability-platform-datafold-raises-20m/",
"date": "Nov 09, 2021"
}
],
"launches": []
},
{
"id": 21858,
"name": "Monosi",
"slug": "monosi",
"former_names": [
"Vocable",
"Kosmos",
"qz"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/a79a7e737458c49c901b1062ceb420254ed8ac77.png",
"website": "https://monosi.dev",
"all_locations": "San Francisco, CA, USA",
"long_description": "Monosi is an extensible data observability platform that ensures teams achieve data reliability.",
"one_liner": "Open Source Data Observability",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1598983823,
"tags": [
"Developer Tools",
"B2B",
"Open Source",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2020",
"status": "Inactive",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/monosi",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2020/monosi.json",
"year_founded": 2020,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/monosi",
"x_url": "https://twitter.com/monosidev",
"fb_url": "https://facebook.com/monosidev",
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/a79a7e737458c49c901b1062ceb420254ed8ac77.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 144486,
"full_name": "Kevin Unkrich",
"title": "Founder",
"founder_bio": "Hacker & Minimalist",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/unkrich5",
"x_url": "https://twitter.com/kevinunkrich",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/3ee3302980deb0ef095291b7ae7c1ee267455dd4.jpg"
},
{
"user_id": 322296,
"full_name": "Ivan Porollo",
"title": "Founder",
"founder_bio": "SWE & founder",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/iporollo",
"x_url": "https://twitter.com/iporollo",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/8f58a73fbb922c24c83f0a4aa7158541e653b7b4.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 21985,
"name": "Streamdal",
"slug": "streamdal",
"former_names": [
"Batch"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/905df51a88d30785af526f036fcac3fcad730bb2.png",
"website": "https://streamdal.com",
"all_locations": "Portland, OR, USA; Remote",
"long_description": "SaaS data platform for observing, repairing and replaying data in streaming systems.",
"one_liner": "Data Quality & Playback Platform",
"team_size": 9,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1598191564,
"tags": [
"Developer Tools",
"Data Engineering",
"DevOps"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2020",
"status": "Inactive",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/streamdal",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2020/streamdal.json",
"year_founded": 2020,
"city": "Portland",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/streamdal",
"x_url": "https://twitter.com/streamdal",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/streamdal",
"github_url": "https://github.com/streamdal",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/905df51a88d30785af526f036fcac3fcad730bb2.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 101013,
"full_name": "Ustin Zarubin",
"title": "Founder",
"founder_bio": "Physicist turned Computer Scientist. I really enjoy working on distributed systems, hardware, and product design. In my spare time, I teach my two children about the world of science. ",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/ustin-zarubin-319659a2/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/f2039b803ce28a30cee22b9d7e6556d47e053436.jpg"
},
{
"user_id": 473282,
"full_name": "Daniel Selans",
"title": "Founder",
"founder_bio": "CTO & Co-founder at Streamdal -- working on improving pipelines in the data engineering world!\n\nI'm all about high-throughput systems, Go, cheap beer and metal \\m/\n\nPreviously at: New Relic, Digital Ocean, InVision, Community and various data centers on the East coast.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/dselans",
"x_url": "https://twitter.com/skey",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/cc6e2e3a87c517679e2848bdb8498df60ce7f09a.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Streamdal wants to bring greater visibility to streaming data architectures • TechCrunch",
"url": "https://techcrunch.com/2023/02/08/streamdal-wants-to-bring-greater-visibility-to-streaming-data-architectures/",
"date": "Feb 08, 2023"
}
],
"launches": []
},
{
"id": 22076,
"name": "Dataland",
"slug": "dataland",
"former_names": [
"Realism Labs",
"Sidekick",
"Realism Labs",
"Sidekick"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/9c1084ef28edc951f15115194ba8b7bc7c1889eb.png",
"website": "https://dataland.io",
"all_locations": "New York City, NY, USA",
"long_description": "Dataland is the applied AI lab for complex operations and customer support. In 8 months, we've grown to multi-million dollar ARR as just two founders and are highly profitable. We’re partnering with some of the fastest growing startups and public companies in the world.",
"one_liner": "AI agents for customer support.",
"team_size": 4,
"industry": "B2B",
"subindustry": "B2B -> Operations",
"launched_at": 1594828571,
"tags": [
"B2B",
"Data Engineering",
"Data Visualization",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Summer 2020",
"status": "Active",
"industries": [
"B2B",
"Operations"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/dataland",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2020/dataland.json",
"year_founded": 2020,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/datalandio",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/9c1084ef28edc951f15115194ba8b7bc7c1889eb.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Gustaf Alstromer",
"url": "https://www.ycombinator.com/people/gustaf-alstromer"
},
"founders": [
{
"user_id": 506027,
"full_name": "Arthur Wu",
"title": "Founder",
"founder_bio": "Now building dataland.io. Previously led product teams at Palantir, and operations at Oishii.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/arthurwu1/",
"x_url": "https://twitter.com/arthurwuhoo",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9ca6abc3e9fd383d34a05fab54d4690e3560189a.jpg"
},
{
"user_id": 130976,
"full_name": "Howard Zuo",
"title": "Founder",
"founder_bio": "Building Dataland, AI-native labor outsourcing for the enterprise.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/howard-zuo-23437258",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/1abd8b801c5f90379b3b94426c4acb8d9586549e.jpg"
}
],
"jobs": [
{
"id": 87231,
"title": "Founding Forward Deployed Engineer",
"url": "https://www.ycombinator.com/companies/dataland/jobs/tDqkVx0-founding-forward-deployed-engineer",
"location": "New York, NY, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $400K",
"equity_range": "1.00%",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"Python",
"TypeScript"
]
}
],
"news": [],
"launches": []
},
{
"id": 22091,
"name": "Supabase",
"slug": "supabase",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/9e8c106f46123a6f28b7a7da41f0ee695da48786.png",
"website": "https://supabase.com",
"all_locations": "San Francisco, CA, USA; Remote",
"long_description": "Supabase is the easiest way to get started with Postgres. \r\n\r\nEach project within Supabase is an isolated Postgres cluster, allowing customers to scale independently, while still providing the features that you need to build: instant database setup, auth, row level security, realtime data streams, auto-generating APIs, and a simple to use web interface.\r\n\r\nWe are 100% remote.\r\n\r\n",
"one_liner": "Build in a weekend. Scale to millions.",
"team_size": 120,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1596180346,
"tags": [
"Developer Tools",
"Open Source",
"Big Data",
"Data Engineering",
"Databases"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2020",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/supabase",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2020/supabase.json",
"year_founded": 2020,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/supabase/",
"x_url": "https://twitter.com/supabase",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/supabase",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/9e8c106f46123a6f28b7a7da41f0ee695da48786.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Jared Friedman",
"url": "https://www.ycombinator.com/people/jared-friedman"
},
"founders": [
{
"user_id": 244419,
"full_name": "Paul Copplestone",
"title": "Founder",
"founder_bio": "CEO, Supabase.\n",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/paulcopplestone/",
"x_url": "https://twitter.com/kiwicopple",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/d8e9228a74c698fae602238ea69bf4699490a5e7.jpg"
},
{
"user_id": 189161,
"full_name": "Ant Wilson",
"title": "Founder",
"founder_bio": "CTO @ Supabase (YC S20)",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/anthony-wilson-46179937/",
"x_url": "https://twitter.com/antwilson",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/7894aeaa75df52968edeaadd9115e60b84aeb442.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Supabase Series F",
"url": "https://supabase.com/blog/supabase-series-f",
"date": "Jun 04, 2026"
},
{
"title": "Supabase nabs $5B valuation, four months after hitting $2B | TechCrunch",
"url": "https://techcrunch.com/2025/10/03/supabase-nabs-5b-valuation-four-months-after-hitting-2b/",
"date": "Oct 03, 2025"
},
{
"title": "Exclusive: Supabase raises $200 million Series D at $2 billion valuation | Fortune",
"url": "https://fortune.com/2025/04/22/exclusive-supabase-raises-200-million-series-d-at-2-billion-valuation/",
"date": "Apr 22, 2025"
},
{
"title": "Supabase, a Postgres-centric developer platform, raises $80M Series C | TechCrunch",
"url": "https://techcrunch.com/2024/09/25/supabase-a-postgres-centric-developer-platform-raises-80m-series-c/",
"date": "Sep 25, 2024"
},
{
"title": "Supabase raises $80M Series B for its open source Firebase alternative – TechCrunch",
"url": "https://techcrunch.com/2022/05/10/supabase-raises-80m-series-b-for-its-open-source-firebase-alternative/",
"date": "May 10, 2022"
}
],
"launches": []
},
{
"id": 22248,
"name": "Mozart Data",
"slug": "mozart-data",
"former_names": [
"MarioData"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/26b12777ded0ad248c87b09da978d09a244dcff3.png",
"website": "http://www.mozartdata.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "Mozart Data provides an out-of-the-box modern data stack that empowers anyone to easily consolidate, organize, and prepare their data for analysis. Spin up a data stack that’s built on a best-in-class data warehouse and ETL tool in hours, without any engineering. You can finally spend more time on generating insights and less time wrangling your data.",
"one_liner": "The easiest way to set up a modern data stack",
"team_size": 24,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1598228399,
"tags": [
"SaaS",
"B2B",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2020",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/mozart-data",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2020/mozart-data.json",
"year_founded": 2020,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/mozartdata/",
"x_url": "https://www.twitter.com/MozartData",
"fb_url": "https://www.facebook.com/Mozart-Data-113166930331547",
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/26b12777ded0ad248c87b09da978d09a244dcff3.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 490519,
"full_name": "Peter Fishman",
"title": "Founder",
"founder_bio": "Dan and I are working on data tools for SMBs, the types of modern data stacks that we've built at multiple high growth startups. I've been running data and data-adjacent teams in the Valley for over a decade at startups from a variety of industries including gaming, social, HR/benefits, real estate, and cannabis. Dan and I have been friends for 20 years and we previously co-founded a hot sauce company, Bacon Hot Sauce, 10 years ago selling hundreds of thousands of bottles.",
"is_active": true,
"linkedin_url": "http://www.linkedin.com/in/petefishman",
"x_url": "https://twitter.com/peterfishman",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/21ad9c20af8a6cb1617cba3299bd550f1c3d26a6.jpg"
},
{
"user_id": 5666,
"full_name": "Dan Silberman",
"title": "Founder",
"founder_bio": "I am a product-oriented software engineer, with a focus on UX, data-engineering and data science. I've founded and worked at numerous startups, from consumer to fintech to healthcare.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/dansilberman23/",
"x_url": "https://twitter.com/dansilberman",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/5c64a754da95394d8008b4c9c43a7ec011499ad3.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Mozart Data announces free tier to encourage smaller businesses to get on platform | TechCrunch",
"url": "https://techcrunch.com/2023/04/05/mozart-data-announces-free-tier-to-encourage-smaller-businesses-to-get-on-platform/",
"date": "Apr 05, 2023"
},
{
"title": "Mozart Data raises $15M to help startups spin up a data stack – TechCrunch",
"url": "https://techcrunch.com/2022/04/27/mozart-data-raises-15m-to-help-startups-spin-up-a-data-stack/",
"date": "Apr 27, 2022"
}
],
"launches": [
{
"id": 80903,
"title": "Mozart Data for BigQuery",
"tagline": "End-to-end data platform with BigQuery or Snowflake under the hood",
"body": "**Mozart Data + Big Query:** \n\nDo you have GCP credits available? You can now get BigQuery, Looker, and use Mozart’s Sonata (free) offering to get your data to a central place and start your business intelligence reporting - ALL FOR FREE. \n\n\n\nThis month, we’re launching **Mozart Data for BigQuery**. This is an extension of Mozart’s core offering: a **managed data platform** with best-in-class analyst support, so teams can reliably **centralize their data** and uncover actionable insights to drive their business more successfully. \n\nWe’ve helped hundreds of companies set up their data infrastructure without hiring a data engineer. With Mozart, you can set up BI reporting to have a business overview, answer questions about what customer segments are good from a usage or advertising perspective, and even gain insight into what customers are at risk of churn. \n\n**Best In Class Modern Data Stack:** \n\nSince YC’s S20 batch, we’ve had a Henry Ford-like stance on the Model T – any color the customer wants, as long as it’s black, or any data warehouse you want so long as it’s Snowflake.\n\nWe have always believed that we should offer a best-in-class gluing together of the modern data stack, so that startups can set up their data infrastructure without a data engineer, while also being able to set up their data infrastructure quickly without being slowed by the paradox of choice.\n\n\n\n**Choose your Data Warehouse**: \n\nNow, we are changing – Mozart will help you get up and running with either Snowflake or BigQuery as your data warehouse. We want to help you use your GCP credits to get your data set up with an ETL and a data warehouse. You get first-class data infrastructure from the start without needing the data engineer to help make it happen – we’ll do it for you.\n\nAgain, the Mozart team will help you use your GCP credits and get your data infrastructure to a strong, self-sufficient state so that you can begin to use BI tools to optimize and report on your business. If using YC deals, this can be done for free.\n\n\n\n**Learn more, and sign up:** \n\nWant to learn more about Mozart Data’s product and Google BigQuery integration, or just want to chat about data infrastructure or analytics, ping [support@mozartdata.com](mailto:support@mozartdata.com).",
"url": "https://www.ycombinator.com/launches/L2t-mozart-data-for-bigquery",
"votes": 21,
"created_at": "2024-05-16T20:12:22.106Z"
},
{
"id": 70031,
"title": "Mozart Data Sonata - we set up and maintain world-class data infrastructure (ELT & Warehousing) for FREE",
"tagline": "Every company should have the ability to use a Modern Data Stack from the start",
"body": "**tl;dr:** We set up and manage your data warehouse (Snowflake), extract and load your data (Fivetran), and provide you a layer for transformation so that you can clean and organize your data before visualizing it (in your favorite tool). If you have startup data volumes and you want a free solution that sets up in less than an hour with no data engineering needed, you can do this with the Mozart Data Sonata package. [Signup for FREE](https://app.mozartdata.com/signup-sonata)!\n\n—\n\nWe’re Dan & Pete, co-founders of [Mozart Data](https://www.mozartdata.com/), and the other maestros on the Mozart team.\n\n\n\n🧠 Dan is the CTO and a product-oriented software engineer, with expertise in user experience, data engineering, and data science. He has a long history of founding and working at numerous startups across a variety of industries, including gaming (Gamador YCW10), fintech (GogoCoin 500S15), and healthcare (Clover Health CLOV). He and Pete also co-founded [Bacon Hot Sauce](https://baconhotsauce.com/) in 2010, which sold hundreds of thousands of bottles.\n\n🎯Pete aka “Fish” is the CEO and has over a decade of running data and data-adjacent teams at startups in a variety of industries. These include gaming (Playdom/Disney), social (Yammer/Microsoft), HR/benefits (Zenefits), real estate (Opendoor), cannabis (Eaze), B2B (GoDaddy), and sports (Philadelphia Eagles). He has a Ph.D. in economics and loves talking about correlation vs. causation.\n\n# What is the Modern Data Stack and why does it matter?\n\nWe jokingly say that the Modern Data Stack is about 500 logos on a VC pitch deck slide. Navigating through the noise is challenging because many of the modern tools aim to solve advanced problems that most companies never encounter. Instead, we’ve optimized the data infrastructure onboarding experience to be achievable without any data engineers or experts. Mozart will set up your data pipelines – seamlessly gluing world-class ELT, data warehousing, data transformation, data monitoring & alerting, cost-optimization, and governance all together for you. This gives you the full power of a modern data stack (Snowflake + Fivetran) even if all you know is some basic SQL, so you can focus on your specific product and business challenges.\n\n\n\nEarly examples of analysis teams do with a Modern Data Stack:\n\n* Answer basic questions (with auto-update) like: How many customers do we have? What does our revenue/cost look like over time?\n* Set up an Investor Dashboard with core metrics using Metabase to visualize\n* Set up Slack or email alerts when events happen in your application db\n* Get your Salesforce/Stripe/Shopify data syncing to GSheets\n* Reconcile how much each client is supposed to be paying and is actually paying\n* Set up a test and alert that we have a first and last name for every client (or any other necessary condition)\n* Push cleaned data about clients to a GSheet for customer service or operations teams to consume\n* View basic product funnels with Segment data through your favorite BI tool\n* Set up lead and churn (likelihood) scores for prospects and customers\n* SQL query collaborative editing with version control backed by GitHub\n* Save money on platforms that price based on seats with the same visibility into performance\n* Set up your long-term data infrastructure that can scale cost-effectively\n\nThere are many reasons to get your data infrastructure set up early. There are many quick wins from reporting, alerting, effective operations, governance, and cost-saving. With tools like Mozart Data, you can do this without data engineers. With our Sonata package, you can see the value in the data for yourself for FREE.\n\n# Our ask 🙏\n\nGive Mozart Sonata a try, [sign up here](https://app.mozartdata.com/signup-sonata)\n\n* Bonus: self-serve\n* Double Bonus: load your first data source (just credentials needed), schedule a transformation, or graph/visualize a key metric\n* Triple Bonus: share your feedback with us at [founders@mozartdata.com](mailto:founders@mozartdata.com)",
"url": "https://www.ycombinator.com/launches/IDX-mozart-data-sonata-we-set-up-and-maintain-world-class-data-infrastructure-elt-warehousing-for-free",
"votes": 50,
"created_at": "2023-03-08T00:34:43.016Z"
}
]
},
{
"id": 22632,
"name": "authzed",
"slug": "authzed",
"former_names": [
"Petricorp",
"Inc."
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/ee578b781cb190a51362b9fda6dc57b36d74972d.png",
"website": "https://authzed.com",
"all_locations": "New York City, NY, USA; Remote",
"long_description": "We build the tools companies need to provide performant and scalable authorization for their applications.\r\n\r\nWe’re founded by 3 successful entrepreneurs with expertise in enterprise software, most recently as leaders at Red Hat. Jake and Joey met on the APIs team at Google in 2010. They went on to found Quay, where Jimmy joined as their first hire. Over the past decade, they’ve changed the landscape for building and deploying software.",
"one_liner": "Authorization Infrastructure securing AI at OpenAI, Zoom, & more",
"team_size": 31,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1624982412,
"tags": [
"Developer Tools",
"Security",
"Open Source",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2021",
"status": "Active",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/authzed",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2021/authzed.json",
"year_founded": 2020,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/authzed",
"x_url": "https://twitter.com/authzed",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/authzed",
"github_url": "https://github.com/authzed",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/ee578b781cb190a51362b9fda6dc57b36d74972d.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Nicolas Dessaigne",
"url": "https://www.ycombinator.com/people/nicolas-dessaigne"
},
"founders": [
{
"user_id": 589803,
"full_name": "Jake Moshenko",
"title": "Founder",
"founder_bio": "Jake Moshenko is an engineering leader that has been building infrastructure tools and services for over 15 years for large companies and startups alike. Having previously struggled to keep up with customer permissions demands on products such as CoreOS’s Quay and Tectonic, he was searching for a better way to do application permissions.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jacob-moshenko-381161b/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/6d2259a372f5d31495f85d518256341fa0a490be.jpg"
},
{
"user_id": 597541,
"full_name": "Jimmy Zelinskie",
"title": "Founder",
"founder_bio": "Jimmy Zelinskie is a software engineer and product leader with the goal of empowering the world through the democratization of software via open source development. He's currently the CPO and cofounder of authzed where he's focused on bringing hyperscaler best-practices in authorization software to the industry at large.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jzelinskie",
"x_url": "https://twitter.com/jimmyzelinskie",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/432dc805c3a6c9f1ac4f0759f6258f3dda97d5af.jpg"
},
{
"user_id": 30633,
"full_name": "Joseph Schorr",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/joseph-s-4324904/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/a17d41b27fc6e7329ab963268732cdb742fa09d8.jpg"
}
],
"jobs": [
{
"id": 88935,
"title": "Sr. Developer Advocate (US-Based)",
"url": "https://www.ycombinator.com/companies/authzed/jobs/NoHR6wW-sr-developer-advocate-us-based",
"location": "US / Remote (US)",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "$140K - $170K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 109442,
"title": "Sr. Site Reliability Engineer",
"url": "https://www.ycombinator.com/companies/authzed/jobs/yWu2MKf-sr-site-reliability-engineer",
"location": "Remote (US)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $195K",
"equity_range": "",
"experience": "5+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 109443,
"title": "Senior Software Engineer",
"url": "https://www.ycombinator.com/companies/authzed/jobs/M49hhUO-senior-software-engineer",
"location": "Remote (US)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $190K",
"equity_range": "",
"experience": "5+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 111196,
"title": "Senior Site Reliability Engineer, Security",
"url": "https://www.ycombinator.com/companies/authzed/jobs/KSV1i4b-senior-site-reliability-engineer-security",
"location": "US / CA / Remote (US; CA)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $195K",
"equity_range": "",
"experience": "5+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 111560,
"title": "Solutions Engineer - U.S. and Canada",
"url": "https://www.ycombinator.com/companies/authzed/jobs/ena6RKJ-solutions-engineer-u-s-and-canada",
"location": "US / CA / Remote (US; CA)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$130K - $160K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
}
],
"news": [
{
"title": "Permissions management startup AuthZed raises $12M to accelerate its strategic expansion - SiliconANGLE",
"url": "https://siliconangle.com/2024/06/27/permissions-management-startup-authzed-raises-12m-accelerate-strategic-expansion/",
"date": "Jun 27, 2024"
},
{
"title": "Cockroach Labs, Authzed stress the importance of distributed SQL - SiliconANGLE",
"url": "https://siliconangle.com/2023/02/08/qa-cockroach-labs-authzed-stress-importance-distributed-sql-databases-kubecon/",
"date": "Feb 08, 2023"
},
{
"title": "Google Zanzibar Through Our Eyes - Hacker News",
"url": "https://news.ycombinator.com/item?id=33910685",
"date": "Jan 14, 2023"
},
{
"title": "SpiceDB Is Open Source - Hacker News",
"url": "https://news.ycombinator.com/item?id=28709886",
"date": "Jan 14, 2023"
},
{
"title": "Zanzibar Implementation SpiceDB Is Open Source - The New Stack",
"url": "https://thenewstack.io/zanzibar-implementation-spicedb-is-open-source/",
"date": "Oct 05, 2021"
}
],
"launches": []
},
{
"id": 22664,
"name": "SBX Robotics",
"slug": "sbx-robotics",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/511a67e1066575bd8304628248a6a9307430e18f.png",
"website": "https://www.sbxrobotics.com/",
"all_locations": "Toronto, ON, Canada",
"long_description": "SBX Robotics generates synthetic data that teaches robots to see. We use simulation software to create training data 10x faster and cheaper than annotation services or in-house teams. \r\n\r\nInstead of being blocked on data, our clients send 25 images from their robot’s camera, and receive 25,000 perfectly labeled synthetic training images. SBX data is ready to be used by deep learning computer vision models. ",
"one_liner": "Synthetic data for better vision.",
"team_size": 5,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1616603536,
"tags": [
"Machine Learning",
"Robotics",
"Computer Vision",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2021",
"status": "Inactive",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"Canada",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/sbx-robotics",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2021/sbx-robotics.json",
"year_founded": 2020,
"city": "Toronto",
"country": "CA",
"linkedin_url": "https://www.linkedin.com/company/sbx-robotics/",
"x_url": "https://twitter.com/sbxrobotics",
"fb_url": "https://www.facebook.com/sbxrobotics",
"cb_url": null,
"github_url": "https://github.com/sbxrobotics",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/511a67e1066575bd8304628248a6a9307430e18f.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 505268,
"full_name": "Ian Dewancker",
"title": "Founder",
"founder_bio": "Led applied research projects at Uber ATG, Kindred AI, and SigOpt focusing on computer vision, robotics, and optimization for machine learning. MSc in CS from UBC (2013), Engineering at Waterloo (2011).",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/ian-dewancker-7a293625/",
"x_url": "https://twitter.com/idewanck",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ce1cb43c50d3095ef0d94605e68ac0441a8ddb52.jpg"
},
{
"user_id": 592065,
"full_name": "Artem Avdacev",
"title": "Founder",
"founder_bio": "Building something new in the intersection of computer vision, robotics, and computer graphics (games & VFX)\n\nBefore SBX, I spent 7 years at Yelp fighting fraud and fake reviews as an engineer & PM, and then took off to sail across the pacific ocean, dive with sharks, and hike the himalayas.\n\nBased in Montreal, Canada.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/aavdacev/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/6e9aacf2d05b25f3418f216e7499b0a70e252072.jpg"
},
{
"user_id": 436601,
"full_name": "Joshua Kuntz",
"title": "Founder",
"founder_bio": "- Canadian\n- Waterloo\n- Wish\n- SBX Robotics (current)",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/joshua-kuntz-92603816/",
"x_url": "https://twitter.com/j3kuntz",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/8a45e9f8c3a47af89eda7bce83eefd18427d0644.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 22771,
"name": "Avenue",
"slug": "avenue",
"former_names": [
"Avenue Technologies"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/e5f67e2ce27f5eb8afbeff838eb65ceab7f77903.png",
"website": "https://avenue.app/",
"all_locations": "New York City, NY, USA; New York, NY, USA",
"long_description": "Avenue is a simple way for business teams to set up alerts from their database or data warehouse. Think Datadog / PagerDuty for operations teams.\r\n\r\nOperations teams create set-and-forget alerts on all their data, so they can be more proactive with their time (and monitor on more nuanced triggers than just what fits on their dashboard page).\r\n\r\nAvenue can improve response times to critical problems from several days to real-time by alerting directly on the data sources that customers already use.",
"one_liner": "Observability platform for operations teams",
"team_size": 8,
"industry": "B2B",
"subindustry": "B2B -> Operations",
"launched_at": 1614620141,
"tags": [
"Developer Tools",
"SaaS",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2021",
"status": "Acquired",
"industries": [
"B2B",
"Operations"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/avenue",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2021/avenue.json",
"year_founded": 2020,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/useavenue",
"x_url": "https://twitter.com/useavenue",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/e5f67e2ce27f5eb8afbeff838eb65ceab7f77903.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 339066,
"full_name": "Justin Bleuel",
"title": "Founder/CEO",
"founder_bio": "people-first",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/justin-bleuel-6a403431/",
"x_url": "https://twitter.com/JustinBleuel",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b6892d79b519bddb893f9ad30da55b0de0ddec4e.jpg"
},
{
"user_id": 303023,
"full_name": "Jeff Barg",
"title": "Founder",
"founder_bio": "Co-founder & CTO of Avenue, an observability platform for operations teams. We let ops teams connect their data sources, define alerts, and respond proactively to important events. We are currently hiring software engineers to build the future of ops tooling.\n\nPreviously, I was a software engineer at Amazon working on the Alexa AI team. Along with my co-founder Justin, I also built and marketed several iOS apps when we were in high school, amassing 300k+ downloads.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/jeffreybarg/",
"x_url": "https://twitter.com/jeffbarg/",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9cdac7cf0892d7c7c7edbbda6eb0be7f29a9aaef.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Operations observability platform Avenue launches with $4M – TechCrunch",
"url": "https://techcrunch.com/2021/09/24/operations-observability-platform-avenue-launches-with-4m/amp/#click=https://t.co/mxHnZfqC6t",
"date": "Sep 24, 2021"
}
],
"launches": []
},
{
"id": 22772,
"name": "Prequel",
"slug": "prequel",
"former_names": [
"Vigo"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/adf6a0c470e58a697fb3d5dfb5dbbe734d9aa0fd.png",
"website": "https://prequel.co",
"all_locations": "New York City, NY, USA; New York, NY, USA",
"long_description": "Prequel makes it easy for companies to share data with their customers. It helps you export data directly to your customer's Snowflake, Redshift, BigQuery, Databricks, or other data warehouse on an ongoing basis.",
"one_liner": "Helping B2B co's sync data to their customers",
"team_size": 9,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1614619481,
"tags": [
"SaaS",
"Analytics",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2021",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/prequel",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2021/prequel.json",
"year_founded": 2020,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/prequel-co/about/",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/adf6a0c470e58a697fb3d5dfb5dbbe734d9aa0fd.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 595588,
"full_name": "Charles Chretien",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/charles-chretien-94350146/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ba40b38930f95a87929426b5b706b501aec5d1a6.jpg"
},
{
"user_id": 595584,
"full_name": "Conor McCarter",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/conormccarter/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/a2cac2ee280d5b3d924bb1024940338352b7397f.jpg"
}
],
"jobs": [
{
"id": 43482,
"title": "Senior Software Engineer",
"url": "https://www.ycombinator.com/companies/prequel/jobs/VNoKffl-senior-software-engineer",
"location": "New York City",
"type": "Full-time",
"role": "Engineering",
"role_type": "Backend",
"salary_range": "$150K - $220K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
}
],
"news": [],
"launches": []
},
{
"id": 23041,
"name": "Platypus",
"slug": "platypus",
"former_names": [
"ProcessLabs"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/fa8d744e8f842398dd0f47dc4ec6415a9bdaa423.png",
"website": "https://www.getplatypus.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "For Business Operators: Connect & automate processes on top of any data, crazy fast.\r\n\r\nFor Engineering Teams: Connect any data, across any stack, in any format, crazy fast.",
"one_liner": "The Distributed Data Operating System",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1615308252,
"tags": [
"B2B",
"Workflow Automation",
"Data Engineering",
"AI Assistant"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2021",
"status": "Inactive",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/platypus",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2021/platypus.json",
"year_founded": 2019,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/getplatypus",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/fa8d744e8f842398dd0f47dc4ec6415a9bdaa423.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 68620,
"full_name": "Pablo Ferrari",
"title": "Founder",
"founder_bio": "Eclectic Engineer.\nCurrently director of engineering and staff engineer at Together,ai\n\nFormer management consultant at Bain & Company and AI consultant for the big firms.\n\nCo-founded the first credit scoring platform in Spain, Ibercheck, and the Spanish Shopify Tiendalista.\n\nYC W21 with multiple pivots, among them Processlabs.ai for dev teams, and Platypus the first data engineer AI agent.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/pablo-ferrari/",
"x_url": "https://twitter.com/pabloferrari",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/4d1f9a616a4debc2c3fd2c6cc9a67674bf1e0bad.jpg"
},
{
"user_id": 548679,
"full_name": "Deepanshu Madan",
"title": "Founder",
"founder_bio": "Entrepreneur, full-stack software engineer, and Product Manager for developer tools, and enterprise AI agent products.\n",
"is_active": false,
"linkedin_url": "https://linkedin.com/in/deepanshumadan",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b1962a1ffdcef6cf8ec0b97cf5b0430c3cfab51d.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 79931,
"title": "Platypus: The distributed data operating system",
"tagline": "Data toolkit to manage distributed and real-time data 10x faster.",
"body": "### **Platypus - The Distributed Data Operating System**\nPlatypus is a toolkit to help data engineers and technical founders manage their distributed and real-time data 10x faster. We help you organize and connect any data, across any stack, in any format. Fast.\n\n### **We are Looking for Feedback and Early Users**\nWe are offering Customized Support for our Early Access Program to founders and data engineering teams dealing with real-time and distributed data challenges - contact us at or [send me an email](mailto:pablo@getplatypus.com).\n\n### **The Problem**\nManaging distributed data is tough and costly in an ever-evolving landscape where the concept of a \"modern\" data stack is rapidly aging, requiring **expert teams, multiple tools, and expensive resources**. On top of that, the Business teams **struggle to access** and use this data effectively.\n\n### **The Solution**\n**A** **customizable,** **real-time** **data platform that** **boosts data engineering productivity**. We simplify data with automation for data discovery, data management, and data pipeline creation while keeping data engineers in full control of their data architecture. We also allow business teams to self-serve the data and data activation they need.\n\n### **Any Data, Any Stack, Any Client.**\n\n\n\n\n\n\n\n### **Our Team**\n\nWe are data engineers with experience at big tech companies like Amazon and Intel. We’re eager to tackle your data challenges, from simple database replications to complex AI-driven data strategies.\n\nWe know our craft, we love it, and we want to help with your specific data challenges.\\\n - [pablo@getplatypus.com](mailto:pablo@getplatypus.com)",
"url": "https://www.ycombinator.com/launches/KnD-platypus-the-distributed-data-operating-system",
"votes": 5,
"created_at": "2024-04-03T23:03:20.517Z"
}
]
},
{
"id": 23550,
"name": "Clear",
"slug": "clear",
"former_names": [
"Quill",
"haut"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/04169b13bb38d8ba7da4e38bb6ab9eafa9c93938.png",
"website": "https://getclearapp.com/",
"all_locations": "London, England, United Kingdom; Remote",
"long_description": "On the surface, Clear is a free mobile app where consumers track routines, products and selfies, get brand-agnostic recommendations, and learn from others in the community. Underneath, we’re building a vertically focused AI/data platform that helps consumers, clinicians, and brands understand what actually works, for whom, and why.\r\n\r\nThe skincare industry is worth over $200B globally, yet it still runs largely on guesswork: consumers waste money on trial-and-error, brands lack real-world evidence, and dermatologists have limited visibility into day-to-day product use and outcomes.\r\n\r\nClear is brand-agnostic, data-rich, and community-driven. Every routine log, product review, and progress update helps create a unique longitudinal dataset across skin concerns, routines, and outcomes - powering better decisions for users and better innovation for the wider industry.\r\n\r\nWe were the 2022 L’Oréal Beauty Tech for Good winners, have been recognised by Beiersdorf, and have been featured multiple times by Apple, including App of the Day and Best New Apps.",
"one_liner": "The unbiased AI and data layer for skin health.",
"team_size": 2,
"industry": "Consumer",
"subindustry": "Consumer -> Social",
"launched_at": 1624200731,
"tags": [
"Marketplace",
"Consumer",
"Digital Health",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2021",
"status": "Active",
"industries": [
"Consumer",
"Social"
],
"regions": [
"United Kingdom",
"Europe",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": true,
"app_answers": null,
"question_answers": [
{
"question": "How did your company get started? (i.e., How did the founders meet? How did you come up with the idea? How did you decide to be a founder?)",
"answer": "Clear's journey traces back to my own experiences and passion for technology and skincare. As I transitioned from studying physics at Imperial College London to delving into tech, finance and startups, I encountered a personal struggle with skin issues (cystic acne) that persisted for over a decade. I had tried everything; from diets, to medications, to products to try and improve my skin, but had great trouble in identifying if what I was trying was actually working. Having turned to online social media skincare communities for support, I knew I wasn’t alone. So, this struggle, coupled with a genuine desire to help others navigate their skincare journeys with confidence, ignited the idea behind Clear; an app that helped people to track their skincare routine, skin progress, access a community of like-minded individuals on a similar journey, and get data-driven, unbiased product recommendations.The vision was not only to provide users with personalized skincare recommendations but also to fuel innovation in the industry, enabling brands to create more effective product formulations. My personal connection to the mission, being my own customer, fueled my decision to become a founder. Clear is more than a company; it's a commitment to revolutionizing skincare and empowering individuals on their path to healthier skin."
},
{
"question": "How did you decide to apply to Y Combinator? What was your experience applying, going through the batch, and fundraising at demo day?",
"answer": "The decision to apply to Y Combinator was driven by a combination of factors, including the belief in Clear's mission and the recognition of Y Combinator's unparalleled reputation for nurturing and propelling innovative startups. The application process was rigorous, requiring a clear articulation of our vision, market potential, and the problem we aimed to solve. Going through the Y Combinator batch was a transformative experience, marked by intense mentorship, invaluable insights, and a supportive community of fellow founders.Fundraising at Demo Day was a pivotal moment in Clear's journey. Presenting our vision to numerous, influential investors provided a platform to showcase the potential impact of Clear in the skincare industry. The experience not only facilitated crucial funding but also opened doors to valuable connections and partnerships. Y Combinator played a pivotal role in shaping Clear's trajectory, contributing to its growth and success in the dynamic startup ecosystem."
},
{
"question": "How have you kept in touch with the YC community and continued to use YC resources & programs since the batch ended?",
"answer": "Staying connected with the Y Combinator community has been integral to Clear's ongoing success. Post-batch, I actively participate in YC alumni events, forums, and networking opportunities, fostering relationships with fellow founders and leveraging the collective wisdom of the community. The YC network remains a valuable source of insights, mentorship, and potential collaborations.Additionally, Clear continues to benefit from YC resources and programs. From access to YC's extensive network of experts to ongoing mentorship opportunities, these resources have been instrumental in navigating challenges and seizing growth opportunities. The continuous engagement with the Y Combinator ecosystem underscores the enduring support and collaborative spirit that define the YC community."
},
{
"question": "What's the history of your company from getting started until the present day? What were the big inflection points?",
"answer": "Our journey began with a vision to revolutionize the skincare experience, a vision that culminated in the creation of Clear, a mobile app designed to empower individuals in their skincare journeys. Founded by Ahana Banerjee, an alumna of Imperial College London, Y Combinator, and a Forbes 30 Under 30 awardee, Clear is more than an app—it's a community-driven platform reshaping how people buy, track, and share their skincare routines.From its inception, Clear has pioneered features that make it the Strava for skincare, offering users a comprehensive platform with selfie analysis data providing insights to cosmetic brands.Our growth story is one of organic success, with 10,000+ users achieved without any paid acquisition or marketing hires. We've been featured as one of the \"Best New Apps\" in the US App Store in 2023, underscoring our impact and relevance in the skincare space.Our community is at the heart of our success, contributing to over 500,000+ routine check-ins and 32,000+ posts, fostering engagement among skincare enthusiasts. The industry has taken notice, with Clear winning the L'Oréal Beauty Tech for Good Challenge and Beiersdorf Beauty Tech Innovation Summit, leading to invaluable partnerships and recognition.As we continue our journey, Clear remains committed to innovation, community building, and revolutionizing how individuals approach and engage with skincare. We're not just an app; we're a movement reshaping the future of skincare."
},
{
"question": "What is the core problem you are solving? Why is this a big problem? What made you decide to work on it?",
"answer": "The core problem Clear addresses stems from a lack of clarity and communication within the skincare landscape. Consumers find themselves grappling with uncertainty about which skincare products to use and whether these products are effective. Simultaneously, skincare brands face a challenge in understanding their consumers, hindering industry-wide innovation. Dermatologists, too, encounter difficulties in efficiently communicating with their patients.\\\\This problem is substantial because it permeates the entire skincare ecosystem. For consumers, the ambiguity around product efficacy can lead to frustration and wasted resources. Skincare brands, without a clear understanding of consumer behavior, struggle to innovate and tailor their products to meet genuine needs. Dermatologists, the experts in skincare, face inefficiencies in conveying information and prescribing effective routines.\\\\The decision to tackle this pervasive issue arose from a personal connection and a broader recognition of its widespread impact. I personally endured the challenges of skincare struggles, which fostered a deep empathy for others facing similar dilemmas. Recognizing the industry-wide ramifications of this problem, the decision to create Clear was driven by a passion for revolutionizing skincare journeys, providing clarity for consumers, empowering brands with actionable insights, and facilitating seamless communication between dermatologists and their patients.Clear's mobile app acts as a transformative solution by offering routine tracking and a dynamic social community. This platform enables users to objectively measure their skincare progress, connect with a supportive community, and receive data-driven product recommendations. For skincare brands, Clear becomes a conduit for real-time insights into consumer behavior and sentiment, leveraging product usage metrics and user-generated content. Moreover, Clear facilitates secure sharing of routine and progress data between users and medical professionals, allowing dermatologists to prescribe effective skincare routines seamlessly.In essence, Clear emerges as the bridge that resolves the communication gaps in the skincare industry, providing users with confidence in their skincare choices, brands with valuable insights, and dermatologists with efficient tools to enhance patient care in this $200B industry."
},
{
"question": "What is your long-term vision? If you truly succeed, what will be different about the world?",
"answer": "Clear's overarching vision extends beyond being a solution for current skincare challenges. Our aim is to become synonymous with skincare, a pervasive force in a $200 billion market. The long-term vision for Clear envisions a comprehensive ecosystem that transcends conventional boundaries. From being a single source of truth for skincare recommendations and self-tracking to delving into teledermatology, operating an expansive e-commerce marketplace, introducing a rewards program, curating engaging skincare content, entering the skincare market, and fostering industry-wide innovation through data-driven insights – Clear aspires to redefine and elevate every facet of the skincare experience.As Clear achieves its long-term vision, the world of skincare will undergo a transformative shift. The pervasive uncertainty and inefficiencies plaguing the skincare industry will dissipate, replaced by a seamlessly integrated ecosystem that empowers consumers, brands, and dermatologists alike. Individuals navigating their skincare journeys will find clarity and confidence, supported by personalized recommendations and a supportive community. Skincare brands will experience heightened innovation and responsiveness, guided by real-time insights into consumer behavior. Dermatologists will leverage efficient tools for communication and care, enhancing the patient experience. Ultimately, the success of Clear will usher in a new era where skincare is not just a routine but a personalized, data-driven, and collaborative journey, positively impacting millions and redefining the standards of skincare excellence."
}
],
"url": "https://www.ycombinator.com/companies/clear",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2021/clear.json",
"year_founded": 2021,
"city": "London",
"country": "GB",
"linkedin_url": "https://www.linkedin.com/company/clear-app",
"x_url": "https://twitter.com/getclearapp",
"fb_url": "https://www.facebook.com/getclearapp",
"cb_url": "https://www.crunchbase.com/organization/clear-6311",
"github_url": "https://github.com/Haut-Technologies",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/04169b13bb38d8ba7da4e38bb6ab9eafa9c93938.png",
"app_video_url": null,
"dday_video_url": "https://bookface-images.s3.us-west-2.amazonaws.com/video_event/54/1630619012886-x9jl4wcqzs-2477078dfbba57e3f28e3f18b7c7f142/89bd2b8e4a75e11459f76522bbb5eaf7.mp4?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=AKIAQC4NIECABPQ2AHNW%2F20261020%2Fus-west-2%2Fs3%2Faws4_request&X-Amz-Date=20261020T022655Z&X-Amz-Expires=3600&X-Amz-SignedHeaders=host&X-Amz-Signature=b696f2c98d80023e7eefc3de7cc5403717b9b578d496fbb2980e3e1841f4f851",
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/4934d44099c14c78252f049ded8cbb6f50c716dd.png"
],
"primary_partner": null,
"founders": [
{
"user_id": 543078,
"full_name": "Ahana Banerjee",
"title": "Founder",
"founder_bio": "Skincare enthusiast and Imperial College London Physics grad",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ahana-banerjee/",
"x_url": "https://twitter.com/ahanabanana",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/98df9114da002d6527c0153d444b6d77e665bd2b.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Meet Ahana Banerjee and Ben Richards: The Imperial Physics Students Who launched A Skincare Tracking App – Positive World",
"url": "https://positiveworldonline.com/2021/06/30/meet-ahana-banerjee-and-ben-richards-the-imperial-physics-students-who-launched-a-skincare-tracking-app/",
"date": "Jun 30, 2021"
},
{
"title": "Imperial Physics students launch skincare tracking app | Imperial News | Imperial College London",
"url": "https://www.imperial.ac.uk/news/223913/imperial-physics-students-launch-skincare-tracking/",
"date": "Jun 29, 2021"
}
],
"launches": [
{
"id": 91922,
"title": "Clear: Track and Share your Skincare",
"tagline": "Meet Clear - the skincare app that helps you track, learn, and finally see what works.",
"body": "🚀 **We just launched Clear Premium: the smarter way to track your skincare, discover what actually works, and feel confident in your skin.**\n\n👋 Hi everyone, I’m Ahana, founder of [Clear](https://getclearapp.com/), a skincare app helping tens of thousands of people take control of their skin through tracking, education, and community. We’re YC W21, and today, we’re launching something big: **Clear Premium**.\n\n### **💡 The Problem**\n\nSkincare is broken. People spend hundreds on products, but don’t know what’s working, what’s causing breakouts, or how to personalise their routine. Skin is complex, and most advice is vague, biased, or not designed for people of colour.\n\nAs someone who struggled with acne for years, I found myself wishing there was a way to _track_ my skin, get _honest_ recommendations, and see _real_ results over time.\n\n\n\n### **🧪 What We’ve Built**\n\n**Clear** is the app I wish I had when I was struggling.\n\nWith Clear, you can:\n\n* Log your routine + products\n* Take progress photos\n* Get ingredient breakdowns\n* Learn from a diverse, supportive skincare community\n\nAnd now, with **Clear Premium**, we’re giving people even more power:\n\n🔓 **Premium Features:**\n\n* Track unlimited progress photos\n* Smart routine analytics: see what’s really helping (or hurting) your skin\n* Compare products and ingredients side-by-side\n* Scan products for instant info\n* Export your routine and skin journal\n* More customisation, better insights, and no guesswork\n\n🎥 [Watch our premium launch video](https://youtu.be/8CzArSSg4ws?si=_VaCOIKZqzvai6jk)\n\n### **🛠️ Why We Built It**\n\nFor the past 3 years, we’ve grown Clear with very little marketing - just word-of-mouth from a passionate, underserved community. We’ve been used by 50K+ people across 100+ countries, featured on the App Store, and recently partnered with top dermatologists to help people get clinical guidance too.\n\nThis launch is a huge milestone for us. It’s our next chapter - one that gives our community more tools, more control, and a way to stop wasting time and money on trial and error.\n\n### **🎁 14-Day Free Trial**\n\nClear Premium is available now, and **every new member gets a 14-day free trial**. No strings attached. Just download the app and start exploring.\n\n📲 [Try Clear Premium now](https://getclearapp.com/premium)\n\n💌 Want to chat, collab or share feedback? Reach me at [ahana@getclearapp.com](https://mailto:ahana@getclearapp.com)\n\n---\n\n### **🙏 Asks**\n\nIf you know someone who’s struggling with their skin, or just skincare-curious, send them Clear. If you’re building in health/wellness/consumer tech and want to jam, I’d love to connect. And if you’ve launched a consumer subscription product recently, I’d love to hear what worked for you.\n\nThanks so much to the YC community for supporting us all the way from a 4-day-old idea to this launch, 4 years later 💙",
"url": "https://www.ycombinator.com/launches/Nuc-clear-track-and-share-your-skincare",
"votes": 15,
"created_at": "2025-07-07T15:44:12.777Z"
}
]
},
{
"id": 23950,
"name": "Pipekit",
"slug": "pipekit",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/04ac699768ee01bea09ec4c32c01f02b31efebd7.png",
"website": "https://pipekit.io",
"all_locations": "Remote",
"long_description": "Our app manages Argo Workflows for data teams, enabling complex data &\r\n CI pipelines in half the time while saving companies hundreds of thousands of dollars annually. We maintain Argo Workflows, an open-source pipeline framework for Kubernetes that’s used in production by Bloomberg, Intuit, Adobe, New Relic, NVIDIA, and many other open-source early adopters. ",
"one_liner": "Pipekit scales data & CI pipelines for enterprises",
"team_size": 9,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1630089531,
"tags": [
"Developer Tools",
"Open Source",
"Data Engineering",
"DevOps"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2021",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/pipekit",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2021/pipekit.json",
"year_founded": 2020,
"city": null,
"country": null,
"linkedin_url": "https://www.linkedin.com/company/pipekit-io/",
"x_url": "https://twitter.com/pipekitio",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/pipekit",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/04ac699768ee01bea09ec4c32c01f02b31efebd7.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Aaron Epstein",
"url": "https://www.ycombinator.com/people/aaron-epstein"
},
"founders": [
{
"user_id": 735277,
"full_name": "Caelan Urquhart",
"title": "Founder",
"founder_bio": "Co-founder, CEO @ Pipekit (S21) (https://pipekit.io)\nex-Kite, Expo, McKinsey\nFunctional strengths: community, marketing, ops, finance\nIndustry experience: dev tools, OSS, digital health",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/caelan-urquhart/",
"x_url": "https://twitter.com/caelanu",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/15bcfebadf740bde049ad5e61b9b61010c31a3cc.jpg"
},
{
"user_id": 387562,
"full_name": "J.P. Zivalich",
"title": "Founder/CTO",
"founder_bio": "Founder, CTO @ Pipekit (S21) (https://pipekit.io)\nex-Docker\nIndustry experience: Dev tools, OSS, investment banking",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jpzivalich/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/2a9000f2a63a831fd0ad88d3ef2f594c7dc39ed9.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 24156,
"name": "Lariat Data",
"slug": "lariat-data",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/48e2e81fa04d812d60bdd7e093944b8090c8742d.png",
"website": "https://www.lariatdata.com",
"all_locations": "New York City, NY, USA",
"long_description": "Lariat is a Continuous Data Quality monitoring platform to discover data bugs before your consumers do. Ensure data products don’t break even as business logic, input data and infrastructure change.\r\n\r\nUse Lariat to define and then automatically extract, store and visualize data quality metrics on raw event-level data through to delivered data products.\r\n",
"one_liner": "Observability for Data Engineering Teams",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1626560864,
"tags": [
"Machine Learning",
"Big Data",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2021",
"status": "Inactive",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/lariat-data",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2021/lariat-data.json",
"year_founded": 2021,
"city": "New York City",
"country": "US",
"linkedin_url": "",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/48e2e81fa04d812d60bdd7e093944b8090c8742d.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 283225,
"full_name": "Aaditya Talwai",
"title": "Founder",
"founder_bio": "Co-founder & Chief Technology Officer, Lariat Data. \n\nAaditya has spent 10 years of his career building DevOps and developer infrastructure products. He was previously a software architect at Datadog, helping launch and scale the APM product across 100+ software runtimes and integrations. He has also built developer-facing products at Confluent and Bloomberg. He leads the technical team at Lariat Data, guiding product and architecture direction.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/talwai",
"x_url": "https://twitter.com/AadityaTalwai",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/53586e1009253153eb206d40d628e8e4aab543d1.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 24159,
"name": "Patterns",
"slug": "patterns",
"former_names": [
"Snapdata",
"Basis",
"Patterns",
"Atoma"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/55e8a16f61ac33cced5393c8d68ea9f0899f1e49.png",
"website": "https://patterns.app/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Patterns revolutionizes financial analysis by making it easy and accessible through natural language. We are seeking passionate individuals excited about simplifying financial analytics and transforming business intelligence. If you're interested in joining an innovative team in the finance space, explore our job openings and become part of our mission.\r\n\r\nOur advanced AI transforms financial data workflows and reporting, surpassing traditional spreadsheets and inflexible SaaS solutions. By integrating state-of-the-art LLMs with autonomous querying and financial reasoning, Patterns empowers practitioners to perform complex analyses effortlessly via a natural language interface.",
"one_liner": "Next-Gen Financial Analysis and Reporting with AI Agents",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1627403220,
"tags": [
"Analytics",
"Data Science",
"Data Engineering",
"Data Visualization"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2021",
"status": "Inactive",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/patterns",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2021/patterns.json",
"year_founded": 2021,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/atoma-ai/",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/55e8a16f61ac33cced5393c8d68ea9f0899f1e49.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 52795,
"full_name": "Ken Van Haren",
"title": "Founder",
"founder_bio": "Founder @ Patterns. Previously Square, Google, stats PhD @ Duke.",
"is_active": false,
"linkedin_url": "http://linkedin.com/in/kenvanharen",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/55451e2f3a29d444202af141e90902291148139d.jpg"
},
{
"user_id": 43909,
"full_name": "Chris Stanley",
"title": "Founder",
"founder_bio": "",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/chris-stanley",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/339f8dca62b76beeedc6c36bbf4dd04f64ded934.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Y Combinator–backed Patterns is building a platform to abstract away data science busywork | TechCrunch",
"url": "https://techcrunch.com/2023/03/09/y-combinator-backed-patterns-is-building-a-platform-to-abstract-away-data-science-busywork/",
"date": "Mar 09, 2023"
}
],
"launches": []
},
{
"id": 24191,
"name": "Secoda",
"slug": "secoda",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/4b049a52be34bb701fef7828f1cea14c3624e5f6.png",
"website": "https://secoda.co",
"all_locations": "Toronto, ON, Canada",
"long_description": "We believe that finding the right data shouldn’t require a technical background or hours of digging. That’s why Secoda applies AI to transform messy, siloed analytics into a searchable, intuitive knowledge layer—so every question gets a fast, useful answer.\r\n\r\nOur vision is to become the AI search engine for your company’s analytics, making data discovery as seamless as finding a website on Google. To do that, Secoda gets data AI-ready by unifying governance, cataloging, observability, and lineage into one trusted, easy-to-use platform—empowering every team to move faster, stay compliant, and make smarter decisions.",
"one_liner": "Secoda is the AI layer for your Analytics",
"team_size": 27,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1626792128,
"tags": [
"SaaS",
"B2B",
"Analytics",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2021",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"Canada",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/secoda",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2021/secoda.json",
"year_founded": 2021,
"city": "Toronto",
"country": "CA",
"linkedin_url": "https://www.linkedin.com/company/secodahq",
"x_url": "https://twitter.com/SecodaHQ",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/secoda",
"github_url": "https://github.com/secoda",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/4b049a52be34bb701fef7828f1cea14c3624e5f6.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Nicolas Dessaigne",
"url": "https://www.ycombinator.com/people/nicolas-dessaigne"
},
"founders": [
{
"user_id": 703944,
"full_name": "Etai Mizrahi",
"title": "Founder",
"founder_bio": "Founder of Secoda",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/etai-mizrahi-07656aa1/",
"x_url": "https://twitter.com/MizrahiEtai",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/e2770f3052f930db5339baaa0c21483c2f9f0736.jpg"
},
{
"user_id": 357036,
"full_name": "Andrew McEwen",
"title": "Founder",
"founder_bio": "https://secoda.co",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/armcewen",
"x_url": "https://twitter.com/andrew_mcewen",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/2fccefd3872a2d00e39f8b8f1fd7e5ac6f786376.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Secoda raises a $14M Series A and introduces Monitoring | Secoda",
"url": "https://www.secoda.co/blog/secoda-series-a-monitoring",
"date": "Sep 21, 2023"
},
{
"title": "Secoda secures $2.75 million for “Google-like” data search tool",
"url": "https://betakit.com/secoda-secures-2-75-million-for-google-like-data-search-tool/",
"date": "Dec 13, 2021"
}
],
"launches": []
},
{
"id": 24195,
"name": "Tarsal",
"slug": "tarsal",
"former_names": [
"V-diff",
"vdiff"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/75747b61e59eadbd8831c406fbe1beed2fd4957b.png",
"website": "https://www.tarsal.co/",
"all_locations": "New York City, NY, USA; San Francisco, CA, USA; Remote",
"long_description": "Tarsal is a data pipeline custom built for security teams. As security data grows 25% year over year, security teams desperately need access to best-in-class data infrastructure. Tarsal bridges the gap between the modern data stack and security teams, pioneering the modern security data stack. \r\n",
"one_liner": "Data pipeline for your security data lake.",
"team_size": 10,
"industry": "B2B",
"subindustry": "B2B -> Security",
"launched_at": 1680491615,
"tags": [
"B2B",
"Cybersecurity",
"Big Data",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2021",
"status": "Acquired",
"industries": [
"B2B",
"Security"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/tarsal",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2021/tarsal.json",
"year_founded": 2021,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/tarsal/",
"x_url": "https://twitter.com/tarsalhq",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/75747b61e59eadbd8831c406fbe1beed2fd4957b.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 504645,
"full_name": "Sunny Rekhi",
"title": "Founder",
"founder_bio": "cofounder/CEO of Tarsal (acq)",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/sunny-rekhi/",
"x_url": "https://twitter.com/sunnyrekhi",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/7871e148fe5e8bc56d0a7ff53112f6ed73439faa.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Tarsal Raises $6 Million for Security Data Movement Platform - SecurityWeek",
"url": "https://www.securityweek.com/tarsal-raises-6-million-for-security-data-movement-platform/",
"date": "Mar 21, 2024"
}
],
"launches": [
{
"id": 71058,
"title": "Tarsal: Data pipeline built for modern security teams",
"tagline": "Run your SIEM on a generic data lake with one-click connectors that normalize your logs to a unified schema",
"body": "### **TL;DR:**\n\n[**Tarsal**](https://tarsal.co) **is the first data pipeline built for modern security teams.** We’re like Fivetran or Segment, but built for security teams.\n\nTarsal provides:\n\n\\- one-click ingestion and normalization for all security logs (e.g multi-cloud infra, Okta, Duo, Slack, CrowdStrike, etc.)\n\n\\- normalization _across_ sources for easy correlation\n\n\\- detections as code\n\n\\- a vendor-agnostic pipeline so you can use the best log destination for the job (supported destinations include Snowflake, S3, Databricks, Splunk, DataDog, etc.) \n\n### 👤 **The Team**\n\n[**Sunny Rekhi**](https://www.linkedin.com/in/sunny-rekhi/) **(CEO)** was previously an infrastructure + backend engineer at TikTok and Uber, where he worked on high scale data systems.\n\n[**Manny Gundampalli**](https://www.linkedin.com/in/manny-gundampalli-6a982019b/) **(CTO)** was previously a data infrastructure engineer at Plaid, where she worked on Plaid’s highest volume ML pipelines.\n\n### **❌ The Problem**\n\n**Security data has become unmanageable.**\n\n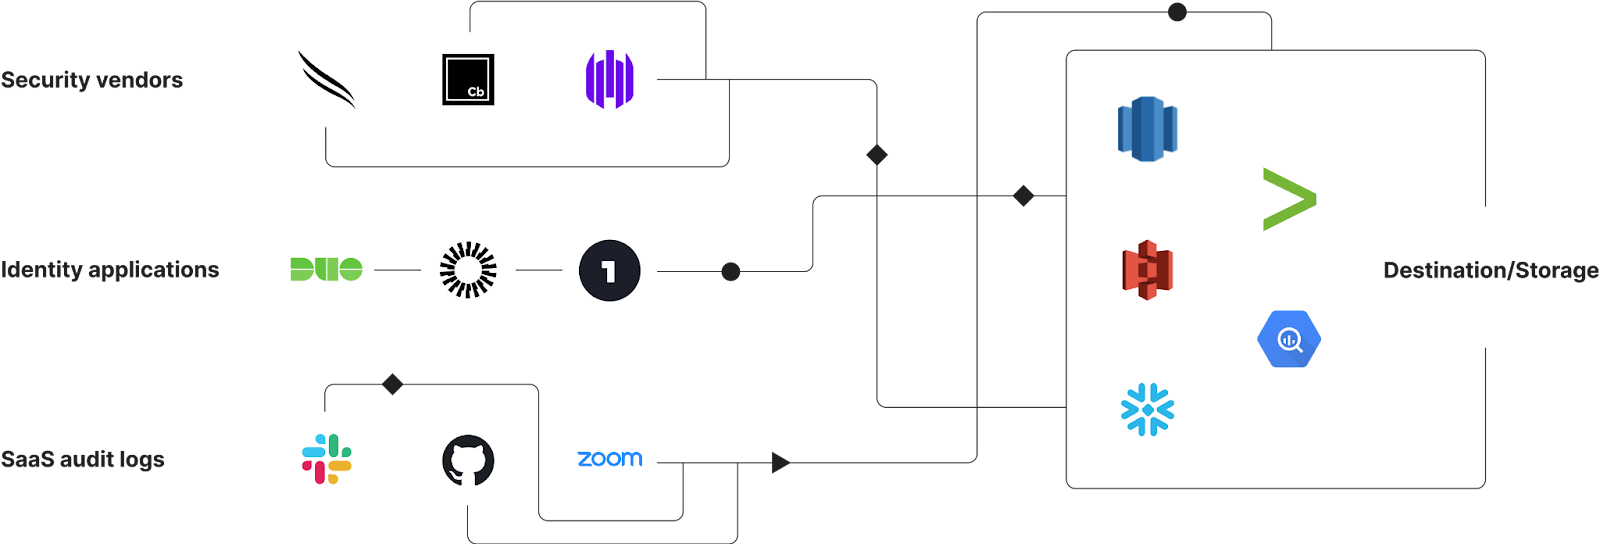\n\n* There’s no standard for how security data is defined, so security teams have to write complex queries to account for all the variations.\n* There’s no consistent way to get your log data: some vendors expose a REST API, others expose a GraphQL API. Some give you JSON data, some give you unstructured text. Schematized data is rare.\n* There’s _a lot_ of it. Security data is growing at 23% CAGR, and log storage costs are incredibly high.\n\n## **✨ Our Solution**\n\n[**Tarsal**](https://tarsal.co) is the first data pipeline built for modern security teams. With zero-hassle, one-click connectors, security teams can ingest normalized data and route it to the destination of their choice.\n\n**Our unified schema is specifically designed to reduce the complexity in incident response.** By normalizing a set of standard fields across all log sources, security teams no longer have to write complex queries to track an incident across their systems. Query once against Tarsal fields — let us figure out how that maps back to the original data.\n\n**We save you money on log storage costs by letting you route logs to the cheapest destination.** With data growing 23% year over year, organizations face ballooning infrastructure cost. Tarsal lets you filter + route logs to any of our supported destinations, including major SIEMs, Amazon S3, or a modern data warehouse like Snowflake, BigQuery, or Databricks.\n\n**Tarsal lets you write real-time detections as code.** Write expressive and flexible detections in Python for needs specific to your enterprise. Benefit from pre-built detections that are mapped to specific threats.\n\n**We alert you if anything breaks in your log ingestion.** Rest assured that you’re collecting the data you’d need during an incident. Set up Slack or PagerDuty alerts if any of your logs stop syncing over.\n\n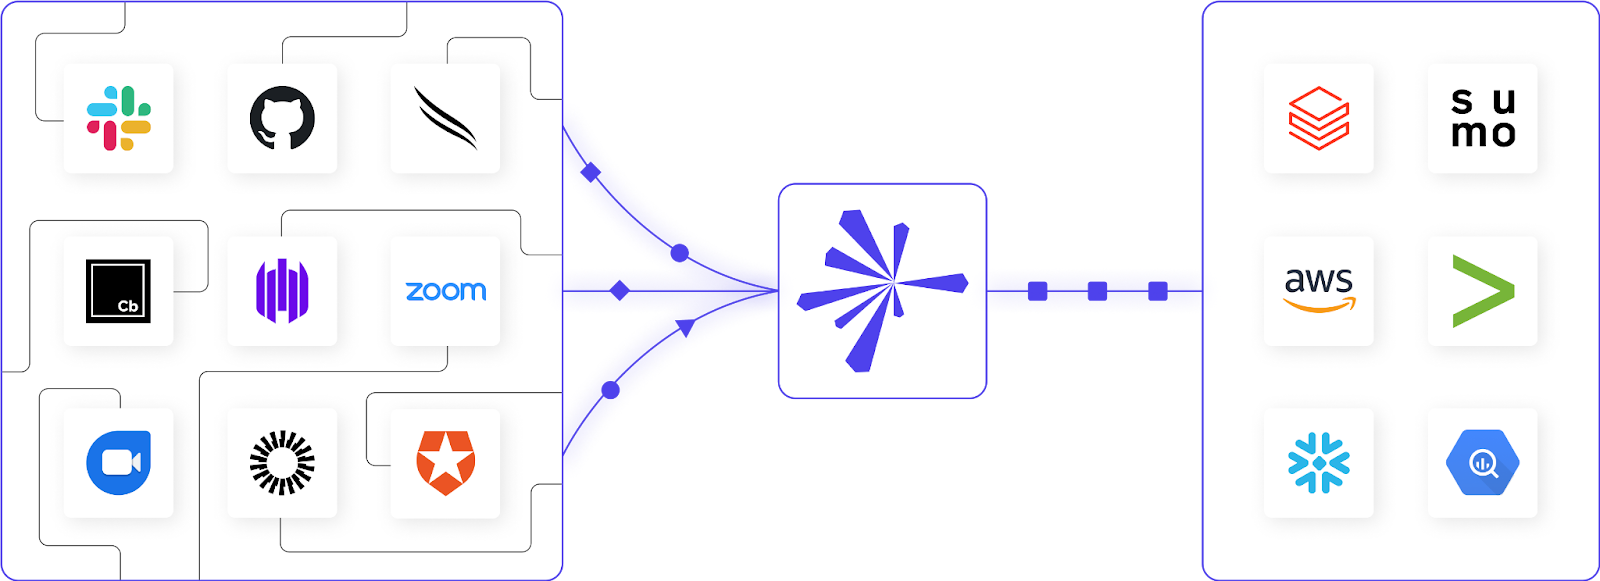\n\n### **🎉 Interested?**\n\nEmail us at [founders@tarsal.co](mailto:founders@tarsal.co) and we’ll give you a link to sign up. You can also a book a call with me [here](https://calendly.com/rohit-rekhi/30min) to learn more.",
"url": "https://www.ycombinator.com/launches/IU6-tarsal-data-pipeline-built-for-modern-security-teams",
"votes": 58,
"created_at": "2023-04-19T14:52:36.010Z"
}
]
},
{
"id": 24384,
"name": "Whalesync",
"slug": "whalesync",
"former_names": [
"Whaleform Inc. (product is Whalesync)"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/859ce6355b2e4ff52655c420f97fbe51b3849528.png",
"website": "https://www.whalesync.com",
"all_locations": "St. Petersburg, FL, USA; Remote",
"long_description": "Whalesync makes data syncing easy. Our automation platform syncs data between key business tools like Webflow/Wix/WordPress and Airtable/Notion/Google Sheets. We give marketing teams two-way, real-time sync, so they can manage their website from their favorite collaboration tools.\r\n\r\nWhalesync launched during Y Combinator’s S21 cohort. Since then we’ve raised from some of the world’s top investors. We’re now trusted by hundreds of companies like [Ramp](https://ramp.com/), [Webflow](https://webflow.com/), and [Alchemy](https://www.alchemy.com/), and process millions of transactions every day. Many of our customers enjoy the product so much they [tell all their friends](https://whalesync.com/customers).",
"one_liner": "Manage your website from your favorite tools like Airtable and Notion",
"team_size": 8,
"industry": "B2B",
"subindustry": "B2B -> Marketing",
"launched_at": 1626201713,
"tags": [
"SaaS",
"Remote Work",
"No-code",
"Data Engineering",
"Web Development"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2021",
"status": "Active",
"industries": [
"B2B",
"Marketing"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/whalesync",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2021/whalesync.json",
"year_founded": 2021,
"city": "St. Petersburg",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/whalesync",
"x_url": "https://twitter.com/WhalesyncData",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/whaleform",
"github_url": "https://github.com/whalesync",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/859ce6355b2e4ff52655c420f97fbe51b3849528.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Aaron Epstein",
"url": "https://www.ycombinator.com/people/aaron-epstein"
},
"founders": [
{
"user_id": 614866,
"full_name": "Curtis Fonger",
"title": "Founder",
"founder_bio": "Cofounder of Whalesync (S21)",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/cfonger/",
"x_url": "https://twitter.com/CurtisFonger",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/09e7af5c143a1c626f28a9d3dd7887f69e2c831d.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Whalesync wants to simplify the process of syncing data between SaaS apps • TechCrunch",
"url": "https://techcrunch.com/2023/01/26/whalesync-wants-to-simplify-the-process-of-syncing-data-between-saas-apps/",
"date": "Jan 26, 2023"
}
],
"launches": [
{
"id": 85696,
"title": "Whalesync: Give your spreadsheet edit access to data in apps",
"tagline": "Do things you shouldn’t with spreadsheets.",
"body": "Hi everyone! We’re Matthew and Curtis, founders of [Whalesync](https://www.whalesync.com).\n\n**Whalesync gives your spreadsheet edit access to data in apps like HubSpot, Webflow, and Supabase.** This way, you can bulk edit, collaborate, or build AI workflows directly from Airtable, Notion, or Google Sheets. It's a little scary... but also super powerful ;)\n\nHere’s a Notion database updating deals directly in HubSpot:\n\n\n\n### **Why spreadsheets?**\n\nSpreadsheets like Google Sheets, Airtable, and Notion are super flexible, require practically no learning curve, and let you view and update records in bulk.\n\nWhen you connect these tools with your business apps (like your CRM, CMS, or database), you basically get spreadsheet superpowers ✨.\n\n\n\n### **Common use cases**\n\nHundreds of companies, including Webflow, Descript, and Clay, use Whalesync to work faster by:\n\n* **Enriching CRM leads with AI** from a spreadsheet (HubSpot + Notion)\n* Creating **thousands of programmatic SEO pages** from a spreadsheet (Webflow + Airtable)\n* **Creating internal tools** without any engineers (Supabase + Airtable)\n* **Updating deal statuses** from a spreadsheet (Affinity + Google Sheets)\n* Giving clients an **easy way to update projects** (Notion + Google Sheets)\n\n### **How it works**\n\n1. Connect your app and your spreadsheet.\n2. Map the tables and fields you want to sync.\n3. Turn it on, and your data syncs into your spreadsheet. Then you can start editing/creating.\n\n### **Try it out**\n\nWe have a two-week free trial on all of our plans if you want to try Whalesync yourself!\n\nAnd always feel free to shoot us a note if you have questions at 👋 [hello@whalesync.com](mailto:hello@whalesync.com).\n\n**🚀 Try it out here** ——> [**https://www.whalesync.com**](https://www.whalesync.com)\n\n",
"url": "https://www.ycombinator.com/launches/MIC-whalesync-give-your-spreadsheet-edit-access-to-data-in-apps",
"votes": 9,
"created_at": "2024-11-19T17:55:29.794Z"
},
{
"id": 68930,
"title": "Whalesync - 2-way sync your no-code tools",
"tagline": "Whalesync lets you create an instant, 2-way sync between Airtable, Webflow, Notion, Postgres, & Bubble",
"body": "**tl;dr** We make it easy to 2-way sync data across tools like Airtable, Webflow, Notion, Postgres, & Bubble. This unlocks powerful use cases like programmatic SEO, no-code apps, ABM pages, and internal tools. You can check out our [free trial here](https://www.whalesync.com/airtable-webflow/choose-connectors)!\n\nHey everyone! We’re Ryder, Matthew, Curtis, Manish, Veneta, and Sean aka the team behind [Whalesync](http://whalesync.com/).\n\n\n\n### **The problem: connecting tools is hard**\n\nConnecting apps like Airtable & Webflow enables amazing use cases, but is actually really hard to do without code!\n\nWe started Whalesync because we repeatedly saw people spending weeks architecting multi-step automations only to find them brittle and unreliable.\n\nWhile we love automation tools, they’re really not built to handle true data syncing where you connect deeply and bi-directionally.\n\n\n\n### **The solution: simple, no-code data sync**\n\nWhalesync is the no-code tool built to handle data syncing. In a few minutes, you can hook up your apps and have them 2-way syncing in real-time.\n\n\n\n### **Use cases: pSEO, internal tools, + much more**\n\nWhalesync works by connecting different tools, so there are a TON of different things you can do. A few of the more popular use cases:\n\n* 🔎 Launch thousands of **programmatic SEO pages** (Airtable x Webflow)\n* ⚒️ Build an **internal tool** on top of your production database (Postgres x Notion)\n* 💻 Create a scalable **no-code app** (Bubble x Airtable)\n* 🧑 Personalize hundreds of tier-1 **ABM landing pages** (Airtable x Webflow)\n* 📝 Manage your **blog** (Notion x Webflow)\n\n### **How it works**\n\n1. Pick the tools you want to sync\n2. Tell Whalesync how the data maps\n3. Turn on sync, we do the rest ✅\n\n\n\n### **🙏 Asks**\n\n* [Try it out](https://www.whalesync.com/airtable-webflow/choose-connectors) and let us know what you think! Support is great, but feedback is even better as it helps us decide what to build next.\n* Also, let us know if you have any [requests for new connectors](https://jjm01gwpyzn.typeform.com/to/lij7aJhR)! We’ll be building a bunch more this year.\n* If you have any questions, feel free to reach out to my personal email 😄 [matthew@whalesync.com](mailto:matthew@whalesync.com)",
"url": "https://www.ycombinator.com/launches/Hvm-whalesync-2-way-sync-your-no-code-tools",
"votes": 19,
"created_at": "2023-02-01T16:56:55.235Z"
}
]
},
{
"id": 24481,
"name": "Whaly",
"slug": "whaly",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/0a1af514f9cd7a1856ce3c31281c3e222087d748.png",
"website": "https://whaly.io",
"all_locations": "Paris, Île-de-France, France",
"long_description": "Whaly helps data teams save time on maintenance and analysis building while making business users more autonomous on the analysis they want to improve their decision making.\r\n\r\nWe do this by providing a self service data platform where both data and business teams can work together.\r\n\r\nWe understood that most data teams were ending up being a bottleneck for the rest of the company and needed to give more autonomy to business teams to back their decisions with data.\r\n\r\nEmilien, Florian and Pierre were the minds behind the Data advertising platforms of the major media and e-commerce companies in France in their earlier position as Product Manager and head of Customer Success, giving them an edge on how to execute successfully a data project.",
"one_liner": "Whaly is building a self-service analytics platform",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1627307992,
"tags": [
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2021",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"France",
"Europe"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/whaly",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2021/whaly.json",
"year_founded": 2021,
"city": "Paris",
"country": "FR",
"linkedin_url": "https://www.linkedin.com/company/whalyhq/",
"x_url": "https://twitter.com/WhalyHQ",
"fb_url": "https://www.facebook.com/Whaly-110195867443096",
"cb_url": "https://www.crunchbase.com/organization/whaly",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/0a1af514f9cd7a1856ce3c31281c3e222087d748.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Aaron Epstein",
"url": "https://www.ycombinator.com/people/aaron-epstein"
},
"founders": [
{
"user_id": 486264,
"full_name": "Emilien Sanchez",
"title": "Founder",
"founder_bio": "As a former product manager I love building products that are heavily used by customers, I also enjoy doing sales and understanding pains and drivers. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/emiliensanchez/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/0f4babfc0476b90740cf337c78652e2d67311ec4.jpg"
},
{
"user_id": 480566,
"full_name": "Florian Buguet",
"title": "Founder",
"founder_bio": "COO & Co-Founder @Whaly\nHead of CS @mediarithmics\nPreviously consulting @Accenture & Deloitte",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/florian-buguet-a1150812/",
"x_url": "https://twitter.com/flobbgt",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ca6be4182862436e59edcb773905c34584c8f098.jpg"
},
{
"user_id": 481512,
"full_name": "Pierre de Poulpiquet",
"title": "Founder",
"founder_bio": "Engineer from Paris, France 🇫🇷🐓\n\nLoves to hack around 👨💻, eat baguette 🥖 and learn new things 🧠!\n\nAfter initial experience in Business Consulting 👔 at large firms and product manager 🦄 at a Data marketing startup, I'm building Whaly 🐳 with my 2 co-founders!\n\nI often have strong opinions/learnings about the stuff that interest me so, keep me posted to see if I can help you with something 😉",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/pierre-de-poulpiquet-28ba1a95/",
"x_url": "https://twitter.com/PoulpiP",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/c689f215d291dab5b5f29198f81c15837d55f2d5.jpg"
}
],
"jobs": [],
"news": [
{
"title": "We raised $1.9m seed to transform business intelligence",
"url": "https://whaly.io/posts/we-raised-1-9m-seed-to-transform-business-intelligence",
"date": "Jun 30, 2022"
}
],
"launches": [
{
"id": 64222,
"title": "Whaly 🐳 BI platform to scale your business with data",
"tagline": "The modern BI platform that makes data decisions accessible by everyone",
"body": "**The problem**\n\nAfter interviewing and working with 100+ companies, we understood that the “best” companies, that are “data driven” only have 20-30% of teams who have adopted data. Why?\n\n1. ⏱ A data project is too long to setup and sometimes requires technical skills (\\~ 6 months average from ideation to implementation)\n2. 💸 Costs are way too high 200K$ on average for a data project\n3. 🧩 Data tools and BI are poorly connected to business teams workflows and tools (slack, spreadsheet, CRM, etc.) asking an additional effort to consume it\n4. 😿 Data teams are too busy maintaining a stack instead of giving something more self-service tools to their users (business teams, investors, partners, clients, etc.)\n5. 💩 In the end business teams tend to rebuild everything manually with spreadsheets or other tools instead of spending time analyzing the data\n\nSo in short, on one hand data leaders spend 80% of their time maintaining a stack and on the other hand, people who need analysis and answers reinvent the wheel manually because they feel underserved.\n\n**Welcome to Whaly, the modern platform that helps everyone makes decision-based on data efficiently**\n\nSo what is Whaly? A platform to help you connect, transform and distribute data easily to everyone\n\n1. 🔥 Analytics ready data where you need it → connect all your tools (Mktg, CRM, Back end, etc.) and get analytics ready data in minutes and forever (Whaly manages all the schema and updates so you can focus on analyzing your performances\n2. 📊 Adhoc questions and chart creation in a safe environment for business users → business users can access data in a friendly way and build their own analysis, welcome to self service, autonomy and engagement for everyone\n3. ⚒️ Data analysis can be part of every team journey and workflow → Send analysis in slack for CS teams, embed them in your CRM for sales, in your product for your customers, Notions or Clickup for OKR, etc.\n\n🐳 An example of the exploration module and report builder\n\n\n\n**We’d love to hear from you** \\\nIf you have questions or are interested in talking about data feel free to reach out at [founders@whaly.io](mailto:founders@whaly.io) or [florian@whaly.io](mailto:florian@whaly.io) we’ll be happy to chat!",
"url": "https://www.ycombinator.com/launches/Ghq-whaly-bi-platform-to-scale-your-business-with-data",
"votes": 22,
"created_at": "2022-06-30T09:46:13.329Z"
}
]
},
{
"id": 24827,
"name": "Evidence",
"slug": "evidence",
"former_names": [
"Evidence.dev"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/4d8b363264f6bac1f6d0ca15696cb97172806885.png",
"website": "https://www.evidence.dev",
"all_locations": "Toronto, ON, Canada; Remote",
"long_description": "Evidence is an open source, code-based alternative to drag-and-drop BI tools. Build polished data products with just SQL and markdown.",
"one_liner": "Business intelligence as code",
"team_size": 6,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1628028455,
"tags": [
"Developer Tools",
"B2B",
"Analytics",
"Data Engineering",
"Data Visualization"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Summer 2021",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"Canada",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/evidence",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2021/evidence.json",
"year_founded": 2021,
"city": "Toronto",
"country": "CA",
"linkedin_url": "https://www.linkedin.com/company/evidence-dev",
"x_url": "https://twitter.com/evidence_dev",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/evidence-1cfc",
"github_url": "https://github.com/evidence-dev",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/4d8b363264f6bac1f6d0ca15696cb97172806885.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 724430,
"full_name": "Adam McAskill",
"title": "Founder",
"founder_bio": "Previously led the data science team at one of Canada's leading private equity funds. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/adam-mcaskill-74515720/",
"x_url": "https://twitter.com/AdamMcaskill",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/2ad8671d97bb5e486ca60a01f8b4755915738dff.jpg"
},
{
"user_id": 102765,
"full_name": "Sean Hughes",
"title": "Founder",
"founder_bio": "Previously led the data science team at one of Canada's leading private equity funds.",
"is_active": true,
"linkedin_url": "https://ca.linkedin.com/in/hughessean",
"x_url": "https://twitter.com/SeanHughes92",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/07de9c5aa123280b82349d36dc989a116e6a9d66.jpg"
}
],
"jobs": [
{
"id": 114987,
"title": "Software Engineer ",
"url": "https://www.ycombinator.com/companies/evidence/jobs/zmlmpjE-software-engineer",
"location": "Toronto, ON, CA / Toronto, Ontario, CA",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$100K - $150K CAD",
"equity_range": "0.25% - 0.50%",
"experience": "1+ years",
"visa": "US citizenship/visa not required",
"skills": []
}
],
"news": [
{
"title": "Announcing our $2.1M Seed Round and Evidence Cloud",
"url": "https://evidence.dev/blog/fundraise-and-cloud/",
"date": "Sep 14, 2023"
},
{
"title": "Access code: Evidence brings open source BI to technical data teams | TechCrunch",
"url": "https://techcrunch.com/2023/09/13/evidence-business-intelligence-open-source-code/",
"date": "Sep 13, 2023"
}
],
"launches": []
},
{
"id": 24866,
"name": "Satsuma",
"slug": "satsuma",
"former_names": [
"Riser"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/534b4a727c846e2797022922053e8d79d2f196d2.png",
"website": "https://www.satsuma.xyz/",
"all_locations": "San Francisco, CA, USA; Remote",
"long_description": "Satsuma is a developer tool for building applications on top of real-time blockchain data. Our product lets developers take decoded data from multiple chains, customize it for their use cases, and access it through API endpoints.\r\n\r\nBlockchains serve as distributed databases for these products, holding their most important data. However, it’s difficult to access and query that data. We believe this friction is an enormous blocker for web3 developers and that better tooling will enable mass adoption for web3.\r\n\r\nWe’re a founding team of engineers, having built data infrastructure and product as early employees at Airtable, Heap, and Y Combinator.",
"one_liner": "Reliable blockchain indexing & querying for web3 engineering teams.",
"team_size": 5,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1652717569,
"tags": [
"Developer Tools",
"SaaS",
"Crypto / Web3",
"Data Engineering"
],
"tags_highlighted": [
"Crypto / Web3"
],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2021",
"status": "Acquired",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/satsuma",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2021/satsuma.json",
"year_founded": 2021,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/satsuma-xyz",
"x_url": "https://twitter.com/satsumaxyz",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/satsuma",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/534b4a727c846e2797022922053e8d79d2f196d2.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 63587,
"full_name": "Jonathan Kau",
"title": "Founder",
"founder_bio": "Co-Founder of Satsuma, acquired by Alchemy. Formerly @YC",
"is_active": true,
"linkedin_url": "http://www.linkedin.com/in/jonathankau",
"x_url": "https://twitter.com/jonathankau",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ea2c56cb12bb446a8530990aba12283a8979354a.jpg"
},
{
"user_id": 268448,
"full_name": "Dan Li",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/dan-li-463aa81b/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/7149f286944fdc52682cdb241afb4e8883e9503c.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Satsuma is Joining Forces with Alchemy",
"url": "https://blog.satsuma.xyz/joining-alchemy/",
"date": "Sep 26, 2023"
},
{
"title": "Alchemy Acquires Satsuma to Power Alchemy Subgraphs",
"url": "https://alchemy.com/blog/alchemy-acquires-satsuma",
"date": "Sep 26, 2023"
},
{
"title": "The Block: Satsuma raises $5 million for blockchain data indexing platform",
"url": "https://www.theblock.co/post/224834/satsuma-seed-funding",
"date": "Apr 04, 2023"
}
],
"launches": []
},
{
"id": 25307,
"name": "Sieve",
"slug": "sieve",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/b247c36fd7cd016d5bb505d32429cd07b9acfcbb.png",
"website": "https://sievedata.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Sieve builds the data and environments frontier AI labs use to train the next generation of multimodal systems.\r\n\r\nAI is moving beyond chatbots into video, audio, images, software, robotics, and interactive worlds. The next generation of models will need to understand how the world looks, sounds, moves, responds, and changes over time. Progress is bottlenecked by one thing: high-quality data.\r\n\r\nSieve brings together exabyte-scale infrastructure, novel multimodal understanding techniques, large-scale sourcing, and deep research partnerships to create datasets and environments with unmatched precision, quality, and speed. This has earned the trust of frontier AI labs, Fortune 100 companies, and fast-growing AI startups working on generative media, robotics, computer use, world models, and agentic systems.",
"one_liner": "The multimodal data lab",
"team_size": 34,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1643510053,
"tags": [
"Developer Tools",
"Video",
"Data Labeling",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/sieve",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/sieve.json",
"year_founded": 2022,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://linkedin.com/company/sievedata",
"x_url": "https://twitter.com/@sievedata",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/b247c36fd7cd016d5bb505d32429cd07b9acfcbb.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Diana Hu",
"url": "https://www.ycombinator.com/people/diana-hu"
},
"founders": [
{
"user_id": 412206,
"full_name": "Mokshith Voodarla",
"title": "Founder",
"founder_bio": "Mokshith is co-founder and CEO of Sieve. Mokshith used to work on computer-vision problems at Scale AI, NVIDIA, and Ford where he experienced first-hand, the difficulties of building and scaling vision-based analytics systems. Before that, he graduated from UC Berkeley with a B.S. Electrical Engineering and Computer Science. Mokshith found his love for computer-vision on his high school robotics team, where he also met Abhi. Mokshith deeply enjoys orange chicken.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/mokshith-voodarla/",
"x_url": "https://twitter.com/mokshith_v",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ed90fadcb7d40c3b39a55d49c9049f636e06fa29.jpg"
},
{
"user_id": 858478,
"full_name": "Abhinav Ayalur",
"title": "Founder",
"founder_bio": "Abhinav (Abhi) Ayalur is the co-founder and CTO of Sieve. Abhi leads technical design and development along with steering the overall company vision. Abhi's previous experience includes stints in computer vision, data analysis, and API development at Second Spectrum, NVIDIA, Microsoft, and Niantic. Abhi graduated UC Berkeley with a B.S. in Electrical Engineering and Computer Science. In his spare time, Abhi loves to play the alto saxophone, eat good food, and play basketball.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/abhi12-ayalur/",
"x_url": "https://twitter.com/thpicy",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ae4830f3e54dadcd5d67c2f4045e3732580975cc.jpg"
}
],
"jobs": [
{
"id": 75776,
"title": "Distributed Systems Engineer",
"url": "https://www.ycombinator.com/companies/sieve/jobs/6UaDNRn-distributed-systems-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $300K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 75777,
"title": "Applied Research Engineer",
"url": "https://www.ycombinator.com/companies/sieve/jobs/epe3f1w-applied-research-engineer",
"location": "San Francisco",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $300K",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 81029,
"title": "Software Engineer",
"url": "https://www.ycombinator.com/companies/sieve/jobs/8viV0w4-software-engineer",
"location": "San Francisco",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $300K",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 82322,
"title": "Product & Ops Lead ",
"url": "https://www.ycombinator.com/companies/sieve/jobs/QO2KXMO-product-ops-lead",
"location": "San Francisco",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "$130K - $250K",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 89312,
"title": "Product Engineer",
"url": "https://www.ycombinator.com/companies/sieve/jobs/R7esADT-product-engineer",
"location": "San Francisco",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $300K",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 89313,
"title": "Recruiting",
"url": "https://www.ycombinator.com/companies/sieve/jobs/4vb50L5-recruiting",
"location": "San Francisco",
"type": "Full-time",
"role": "Recruiting & HR",
"role_type": "Recruiter",
"salary_range": "$120K - $200K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 89736,
"title": "Reliability Engineer",
"url": "https://www.ycombinator.com/companies/sieve/jobs/2mp3sT5-reliability-engineer",
"location": "San Francisco",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $300K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 91896,
"title": "Data Operations Lead",
"url": "https://www.ycombinator.com/companies/sieve/jobs/gpArec4-data-operations-lead",
"location": "San Francisco",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "$130K - $250K",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizen/visa only",
"skills": []
}
],
"news": [
{
"title": "Sieve's Video AI API Beta and ~$4M Raise | Sieve Blog - Video AI | Sieve",
"url": "https://www.sievedata.com/blog/launch",
"date": "Nov 14, 2022"
}
],
"launches": []
},
{
"id": 25334,
"name": "FlowDeploy",
"slug": "flowdeploy",
"former_names": [
"Toolchest"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/2d5821bc4ff8ad8ac82401a9ffd37cd8adb868bc.png",
"website": "https://flowdeploy.com",
"all_locations": "San Francisco, CA, USA; Mountain View, CA, USA; Remote",
"long_description": "FlowDeploy helps bioinformaticians manage their data analysis pipelines. We provide everything they need to try, run, develop, and share their pipelines. That includes integrations with AWS, Snakemake, Nextflow, GitHub, Slack, SSO, and more, as well as a clean API and web app for launching and monitoring pipelines and managing their data.\r\n\r\nFlowDeploy is built for bioinformaticians: it doesn't restrict how pipelines are built and managed, as long as a bioinformatics workflow manager like Nextflow or Snakemake is used. But it does eliminate several footguns like idle spend and accidental data egress, and it reduces the potential for users accidentally sharing credentials.\r\n\r\nFlowDeploy runs the pipelines in either our managed cloud or the customer's cloud – eliminating the need to transfer data externally.\r\n\r\nNon-computational biologists can use FlowDeploy, too: features like pipelines templates decrease the complexity to launch a new pipeline, which reduces user error and decreases the need for advanced cloud training for non-computational users.",
"one_liner": "Bioinformatics pipelines in the cloud",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1643247528,
"tags": [
"Developer Tools",
"Drug discovery",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Inactive",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/flowdeploy",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/flowdeploy.json",
"year_founded": 2021,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/toolchest",
"x_url": "https://twitter.com/trytoolchest",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/trytoolchest",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/2d5821bc4ff8ad8ac82401a9ffd37cd8adb868bc.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 418865,
"full_name": "Noah Lebovic",
"title": "Founder",
"founder_bio": "Noah Lebovic is the co-founder and CEO of FlowDeploy. Prior to FlowDeploy, he led software engineering at a bio startup that build an in-house platform for bioinformatics pipelines.",
"is_active": false,
"linkedin_url": "https://linkedin.com/in/lebovic/",
"x_url": null,
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/c9cae1d29bb5148a87e4a3e5c3e39005597dd733.jpg"
},
{
"user_id": 820695,
"full_name": "Bryce Cai",
"title": "Founder",
"founder_bio": "Former CTO of FlowDeploy / Toolchest (YC W22). Now working on AI-bio evals and more broadly getting involved in the AI alignment space. More than happy to help others get more involved, feel free to reach out via email if you'd like to chat!",
"is_active": false,
"linkedin_url": "https://linkedin.com/in/bryce-cai-b1278419a",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/bd3829398b25f5b0f9d0983ed8807c755e6c80fe.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 25353,
"name": "Sarus",
"slug": "sarus",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/eeaf8f8226d85960b7834ae51a48adfa24515b3b.png",
"website": "https://www.sarus.tech",
"all_locations": "Paris, Île-de-France, France",
"long_description": "Sarus solves the problem of accessing or sharing personal data for analytics or machine learning. \r\nThe solution deploys natively in data infrastructures and lets practitioners work on data they cannot see. Every interaction with the sensitive data is protected with the highest privacy standard: differential privacy\r\nSarus makes traditional anonymization methods irrelevant, saving months in compliance and data engineering while preserving all of the value of data.",
"one_liner": "Use personal data for analytics and ML, safely and seamlessly",
"team_size": 16,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1642494204,
"tags": [
"Analytics",
"Compliance",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Acquired",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"France",
"Europe",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/sarus",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/sarus.json",
"year_founded": 2020,
"city": "Paris",
"country": "FR",
"linkedin_url": "https://www.linkedin.com/company/sarus-technologies",
"x_url": "https://twitter.com/sarus_tech?lang=en",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/sarus-1f2d",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/eeaf8f8226d85960b7834ae51a48adfa24515b3b.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 811762,
"full_name": "Maxime Agostini",
"title": "Founder",
"founder_bio": "Maxime Agostini is Sarus cofounder and CEO. He previously cofounded AlephD a ML startup solving publishers monetization challenges. As CEO, he grew the business internationally and led the company up to a successful exit to Verizon Media in 2016. \nMaxime graduated from Ecole Polytechnique in computer science and physics. He interned at Google and Stanford physics lab.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/maximeago/",
"x_url": "https://twitter.com/maximeago?lang=en",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/7fa46756d809ae8d17163de13b53cfbecd89efb9.jpg"
},
{
"user_id": 811812,
"full_name": "Nicolas Grislain",
"title": "Founder",
"founder_bio": "Nicolas Grislain is Chief Science Officer at Sarus Technologies.\nHe graduated from École Normale Supérieure de Lyon in Mathematics and Computer Science.\nNicolas started his career in economics and finance modeling at the French Treasury and then at Société Générale.\nHe co-founded a first company: AlephD, in 2012, where he was also leading Research and Development.\nAlephD got acquired by Yahoo in 2016.\nIn 2020 he co-founded Sarus Technologies with the same founding team as AlephD.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/nicolas-grislain/",
"x_url": "https://twitter.com/ngrislain",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/db6f560e93e6e0fac031fb035d42806c32f5408b.jpg"
},
{
"user_id": 825992,
"full_name": "Vincent Lepage",
"title": "Founder",
"founder_bio": "repeat entrepreneur (Sarus is my third startup), former CTO & co-founder Alephd (ML & big data for online advertising, sell-side).\nFormer CPO Owkin (AI for medical research)\nLove to make things work.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/vincent-lepage-064ab41/",
"x_url": "https://twitter.com/vincentLep",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/13bc2f72f65e3df96cc91f1be8cebb51544255ea.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 25396,
"name": "HomeRoom",
"slug": "homeroom",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/28c5f983626c200b08794eb57093e4b2320036df.png",
"website": "https://livehomeroom.com/",
"all_locations": "San Francisco, CA, USA; San Jose, CA, USA; Remote",
"long_description": "Homeroom helps investors provide affordable housing while making a 22% ROI.\r\n\r\nWe do this by sourcing properties, arranging capital, managing construction, vetting tenants and collecting rent by the room. To date, Homeroom has brought on 85 property investors, growing 6X annually, are bringing in 420K in annualized net-revenue\r\n\r\nHow it works:\r\nWe help investors buy homes in cities that are attractive to young people, but lack affordable housing options. We then renovate and after about 20 days, the home is ready and we find qualified renters by the room.\r\n\r\nWe launched in 2018 in Kansas City with 1 home. We now have 105 homes in 31 cities. In 2021, we grew rental GMV to $1.8M (300% YoY growth). Our average rent across every property is $458, which is about 50% lower than market comps, and our investors see returns up to 50% higher.\r\n\r\nWe are HomeRoom. Johnny is the financial analyst/domain expert. Thomas is a cereal entrepreneur with a PHD in ML, and Mike hacked growth for Airbnb and Facebook.",
"one_liner": "We Rent Your Property by the Room. You earn 50% more Rent.",
"team_size": 25,
"industry": "Real Estate and Construction",
"subindustry": "Real Estate and Construction -> Housing and Real Estate",
"launched_at": 1643818108,
"tags": [
"Machine Learning",
"Real Estate",
"Proptech",
"NLP",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Acquired",
"industries": [
"Real Estate and Construction",
"Housing and Real Estate"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/homeroom",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/homeroom.json",
"year_founded": 2018,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/livehomeroom",
"x_url": "",
"fb_url": "https://www.facebook.com/livehomeroom/",
"cb_url": "https://www.crunchbase.com/organization/homeroom-eecb",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/28c5f983626c200b08794eb57093e4b2320036df.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 556447,
"full_name": "Johnny Wolff",
"title": "Founder",
"founder_bio": "I'm the CEO and Founder of HomeRoom Coliving – one of the fastest-growing coliving companies in the United States. After starting my career as a financial analyst in Silicon Valley I relocated to Austin, Texas to pursue real estate investing full-time. HomeRoom recently expanded to \nDallas and Austin, Texas. I still lives in one of HomeRoom’s \nfirst coliving houses in Kansas City, and enjoys hanging out \nand surviving the pandemic with my awesome roommates - \nespecially on chicken wing Thursdays",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/johnnywolff/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/e3c999f9f35b1bd762c674b755cf060fe0d79f59.jpg"
},
{
"user_id": 460855,
"full_name": "Thomas Hornbeck",
"title": "Founder",
"founder_bio": "I'm a serial entrepreneur who has founded multiple tech startups, including GotIt! (EdTech), Distynct (AgTech), and Homeroom (Coliving/PropTech) YC W'22. PhD (abd) in Computer Science, dropped out in the 5th year to start my first company. I moved to Silicon Valley in 2013 and built an EdTech app that ended up #2 in Education on the AppStore. I've been an angel investor in a few startups Jobhop (HR Tech company in Vietnam) and LegalQ (TechStars '21), and Venture Partner at Kind Capital.",
"is_active": true,
"linkedin_url": "http://linkedin.com/in/thornbeck",
"x_url": "https://twitter.com/thomashornbeck",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/62b41c2c47663ee593b6828aba0ca7579f737590.jpg"
},
{
"user_id": 336717,
"full_name": "Mike Tich",
"title": "Founder",
"founder_bio": "Experienced Marketer and Data Scientist. \nCo-Founder & Head of Growth @ HomeRoom (W22)\nMarketing Science Expert @ Facebook\nPM / DS @ Airbnb (W09)\nHead of Digital Marketing @ iCracked (W12)",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/michael-tich-53849b30/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ca1a9196382bc31c86235a4b3fbcf2f22c2ea623.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 25398,
"name": "Dynamo AI",
"slug": "dynamo-ai",
"former_names": [
"DynamoFL"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/a0f71dda3502bef2323fa4a11bd6c434154ddec8.png",
"website": "https://dynamo.ai",
"all_locations": "San Francisco, CA, USA",
"long_description": "End-to-end privacy, security, and compliance solutions to prepare your organization for emerging AI regulations.",
"one_liner": "Compliant-Ready AI for the Enterprise",
"team_size": 40,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1645652403,
"tags": [
"Machine Learning",
"Privacy",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/dynamo-ai",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/dynamo-ai.json",
"year_founded": 2021,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/dynamofl",
"x_url": "https://twitter.com/dynamo_fl",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/dynamofl",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/a0f71dda3502bef2323fa4a11bd6c434154ddec8.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Tom Blomfield",
"url": "https://www.ycombinator.com/people/tom-blomfield"
},
"founders": [
{
"user_id": 815874,
"full_name": "Christian Lau",
"title": "Founder",
"founder_bio": "Co-founder @ Dynamo AI (YC W22) | EECS Ph.D. at MIT | Secure and Compliant AI",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/christian-lau-18055546",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/bc0d361a6d18f9a6cc908b1b4a93f747ec72cd40.jpg"
},
{
"user_id": 540687,
"full_name": "Vaikkunth Mugunthan",
"title": "Founder",
"founder_bio": "Co-Founder/CEO - DynamoFL | MIT CS SM'19 PhD'22 | Differential Privacy and Federated Learning",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/vaikkunth/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/1d4b630813b442a0952b8b50a372740a92db6ced.jpg"
}
],
"jobs": [
{
"id": 63835,
"title": "Lead Software Engineer - ML Service",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/C7NWDAd-lead-software-engineer-ml-service",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Backend",
"salary_range": "$200K - $275K",
"equity_range": "",
"experience": "6+ years",
"visa": "US citizen/visa only",
"skills": [
"Amazon Web Services (AWS)",
"Kubernetes",
"Python",
"TypeScript",
"Machine learning"
]
},
{
"id": 66641,
"title": "Senior Software Engineer",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/awcqCwP-senior-software-engineer",
"location": "Remote (US)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Backend",
"salary_range": "$80K - $130K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"Kubernetes"
]
},
{
"id": 66840,
"title": "Customer Success Senior Manager",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/bqyDeqG-customer-success-senior-manager",
"location": "New York, NY",
"type": "Full-time",
"role": "Support",
"role_type": null,
"salary_range": "$150K - $180K",
"equity_range": "",
"experience": "6+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 66843,
"title": "ML Engineer — LLM Evaluation",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/x38E3p8-ml-engineer-llm-evaluation",
"location": "San Francisco, CA",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 66844,
"title": "ML Engineer — LLM Privacy",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/fNpDnIw-ml-engineer-llm-privacy",
"location": "San Francisco, CA",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 66846,
"title": "ML Research Engineer — LLM Safety",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/JE3H7si-ml-research-engineer-llm-safety",
"location": "San Francisco, CA",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 67283,
"title": "Technical Product Manager",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/GOAtMfD-technical-product-manager",
"location": "San Francisco, CA",
"type": "Full-time",
"role": "Product",
"role_type": null,
"salary_range": "$165K - $220K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"Kubernetes"
]
},
{
"id": 72115,
"title": "Operations Coordinator",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/5bW12zo-operations-coordinator",
"location": "San Francisco, CA, US / New York, NY, US / Remote (US)",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "$60K - $80K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 90407,
"title": "ML Research Scientist Intern – Dynamo Guard / Dynamo Eval / AgentWarden",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/fM78FTT-ml-research-scientist-intern-dynamo-guard-dynamo-eval-agentwarden",
"location": "San Francisco, CA, US / New York, NY, US / London, England, GB / Remote (Amsterdam, NH, NL; Amsterdam, North Holland, NL; Paris, IDF, FR; Paris, Île-de-France, FR)",
"type": "Internship",
"role": "Engineering",
"role_type": "Machine learning",
"salary_range": "$3.5K - $6.5K / monthly",
"equity_range": "",
"experience": null,
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 90418,
"title": "ML Research Engineer Intern – Dynamo Guard / Dynamo Eval / AgentWarden",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/bUcFnbU-ml-research-engineer-intern-dynamo-guard-dynamo-eval-agentwarden",
"location": "New York, NY, US / San Francisco, CA, US / Remote (Amsterdam, NH, NL; Amsterdam, North Holland, NL; Paris, IDF, FR; Paris, Île-de-France, FR)",
"type": "Internship",
"role": "Engineering",
"role_type": "Machine learning",
"salary_range": "$3.5K - $5K / monthly",
"equity_range": "",
"experience": null,
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 98725,
"title": "Product Analyst",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/IMDZ5fW-product-analyst",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Product",
"role_type": null,
"salary_range": "$100K - $130K",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": [
"Python",
"Data Analytics"
]
},
{
"id": 113106,
"title": "Product Manager, AgentWarden (Agent Security)",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/JBI11pg-product-manager-agentwarden-agent-security",
"location": "San Francisco, CA, US / London, England, GB",
"type": "Full-time",
"role": "Product",
"role_type": null,
"salary_range": "$125K - $165K",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 113107,
"title": "Product Manager, AI Governance & Compliance",
"url": "https://www.ycombinator.com/companies/dynamo-ai/jobs/XsTHYfP-product-manager-ai-governance-compliance",
"location": "San Francisco, CA, US / London, England, GB",
"type": "Full-time",
"role": "Product",
"role_type": null,
"salary_range": "$125K - $165K",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizen/visa only",
"skills": []
}
],
"news": [
{
"title": "DynamoFL raises $15.1M to help enterprises adopt 'compliant' LLMs | TechCrunch",
"url": "https://techcrunch.com/2023/08/16/dynamofl-raises-15-1m-to-help-enterprises-adopt-compliant-llms/",
"date": "Aug 16, 2023"
},
{
"title": "DynamoFL aims to bring privacy-preserving AI to more industries",
"url": "https://techcrunch.com/2022/09/20/dynamofl-aims-to-bring-privacy-preserving-ai-to-more-industries/",
"date": "Sep 20, 2022"
}
],
"launches": []
},
{
"id": 25541,
"name": "Versable",
"slug": "versable",
"former_names": [
"Vista"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/27cef04a2b2af454d42923ab9d77113e9f198884.png",
"website": "https://www.versableai.com/",
"all_locations": "San Francisco, CA, USA; Remote",
"long_description": "Auto parts retailers get product data from hundreds of manufacturers that is inaccurate and inconsistent, often with big gaps in key values. They currently have a team of \"catalog managers\" who are required to process and enhance this data line by line, resulting in a week to months long lag between receiving product data and actually being able to start generating revenue from those products. \r\n\r\nVersable leverages AI to scan the web for tens of millions of auto parts listings, and uses a fine-tuned LLM with RAG to instantly process, enhance, and transform data. With just a part number, Versable is able to generate market-ready titles, product descriptions, and specs, in any format that's needed. ",
"one_liner": "AI powered product description enhancement for the auto parts industry",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Retail",
"launched_at": 1642519106,
"tags": [
"Manufacturing",
"Data Engineering",
"AI",
"Automotive"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Active",
"industries": [
"B2B",
"Retail"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/versable",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/versable.json",
"year_founded": 2021,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/versableai/",
"x_url": "",
"fb_url": null,
"cb_url": "https://www.linkedin.com/company/versableai",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/27cef04a2b2af454d42923ab9d77113e9f198884.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 581453,
"full_name": "Christina Seong",
"title": "Founder",
"founder_bio": "Seoul>Vancouver>SF>LA>SF\n\nUC Berkeley \nAlpine Investors\nSalesforce",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/christinaseong/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/8e953270721669a6b2ed89ac205c8c76601afb33.jpg"
}
],
"jobs": [
{
"id": 85098,
"title": "Product Engineer (contract to hire)",
"url": "https://www.ycombinator.com/companies/versable/jobs/vKWT8Ls-product-engineer-contract-to-hire",
"location": "IN / Remote (IN)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$2.5K - $3K / monthly",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
}
],
"news": [
{
"title": "Announcing our $2.6m seed round! | Vista",
"url": "https://docs.govista.io/blog/seed",
"date": "Jul 12, 2022"
}
],
"launches": [
{
"id": 90121,
"title": "Versable - Generate your auto parts catalog with AI",
"tagline": "Designed for complexity, built for scale",
"body": "Hi everyone! I’m [Christina](https://www.linkedin.com/in/christinaseong/), founder of [Versable](https://versableai.com/).\n\nVersable uses AI fix sparse and messy catalogs in high-value, high pain legacy industries. Our first focus is the $500B auto aftermarket.\n\n### 🧩 **The problem: bad product data costs sales and is hard to fix**\n\n* Bad product data leads to **lost sales, slow time to market, and high return rates**, especially in the aftermarket where accuracy is critical.\n* Most aftermarket catalogs were built decades ago and are not designed for modern digital demands. Product data lives in silos, lacks standardization, and requires deep domain expertise to classify correctly.\n* Today, teams of catalog managers manually onboard, audit, and update product content for millions of SKUs, causing **weeks of delay before a part can start generating sales**.\n\n---\n\n### 🔧 **Why Versable solves this 10x better than status quo**\n\n* Versable is the **only tool built specifically to accommodate the technical complexity and massive scale required in industrial and aftermarket applications**. We use context aware and domain specific AI to automatically clean, standardize, and enrich product data with precision.\n\n\n\n* With just a part number, Versable generates market-ready titles, product descriptions, and specs in any required format. This means our customers are able to sell more, faster, and across more platforms than ever before.\n\n\n\n### **🙏** **Our Ask**\n\nWe’d love any intros to anyone managing ecommerce data at scale, especially\n\n1. Sellers managing industrial products like auto parts\n2. Sellers managing multiple marketplaces and platforms (eBay, Walmart, Amazon, etc.)\n3. Service providers supporting these sellers (PIM systems/ecommerce syndicators, etc.)\n\nShoot me an email at [tina@versable.ai](mailto:tina@versable.ai)!",
"url": "https://www.ycombinator.com/launches/NRZ-versable-generate-your-auto-parts-catalog-with-ai",
"votes": 70,
"created_at": "2025-05-06T02:30:12.462Z"
},
{
"id": 82840,
"title": "Versable - AI-powered product data enhancement for the auto parts space",
"tagline": "🚀 Supercharge your product data to help you sell more, faster.",
"body": "Hi everyone! My name is [Christina](https://www.linkedin.com/in/christinaseong/), and I’m building [Versable](https://www.versable.ai/). We use AI to help auto parts manufacturers, retailers, and distributors generate market-ready product listings at scale.\n\n**The data problem in auto parts**\n\nAuto parts retailers get product data from hundreds of manufacturers, often riddled with inaccuracies, inconsistencies, and missing key values. This forces companies today to manually process and enhance this data line by line, causing a weeks to months long lag between receiving product data and actually being able to start generating revenue from those products.\n\nThis bottleneck means companies are slower to market and unable to onboard new products at the scale they want. Manufacturers also face challenges with data requirements, which limits their ability to sell across multiple retailers or even consider listing their own products on online marketplaces like Amazon or eBay, which have even stricter platform-specific content guidelines.\n\n**How Versable solves this 10x better than the status quo**\n\nVersable leverages AI to scan the web for tens of millions of auto parts listings and uses a fine-tuned LLM with RAG to instantly process, enhance, and transform product data. With just a part number, Versable generates market-ready titles, product descriptions, and specs in any required format. This means our customers are able to sell more, faster, and across more platforms than ever before.\n\nBy incorporating brand-specific voices and relevant SEO keywords, Versable ensures that in a market filled with near-perfectly competitive products, our customers can come out on top.\n\n\n\n**Our Ask**\n\n1. Connect us with companies dealing with auto parts (distributors, manufacturers, retailers)\n2. Reach out if you work with any e-commerce product data at scale! Always looking to connect with founders building other cool tools in the space. [tina@versable.ai](mailto:tina@versable.ai)\n3. Follow us on [LinkedIn](https://www.linkedin.com/company/versableai)!\n\n# ",
"url": "https://www.ycombinator.com/launches/LY8-versable-ai-powered-product-data-enhancement-for-the-auto-parts-space",
"votes": 61,
"created_at": "2024-08-08T00:23:07.709Z"
}
]
},
{
"id": 25542,
"name": "Elementary",
"slug": "elementary",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/45aadc83c7554b356da35bb6d48a350f575804b2.png",
"website": "http://elementary-data.com/",
"all_locations": "Tel Aviv-Yafo, Tel Aviv District, Israel",
"long_description": "Elementary enables data teams to detect problems in their data before their users do. An open-source solution that any data engineer can deploy in minutes without sharing sensitive data.",
"one_liner": "Open-source data observability for data teams",
"team_size": 12,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1647515701,
"tags": [
"Developer Tools",
"Analytics",
"Open Source",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"Israel",
"Middle East and North Africa"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/elementary",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/elementary.json",
"year_founded": 2021,
"city": "Tel Aviv-Yafo",
"country": "IL",
"linkedin_url": "https://www.linkedin.com/company/elementary-data",
"x_url": "https://twitter.com/ElementaryData",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/elementary-data/elementary",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/45aadc83c7554b356da35bb6d48a350f575804b2.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Tom Blomfield",
"url": "https://www.ycombinator.com/people/tom-blomfield"
},
"founders": [
{
"user_id": 731217,
"full_name": "Maayan Salom",
"title": "Founder",
"founder_bio": "Ex-8200, Formerly Incident Response engagement manager at Sygnia (acquired by Temasek).\nOver 10 years in data analysis and managing teams of analysts and researchers. \nValidating data since 2010.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/maayansa/",
"x_url": "https://twitter.com/MaayanSalom",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ed8e2e1def91e4f15e5b26315a1dc2e42b62c264.jpg"
},
{
"user_id": 866550,
"full_name": "Or Avidov",
"title": "Founder",
"founder_bio": "Ex-8200 (Israeli intelligence unit), formerly Director of engineering at Singular.\nOver 10 years in software and data engineering. \nM.Sc. in Computer Science and Machine learning.\nBuilding data pipelines since 2010.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/oravidov/",
"x_url": "https://twitter.com/oravidov",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/d721363352d5f1ca064543ea5250a9c3c8cd2c57.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Boomi acquires Israeli startup Elementary for $40-45 million",
"url": "https://www.calcalistech.com/ctechnews/article/b1zgj8mnzg",
"date": "Oct 19, 2026"
}
],
"launches": []
},
{
"id": 25561,
"name": "LanceDB",
"slug": "lancedb",
"former_names": [
"ETO",
"Eto"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/7b3b44ab11047bbfddb4bfe44c9d2d3c87027258.png",
"website": "https://lancedb.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "LanceDB is a new open-source vector database that can support low-latency billion-scale vector search on a single node. Built around a new columnar data format, LanceDB makes it incredibly easy to build applications for generative AI, recsys, search engines, content moderation, and more.",
"one_liner": "Open-source, serverless vectordb for production-scale generative AI",
"team_size": 35,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1648263864,
"tags": [
"AIOps",
"Machine Learning",
"Open Source",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/lancedb",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/lancedb.json",
"year_founded": 2022,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/lancedb/",
"x_url": "https://twitter.com/lancedb",
"fb_url": null,
"cb_url": null,
"github_url": "github.com/lancedb",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/7b3b44ab11047bbfddb4bfe44c9d2d3c87027258.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Nicolas Dessaigne",
"url": "https://www.ycombinator.com/people/nicolas-dessaigne"
},
"founders": [
{
"user_id": 858308,
"full_name": "Chang She",
"title": "Founder",
"founder_bio": "My passion is building tools to make teams more productive working with data. I was VP of Eng at TubiTV where I designed the ML stack and the experiment platform, in addition to growing the team by more than 3x. Previously I was CTO/co-founder of DataPad and the second major contributor to the pandas library. In a former life, I was a financial quant with stints at AQR and Barclays.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/changshe",
"x_url": "https://twitter.com/changhiskhan",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/7fac6d13a6e767ce791580c1200cbdaaa236d900.jpg"
}
],
"jobs": [],
"news": [
{
"title": "LanceDB Raises $30M Series A to Build the Multimodal Lakehouse - LanceDB Blog",
"url": "https://lancedb.com/blog/series-a-funding/",
"date": "Jun 24, 2025"
},
{
"title": "New Funding and A New Foundation for Multimodal AI Data",
"url": "https://blog.lancedb.com/new-funding-and-a-new-foundation-for-multimodal-ai-data/",
"date": "May 15, 2024"
}
],
"launches": [
{
"id": 71382,
"title": "LanceDB 🍢 - serverless, low-latency vector database for AI applications",
"tagline": "Meet LanceDB, the easy-to-use and developer-friendly alternative to Pinecone",
"body": "🙋 Are you building a generative AI app using an LLM or API? Are you working on a new recsys, a modern search engine, or a new analytical tool for unstructured data? Good news: you no longer have to struggle with Pinecone’s high cost, over the top complexity, or data privacy concerns.\n\n🚀 [LanceDB](https://lancedb.com/) is a free and open-source vector database that you can run locally or on your own server. It’s lightning fast and is easy to embed into your backend server. Check out our [github repo](https://github.com/lancedb/lancedb) or pip install lancedb to get started.\n\nFor a quick demo, you can take a look at our sample [youtube transcript search app](https://github.com/lancedb/lancedb/blob/main/notebooks/youtube_transcript_search.ipynb). We’ll be adding a lot more soon. For more details on the API, take a look at [LanceDB docs](https://lancedb.github.io/lancedb/).\n\n\n\n### **❓ Why we built LanceDB**\n\nAs we spoke to builders of ML/AI applications, a common refrain from users was struggling to get services like Pinecone even running. After a while, we realized that the retrieve-filter-hydrate workflow was often time a big bottleneck in productivity and app latency.\n\nSo we put our heads together. I was one of the original co-authors of the pandas library. Lei was a core-contributor to HDFS and led ML infrastructure at Cruise. Using our experience building data/ML tooling, we’ve built something totally new.\n\n\n\n### **LanceDB ❤️ builders**\n\nWe’ve reimagined vector search from the ground up for better developer productivity, scalability, and performance. LanceDB is backed by [Lance format](https://github.com/eto-ai/lance) — a modern columnar data format that is an alternative to parquet. It’s optimized for high speed random access and management of AI datasets like vectors, documents, and images.\n\nWe then added our own Rust implementations of a number of SOTA ANN-index algorithms to support low-latency vector search. These indices are SSD-based and can easily scale wayyyy beyond memory.\n\nWhat’s more, LanceDB allows you to store and filter other features along with vectors. Our users have been able to replace 3–4 different data stores with LanceDB alone and achieve a speedup at the same time.\n\n### **🛣️ Roadmap**\n\nSince our launch, the community has added LangChain support. Our integration for LlamaIndex is also under review. Our current focus is building a TypeScript implementation with a native-level experience. \n\nCurrently, we provide a python package called lancedb which is pip installable and delivers a great local workflow. Beyond what we’re working on right now, here’s what you can expect:\n\n* Ecosystem **integrations** into OpenAI plugin / AutoGPT etc\n* Richer set of **embedding functions** and **document processing** conveniences\n* **Gallery** of generative AI apps powered by LanceDB\n* Solutions for **cloud** deployment\n\n### **🙏 How to get started**\n\nTo get started with LanceDB head over to our [repo](https://github.com/lancedb/lancedb). If you have questions, feedback, or want help using LanceDB in your app, don’t hesitate to drop us a line at .",
"url": "https://www.ycombinator.com/launches/IZK-lancedb-serverless-low-latency-vector-database-for-ai-applications",
"votes": 22,
"created_at": "2023-05-05T03:22:53.361Z"
}
]
},
{
"id": 25616,
"name": "Stackshine",
"slug": "stackshine",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/2f75e99dea11ca83cb5f3e5de76cf447b57d842e.png",
"website": "https://www.stackshine.com",
"all_locations": "Portland, OR, USA; Providence, RI, USA; Remote",
"long_description": "Stackshine is creating mission control for enterprise IT teams. We discover all the software being used across their organization and then automate workflows related to onboarding/offboarding, cost savings, and security. ",
"one_liner": "Automating all IT operations",
"team_size": 7,
"industry": "B2B",
"subindustry": "B2B -> Operations",
"launched_at": 1646144116,
"tags": [
"Robotic Process Automation",
"Productivity",
"Analytics",
"Enterprise",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Acquired",
"industries": [
"B2B",
"Operations"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/stackshine",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/stackshine.json",
"year_founded": 2020,
"city": "Portland",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/stackshine",
"x_url": "https://twitter.com/StackshineSaaS",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/stackshine",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/2f75e99dea11ca83cb5f3e5de76cf447b57d842e.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 49962,
"full_name": "Tyler Diaz",
"title": "Founder",
"founder_bio": "Builder of tech",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/tylerjdiaz/",
"x_url": "https://twitter.com/tylerdiaz",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/dd7c36c437e2147eedbdd5d5e159787332924d8d.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 25738,
"name": "Hydra",
"slug": "hydra",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/87c0954c151aa7067e034d8de33b3174d43f5ff0.png",
"website": "https://hydra.so",
"all_locations": "San Francisco, CA, USA; Remote",
"long_description": "Hydra is a real-time analytics database management system for Postgres. We seperate compute from storage to offer software engineers serverless analytics with autoscale, write isolation, automatic caching, and more.\r\n\r\nShipping scalable projects on time series and event data has never been easier. Hydra is available for local development, cloud, and bare metal deployment.",
"one_liner": "Serverless Analytics on Postgres",
"team_size": 6,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1642199733,
"tags": [
"Developer Tools",
"Analytics",
"Open Source",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Acquired",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/hydra",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/hydra.json",
"year_founded": 2021,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/hydradatabase",
"x_url": "https://twitter.com/hydradatabase",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/hydra-7681",
"github_url": "https://github.com/HydrasDB",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/87c0954c151aa7067e034d8de33b3174d43f5ff0.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Tom Blomfield",
"url": "https://www.ycombinator.com/people/tom-blomfield"
},
"founders": [
{
"user_id": 54309,
"full_name": "Joseph Sciarrino",
"title": "Founder",
"founder_bio": "CEO, Hydra\nFormer PM @ MSFT Azure Open-Source Databases team.\nHeroku (W08) and Citus Data (S11) alum",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jsciarrino12/",
"x_url": "https://twitter.com/JoeSciarrino",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/4f798def8e78bebf37b918e014a9a4d933b47fc2.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Microsoft backs open source PostgreSQL analytics extension • The Register",
"url": "https://www.theregister.com/2024/08/20/postgresql_duckdb_extension/",
"date": "Aug 20, 2024"
},
{
"title": "Hydra aims to be the open cloud data warehouse alternative to Snowflake – TechCrunch",
"url": "https://techcrunch.com/2022/07/01/hydra-aims-to-be-the-open-cloud-data-warehouse-alternative-to-snowflake/",
"date": "Jul 01, 2022"
}
],
"launches": [
{
"id": 88443,
"title": "Hydra: Serverless Realtime Analytics on Postgres",
"tagline": "Unlock realtime analytics on live data in seconds",
"body": "\n\n**Hydra is Serverless Realtime Analytics on Postgres.**\n\nBy separating compute from storage, Hydra enables compute-isolated analytics and bottomless storage. It is designed for low latency applications built on time series and event data.\n\n# [**Try Now! (free)**](https://start.hydra.so/get-started)\n\n\n\n# **Enable in seconds**\n\n\n\nSet up is simple. To unlock serverless realtime analytics on Postgres, run:\n\n```\npip install hydra-cli\n```\n\nFor setup\n\n```\nhydra\n```\n\n1. fetch your hydra token, paste in to enable Hydra\n2. create analytics schema / tables and insert data ([**quickstart docs**](https://docs.hydra.so/intro/quickstart))\n3. _voila_ - run queries, get insights in milliseconds\n\n# **Problem**\n\nFor decades, there’ve been two core problems with analytics on Postgres:\n\n**Slow** - aggregates and complex queries can take minutes to return results from large data sets.\n\n**Resource Contention** - Expensive analytics queries hog Postgres’ RAM / CPU resources and impair transactional performance. In other words, the entire app slows down, which makes users unhappy.\n\n# **Solution**\n\n### **Fast**\n\nHydra returns analytics queries 400X faster than standard Postgres. Hydra uses duckdb to perform isolated serverless processing on these tables in Postgres. In fact, Hydra is faster than most specialized analytics databases.\n\nIf you’re running AWS RDS, AWS Aurora, Heroku Postgres, Supabase, Fly Postgres, Render Postgres, GCP Cloud SQL, etc.. you can improve expensive analytics queries by 400X by using Hydra.\n\n\n\nfun fact: the Snowflake instance (128x4XL) in the benchmark is $100k / month.\n\n\n\nThese are results from clickbench which represents a typical workload in the following areas: clickstream and traffic analysis, web analytics, machine-generated data, structured logs, and events data. The table consists of exactly 99 997 497 records — rather small by modern standards but allows tests to be performed in a reasonable time.\n\n### **Isolated, serverless processing**\n\nUsing Hydra there is no impact on Postgres’ RAM / CPU resources when reading from or writing to an analytics tables.\n\nAs a result, here are more cool things Hydra can do: zero-copy clones for scaling read replicas, automatic caching, write isolation, bottomless storage with high data compression, and more.\n\n# **How it works**\n\n\n\nHydra integrates duckdb execution and features with Postgres using [**pg_duckdb**](https://github.com/duckdb/pg_duckdb), an open-source project we co-developed with the creators of DuckDB.\n\n**FAQ:**\n\nyes, you can join between an analytic table and a standard row-based table.\n\nyes, you can write (insert & update) to analytics tables.\n\nyes, Hydra is identical to using standard postgres.\n\nyes, data inserted into an analytics table is automatically converted into analytics-optimized columnar format.\n\ntell Hydra you are creating an analytics table by including the ‘using duckdb’ keyword - that’s it.\n\n# **Hydra is best for**\n\nHydra is both a row and columnstore, so you can use it for standard Postgres work, like multitenant apps, as well as analytical work, like monthly reporting. Here are several cool Hydra use cases that blend both transactional & analytics — more in our [**use case docs**](https://docs.hydra.so/guides/usecase).\n\n* time series, logs, events, traces\n* monitoring & telemetry\n* financial services\n* observability & metrics\n* cybersecurity & fraud detection\n* web & product analytics\n* iot\n* realtime ml / ai\n\n# **ok, but why use postgres instead of … \\[insert favorite tech\\]?**\n\nIt’s true, there are many specialized analytics databases. reviewing the benchmark above, the majority of analytics databases are actually _slower_ than Hydra. Regardless, isolated analytics databases produce their own set of challenges and costs.\n\n### **data pipelines (etl)**\n\nTraditionally, an analytics database is isolated, and in most cases, engineers must set up data pipelines for data movement and transformation between Postgres, S3, and the analytics db. Pipelines aren’t cheap. Also, there’s pipeline latency bottlenecking how stale the analytics are. And when pipelines break — because they do — you’re stuck with downtime and wrong results.\n\nHydra side-steps the latency and costs of data pipelines entirely with full support for inserts and updates on columnar files in analytics tables.\n\n### **overweight design**\n\nMany use cases don’t justify a heavy setup. From our time working at Heroku, we saw many transactional apps that only need a couple high level aggregates and a few complex analytical queries to return quickly. Hardly OLAP (online analytical processing) and not really HTAP (hybrid transactional and analytical processing) - just apps in need of a speed boost.\n\nThe most heavyweight option, data warehouses like BigQuery, are good at “big queries”, but not great at smaller, rapid analytics queries that’re more common with applications, rather than monthly reporting.\n\nThese traditional approaches are too heavy, can be brittle, and introduce extra costs and latency your startup doesn’t need.\n\n# **do we have a hosted cloud offering?**\n\nYes, and [it’s awesome](https://start.hydra.so/get-started).\n\n# [**Try now!**](https://start.hydra.so/get-started)\n\n## **useful links**\n\n[**website**](https://www.hydra.so/), [**docs**](https://docs.hydra.so/overview), [**local dev guide**](https://docs.hydra.so/guides/local_development), [**analytics guide**](https://docs.hydra.so/guides/analytics), [**architecture**](https://docs.hydra.so/intro/architecture), [**changelog**](https://docs.hydra.so/changelog/changelog)\n\nIf you’ve made it this far here’s a pic of me (joe) and my cofounder (jd) in hood river, oregon. Building Hydra has been a wild ride, but we found a way to have fun.\n\n\n\n",
"url": "https://www.ycombinator.com/launches/N0V-hydra-serverless-realtime-analytics-on-postgres",
"votes": 8,
"created_at": "2025-03-11T12:27:09.916Z"
}
]
},
{
"id": 25743,
"name": "Trackingplan",
"slug": "trackingplan",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/7b1ef39c22b700cf5d44570c7f6569b245f3ee28.png",
"website": "https://trackingplan.com",
"all_locations": "Barcelona, CT, Spain; CT, Spain; Remote",
"long_description": "Trackingplan automatically discovers and monitors all the information your applications and websites are collecting, ensuring that you can trust your BI, analytics, marketing, and sales tools. \r\n\r\nYou can think of us as Segment Protocols but totally transparent, where developers can keep using Google Analytics, Amplitude, Hubspot, Intercom, Braze, etc. as they are used to. \r\n\r\nInstalled in minutes in using your Tag Manager or adding just one line of code to your web or apps, we model all the data being sent to third parties. Since Trackingplan understands what each piece of data means, it identifies patterns, detects anomalies, and automatically connects the dots to create value from data that was hidden in plain sight:\r\n\r\n- An always up-to-date single source of truth and data governance tool. To discover, understand and document your data and improve communication across teams.\r\n- Automated notifications when something breaks or changes. To make sure that integrations are always well implemented: Schema errors, traffic anomalies, rogue events... \r\n- Easy to understand, customizable, cross-service alerts. To detect trends, insights, and problems without using complex, engineer-oriented solutions.",
"one_liner": "Automated QA for your Digital Analytics",
"team_size": 17,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1641391102,
"tags": [
"SaaS",
"Analytics",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"Spain",
"Europe",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": true,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/trackingplan",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/trackingplan.json",
"year_founded": 2021,
"city": "Barcelona",
"country": "ES",
"linkedin_url": "https://www.linkedin.com/company/trackingplan",
"x_url": "https://twitter.com/trackingplanco",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/7b1ef39c22b700cf5d44570c7f6569b245f3ee28.png",
"app_video_url": null,
"dday_video_url": "https://bookface-images.s3.us-west-2.amazonaws.com/video_event/56/1648680083402-jep797sxatg-2d1ddc90e418837f7f8693cca0a48cbb/c5d555b43777814dc8674bbdcbb3ea82.mp4?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=AKIAQC4NIECABPQ2AHNW%2F20261020%2Fus-west-2%2Fs3%2Faws4_request&X-Amz-Date=20261020T022704Z&X-Amz-Expires=3600&X-Amz-SignedHeaders=host&X-Amz-Signature=be5961ecaaa66b80943a2f5a7fe30a22680ed44de7f0be2c75537f5f56f6997d",
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 644571,
"full_name": "Alexandros Andre Chaaraoui",
"title": "Founder",
"founder_bio": "I'm a Software Engineer and I love to apply AI in the industry. After obtaining a PhD in Machine Learning, I joined Google to work on Computer Vision for Android and NLP for the Google Assistant, where I owned the Weather vertical. I left to start and lead a ML Team at the 90-year old Rohde&Schwarz. There we patented and launched metrics for Data Analytics based on Deep Learning. As a founder at Trackingplan, I'm managing the technical department and people coordination.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/alexandrosandre/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/2cfd581f2f7472b0f6cce73648bb9d1a095a0326.jpg"
},
{
"user_id": 655112,
"full_name": "Jose Padilla",
"title": "Founder",
"founder_bio": "Hi there! Trackingplan co-founder here. Our team joined because we had the need to do something. We had suffered a well-known problem: bad data. Relying on bad data to take business decisions is a pain in the ass. As we are enthusiasts in software, artificial intelligence and business, we had to do something about it. Trackingplan was born. I've built many kinds of software before, from desktop apps to home automation systems. So I'm excited about building Trackingplan and kill -9 bad_data",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/joserpadilla",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/57958584b59af24275e076f412224702cb4d52f0.jpg"
},
{
"user_id": 1977,
"full_name": "Jose Luis Perez",
"title": "Founder",
"founder_bio": "I'm born and I live in Spain. I love creating products that matter, dogs and soccer.\nI studied CS and founded three tech companies, where I took the role of CEO and product lead, but I try to code when my smarter fellows don't see me. \nAt Guiomatic, we sold millions of custom travel guides to airlines\nAt Hooks, we sent billions of notifications to millions of users. \nAt Techstars we learned a lot.\nNow at Trackingplan, we help companies trust their data.",
"is_active": true,
"linkedin_url": "https://linkedin.com/joseluisperezgonzalez",
"x_url": "https://twitter.com/joseleperez",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/e4eb6db66a485252ca4e05bffc788ca1fe74042c.jpg"
},
{
"user_id": 911464,
"full_name": "Pedro Trujillano",
"title": "Founder",
"founder_bio": "Business and technical oriented.\nWorked in development, product, operations and sales. 3x founder and VC.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/pedrotrujillano/",
"x_url": "https://twitter.com/ptrujillano",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/15c5f1e78ecdb733b04a1750f397913e7b11bf0e.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 25905,
"name": "Bracket",
"slug": "bracket",
"former_names": [
"Palette Financial",
"Inc.",
"Palette"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/743850446c402a0284c29ccc61272697d62fc139.png",
"website": "https://www.usebracket.com/",
"all_locations": "New York City, NY, USA; Los Angeles, CA, USA",
"long_description": "Bracket is the two-way data pipeline between popular business tools and backend databases. When ops teams update data in Salesforce or Airtable, and engineers update data in the database, Bracket connects the two sources to reflect the same information. ",
"one_liner": "Two-way syncs between business tools and your database",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1641941124,
"tags": [
"SaaS",
"B2B",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2022",
"status": "Acquired",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/bracket",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2022/bracket.json",
"year_founded": 2021,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/use-bracket",
"x_url": "https://twitter.com/usebracket",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/743850446c402a0284c29ccc61272697d62fc139.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 1760203,
"full_name": "Vinesh Arun",
"title": "Founder",
"founder_bio": "Founder @ Bracket. Formerly at Shipper (YC W19) and Oliver Wyman",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/vinesharun/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/cf4a3af30b304d1f27cd4ad2cbfb7a303c9d02d8.jpg"
},
{
"user_id": 842541,
"full_name": "Kunal Garg",
"title": "Founder",
"founder_bio": "Building @ Bracket.\n\nPreviously: Brokerage Ops Engineering @ Wealthfront, Product/Engineering @ Redfin, Internal Tooling Engineering @ Facebook\n\nPassionate about real estate investing, fintech/financial literacy, quality design, concussion therapy, Catan, biking and volleyball.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/kunalrgarg/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/8b8f89b18fb9abaa0e39a7991dfd9bbbc9bc74d6.jpg"
},
{
"user_id": 678518,
"full_name": "Ian Yanusko",
"title": "Founder",
"founder_bio": "Building two-way data syncs @ Bracket (W22). Previously Product @ Shipper Indonesia, Fellow @ Alter Global, and Research Associate @ Cornerstone/\n\nPassionate about bikes, mycology, Catan, and my synth.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/ian-yanusko-6b240591/",
"x_url": "https://twitter.com/IanYanusko",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/1c621d3cf0d77ed92abaad134b555e2e0314c165.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 74154,
"title": "Bracket - Sync Salesforce & Postgres: Heroku Connect alternative for any SaaS",
"tagline": "Two way syncs between business tools and your database",
"body": "**Tl;dr:** [**Bracket**](https://app.usebracket.com) syncs data bidirectionally between tools like Salesforce & databases like Postgres — think Heroku Connect between any SaaS tool and any database or warehouse. For companies that collect customer-relevant information in SaaS tools, Bracket is the simplest way for engineers to get this data in front of customers in real time.\n\n—\n\nHey everyone! We’re Vinesh, Ian, and Kunal and we’re building Bracket.\n\n\n\n### **The problem**\n\nCompanies often need a way to manually adjust the info that a lead or customer sees - think of the sales team of a software company that wants to customize a demo environment for a high-value lead, or the ops team of a car rental company that needs to manage which cars are available for customers to book. \n\nThe job of designing, implementing, and championing a fix falls to engineering. Engineers can either build a custom UI for their teammates, or connect with the tools they already use, like Salesforce or Airtable. \n\nThere are a few problems with this:\n\n1. Custom UIs run against the grain of the tools that business teams already use and can even require double data entry on the part of those teams. This leads to low adoption. \n2. This leads most engineers to integrate with their business teams’ existing tools. However, setting up real-time two-way syncs is a highly technical challenge that can take entire quarters of implementation time.\n\nIn short, custom-built solutions lead to low adoption, and built-from-scratch integrations with business teams’ tools can take months of engineering effort.\n\n### **How we solve it**\n\n**Using two-way syncs, Bracket is the easiest way to keep data in sync between business teams’ existing tools, like Salesforce, and databases, like Postgres.** \n\nThis creates a win-win-win. Using the Salesforce <> Postgres example:\n\n* Engineering gets to build on top of Postgres and doesn’t have to deal with the Salesforce API (we do that for you). Engineering also meets business teams where they are, optimizing adoption.\n* Customer-facing business teams (e.g. Sales, CX) continue to leverage Salesforce, a familiar, highly productive tool with tons of features and a strong community, and can trust that their data is fresh.\n* Customers - seeing fresh, personalized data - get the best UX possible, increasing lead conversion and paid retention.\n\n \n\nOur new web app works with Salesforce and Postgres along with other connectors (like Airtable, Google Sheets, MySQL and more).\n\n\n\n### **Demo:**\n\n[ ](https://www.youtube.com/watch?v=sRkaAa667T0)\n\n### **Differences from Heroku Connect?**\n\n1. **Built for your tech stack:** We support beyond just Heroku Postgres. Not only do we support any hosted Postgres, but we also have two-way syncs with other databases and warehouses.\n2. **Active Development:** Heroku Connect hasn’t been updated in years and has no new features on their official roadmap. Bracket continues to develop around the modern stack.\n3. **Uses cases across teams:** We’ve built two-way syncs for CRMs like Salesforce but also other products like Airtable, Google Sheets, and more.\n4. **Price:** We’re far cheaper than Heroku Connect, which can run north of $50k / year.\n\n### **Our ask:**\n\nIf you want to try this yourself, get started[ **here**](https://app.usebracket.com)\n\nOtherwise, if you:\n\n1. Are looking for two-way syncs between other tools and want us to build it\n2. Know any data engineers at mid-market / enterprise companies to make an intro\n3. Have any other questions, please reach out to [founders@usebracket.com](mailto:founders@usebracket.com)",
"url": "https://www.ycombinator.com/launches/JI2-bracket-sync-salesforce-postgres-heroku-connect-alternative-for-any-saas",
"votes": 28,
"created_at": "2023-08-16T13:53:42.831Z"
}
]
},
{
"id": 26726,
"name": "ilumadata",
"slug": "ilumadata",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/66d4cb68e2a9b002d6e82fe002cef40a30254971.png",
"website": "https://www.ilumadata.io/",
"all_locations": "London, England, United Kingdom; Sydney, NSW, Australia; Remote",
"long_description": "We’re retool for data pipelines. We allow less-technical people to edit data pipelines, with easy to use tools.",
"one_liner": "Confidently ship analytics code faster with fewer errors",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1657474709,
"tags": [
"Developer Tools",
"B2B",
"Analytics",
"Enterprise",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2022",
"status": "Inactive",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United Kingdom",
"Australia",
"Europe",
"Oceania",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/ilumadata",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2022/ilumadata.json",
"year_founded": 2022,
"city": "London",
"country": "GB",
"linkedin_url": "https://www.linkedin.com/company/ilumadata",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/66d4cb68e2a9b002d6e82fe002cef40a30254971.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 1006154,
"full_name": "Luke Singham",
"title": "Founder",
"founder_bio": "Formerly, Data Platform Engineer and data lead at Monzo, previously at Palantir working across the commercial and government sectors. Over 10 years in the data industry.",
"is_active": false,
"linkedin_url": "http://linkedin.com/in/lukesingham",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/5aeccb33236c162e1e0eed45e0a9601c3e75e914.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 64710,
"title": "ilumadata - Confidently ship analytics code faster with less errors",
"tagline": "ilumadata is a single workspace for the modern data stack, enabling data teams to ship 3x more analytics code with fewer errors",
"body": "Hey YC,\n\nWe’re [Luke Singham](https://www.linkedin.com/in/lukesingham/) and [Matt Sutton](https://www.linkedin.com/in/matthew-sutton-02290984/), co-founders of [ilumadata](http://ilumadata.io).\n\nilumadata helps data teams make changes faster, with confidence. Catch mistakes before shipping. And when debugging, pinpoint the source of failures–fast.\n\n## 🤓 Who is it for?\n\nData teams in large organisations feeling the pain of scaling data teams: struggling with broken pipelines, or taking too long to make changes.\n\n## ❓The ask + can I try it?\n\nIf you fit this 👆category or know someone who does, we’d love to talk to you!\n\nEmail us at [founders@ilumadata.io](mailto:founders@ilumadata.io) or request a demo at [ilumadata.io](http://ilumadata.io)\n\n## 😩 The problem - why we built ilumadata\n\nAt Monzo, I experienced a growing number of pains as we scaled the data team:\n\n* Onboarding new team members took days to weeks\n* Debugging broken pipelines took hours to fix because information was hard to piece together\n* It was hard to know the impacts downstream of changes you made\n* Difficult to know who owns the data, who uses it or if it is even used at all\n\n## ✅ The solution\n\nilumadata is a single workspace for the modern data stack, enabling data teams to ship 3x more analytics code with less errors:\n\n* Onboard new team members in under 60 seconds with a cloud hosted environment.\n* Learn, manage, version control, validate and test your pipeline in one workspace.\n\n \n\n* Mock out pipeline architecture like you would in a flow chart tool, with code you can use!\n\n \n\n* Debug, optimise and resolve your pipelines issues, fast.\n\n \n\n",
"url": "https://www.ycombinator.com/launches/Gpi-ilumadata-confidently-ship-analytics-code-faster-with-less-errors",
"votes": 24,
"created_at": "2022-07-18T21:37:33.587Z"
}
]
},
{
"id": 26756,
"name": "Midplane",
"slug": "midplane",
"former_names": [
"Deekard",
"IvyCheck",
"WithIda"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/5fda9dc0196ef666a5a460e8ffbc29dddfc27396.png",
"website": "https://midplane.ai/",
"all_locations": "Berlin, Berlin, Germany; Remote",
"long_description": "Companies are connecting AI coding agents like Cursor and Claude directly to their databases — where one wrong command can delete data or leak customer records. Midplane sits in between and controls what each agent is allowed to do: it blocks dangerous queries, hides sensitive data, and keeps a record of everything the agent touches. It’s open source, and runs either as a hosted service or on your own servers.",
"one_liner": "The safety layer between AI agents and your database",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1658837091,
"tags": [
"Generative AI",
"B2B",
"Productivity",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2022",
"status": "Active",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"Germany",
"Europe",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/midplane",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2022/midplane.json",
"year_founded": 2022,
"city": "Berlin",
"country": "DE",
"linkedin_url": "https://www.linkedin.com/company/midplane",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/midplaneai",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/5fda9dc0196ef666a5a460e8ffbc29dddfc27396.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 825709,
"full_name": "Dustin Lange",
"title": "Founder",
"founder_bio": "Dustin is co-founder of Midplane. Dustin has 8.5 years of industry experience at Amazon as Machine Learning Scientist and Applied Science Manager. He founded a team that built tools for data quality measurement and cleaning, including Deequ (2.4k+ stars on GitHub). Dustin later owned data products powering the Amazon product search page, used by millions of users every day. Dustin holds a PhD in database systems from Hasso Plattner Institute, Potsdam, Germany.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/dustin--lange/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/0236f2b924cc4a53bf62faedf2455f746f33d45b.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 79742,
"title": "IvyCheck – Guard against AI risks with real-time checks",
"tagline": "An API for ensuring the integrity and safety of your AI application",
"body": "**TL;DR:** [IvyCheck](https://www.ivycheck.com/) offers an API designed for classifying user- and AI-generated texts, along with extracting sensitive data. Our specialized machine-learning models ensure the safety and quality of your AI app in real-time.\n\n\n\n### What are AI risks?\n\nAI-powered interfaces such as chatbots emerge and pose **new AI risks:**\n\n* **Prompt Injection Attacks:** Attackers try to manipulate language models to execute unauthorized actions or access sensitive data. These attacks exploit the way AI interprets inputs as natural language text. Prompt injection attacks create a risk that spans from data exfiltration to influencing decision-making processes.\n* **PII Data Leakage:** Customers may include sensitive data in requests that are then sent to LLM providers. Companies must ensure that sensitive data is detected and redacted from requests.\n* **Hallucinations:** Chatbots in RAG applications use context retrieved from document stores, posing the risk of hallucinated, inaccurate, off-topic, or made-up information to users. IvyCheck evaluates whether chatbot answers are faithful to the provided context.\n\n\n\n### How does IvyCheck help?\n\nIvyCheck provides a library of checks for managing AI risks in your application. IvyCheck is:\n\n* **Flexible**: You can add checks to your LLM app with **just 2 lines of code** and protect your users and your data from prompt injection attacks, PII data leakage, and hallucinations. Works regardless of which LLM provider you use in your app.\n* **Secure**: We use customized, fine-tuned models for the checks. We self-host all our models and your data is not sent to third-party model providers.\n* **Fast**: Since the models are small and specialized, you can expect a latency under 100-200 ms. If you require even faster endpoints, please get in touch!\n\n### The founding team\n\n\n\nWe’re [Tammo](https://de.linkedin.com/in/tammo-rukat-34529471) (left) and [Dustin](https://www.linkedin.com/in/dustin--lange/) (right). We met at Amazon, where we were part of the Core Machine Learning team in Berlin. We worked on systems for large-scale data quality checks, missing value imputation, and search filter optimization. We’re both obsessed with delighting our customers and solving their toughest challenges! Let’s create a safer world with AI.\n\n### How do I get started?\n\nVisit [https://ivycheck.com](https://ivycheck.com/) or [book a call](https://ivycheck.com/request-demo) directly with us. We’d love to get in touch and help you make your AI app safe today!",
"url": "https://www.ycombinator.com/launches/KkA-ivycheck-guard-against-ai-risks-with-real-time-checks",
"votes": 5,
"created_at": "2024-03-27T14:54:09.208Z"
},
{
"id": 74336,
"title": "Deekard - Instant answers from your database with AI",
"tagline": "Stop waiting on data teams, guessing at undocumented schemas, and debugging SQL. Start getting answers.",
"body": "**TLDR:**\n\nDeekard is your one-stop shop for fast and easy data analysis. Just enter your database details, ask your burning questions, and let Deekard do the rest. Forget waiting on your data team - it’s time to get your answers fast.\n\n**Problem:**\n\nYou are collecting data about your business and want to become more data-driven in your decision-making. But you’re hitting some speed bumps:\n\n* **Waiting game:** You’re stuck in a queue, waiting for your data team to free up and handle your request. They can’t update the dashboards fast enough or don’t have time to work on your ad-hoc data requests.\n* **No time to write SQL**: You’ve got a business to run, not a course in SQL to take. It should be simple to run your database queries, not a guessing game.\n* **Documentation? What documentation?** You look at your team’s data warehouse and you don’t understand what’s in there. There’s no documentation and you have no idea if that column really contains the data you hope for.\n\n**Solution**\n\nDeekard gives you a powerful, integrated analytics experience - powered by AI. Connect your database and you’re ready to go.\n\n\n\n* **Requests in plain English**: Get started with your request in natural language and Deekard takes care of translating it into a database query. Refine your request with a graphical query builder - or just edit the plain English request. You can also switch to SQL mode - _and back -_ whenever you like.\n* **Explore your database**: See what’s _inside_ your database. Deekard automatically profiles your data and creates that missing documentation for you. This helps with writing queries that actually work.\n* **Team effort**: Share the AI-powered query editor and unblock your whole team. They can instantly reuse your database connection and ask their own questions.\n\n\n\n**Ask:**\n\nTry Deekard! Start at [deekard.com](https://www.deekard.com). Tell us what you think at [founders@deekard.com](mailto:founders@deekard.com).\n\nIf you have a few min for a chat about Deekard, please book time with us [here](https://calendly.com/d/dxz-ddm-67k/deekard-call).\n\nThank you!\\\nDustin and Tammo",
"url": "https://www.ycombinator.com/launches/JKy-deekard-instant-answers-from-your-database-with-ai",
"votes": 15,
"created_at": "2023-08-23T13:49:23.717Z"
},
{
"id": 71231,
"title": "🤖 Deekard - Your autonomous assistant for data science and analytics",
"tagline": "We use generative AI to make all data tasks effortless and accessible: extract, transform, analyze, and visualize data using only natural language.",
"body": "Hey everyone! We’re Tammo and Dustin from [Deekard](https://www.deekard.com/).\n\n**_TL;DR:_** _Deekard is an all-in-one data science and analytics assistant. Connect your data source and get any question answered and any task executed, using only natural language. Powered by GPT-4, our AI model understands your intent, plans workflows, and executes them step-by-step._\n\n**The Problem**\n\nData science involves a wide range of skills, tools, and formats, which can be challenging to learn and manage. Tasks like extracting data with SQL, training machine learning pipelines with Python, and visualizing data using frameworks such as Vega are time-consuming, iterative, and error-prone.\n\n**Our Solution**\n\nDeekard simplifies data science by offering a chat interface where you simply state what you want to do and watch the AI select the right tools in the right order. Like in a data science notebook, you can refer to previously created datasets and refine or combine them later in the conversation. Data science has never been easier or more approachable.\n\n\n\n**Features**\n\n📚 Database: Write queries in natural language and let Deekard translate them into SQL for you! Simply state your query, and you'll receive the result table.\n\n🐍 Python: Transform data or apply machine learning models with ease. Just write your request, and Deekard translates it into Python code and executes it. You'll get the results in no time.\n\n📊 Visualization: Generate charts with natural language. Deekard translates your request into Vega-Lite specifications and creates beautiful visualizations. Apply changes to charts just by writing them down.\n\n🧠 Wikipedia: Enrich your datasets by retrieving tables from Wikipedia. Just write your request, and Deekard will access the world's greatest knowledge base for you.\n\n🎯 Task Organization: Write complex requests, and Deekard will split them into multiple tasks that are executed in the right order.\n\n**Start Today**\n\nYou can start using Deekard today at [deekard.com](http://deekard.com). \n\nThank you for your support, and we look forward to hearing your thoughts on Deekard! 🎉",
"url": "https://www.ycombinator.com/launches/IWt-deekard-your-autonomous-assistant-for-data-science-and-analytics",
"votes": 13,
"created_at": "2023-04-27T14:07:14.366Z"
}
]
},
{
"id": 27040,
"name": "Grai",
"slug": "grai",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/217dbf57c9649c7822bbee101a62b2d34a750a85.png",
"website": "https://www.grai.io",
"all_locations": "San Francisco, CA, USA; London, England, United Kingdom; St. Louis, MO, USA",
"long_description": "Grai is open source version control for metadata. We can determine how database changes will affect deployed machine learning models, apis, and dashboards because we understand how data relates across systems which don’t otherwise talk to each other.",
"one_liner": "Open source version control for metadata",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1660014966,
"tags": [
"Developer Tools",
"SaaS",
"Analytics",
"Open Source",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2022",
"status": "Inactive",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"United Kingdom",
"America / Canada",
"Europe",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/grai",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2022/grai.json",
"year_founded": 2021,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/grai-io/",
"x_url": "",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/grai",
"github_url": "https://github.com/grai-io",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/217dbf57c9649c7822bbee101a62b2d34a750a85.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 696649,
"full_name": "Ian Eaves",
"title": "Founder",
"founder_bio": "Ian is a recovering ex-physicist turned machine learning engineer with experience building MLE teams everywhere from startups (Bellhops) to fortune 50 companies (Centene). An active open source contributor he's written software with over 11M downloads (Visions). Grai was born from the pain of working on distributed data particularly within enterprise settings.",
"is_active": false,
"linkedin_url": "https://www.linkedin.com/in/ieaves/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/a0e6ffe7f84a454640193fd1395f3940c644a5db.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 65887,
"title": "✨ Grai - Open-source version control for metadata",
"tagline": "Grai knows how a database migration will impact deployed ML models, APIs, and more because it understands how data relates across systems.",
"body": "\n\n**TL;DR Grai makes developers smarter by bringing metadata from across their stack into their development tools. We make testing data flows between applications painless.**\n\nGo to 👉 [grai.io](http://grai.io)\n\n### 😭 **Problem**\n\nTracking (let alone testing) data once it leaves a production environment is challenging. Whether in a data engineers transformation pipeline, an ML model, or the CFO’s metrics dashboard, that data _will_ be used elsewhere. Without visibility on those use cases data changes remain risky and outage prone.\n\n### 🚀 **Solution**\n\nGrai is an open-source data management platform designed to help you better use your data.\n\n* **Automated data lineage** - Pre-built connectors to keep metadata fresh.\n* **Integrated with git** - Changing a column in your DB? Run data integration tests for all downstream users as part of your standard CI/CD process.\n* **One-stop-shop** - A unified model of your entire data stack.\n* **Your data belongs to you** - Grai is open-source & self-hosted with a cloud option coming soon.\n\n### 🎉 **Closing thoughts (and asks!)**\n\nMy ask: give it a shot!\n\n* Browse the [code](https://github.com/grai-io/grai-core)\n* Check out the [demo](https://github.com/grai-io/grai-core/tree/master/examples/quick_start_postgres)\n* Reach out! [ian@grai.io](mailto:ian@grai.io)\n\n\\~ Ian\n\n\n\n",
"url": "https://www.ycombinator.com/launches/H8h-grai-open-source-version-control-for-metadata",
"votes": 51,
"created_at": "2022-09-07T00:00:00.601Z"
}
]
},
{
"id": 27092,
"name": "Lamin",
"slug": "lamin",
"former_names": [
"Lamin Labs"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/65bf3f581eea5d1a5b7640c508e3fc0e7c8930f9.png",
"website": "https://lamin.ai",
"all_locations": "",
"long_description": "We make it easy to query, trace, and govern R&D data in the age of AI, serving big pharma enterprises, biotech, and academia.\r\n\r\nOur core product is an open-source, lineage-native, format-agnostic lakehouse for agents and teams.",
"one_liner": "Open data platform for traceable, multimodal AI",
"team_size": 12,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1655969538,
"tags": [
"Developer Tools",
"Machine Learning",
"Biotech",
"Open Source",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2022",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/lamin",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2022/lamin.json",
"year_founded": 2022,
"city": null,
"country": null,
"linkedin_url": "https://www.linkedin.com/company/lamin-labs",
"x_url": "https://twitter.com/laminlabs",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/laminlabs",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/65bf3f581eea5d1a5b7640c508e3fc0e7c8930f9.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 1014343,
"full_name": "Alex Wolf",
"title": "Founder/CEO",
"founder_bio": "Building open-source data infra for biology at Lamin.\n\nPreviously, created Scanpy and led the build-up of Cellarity’s compute platform.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/falexwolf/",
"x_url": "https://twitter.com/falexwolf",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/534fd23c014da309d8eb5c4831d5e1693d48ddc3.jpg"
},
{
"user_id": 1014442,
"full_name": "Sunny Sun",
"title": "Founder",
"founder_bio": "",
"is_active": true,
"linkedin_url": "http://linkedin.com/in/sunnyosun",
"x_url": "https://twitter.com/sunnyosun",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/f46137e52adf8e8d65c130efd41cc0e1224d0c92.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 27108,
"name": "Sanifu",
"slug": "sanifu",
"former_names": [
"Patika Technology Limited",
"Patika"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/dc10943e14517d77a119ecad164eb2d76d6db52b.png",
"website": "https://sanifu.ai",
"all_locations": "Nairobi, Nairobi County, Kenya; Remote",
"long_description": "Sanifu automates the repetitive work spreadsheets are used for. Teams across finance, marketing, operations, and revenue simply describe their repetitive work like cleaning and validating data, matching records, preparing reports and moving data from emails, PDFs and Excel exports into dashboards and other systems. Sanifu captures the steps, rules and outputs so the work is repeated reliably every time\r\n\r\nSome of these work never needed spreadsheets to begin with; the likes of data cleanup, bank reconciliations, report consolidation, payment allocations, channel attributions. Spreadsheets have become the standard workbench for handling these tasks and in the process, teams lose valuable time doing manual data entry, filling templates, formatting data, applying formulas, deleting rows or columns.\r\n\r\nSanifu is replacing the spreadsheet while maintaining the logic and processes behind the work, getting you from inputs to your desired outputs in seconds. This significantly reduces time spent on copy-paste work, spreadsheet cleanup, and manual entries and checking, while improving accuracy, consistency, and operational visibility. Sanifu helps teams scale critical back-office processes without relying on brittle spreadsheets, scripts, or general AI tools that reinvent the logic every run.\r\n\r\nSanifu is a full operational platform with 5k+ app integrations, 1k+ native functions, forms, scheduler, data stores, dashboards, approvals, reviews, AI-powered entity matching among many other features that make it an end-to-end data app management platform",
"one_liner": "Automate the repetitive work spreadsheets are used for",
"team_size": 5,
"industry": "B2B",
"subindustry": "B2B -> Operations",
"launched_at": 1655225496,
"tags": [
"SaaS",
"B2B",
"Analytics",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2022",
"status": "Active",
"industries": [
"B2B",
"Operations"
],
"regions": [
"Kenya",
"Africa",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/sanifu",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2022/sanifu.json",
"year_founded": 2021,
"city": "Nairobi",
"country": "KE",
"linkedin_url": "https://www.linkedin.com/showcase/sanifu",
"x_url": "https://x.com/SanifuAi",
"fb_url": "https://www.facebook.com/Patika-Africa-103542242060777",
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/dc10943e14517d77a119ecad164eb2d76d6db52b.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/21096d7db5182ef9ab5248fc56a7e958ee819e84.png"
],
"primary_partner": null,
"founders": [
{
"user_id": 747527,
"full_name": "Sidney Rema",
"title": "Founder",
"founder_bio": "Co-Founder & CEO at Patika - helping finance, marketing, operations, and revenue teams automate the manual data processes they currently do across spreadsheets, emails, PDFs, and disconnected systems.\n\nTrained as a Medical Doctor (Partly). 5 Years+ experience in Banking - Extending credit to micro & small businesses in Nairobi, Kenya. In my previous company, built payments systems with $10M+ monthly GTV across Kenya, Nigeria & Uganda. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/sidney-rema-90138658/",
"x_url": "https://twitter.com/sidneyrema_?t=Xr0rdOT-gm2VdRYFbatHRg&s=09",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/f20e08b1b2e80d24a7c4471aaa97390f5c8c5d36.jpg"
},
{
"user_id": 742381,
"full_name": "Phelix Juma",
"title": "Founder",
"founder_bio": "Co-Founder & CTO at Sanifu - helping finance, marketing, operations, and revenue teams automate the repetitive work they spend hours doing manually in spreadsheets \n\nI previously helped 3 companies build payments systems that processed $10M in monthly GTV across Kenya, Uganda and Nigeria. \nI am an EE graduate from University of Nairobi with background in information systems, banking, payments integration and data science",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/phelix-juma-80877193/",
"x_url": "https://twitter.com/jumaphelix",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9b18e418314e77cd9e88fc431aa560d38311e408.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 101295,
"title": "Sanifu: Automate the repetitive work spreadsheets are used for",
"tagline": "Describe your repetitive and manual work you currently do in spreadsheets and Sanifu turns them into autonomous data apps that run the same way every time.",
"body": "Sanifu automates the repetitive work spreadsheets are used for. Teams across finance, revenue, and operations simply describe their repetitive work like cleaning and validating data, matching records and moving data across systems. Sanifu captures the steps, rules and outputs and runs it automatically and reliably every time.\n\nThis significantly reduces time spent on copy-paste work, spreadsheet cleanup, and manual entries and checking, while improving accuracy, consistency, and operational visibility. Sanifu helps teams scale critical back-office processes without relying on brittle spreadsheets, scripts, or general AI tools that reinvent the logic every run.\n\n\n\n### **The problem**\n\nAnalysts and teams in finance, revenue, and operations spend a huge part of their day doing manual data work. Cleaning data, preparing reports, moving things across systems, tracking work. It's repetitive, boring, and takes time away from the parts of their job that actually matter. The same work gets done repeatedly because their data is scattered across systems, emails, PDFs, and files. Only a few people know the rules and exceptions. When they leave, the process breaks.\n\nExisting tools don't solve the whole problem. Spreadsheets, macros, and scripts are brittle and hard to maintain. General AI tools can help, but they reinvent the logic on every run, so outputs need constant checking and can't be trusted for critical workflows.\n\n### **How Sanifu solves this**\n\nAnyone can turn their manual data work into an autonomous data app—just by describing it.\n\n1. You describe the process.\n\nIn plain English, you walk Sanifu through what you do. It asks the right questions, handles edge cases, understands your rules, and works with your real data (files, emails, systems) to define the full workflow.\n\n2. Sanifu runs it with you.\n\nIt executes the process end-to-end, showing real-time progress and outputs. You review results, make changes, and refine the workflow until it matches exactly what you expect.\n\n3. It becomes a reliable operations platform.\n\nOnce approved, Sanifu saves the entire process and turns it into a data app. All future runs replay the exact steps whereby the same input plus same context equals same output. It’s more than a workflow tool: built-in data stores, dashboards, forms, integrations, scheduled and event triggers as well as audit trails.\n\nSanifu is a full operational platform with 5k+ app integrations, 1k+ native components, forms, scheduler, data stores, dashboards, approvals, reviews, AI-powered entity matching among many other features that make it an end-to-end data app management platform.\n\nSome of the fastest growing teams in various industries are already using Sanifu to save their team’s hundreds of hours per day of manual data handling.\n\n**Asks**\n\nIf you run a SaaS, finance, ops, or sales team and you have a workflow that involves cleaning, matching, moving data across systems or manual reporting, please reach out. We'll build your first data app with you, free, in exchange for honest feedback.\n\n* Get Free $25 Credits at \n* Talk to us: [founders@sanifu.ai](mailto:founders@sanifu.ai) or WhatsApp +254 712 983 630\n* Intros welcome: anyone in finance, ops, RevOps, or biz ops at a YC company is exactly our ICP.",
"url": "https://www.ycombinator.com/launches/QLn-sanifu-automate-the-repetitive-work-spreadsheets-are-used-for",
"votes": 13,
"created_at": "2026-05-13T18:32:52.849Z"
},
{
"id": 64212,
"title": "🚀 Patika - Receivable Automation & Payments for Africa’s SMBs",
"tagline": "Enabling SMBs in Africa to track customer debt, facilitate the repayments and manage their cash flow",
"body": "**Patika enables Africa’s SMBs to track customer debt, facilitate the repayments and manage their cash flow**\n\nMy mum runs a small shop and we saw her struggle with this problem. She was spending up to 3 hours a day doing phone call follow ups and reconciliations.\n\n### **Problem**\n\nSMBs in Africa are using pen and paper to record and track customer debt which is ineffective and time consuming. As a result, up to 60% is paid late and they lose as much as $2k a year to non-payments.\n\n\n\n### **Solution**\n\nWe are automating previously manual processes like debt repayment reminders, billing, payments and reconciliations.\n\n1. A business on Patika adds their customer and the debt amount.\n2. Patika sends automated payment reminders directly via SMS or WhatsApp.\n3. The customer can pay them directly through the payment link they received or if paid in cash, they can record the repayment on the app and issue a receipt.\n\n \n\n\n### **Want to join us?**\n\n1. You can reach us at [founders@patika.africa](mailto:founders@patika.africa)",
"url": "https://www.ycombinator.com/launches/Ghg-patika-receivable-automation-payments-for-africa-s-smbs",
"votes": 43,
"created_at": "2022-06-30T05:47:38.319Z"
}
]
},
{
"id": 27146,
"name": "Sunpia",
"slug": "sunpia",
"former_names": [
"Cloudless",
"Sunpia",
"Cloudless"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/0a8f293ade5299bdff930dd4920f116a323117fe.png",
"website": "http://sunpia.io",
"all_locations": "San Francisco, CA, USA; Remote",
"long_description": "Sunpia lets developers easily experience the cost and speed benefits of serverless infrastructure, without having to rewrite their code. Developers annotate their code and Sunpia automatically designs a microservice version of it they can deploy on their own cloud.",
"one_liner": "Deploy serverless without rewriting code",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1662145175,
"tags": [
"Developer Tools",
"Kubernetes",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2022",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/sunpia",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2022/sunpia.json",
"year_founded": 2022,
"city": "San Francisco",
"country": "US",
"linkedin_url": "",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/0a8f293ade5299bdff930dd4920f116a323117fe.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 642913,
"full_name": "Alan Pham",
"title": "Founder",
"founder_bio": "I graduated from UC Berkeley with Bachelors and Masters in EECS, conducting speech, systems, and machine learning research in image and natural language processing.",
"is_active": true,
"linkedin_url": "",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/a27a72c37109c1c901b876de9031cf673fae0a04.jpg"
},
{
"user_id": 1018399,
"full_name": "Ivy Pham",
"title": "Founder",
"founder_bio": "I graduated from Harvard with my B.A. in Economics and have a professional background in product management and business analytics. I'm interested in building solutions that can streamline workflows and improve efficiency. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ivylp/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b49108171ea04ad67b3241a46a410968686a66df.jpg"
},
{
"user_id": 1018726,
"full_name": "Vikranth Srivatsa",
"title": "Founder",
"founder_bio": "I graduated from UC Berkeley EECS doing systems and machine learning research. I do research as part of the UC Berkeley SKY Lab. I am interested in cloud/edge computing.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/vikranth-srivatsa-921067126",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/3d8e2384ae9d830057dff97ffe8af9d508d6c350.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 27177,
"name": "MovingLake",
"slug": "movinglake",
"former_names": [
"Moving Lake"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/ca7dff480b4b49f376fc3b90d1adc3c17872277f.png",
"website": "https://movinglake.com",
"all_locations": "Mexico City, CDMX, Mexico; Remote",
"long_description": "MovingLake is Fivetran for event-driven architectures. Companies such as Casai use our product to obtain orders and price changes in real time.",
"one_liner": "Realtime Data Connectors",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1657821965,
"tags": [
"SaaS",
"B2B",
"Analytics",
"API",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2022",
"status": "Active",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"Mexico",
"Latin America",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/movinglake",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2022/movinglake.json",
"year_founded": 2022,
"city": "Mexico City",
"country": "MX",
"linkedin_url": "https://www.linkedin.com/company/movinglake",
"x_url": "https://twitter.com/MovingLake",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/ca7dff480b4b49f376fc3b90d1adc3c17872277f.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Nicolas Dessaigne",
"url": "https://www.ycombinator.com/people/nicolas-dessaigne"
},
"founders": [
{
"user_id": 200174,
"full_name": "Andres Paez",
"title": "Founder",
"founder_bio": "Worked as a Software Engineer and Product Manager at Amazon Prime, Google Search and Google Cloud Platform for about 7 years. Have worked as the CTO of Casai and Valoreo for the last 3 years starting technology teams from scratch leading software engineers, hardware engineers, software managers, data engineers, data scientists, IT professionals, DevOps engineers, product managers and product designers.\n\n",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/andrespaezmartinez/",
"x_url": "https://twitter.com/APaezMx",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/224e0603789e0166a5ffd26612b9fe00f2bf79fb.jpg"
},
{
"user_id": 1104191,
"full_name": "Edgar Cabrera",
"title": "Founder",
"founder_bio": "About ten years of Sofware Engineer Experience at startups of several stages. I have worked in developing products from scratch until they become scalable, robust systems. I love the feeling of my work bringing value to others.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/edgarcabrera-dev/",
"x_url": "https://twitter.com/aleandros",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/c2dc5600f1710409129ac66012541518e8ca9acd.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 71150,
"title": "MovingLake - Vertical-first, realtime, AI-enabled data platform",
"tagline": "LLM-enabled data connectors, transformations and visualizations for e-commerce, hospitality and more",
"body": "Hi!\\\n**We are now launching our LLM-enabled BI tool which allows all of our clients to query their databases by using prompts in plain english.**\n\n\n\nHappy to announce that MovingLake user’s can not only get their data centralized in their data warehouse, but we are now enabling an end-to-end business intelligence experience where in a matter of minutes you can get the data flowing AND get the dashboards going.\n\nThis is important because not all of our clients are friendly with SQL or with BI tools. Letting them access their data in a secure way and using plain english questions is a game changer for them.\n\n**Ask**\n\nWe are looking to integrate to other data connector tools and companies as well as other data products to be able to give the most value faster to our clients. Please reach out if this would be interesting to your company.\\\n\\\nWe are available at [andres@movinglake.com](mailto:andres@movinglake.com) and [edgar@movinglake.com](mailto:edgar@movinglake.com) ",
"url": "https://www.ycombinator.com/launches/IVa-movinglake-vertical-first-realtime-ai-enabled-data-platform",
"votes": 17,
"created_at": "2023-04-24T19:26:45.556Z"
},
{
"id": 64655,
"title": "MovingLake: Realtime, event-driven data connectors",
"tagline": "Proprietary data connectors which feed both data and transactional systems",
"body": "Hey YC!\n\n[Edgar Cabrera](https://www.linkedin.com/in/edgarcabrera-dev/) and [I](https://www.linkedin.com/in/andrespaezmartinez/) are excited to launch [Moving Lake](https://movinglake.com/) today.\n\n**TLDR: MovingLake aims to do ETLs for event-driven architectures. Power your data warehouse as well as your microservices using the same API connectors.**\n\n### ⚠️ **What’s the Problem?**\n\nAfter talking to dozens of data engineers as well as technology stakeholders, and from our past experience, we uncovered a set of intertwined problems with current data connectors:\n\n1. A data connector does not provide data to transactional systems. This can lead to duplication of integration work plus lack of reliability between different sources of data. For machine learning this can be real trouble\n2. API integrations done in house are flaky and require a lot of investment in development and maintenance\n3. Event-driven architectures are reimplementing over and over again the same pieces of infrastructure such as schedulers, pollers and webhook receivers\n4. Batch extractors can skip states and so end up with missing data. For example if I have a booking business and a reservation gets cancelled 10 minutes after created, the batch pipeline will only see the cancelled state but not the created state.\n5. Running automations and other workflows is impossible with batch data connectors.\n\n### 👍 **What’s the solution?**\n\n**Realtime, event-driven, deduplicated, replayable, ELT friendly and SDK ready connectors which feed both data and transactional systems at the same time.**\\\nWe are rolling out connector for APIs which give you the ability to add any number of destinations including data and backend systems. We provide on top of that transformations for the data side so that you get the data in nicely formatted tables. Plus we also aim to provide easy to use SDKs so that consuming MovingLake’s webhooks is as easy and fast as possible.\\\n\\\n❓ **What’s the ask?**\n\nDo you have recurring issues with data reliability? Do you end up writing batch scripts to recover lost data from webhooks? Do you struggle with running your machine learning models from batch pipeline’s data? Reach out to [founders@movinglake.com](mailto:founders@movinglake.com) or contact us through our [website](https://movinglake.com/contact-us).\\\n\\\nThanks!",
"url": "https://www.ycombinator.com/launches/Gop-movinglake-realtime-event-driven-data-connectors",
"votes": 166,
"created_at": "2022-07-15T16:27:46.974Z"
}
]
},
{
"id": 27683,
"name": "Versori",
"slug": "versori",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/72ebeb10f18857a66bed8b775cde8113255925d4.png",
"website": "https://www.versori.com/",
"all_locations": "Manchester, England, United Kingdom",
"long_description": "Orchestrate custom integrations, workflows & agents in hours, not months. Take control of your integration strategy and breathe easy with maintenance on AI Autopilot.\r\n\r\nFor Product Teams: Build better integration libraries. Build a feature-rich integration library, for your users to enjoy. Offer out-of-the-box integrations that work for you and your customers. Embedded IPaaS typically locks you into connector or endpoint limitations. Versori gives you to tools for limitless customisation. Proactive, self healing agents, scan your connected apps for endpoint or schema changes. You get alerted, Versori AI fixes the change. Embed Versori built integrations into your app with the Versori SDK. Flexible to your development approach with advanced user management.\r\n\r\nFor Operations Teams: Get your internal systems speaking the same language. Deliver integrations for new software in days, not months—so you can start unlocking value immediately. Versori’s speed to value reduces typical deployment fees by half—or more. Low code for speed. Full code for control. No more limits from inflexible integration platforms.\r\n\r\nFor GTM & Sales Teams: Say yes to any prospect's integration request. Stop bouncing between teams to get integrations built. With Versori, Sales can go straight to yes. No more escalations or delays. Versori offer fully managed custom-builds, so your customers get exactly what they need, without compromise.",
"one_liner": "Agentic integrations & automations for enterprise",
"team_size": 16,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1666106474,
"tags": [
"SaaS",
"B2B",
"API",
"No-code",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2023",
"status": "Acquired",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United Kingdom",
"Europe",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/versori",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2023/versori.json",
"year_founded": 2022,
"city": "Manchester",
"country": "GB",
"linkedin_url": "https://www.linkedin.com/company/versori",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/72ebeb10f18857a66bed8b775cde8113255925d4.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 920068,
"full_name": "Sean Brown",
"title": "Founder",
"founder_bio": "Previously Founder and CEO at Mercarto (eCommerce/marketplace platform - acquired) and Hatch (Influencer Platform Acquired by Social Chain AG), Sean is fanatical about building technology to provide critical business infrastructure. \n\nHis strengths lie in Product and Business Development, by merging the two results in great product that delivers best in class products that provide high value solutions to clients. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/sean1brown/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/70365dc4555fdca3d8fb6a8d8dadd0d42615f3ad.jpg"
},
{
"user_id": 1164100,
"full_name": "Dan Jones",
"title": "Founder",
"founder_bio": "Dan is a CTO/Founder who loves getting stuck into code and is an advocate for all things cloud-native. With experiences in both public and private sectors, spanning industries such as Finance, Telecoms, Healthcare and Commerce, Dan has grounded himself as a versatile software engineer capable of solving complex problems in simple ways.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/dan-jones25217",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/97873b83b1e5f25d6c4c67f81c216b9f2ff7dbbd.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Manchester start up Versori wins $500k Y-Combinator funding Prolific North",
"url": "https://www.prolificnorth.co.uk/news/manchester-news/2022/10/manchester-start-versori-wins-500k-y-combinator-funding",
"date": "Oct 18, 2022"
}
],
"launches": [
{
"id": 91368,
"title": "Versori: Integration & workflow automation magic",
"tagline": "Go live with integrations built with Versori AI in hours, not weeks",
"body": "\n\nHey YC 👋\n\nWe just rebuilt the way integrations are done.\n\nLike many of you, we’ve wrestled with the limitations of traditional iPaaS tools: rigid templates, slow development cycles, poor customisation, and too many disconnected tools. \n\nSo we decided to take a different approach.\n\n**Versori AI** is a generative AI-powered integration and automation platform that enables businesses to build, deploy, and manage custom integrations and workflows with unprecedented speed and ease. \n\nWith Versori AI, businesses can connect APIs, automate processes, and deploy powerful integrations, across legacy systems, modern SaaS tools, and everything in between. Without the heavy lift of coding or cobbling together multiple platforms.\n\n[Here’s an intro to the new platform.](https://youtu.be/BF5_oVSQnKQ?feature=shared)\n\n**Key Features:**\n\n* **Prompt to Build:** Describe your integration needs in natural language, and Versori's AI will generate a complete workflow, including connector creation, data mapping, and deployment. [versori.com](http://versori.com)\n* **Flexible Modes**: Use a visual low-code editor, go full-code, or let the AI take the wheel. You’re in control.\n* **Transformer Mapping**: Powered by Agentic AI, we handle complex data transformations and mappings instantly, no manual field-matching required.\n* **Enterprise-Grade Security:** Benefit from SOC 2 compliance, data encryption, isolated environments per organization, and 24/7 monitoring and support.\n\nWe’re here to redefine what’s possible with integrations. Faster builds, deeper automation, more control, with the power of generative AI behind every step.",
"url": "https://www.ycombinator.com/launches/Nlg-versori-integration-workflow-automation-magic",
"votes": 10,
"created_at": "2025-06-18T04:47:50.968Z"
},
{
"id": 73415,
"title": "Versori Sparkboard: AI Integrations",
"tagline": "Create integrations and workflows with just a prompt",
"body": "[**Sparkboard**](https://sparkboard.versori.io/) is a prompt-based data integration and workflow automation tool. Just tell Sparkboard what you want to connect and automate and it will use generative AI agents to create a task list and get to work with those tasks.\\\n\\\n**Sparkboard will:**\\\n\\- Create a task list for agents to fulfill \\\n\\- Scrape the internet for the appropriate documentation\\\n\\- Build an OpenAPI spec with the correct auth methods and operations\\\n\\- Use [Versori](https://www.versori.com/) transformation tools to transform and map data\\\n\\- Offer full editing of the workflow with additional tools\\\n\\- Review your finished integration and publish!\n\n[Super Cool Marketing Video (please watch)](https://youtu.be/oIPXrf2088c)\n\n\n\n\n\n\n\n**Try it for free:** [**https://sparkboard.versori.io/**](https://sparkboard.versori.io/)",
"url": "https://www.ycombinator.com/launches/J67-versori-sparkboard-ai-integrations",
"votes": 12,
"created_at": "2023-07-25T16:54:38.432Z"
},
{
"id": 69359,
"title": "Versori - System & data integration platform",
"tagline": "We help enterprises connect any internal system to any external system without hiring expensive consultants.",
"body": "**Hello YC!** 👋\n\nAwesome to be here and proud to be part of this fantastic community.\n\nWe’re Sean and Dan, the Founders of [**Versori.**](https://www.versori.com/)\n\n\n\n### **The Problem 😫**\n\nThe enterprise integration market is controlled by traditional system integrators (Accenture, Cognizant, Capgemini etc), who charge for professional services and manual development.\n\nTime, money and resource is wasted on manual system and data integrations. Complex iPaaS solutions aren’t easy, and easy iPaaS solutions aren’t complex.\n\n### **The Solution 😊**\n\nVersori “Switchboard” is a no-code system and data integration platform, primarily for major retailers that lets them connect any internal system to any external system without hiring expensive consultants. \n\nFor example, Sephora used Versori to build an integration that imports 3rd party brand products into its own ecommerce site in a few clicks. Reducing integration time from 9 weeks to 2 hours.\n\n[Here’s an intro video](https://www.youtube.com/watch?v=d7T1z3nxoD0&t=3s&ab_channel=Versori)\n\n**Create data sources (connectors) in seconds, not weeks.**\n\n* Drag and drop or paste the URL to your API specs\n* Switchboard strips and stores the auth and server types, end points, operations and schemas.\n\n**Build complex and advanced integrations with no-code tools**\n\n* **_Transformer_** provides functionality to take data from multiple sources into a format suited for your target, with all the features you’d expect such as filtering, converting and mapping.\n* **_Selectors_** gives you access to any data from all previous steps in your board, allowing you to perform complex tasks such as merging or flow-control.\n* **_Data Mapping_** allows you to define mappings where some value in one system is equivalent to another value in another system. These can be defined up front in our dashboard, or interactively updated within your board.\n* **_Filter_** allows you to stop or continue execution of a workflow based on a set of conditions. These conditions can be as simple or as complex as your data requires, and can be combined with Selectors to compare data from multiple workflow steps.\n* **_Delay_** halts execution of the current message until a predefined duration has elapsed.\n* **_Batch_** aggregates all data received over a specified batch period before releasing the result to subsequent steps and is useful when integrating real-time APIs with bulk import/export APIs.\n* **_Trigger_** allows a board to be triggered manually or via a schedule instead of via an external API call\n* **_CSV Processing_** allows you to truncate, join and deduplicate CSV files\n* **_Splitter_** takes in an array and outputs multiple new messages for each element in that array\n\n**Deploy integrations and workflows your way**\n\n* Public Cloud\n* Private Cloud\n* On Prem\n* SDK\n\n### **We can integrate your systems, that Zapier can’t.. ⚡️**\n\nYou need the break free from the static guard rails of existing integration platforms!\n\nIf your company has bespoke system or data integration requirements, that can’t be done with an existing IPaaS provider, please reach out to us at [sales@versori.io](mailto:sales@versori.io). We would love to give you a demo!\n\n### **The Deal 🤑**\n\nFor all YC Alum, the first 10,000 data messages are on the house!",
"url": "https://www.ycombinator.com/launches/I2h-versori-system-data-integration-platform",
"votes": 132,
"created_at": "2023-02-16T17:19:59.571Z"
}
]
},
{
"id": 27697,
"name": "Lume",
"slug": "lume-2",
"former_names": [
"Abyssinia"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/053379bcb6d2f8ca33ff9eb81f1d899a06a6872a.png",
"website": "https://www.lume.ai",
"all_locations": "",
"long_description": "Lume speeds up customer implementation with AI. Lume helps teams analyze, map, and ingest customer data up to 87% faster, accelerating time-to-revenue.",
"one_liner": "Speed up customer implementation with AI",
"team_size": 5,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1675974530,
"tags": [
"SaaS",
"B2B",
"Data Engineering",
"Infrastructure",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2023",
"status": "Acquired",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"Unspecified"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/lume-2",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2023/lume-2.json",
"year_founded": 2022,
"city": null,
"country": null,
"linkedin_url": "https://www.linkedin.com/company/lume-ai/",
"x_url": "https://twitter.com/TryLume",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/lume-ee1a",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/053379bcb6d2f8ca33ff9eb81f1d899a06a6872a.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/a4a09c0df0505d292ec360324b588ebb509217e1.png"
],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 1157038,
"full_name": "Robert Ross",
"title": "Founder",
"founder_bio": "Co-Founder of Lume (W23) || Stanford CS ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/robertross04",
"x_url": "https://twitter.com/imrobertross",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/5e7508e23027231f8a8a622784d767f645ba2af1.jpg"
},
{
"user_id": 1159508,
"full_name": "Nicolas Machado",
"title": "Founder",
"founder_bio": "Co-Founder of Lume (W23), Stanford AI, Brazilian.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/machado-nicolas",
"x_url": "https://twitter.com/machado___nic",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b9c71f39931d9c5a32bd9eafa8eb0f2fbf504d6f.jpg"
},
{
"user_id": 1141304,
"full_name": "Nebyou Zewde",
"title": "Founder",
"founder_bio": "Co-Founder of Lume, Stanford CS AI, Ethiopian ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/nebyou-zewde-b6ba02157/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ea4b965b24c80d662cb2560764c500023276586c.jpg"
}
],
"jobs": [],
"news": [
{
"title": "General Catalyst and Khosla Ventures back data mapping startup Lume | TechCrunch",
"url": "https://techcrunch.com/2024/11/12/general-catalyst-and-khosla-ventures-back-data-mapping-startup-lume/",
"date": "Nov 12, 2024"
}
],
"launches": [
{
"id": 81770,
"title": "Lume: Automate data mappings using AI",
"tagline": "Ingest client data, normalize data from different sources, and build data pipelines, automatically.",
"body": "**TL;DR**\n\nLume helps teams map data between systems with AI. If your team spends time mapping data for customer data onboarding, data normalization between systems, or mapping for data integrations, we can help! Please go to our [website and sign up](https://www.lume.ai/?utm_source=ycombinator&utm_medium=social&utm_campaign=launch_yc_5_24) for a free trial.\n\n—-\n\nHi everyone! We are Nicolas, Nebyou, and Robert, the founders of Lume. We are on a mission to automate the painstakingly manual process of data mapping, after experiencing this frustration as engineers ourselves. We have onboarded several customers who are growing and are excited to help more teams use AI in their data mapping workflows.\n\n\n\n**🧨 Problem**\n\nThe usual mapping process involves a labor-intensive cycle: analyzing data to determine what's relevant, selecting the appropriate properties, developing the mapping logic, and constantly updating mappers to accommodate schema changes in source or target systems. This process, we learned, takes days, weeks, or even months for most teams, and automating it has traditionally been borderline impossible due to unique differences in data.\n\n**✨ Solution**\n\nLume uses AI to automatically map data between any start and end schema, whether it is customer data, external sources, or anything else. Lume provides this via an API and a no-code platform where you can generate mapping logic, review and edit it, and manage multiple data pipelines. Whether you want to onboard customer data, normalize data from multiple sources, or create auto-mapping UIs over Lume, Lume delivers. With automated transformations and data delivery, error and type checking, auto-maintenance with schema inference, and execution via an API or a no-code App for different use cases, teams can spend more time delivering their core value to customers instead of wrangling and manually mapping data.\n\n**🚀 Key Features**\n\n* ✨ Generate mapping logic in seconds: via our API or the Lume app, simply pass in a sample of your source data and a target format, and Lume will generate the mappings.\n* 🛠️ Edit mapping logic: review and edit the mapping logic and mapped data as needed to ensure you have the desired outcome. Leverage tools ranging from natural language all the way to full code edits to edit the mappers quickly and easily.\n* ✅ Deploy mappers: Use the mappers deterministically in your code via our API or the app, allowing you to reliably move data between schemas as you scale your data pipelines.\n* 🤖 Auto-maintain mappers: Lume detects changes in your schemas, notifying you and allowing you to use AI to update the mapping logic, effectively automating your maintenance.\n* 📊 Manage and organize mappers: use Lume’s dashboard to have visibility over all of your mappers and live data pipelines.\n* 📑 Handle any format: Lume supports JSON, CSV, XLS, PDF, and other formats! You can move data through the API or the app.\n* 🔮 Upcoming: adding custom logic with lambda functions, custom validation rules, python SDK, transferring your existing mappings when migrating to Lume, and more.\n\n**⚙️ How it works**\n\n* To create mappers: specify your target structure and provide a sample of source data. This can be done via the Lume API or the Lume Platform.\n\n\n\n* ✨ Lume’s AI system creates the mappings between any two schemas, ranging from simple 1-1 mappings, time-series aggregations, complex calculations, and ontology classifications.\n* Use the generated mappings and mapping logic: Use the Lume API or the Lume Platform to upload new incoming data and retrieve the corresponding output mapped data and mapping logic. Your data has just been automatically mapped with AI!\n\n \n\n* For creating robust data pipelines, review and edit the generated mapping logic before running production data. Once saved, you can confidently use these mappers as deterministic pipelines. This is helpful for your data integrations between systems.\n\n\n\n\n\n* Alternatively, build on top of the Lume API to deploy your own auto-mapper UI to allow customers to self-onboard.\n\n**💡 Use Cases**\n\nLume handles three core use cases:\n\n* Onboarding Client Data\n* Normalizing Data from Multiple Sources\n* One to Many Integrations\n\nHere are three customer success stories:\n\n* For a growth-stage battery analytics company, mapping each customer’s sensor data went from 2 weeks to 1.5 hours with Lume.\n* For a large HR analytics platform, Lume mapping accuracy reached 95% for their most recent batch of integrations, saving them weeks of onboarding time for mapping and classifying data from incoming systems.\n* For an early-stage financial product startup, Lume is handling \\~500 live data pipelines that are externally facing, constantly mapping and adapting to new incoming data.\n\nAll of these have the common theme of having to map data between unique schemas, where even discrepancies as minor as column name variations make this process time-consuming and near-impossible to automate. This gets even worse at scale. Clients previously were allocating engineers, customer success teams, or offshore labor to analyze incoming data, map the data, and route it to their new systems. This process used to take up to multiple months for some teams, costing significant time and money.\n\nWe serve multiple industries ranging from ecommerce, insurance, manufacturing, and financial products.\n\n**👨💻Meet the Team**\n\n\n\nMy co-founders Nebyou Zewde (right), Robert Ross (middle), and I (left) all met during our first year at Stanford. As engineers ourselves, we’ve spent plenty of time grudgingly going over the manual task of mapping data. We quickly learned that we were not the only ones who faced this problem - most companies spend too much time on this. As AI grads, and with a fire for this problem, we built Lume AI. We are part of the Y Combinator W23 batch, and we’re excited to be launching here.\n\n**🙏 Our ask**\n\n* Sign up for a free trial to get started by [visiting our website](https://www.lume.ai/?utm_source=ycombinator&utm_medium=social&utm_campaign=launch_yc_5_24) or [booking a call here](https://cal.com/team/lume/intro). We’ll get you on a Slack and onboarded quickly.\n* Share this with anyone who works on data mapping for customer onboarding, data normalization, or moving data between any two systems. We support a variety of use cases.\n* Upvote and share this post!\n\n**💥 The Deal**\n\nMention you saw Lume via Launch YC, and we will give you a 50% discount for your first 6 months. We also offer a free pilot.",
"url": "https://www.ycombinator.com/launches/LGs-lume-automate-data-mappings-using-ai",
"votes": 40,
"created_at": "2024-06-26T17:31:22.598Z"
},
{
"id": 70009,
"title": "Lume - No-code tool to create and maintain custom data integrations",
"tagline": "Lume uses AI to automatically transform data between any start and end schema.",
"body": "**TL;DR**\n\nLume helps engineering teams build and maintain custom data integrations with no code. If you spend countless hours manually transforming data for custom integrations, we can help! Please go to our [website](https://www.lume.ai/?utm_source=ycombinator&utm_medium=social&utm_campaign=launch_yc_5_23) and sign up for our private beta.\n\n—-\n\n---\n\nHi everyone! We are Nicolas, Nebyou, and Robert, the founders of Lume. We are on a mission to empower companies to focus on delivering their core value proposition rather than spending time on data integrations and transformations. \n\n\n\n**🧨 Problem** \n\nEngineers spend countless hours manually transforming data for custom integrations or pay large amounts to consulting firms to do the same. Dynamic schemas from different clients or apps require engineers to build and maintain custom integration pipelines one by one, and companies spend days, weeks, and even months building integrations. Lume is tackling this problem head-on. \n\n**✨ Solution**\n\nLume uses AI to automatically transform data between _any_ start and end schema and pipes the data directly to your desired destination. Lume provides this through a no-code platform where you can build and maintain your custom data integrations. Whether you want to map multiple sources to your internal unified schema or connect to your third-party apps without manual mapping, Lume delivers. With automated transformations and data delivery, backtesting and data quality checks, and version control, engineers can spend more time delivering their core value to customers instead of wrangling and manually mapping data. \n\n**⚙️ How it works**\n\n* You connect your custom schemas and authenticate into your desired apps.\n* Lume’s AI system creates the transformations between any two schemas, ranging from internal schemas to structured third-party apps.\n* Once you validate the transformed data, Lume will pipe the correct data to your specified destination.\n\nWe can connect to your data warehouse and leverage its compute to keep your data in-house.\n\n**Common Use Cases:**\n\n* Internal: Transforming separate data sources into one unified internal ontology\n * Ex: a unified schema between Salesforce, Hubspot, Quickbooks, and Pipedrive.\n* External: Custom syncs between your SaaS apps\n * Ex: Enrich CRM data from multiple sources before sending it to your BI tool\n* Onboarding: Mapping prospective client data to fit your product’s input schema\n * Ex: Consulting firms mapping each new clients’ unique ERP schemas to their internal ontology on Snowflake.\n* Migration: Creating custom integration pipelines between competitor products to yours \n * Ex: New productivity tool startup creates an “Import from Notion/Evernote” for newly converted users.\n\n**👨💻Meet the Team**\n\n\n\nMy co-founders Nicolas Machado (right), Nebyou Zewde (middle), and I (left) all met during our first year at Stanford, where we received our undergraduate and Master's degrees in computer science with a focus on Artificial Intelligence. With experience working at both unicorn startups and big tech companies, our team has knowledge and experience building and deploying applied machine learning systems.\n\n**🙏 Our ask**\n\n* Sign-up for our [private beta](https://www.lume.ai/?utm_source=ycombinator&utm_medium=social&utm_campaign=launch_yc_5_23) if you want to try Lume and see a demo.\n* Share this with anyone that works on custom data integrations.\n* Upvote and share this post!\n\n**💥 The Deal**\n\n**Sign-up before demo day for a 50% discount for the first year!**",
"url": "https://www.ycombinator.com/launches/IDB-lume-no-code-tool-to-create-and-maintain-custom-data-integrations",
"votes": 251,
"created_at": "2023-03-07T18:12:57.774Z"
}
]
},
{
"id": 27762,
"name": "Ohm",
"slug": "ohm-2",
"former_names": [
"Byterat"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/55b1c275e0ba176abf2805a822f08b78ecea7eba.png",
"website": "https://www.ohm.ai",
"all_locations": "San Francisco, CA, USA",
"long_description": "Ohm’s AI platform helps Fortune 100 engineering teams accelerate the engineering and testing of complex hardware, including wearables, electric vehicles, and batteries. Launched in 2025, Ohm's platform is used by leading teams to compress development cycles, optimize test programs, and launch better products, faster.",
"one_liner": "Ohm helps engineering teams accelerate hardware development & testing.",
"team_size": 7,
"industry": "Industrials",
"subindustry": "Industrials",
"launched_at": 1676603508,
"tags": [
"Hardware",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2023",
"status": "Active",
"industries": [
"Industrials"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/ohm-2",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2023/ohm-2.json",
"year_founded": 2023,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/ohm/",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/55b1c275e0ba176abf2805a822f08b78ecea7eba.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Jared Friedman",
"url": "https://www.ycombinator.com/people/jared-friedman"
},
"founders": [
{
"user_id": 1145681,
"full_name": "Penelope Jones",
"title": "Founder",
"founder_bio": "Founder and CEO of Ohm. Previously PhD (Physics) at Cambridge",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/penelope-jones-396a94105/",
"x_url": "https://twitter.com/penelopekjones_",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/5fb6a6f532ae5c0d59a3a1cf7a9195600808ebfb.jpg"
}
],
"jobs": [
{
"id": 100834,
"title": "Full Stack Engineer",
"url": "https://www.ycombinator.com/companies/ohm-2/jobs/rF5JtAx-full-stack-engineer",
"location": "San Francisco, CA",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 100835,
"title": "Forward Deployed Engineer, Test & Validation",
"url": "https://www.ycombinator.com/companies/ohm-2/jobs/Od4JrPn-forward-deployed-engineer-test-validation",
"location": "San Francisco, CA / Remote (US)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 100836,
"title": "Applied Machine Learning Engineer",
"url": "https://www.ycombinator.com/companies/ohm-2/jobs/oAT3a9A-applied-machine-learning-engineer",
"location": "San Francisco, CA / Remote (US)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 100837,
"title": "Founding Account Executive, EMEA",
"url": "https://www.ycombinator.com/companies/ohm-2/jobs/JOlqA1X-founding-account-executive-emea",
"location": "Remote (US)",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 100838,
"title": "Founding Account Executive",
"url": "https://www.ycombinator.com/companies/ohm-2/jobs/jn6BlBR-founding-account-executive",
"location": "San Francisco, CA / Remote (US)",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 100839,
"title": "Forward Deployed Engineer, Battery Engineering",
"url": "https://www.ycombinator.com/companies/ohm-2/jobs/p4AdikP-forward-deployed-engineer-battery-engineering",
"location": "San Francisco, CA / Remote (US)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 105576,
"title": "Chief of Staff",
"url": "https://www.ycombinator.com/companies/ohm-2/jobs/OOZ8aTx-chief-of-staff",
"location": "San Francisco, CA, US / Remote (London, England, GB)",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "$120K - $170K",
"equity_range": "0.20% - 0.50%",
"experience": "Any (new grads ok)",
"visa": "US citizenship/visa not required",
"skills": []
},
{
"id": 112875,
"title": "Founding GTM Intern",
"url": "https://www.ycombinator.com/companies/ohm-2/jobs/gJ5Oglm-founding-gtm-intern",
"location": "San Francisco, CA, US",
"type": "Contract",
"role": "Marketing",
"role_type": null,
"salary_range": "$1K - $2.5K / monthly",
"equity_range": "0.01% - 0.10%",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": []
}
],
"news": [
{
"title": "Byterat nabs $4M seed round to collect and analyze data for battery labs | TechCrunch",
"url": "https://techcrunch.com/2023/10/27/byterat-seed-round/",
"date": "Oct 27, 2023"
}
],
"launches": []
},
{
"id": 27868,
"name": "Outerbase",
"slug": "outerbase",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/e7ffc83c79c7fc5268f3ebcb40e602151effc32b.png",
"website": "https://www.outerbase.com",
"all_locations": "Pittsburgh, PA, USA; San Francisco, CA, USA; Remote",
"long_description": "Outerbase is the interface for your database. Companies use Outerbase to view, edit, and modify their data and even generate beautiful visual dashboards without having to write a single line of SQL.",
"one_liner": "The interface for your database",
"team_size": 4,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1673832882,
"tags": [
"Developer Tools",
"Generative AI",
"Analytics",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2023",
"status": "Acquired",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/outerbase",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2023/outerbase.json",
"year_founded": 2022,
"city": "Pittsburgh",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/outerbase",
"x_url": "https://www.twitter.com/outerbase",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/outerbase",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/e7ffc83c79c7fc5268f3ebcb40e602151effc32b.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 1247130,
"full_name": "Brandon Strittmatter",
"title": "Founder",
"founder_bio": "Brandon is co-founder of Outerbase, the interface for your database. Modern teams use Outerbase to view, edit, query, visualize, and share their data. Prior to co-founding Outerbase, Brandon led design for DigitalOcean's managed solutions (App Platform, Serverless, and DBaaS (Database as a Service), and was the founding designer of Containership, a startup building a multi-cloud Kubernetes platform.",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/brandonstrittmatter",
"x_url": "https://www.twitter.com/burcs",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b75559606ef38a37cbdc92a165ab1b5950adb763.jpg"
},
{
"user_id": 505802,
"full_name": "Brayden Wilmoth",
"title": "Founder",
"founder_bio": "Brayden is a co-founder of Outerbase, the interface for your database. Prior to founding Outerbase, Brayden was a software engineering manager at Walmart leading multiple teams of engineers on various platforms for the native applications and web experiences. At his time there he guided teams in making key data-driven decisions, in which he took his experience from to assist in building Outerbase.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/brayden-wilmoth/",
"x_url": "https://twitter.com/BraydenWilmoth",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/30c5b71e48d1a39556079a95091351ba214bedd7.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 69291,
"title": "👾 Outerbase – Interface for your database",
"tagline": "Outerbase is the easiest way for you and your team to securely access your data.",
"body": "Hi everyone – we are Brandon & Brayden from Outerbase.\n\n**📚 TL;DR**\n\nCurrent database tooling is poorly designed and historically been targeted solely at developers. Outerbase is a modern platform that allows you and your entire team to view the data you need whether it be in Postgres, MySQL, Snowflake, BigQuery or more.\n\n### \n\n**🪨 The Problem**\n\nGetting access to your data is hard. Typically there are only a few people who hold the keys to it at any given company and they quickly become a bottleneck on data requests. The tooling around it is outdated and poorly designed, and not intended for the modern collaborative work environments.\n\n\n\n### \n\n**⚒️ Our Solution**\n\nOuterbase provides an intuitive interface with granular access to your data. It has a familiar spreadsheet-like experience that anyone can use. Outerbase’s EZQL provides a sql-less experience through the use of GPT-3. You can take those same queries and create beautiful dashboards all in one experience.\n\n### \n\n**⚙️ How Outerbase Works**\n\nWe sit on top of most relational database types, including Postgres, MySQL, Redshift, BigQuery, and Snowflake. You simply provide your database credentials and Outerbase gives you a spreadsheet-like experience to view, edit, query, and visualize your data. Since access is based on your credentials you can easily control how granularly your team accesses your data. Our EZQL feature is powered by OpenAI and takes your databases schema and structures your questions/queries based on it.\n\n\n\n### \n\n**🙋 Asks**\n\nTry Outerbase, simply [sign up](https://app.outerbase.com/signup) and get started with our demo database, or add your own database credentials in the connections tab. You can also [download](http://app.outerbase.com/downloads/Outerbase.dmg) our mac app.\n\nIf you know of anyone trying to kick off the process of making data-driven decisions but doesn’t know where to start, please intro them to us!\n\nJoin our Slack [community](https://join.slack.com/t/outerbasecommunity/shared_invite/zt-1ple7fhsg-2z6MIC_P4fzdrKe1koJ7kQ).\n\nAnd, if you have 15 minutes to chat about your pain points accessing your data please book some time [here](https://calendly.com/outerbase/demo).",
"url": "https://www.ycombinator.com/launches/I1b-outerbase-interface-for-your-database",
"votes": 86,
"created_at": "2023-02-14T23:19:39.388Z"
}
]
},
{
"id": 27897,
"name": "TableFlow",
"slug": "tableflow",
"former_names": [
"Inquery"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/fad6d127e5843dda3d9f06585de22ad73a6df795.png",
"website": "https://tableflow.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "TableFlow builds AI teammates for data tasks, helping operations and data teams automate the messy, manual tasks buried in PDFs, spreadsheets, images, and emails.",
"one_liner": "AI Teammates for Data Tasks",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Operations",
"launched_at": 1676487521,
"tags": [
"Documents",
"SaaS",
"Data Engineering",
"Automation",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2023",
"status": "Active",
"industries": [
"B2B",
"Operations"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/tableflow",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2023/tableflow.json",
"year_founded": 2022,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/tableflowhq",
"x_url": "https://x.com/tableflow",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/tableflow",
"github_url": "https://github.com/tableflowhq",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/fad6d127e5843dda3d9f06585de22ad73a6df795.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 405594,
"full_name": "Mitch Patin",
"title": "Founder",
"founder_bio": "Co-founder and CEO at TableFlow. Early engineer at Bolt (transitioned to product). First product hire at Heymarket.\n",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/mitchpatin/",
"x_url": "https://twitter.com/mitchpatin",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/1951bf8df013b0f7a0a692a6e5c288aa4392e57c.jpg"
},
{
"user_id": 1166460,
"full_name": "Eric Ciminelli",
"title": "Founder",
"founder_bio": "Co-founder and CTO at TableFlow. Early engineer on the commerce team at Facebook. First full-stack engineering hire at Heymarket.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ericciminelli/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/2387b88cd77c1ab73a503d75967f5c28c5365823.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 73464,
"title": "🛶 TableFlow: AI Document Processing",
"tagline": "Extract, transform, and validate data from any file: CSV, PDF, and more",
"body": "### TL;DR\n\nTableFlow enables enterprises to extract and transform unstructured data from CSVs, PDFs, images, and web pages. Instead of spending time on manual data entry and validation, teams use TableFlow to automate these tasks with AI.\n\n\n\nHi everyone, we’re Eric and Mitch from [TableFlow](http://tableflow.com)! 👋\n\n### Problem\n\nMany companies rely on spreadsheets, PDFs, and other file types to import partner or customer data, which exists in a variety of formats. This difficult and time-consuming process often leads to companies relying on a combination of in-house tooling and manual work to migrate the data. This becomes even more problematic when ingesting hundreds or thousands of files a week.\n\n### Solution\n\nTableFlow handles the file import process with automated pipelines that use AI to map, extract, transform, and validate data.\n\n**How it works:**\n\n1. Define your destination schema in our app. These are the columns and data types that you want to transform data to.\n2. Import a file via our API.\n3. Receive a webhook when the file finishes processing (takes \\~10 seconds, even with 100k+ records). This will include any errors, such as a required field being missing.\n4. Optional: Review the imported data in our application before continuing.\n5. Import the cleaned, transformed data into your system.\n\n[Demo Video](https://www.loom.com/share/a07bfd2c55454127afa44df31a973c81?sid=42c402db-1ee5-4886-a009-484bcdc1df3a)\n\n### TEAM\n\nWe met while working at Heymarket, a Series-A startup in SF. Mitch was the first product hire, and Eric was the first full-stack engineer. During our two years there, we co-owned many projects and defined many of the engineering & product processes to help the company scale. We became friends outside of the office by talking about startups, tennis, pickleball, and mountain biking.\n\n[Mitch](https://www.linkedin.com/in/mitchpatin/) started his career as an engineer before moving to the dark side (product 😛). He previously worked at GE Digital and Bolt and founded a company focused on B2B payments.\n\n[Eric](https://www.linkedin.com/in/ericciminelli/) is a software engineer who previously worked at Facebook and myMatrixx and co-founded a company that created a search engine for car shopping online.\n\n### Asks\n\n💌 If your team handles recurring imports of data in different schemas and formats, we’d love to hear about the problems you’ve encountered. Just leave your info [here,](https://tableflow.com/join-waitlist) and we’ll reach out!",
"url": "https://www.ycombinator.com/launches/J6u-tableflow-ai-document-processing",
"votes": 122,
"created_at": "2023-07-26T20:36:20.772Z"
}
]
},
{
"id": 27951,
"name": "Honeydew",
"slug": "honeydew",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/628b819928f75f1e921c92594fbcd9a7e63a91b4.png",
"website": "https://honeydew.ai",
"all_locations": "Tel Aviv-Yafo, Tel Aviv District, Israel",
"long_description": "The way people use data is constantly changing. Data teams must support every new context without breaking the shared truth. Honeydew’s semantic layer does it automatically. We validate each change and update every data flow.\r\n\r\nUsing Honeydew, data teams can support 10x more data users - without more engineers or compromising integrity. ",
"one_liner": "The home for shared data logic",
"team_size": 6,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1670747027,
"tags": [
"SaaS",
"B2B",
"Analytics",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2023",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"Israel",
"Middle East and North Africa",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/honeydew",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2023/honeydew.json",
"year_founded": 2022,
"city": "Tel Aviv-Yafo",
"country": "IL",
"linkedin_url": "https://www.linkedin.com/company/honeydewai/",
"x_url": "https://twitter.com/honeydewai",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/honeydew",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/628b819928f75f1e921c92594fbcd9a7e63a91b4.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 1136239,
"full_name": "David Krakov",
"title": "Founder",
"founder_bio": "My last 20 years are in and around data and software. At the first startup I founded, Varada (acq. by Starburst), we created an acceleration engine for data lakes - helping queries run faster on huge amounts of data. Before becoming a founder, I was an early employee at XtremIO (later EMC) - which became the market leader in all-flash-storage. Even before that, I was a computer science and physics nerd. Still am.\nI live in Tel Aviv with my wife and two kids. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/david-krakov/",
"x_url": "https://twitter.com/davidkrakov",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/c6c2fb2d3b5ae7581f5df895e8643eb265b8403d.jpg"
},
{
"user_id": 1136236,
"full_name": "Baruch Oxman",
"title": "Founder",
"founder_bio": "I have been in software for over 20 years, leading technology and engineering, and building products around data. I was the first employee of Implisit, building AI for sales. After being acquired by Salesforce, I led the architecture and engineering of Einstein for Sales.\nMy passion is traveling, cycling and finding simple solutions for complex problems.\nI live in Tel Aviv, with my wife and 2 daughters.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/baruchoxman/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/14f768338d6f6f473330eb9d5283885546392639.jpg"
},
{
"user_id": 1136228,
"full_name": "Liron Slonimsky-Shemy",
"title": "Founder",
"founder_bio": "In my previous life, I worked as a script writer (and even won first prize for best drama feature), I pivoted and decided to \"produce\" my scripts in real life by opening a startup. At my first startup, Awear, we did \"Frequent-Flyer for fashion\" - We sold data to fashion companies showing how people are actually wearing their garments. \nCurrently living in Tel Aviv with my husband and our two kids - Orr and Eyal.\n",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/liron-slonimsky-0aba3240/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/66ae854df6096e8b14ca316b4f868ae7379d43d2.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 70089,
"title": "🍈 Honeydew - one truth to rule them all",
"tagline": "We help data teams achieve consistent metrics like Revenue or Churn",
"body": "# TL;DR\n\n**We are a shared source of truth for data teams living** **in the data warehouse.**\n\nWhy is it that your “daily active users” never add up to the same number in different reports? Your data team is amazing, but it’s a struggle to keep all metrics synchronized. There is no single place that enables a shared workflow and truth.\n\nHave you ever seen a screw-up like:\n\n1. Presenting wrong numbers in an exec meeting 🤦♂️\n2. Not being able to understand how a KPI such as Daily Active Users, Churn or ARR was built 😡\n3. Spending all your time on preparing and transforming data instead of producing insights on top of it 😫\n4. Making a change to a KPI calculation and breaking the CEOs favorite dashboard 🙀\n\nWe fix this! [Honeydew](https://honeydew.ai/) helps the data team organize analytics into manageable blocks of knowledge supporting every data flow. Users can consume them in SQL, Tableau, Looker, Python, or dbt.\n\nOur product is being used by multiple early adopters - unicorn companies in cyber, insurance tech, and cloud ops.\n\nWe (Baruch, Liron and David) always want to talk, at [founders@honeydew.ai](mailto:founders@honeydew.ai); or just [grab a time](https://calendly.com/d/yjm-8jd-pwt/honeydew-20min-call) if you ever felt or feel the data mess pain.\n\n\n\n---\n\n# **Would you like to know more?**\n\n### 💡 How does it work?\n\nWe connect to Snowflake and act as a layer on top of it for different data tools.\n\n(_we don’t need to access your data, and yes - we are SOC2-compliant_)\n\nThen,\n\n1. Map the source data and relations (we can map it automatically for you 😎)\n2. Create reusable pieces of logic like what is a _User_, what is _Active_, what is _Daily_\n3. Create a workflow around it, that helps the team to control changes\n4. Connect any tool, it will use the same logic ✌️: Tableau, Looker, dbt, Python or SQL\n5. Under the hood: we’ll will build the needed data pipeline on the fly and then maintain it to reflect the current truth.\n\n\n\n---\n\n### 🏗️ Why did we build this?\n\nAll three of us encountered and solved this problem in our previous roles.\n\nLiron founded a company that turned fashion consumer behavior data into real-time (yes, the numbers always lie 🤥 ). Baruch built AI products on sales data in Salesforce (yes, the numbers lie even with AI 🤥 ). David founded a company that built data lake acceleration (we calculated everything right, the questions lied 🤥 ).\n\nSo far we talked with over 300 analytics teams. They were all busy trying to get consistent data their stakeholders can trust. The surprising thing is that there is a gap that nobody is filling at the moment - this gap was covered before BI like Looker, and even before with likes of SAP Business Object. We fill this gap.\n\n### 👩💻 Why do customers want to use Honeydew?\n\n* “I struggle to keep logic in Looker and in the warehouse the same. I want to build it once”\n* “I am building a new data team, and I don’t want to end up with another dbt spaghetti”\n* “We have every tool in the modern data stack, and yet our KPIs calculations end up being managed in a wiki, reimplemented in ETL and dashboards. This does not make any sense”\n\n### 🙏 Our ask\n\n* Does your company have a data team? We would love to talk to them!\n* Does your company plan to have a data team? We would love to talk to you!\n* Do you like to talk about data in general? We also do, any time 😀\n\n### 🍈 Our deal\n\n* Sign up before demo day, and we do all the onboarding for you, free of charge\n\nLove - team [Honeydew](https://honeydew.ai/)\n\nFind us at [founders@honeydew.ai](mailto:founders@honeydew.ai); or just [grab a time](https://calendly.com/d/zyr-qvr-dhv/honeydew-grab-a-time)",
"url": "https://www.ycombinator.com/launches/IET-honeydew-one-truth-to-rule-them-all",
"votes": 260,
"created_at": "2023-03-09T14:22:45.602Z"
}
]
},
{
"id": 28650,
"name": "Artie",
"slug": "artie",
"former_names": [
"Artie Technologies"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/973d2f0c6c4d07505113e974a08d18864eb95d54.png",
"website": "https://www.artie.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Artie is software that streams data from databases to data warehouses in real-time. Today, most companies run their ETL process every few hours or overnight, so their data warehouse is always out of date; with Artie, the warehouse always has live production data.",
"one_liner": "Software that streams data from databases to warehouses in real-time",
"team_size": 20,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1684375922,
"tags": [
"Developer Tools",
"SaaS",
"Data Engineering",
"Enterprise Software"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Summer 2023",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/artie",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2023/artie.json",
"year_founded": 2023,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/artie-technologies/",
"x_url": "https://x.com/artie_labs",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/artie-a438",
"github_url": "https://github.com/artie-labs/transfer",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/973d2f0c6c4d07505113e974a08d18864eb95d54.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Jared Friedman",
"url": "https://www.ycombinator.com/people/jared-friedman"
},
"founders": [
{
"user_id": 1276059,
"full_name": "Jacqueline Cheong",
"title": "Founder",
"founder_bio": "Co-founder and CEO at Artie. Building the real-time data streaming platform for AI. \n\nWe give companies the kind of streaming pipelines and deep observability that Netflix, DoorDash, and Instacart built in-house - without hiring 10+ engineers and spending 1-2 years on platform work. Artie automates the entire data ingestion lifecycle, from capturing changes to merges, backfills, and observability, and scales to billions of change events per day. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jacqueline-cheong/",
"x_url": "https://x.com/JacquelineSYC19",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9ffed376cfde87489929309878adbde531752727.jpg"
},
{
"user_id": 674147,
"full_name": "Robin Tang",
"title": "Founder",
"founder_bio": "CTO @ Artie. Software engineer with a background in distributed systems.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/tang8330/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/7cdcac4bb146b8aabcbb1bc6751fee1c6c37d9b5.jpg"
}
],
"jobs": [
{
"id": 85441,
"title": "Enterprise Account Executive",
"url": "https://www.ycombinator.com/companies/artie/jobs/HyaHWUs-enterprise-account-executive",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Sales",
"role_type": null,
"salary_range": "$240K - $320K",
"equity_range": "",
"experience": "6+ years",
"visa": "Will sponsor",
"skills": []
},
{
"id": 94613,
"title": "Solutions Engineer",
"url": "https://www.ycombinator.com/companies/artie/jobs/APdtYeH-solutions-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Sales",
"role_type": null,
"salary_range": "$175K - $200K",
"equity_range": "",
"experience": "3+ years",
"visa": "Will sponsor",
"skills": [
"SQL Server",
"Oracle",
"Data Warehousing",
"Kafka"
]
},
{
"id": 99179,
"title": "Product Engineer",
"url": "https://www.ycombinator.com/companies/artie/jobs/A5udo6A-product-engineer",
"location": "San Francisco",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $250K",
"equity_range": "",
"experience": "6+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 99181,
"title": "Senior Software Engineer ",
"url": "https://www.ycombinator.com/companies/artie/jobs/7KTFRRy-senior-software-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Backend",
"salary_range": "$150K - $250K",
"equity_range": "",
"experience": "6+ years",
"visa": "Will sponsor",
"skills": []
},
{
"id": 100518,
"title": "Senior Business Development Representative - Enterprise ",
"url": "https://www.ycombinator.com/companies/artie/jobs/vv6SEu9-senior-business-development-representative-enterprise",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Sales",
"role_type": null,
"salary_range": "$115K - $150K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
}
],
"news": [
{
"title": "Artie: Real Time Data Streaming For The AI Age",
"url": "https://www.youtube.com/watch?v=M57MeOY-n3g",
"date": "Jan 26, 2026"
},
{
"title": "Artie helps companies put data to work faster with real time syncing | TechCrunch",
"url": "https://techcrunch.com/2024/02/14/artie-helps-companies-put-data-to-work-faster-with-real-time-syncing/",
"date": "Feb 14, 2024"
}
],
"launches": [
{
"id": 111491,
"title": "Artie Free Plan: real-time data replication for $0/mo",
"tagline": "Stream data to your warehouse or another database, free forever – up to 1M rows a month.",
"body": "### TL;DR\n\nArtie streams production data into your warehouse or another database in real time, so your downstream systems and workflows never run on stale data.\n\nWe launched Artie’s Free plan so startups and solo builders can get real-time database replication without a card, sales call, or CDC infrastructure project.\n\n[Check out our launch video:](https://www.youtube.com/watch?v=jXPNzOyPVH0)\n\n### The problem\n\nA solo developer wiring Supabase or Postgres into a warehouse doesn’t want to take on a CDC project. A startup’s first data hire needs fresher data for a product workflow, payments, or support, but doesn’t have a data platform team to build it. A larger company wants to test a narrow use case before pulling in procurement and security.\n\nAll three have the same initial question: will this work with our database, our destination, and our data? Answering that should take less than an afternoon, without needing to put down a credit card or join a sales call.\n\nFor Keep, a fintech startup, setting up a connector on Artie took around 10 minutes. Their team wanted Postgres and MongoDB data in Snowflake, but didn’t want to spend months building and maintaining pipelines. Their CTO’s reason for that was straightforward: he wanted the team differentiating on product, not babysitting data infrastructure. [Read Keep’s story](https://www.artie.com/customer-stories/keep-enables-real-time-data-stack-and-audit-logs?utm_source=ycombinator&utm_medium=organic&utm_campaign=free_plan).\n\n### Why now\n\nStartups are building products and operating workflows around production data with smaller teams than ever. They want that data in their warehouse (or another database) in real time, but need a way to test a real workload without building and running Kafka, Debezium, connectors, and monitoring.\n\n### What's included\n\nArtie Free includes:\n\n* Two active pipelines\n* 1 million billable rows per month\n* Backfills, not counted toward the monthly row limit\n* Sources: Postgres, MySQL, MongoDB, DynamoDB, CockroachDB, DocumentDB, Amazon Keyspaces, and PlanetScale\n* Destinations: Snowflake, BigQuery, Redshift, Databricks, MotherDuck, Postgres, S3, GCS, and ClickHouse\n\n[See the full plan details](https://www.artie.com/pricing?utm_source=ycombinator&utm_medium=organic&utm_campaign=free_plan).\n\n### Artie’s MCP Server\n\nArtie also has [an MCP server,](http://mcp.artie.com/?utm_source=ycombinator&utm_medium=organic&utm_campaign=free_plan) so you can manage pipelines from Claude or Codex instead of switching to the dashboard. You can list and create pipelines, inspect schema changes, manage backfills and connectors, and search the Artie data catalog, all from a conversation.\n\nThe MCP server is now a [ChatGPT Plugin](https://chatgpt.com/plugins/plugin_asdk_app_6a62a153d4088191a5e551ec94e025da?q=artie) and listed in [Claude's connector directory](https://claude.ai/directory/artie). You can also use another MCP-compatible client, such as Cursor, by pointing it at `https://mcp.artie.com/mcp` with an API key from your Artie dashboard. [Full setup docs here](https://www.artie.com/docs/api/mcp?utm_source=ycombinator&utm_medium=organic&utm_campaign=free_plan).\n\n### Our ask\n\nIf you are a founder, solo developer, or first data hire, [try Artie’s Free plan](https://app.artie.com/signup?utm_source=ycombinator&utm_medium=organic&utm_campaign=free_plan) with one real workload. Tell us what gets in the way: permissions, configuration, schemas, or getting the first row through.",
"url": "https://www.ycombinator.com/launches/T0F-artie-free-plan-real-time-data-replication-for-0-mo",
"votes": 33,
"created_at": "2026-08-20T16:50:12.222Z"
},
{
"id": 102815,
"title": "Artie - Real-time data replication to your data warehouse",
"tagline": "Give your AI agents fresh data they can actually act on",
"body": "**TL;DR:** Artie is a fully managed, real-time data replication tool that streams every row-level change from your production database to your warehouse in under 60 seconds. You can now sign up and start replicating today, no call required. Most teams run their first sync in under an hour.\n\n\n\n**The Problem**\n\nGetting data from your production database to your warehouse in real time has always meant picking your poison.\n\nYou build it yourself: Kafka, Debezium, custom merge logic, months of engineering, and years of maintenance as schemas evolve and the engineers who built it move on.\n\nYou use an existing CDC tool: usually something inherited, unreliable at scale, and not built for the warehouse destinations you're actually running.\n\nOr you accept stale data: dashboards refreshing every 3-24 hours, AI pipelines reasoning over yesterday's snapshot, analytics teams filing 9 am tickets asking why the numbers don't add up.\n\nMost teams are somewhere on this spectrum – either maintaining a pipeline they didn't want to build, or working around data they can't trust. That was a manageable problem when stale dashboards just annoyed your analytics team, but it becomes a bigger beast when AI agents are making pricing decisions, routing support tickets, and scoring risk off the same lagged data.\n\nA warehouse that's 12 hours behind isn't a minor inconvenience anymore – it's a liability.\n\n**The Solution**\n\nSee it work: \n\nArtie handles the entire replication layer so you don't have to. No self-built Kafka stack to maintain, no unreliable CDC tool to babysit, no stale data to apologize for. Connect your source, choose your destination, and your warehouse stays in sync with production continuously.\n\nAI agents are only as good as the data they act on. If your warehouse is hours behind, your agents are too. Artie gives your AI layer what it actually needs: a warehouse that reflects production in real time, without engineering overhead.\n\n**How It Works**\n\nArtie uses change data capture (CDC) to read directly from your database's replication logs – capturing every insert, update, and delete as it happens. Those changes stream continuously to your warehouse, landing in under 60 seconds. There's no bulk export, no scheduled job, no polling. Just a live, accurate reflection of your production data.\n\nUnder the hood, Artie handles the operational complexity: schema changes propagate automatically, delivery is exactly-once even through failures, and your destination tables stay in sync without any pipeline code on your end. The things that take most teams a year or two to get right are already solved.\n\n**Sources:** PostgreSQL, Amazon Aurora/RDS, GCP CloudSQL, Supabase, MySQL, Microsoft SQL Server, MongoDB, DocumentDB, DynamoDB, Oracle, CockroachDB, Amazon Keyspaces (Cassandra), and an Events API\n\n**Destinations:** Snowflake, BigQuery, Redshift, Databricks, ClickHouse, PostgreSQL, MySQL, Microsoft SQL Server, MotherDuck, S3, GCS, Iceberg REST Catalog, and Amazon S3 Tables\n\n**The Team**\n\nRobin (co-founder and CTO) has been building large-scale data pipelines his entire career – from processing 14 billion daily events at [Outbound.io](http://Outbound.io), to filing patents on event streaming at Zendesk, to running data infrastructure at Opendoor. He started Artie because he kept hitting the same ceiling: pipelines that worked until they didn't, and teams spending years maintaining infrastructure that should have been solved.\n\nBefore co-founding Artie, I covered enterprise software at Bank of America and Balyasny Asset Management and kept running into the same gap: companies burning engineering cycles on data pipelines that shouldn't require a team to maintain. We've been building Artie together for three years, went through YC S23, and closed a $12M Series A led by Dalton Caldwell at Standard Capital.\n\n**Our Ask**\n\nIf you're a data engineer or engineering manager tired of stale warehouse data, [try it yourself](https://go.artie.com/launch) today. See real-time replication running in your own environment – not a demo, not a sandbox, but against your actual data.\n\nIf you need private networking, dedicated infrastructure, or compliance support, [book a demo](https://go.artie.com/2822ee) and we'll walk you through what an enterprise setup looks like.\n\n[Try Artie today](https://go.artie.com/launch)",
"url": "https://www.ycombinator.com/launches/QkJ-artie-real-time-data-replication-to-your-data-warehouse",
"votes": 43,
"created_at": "2026-06-09T17:12:18.002Z"
},
{
"id": 88730,
"title": "🐘 Artie for Enterprise - Data Replication at Petabyte Scale",
"tagline": "High-volume, low-latency data replication that scales effortlessly",
"body": "# TL;DR\n\n[Artie](https://www.artie.com/?utm_campaign=launch-week-q125&utm_source=yc-launch) streams data from databases to data warehouses in real-time and more reliably than traditional ETL solutions. Many companies are still running their ETL process every few hours, so their data warehouse is constantly out of date; with Artie, the data warehouse always has live production data.\n\nArtie was founded to solve an enterprise data movement problem. Today, we’re launching Artie for Enterprise, for teams requiring high-volume, low-latency data replication that scales effortlessly. Whether dealing with massive volumes, strict security requirements, or mission-critical workloads, Artie ensures data is always live, accurate, and easy to manage. 🚀\n\n\n\n# Problem\n\nEnterprises need real-time, reliable, and secure data replication—but existing solutions make this far more painful than it should be.\n\nTraditional ETL pipelines often run on fixed schedules, updating data warehouses hours behind reality and leaving teams with outdated insights. Many replication tools try to brute-force data movement by running expensive, inefficient queries that **increase load on production databases**, slowing down applications and, in extreme cases, even **bringing them down entirely**. Scaling these systems across thousands of tables typically requires **manual, error-prone configurations**, forcing teams to spend countless hours debugging pipelines just to keep data flowing.\n\nOn top of that, many enterprises operate in highly regulated environments where data can’t be fully offloaded to the cloud. Traditional replication solutions struggle to support hybrid deployments, forcing teams to choose between security and ease-of-use.\n\n# Artie for Enterprise provides reliable, secure, and high-volume data replication\n\n### Terraform support\n\n_“Um, we have thousands of tables to configure. Do I really need to click thousands of times on your dashboard to get connectors set up?”_ We hear this question a lot and our answer is “**Absolutely not”**, which is where our Terraform provider comes in. \n\nJust because your data volume is high does not mean management needs to be equally complex. No more endless clicks—just code it, deploy it, and go.\n\n\n\n### Multi-step merge\n\nMerging large, frequently updated tables can be expensive and slow. We wanted to solve this problem without forcing customers to increase compute costs or scale up their virtual data warehouses.\n\nWith multi-step merge, Artie now loads data into a staging table in multiple bursts, allowing updates to accumulate before merging into the target table. This reduces latency and improves efficiency. Customers can now control how often data lands in the staging table before triggering a final merge—giving them real-time syncs with more flexibility and cost savings.\n\n\n\n### Hybrid deployment\n\nEnterprise-grade replication means deployment flexibility is non-negotiable. There are many organizations out there that handle data containing sensitive information and are required to operate under strict regulations.\n\nOur hybrid deployment model ensures the security of on-premise data processing with the ease of use of cloud services. What’s more? Artie’s fully-managed service allows for zero-maintenance, and removes the need to install and manage client-side agents.\n\n\n\n### MySQL Connector upgrade\n\nWe’ve made major improvements to our MySQL connector, making it enterprise-grade with improved performance, efficiency, and automation. These updates streamline database operations, reduce disk usage and I/O load, and automates data synchronization without complex configuration requirements and management overhead. \n\nKey improvements include full DDL and gh-ost migration support for seamless, non-disruptive schema changes, automatic fan-in for partitioned tables, and GTID support for reliable transaction replication.\n\n### PostgreSQL CTID scanning\n\nBackfills can be disruptive and resource-intensive. That’s why Artie is built to seamlessly recover from errors and avoid backfills unless absolutely necessary. \n\nHowever, in the event that backfills are required, how do we minimize disruption? Enter PostgreSQL CTID; an alternative backfill method that is **10-20x faster** than traditional methods.\n\n### Datadog integration\n\nAt Artie, we’ve always been big on observability. What good are your data pipelines if nobody has visibility into them? We prioritize accurately monitoring your pipeline performance and making sure you know what’s up. \n\nWith our Datadog integration, you can now track all Artie-exposed metrics directly from your Datadog dashboard. This allows you to **proactively monitor pipeline performance, set up custom alerts**, and build dashboards for deeper insights.\n\nStay on top of your data pipeline health—effortlessly.\n\n\n\n# Curious to learn more?\n\nFollow our journey on [LinkedIn](https://www.linkedin.com/company/artie-technologies), [X](https://x.com/artie_tech) and reach out to us [here](https://www.artie.com/contact?utm_campaign=launch-week-q125&utm_source=yc-launch) to see how you can benefit from enterprise-grade replication!",
"url": "https://www.ycombinator.com/launches/N58-artie-for-enterprise-data-replication-at-petabyte-scale",
"votes": 17,
"created_at": "2025-03-18T14:06:08.364Z"
},
{
"id": 76461,
"title": "Artie’s Analytics Portal - Real-time data pipeline observability",
"tagline": "Real-time observability into database pipelines and peripheral infrastructure",
"body": "# TL;DR\n\n[Artie](http://www.artie.so) is a real-time database replication solution. We leverage change data capture (CDC) and stream processing to perform data syncs in a more efficient way, which enables sub-minute latency and helps optimize compute costs. Today, we’re launching our Analytics Portal to provide visibility into our streaming pipelines and offer production-level monitoring for related system infrastructure out-of-the-box.\n\nWith the Analytics Portal, we hope to help alleviate some of the challenges that data teams face when running their data stack. By offering real-time observability into database pipelines and peripheral infrastructure, we hope companies can increase their understanding of how systems impact one another, reduce downtime/debug issues faster, and generate proactive alerts to maintain robust infrastructure. \n\n# **Visibility related to database replication is lacking**\n\nThe core of database replication is transferring data in a timely, accurate, and reliable manner. This is table stakes. In addition, there is a lot more happening in the peripheral, such as database monitoring, data pipeline visibility, data latency monitoring, and others. Data engineers need visibility to answer questions like: \n\n* How many rows have been synced in the past hour? How does that compare to the average/median/last month? \n* What is the data latency for our organization’s three most important tables? What are the factors that impact data latency and how are those metrics trending? \n* How are my systems performing?\n * Are there any database permission errors that may cause my data pipeline to go down? \n * Are my databases sized correctly? How is CPU, memory, and storage utilization? \n * Is my replication slot growing? By how much?\n\n \n\nSetting up these metrics and monitors is important to help with debugging and maintaining a robust database replication solution. However, this requires expertise and domain knowledge that may not be accessible at every company. There is also no standardization of which metrics to track and what benchmarks to follow. To make matters worse, when it comes to adopting cloud solutions, database/pipeline visibility is severely limited. When pipelines break down, customers are often left in the dark, not knowing what broke, why it broke, and how to fix it. \n\n# **Artie’s Analytics Portal unlocks visibility & reduces MTTD**\n\nWe are extremely excited to announce our Analytics Portal to increase the visibility and observability of our streaming pipelines. This will provide insights into system-level infrastructure and help with monitoring database and pipeline health. When identifying and resolving issues, one of the most important metrics is to reduce MTTD (mean time to detection). With Artie’s streaming pipelines and periodic jobs like [Postgres Watcher](https://docs.artie.so/real-time-sources/postgresql#postgresql-watcher), metrics are being sent to our Analytics Portal in flight, as the underlying data is still being processed. \n\n\n\nWith the first iteration of our Analytics Portal, we are providing industry-standard telemetry to streaming pipelines and related infrastructure. Data teams will be able to observe the following: \n\n* Data ingestion latency by table and database/deployment\n* Operation distribution by table and database/deployment\n* Rows synced by table and database/deployment\n* Database monitors that are related to and can impact pipeline performance: \n * Permission errors that may interfere with data replication\n * Replication slot size\n * Free disk space\\*\n * CPU utilization\\*\n * Memory and Disk I/O (input/output)\\*\n * Average transaction time\\*\n * Existence of long-running queries\\*\n\n\\*coming soon\n\n# Production level monitoring out-of-the-box\n\nThe Analytics Portal initially comes with a set of pre-built charts and monitors. Customers are able to drill down to get deployment, database, and table-level statistics.\n\n\n\n\n\nThe pre-built monitors that we are launching with include alerts for database permission errors and replication slot growth (for Postgres users). Over time, we will add alerting for the other monitors we mentioned above and more. This enables customers to have production-level monitoring set up out-of-the-box for their business-critical data. \n\nFor example, an e-commerce company might be watching its `online transactions` table closely during the holidays. Let’s say they observe data ingestion latency going up for `online transactions`. They zoom out and realize it’s not just the `online transactions` table that is experiencing higher latency, but all tables under their Postgres connector are impacted and very few rows have been synced in the past 5 minutes. To troubleshoot this, they look over to the database monitors and realize their database’s replication slot has been growing and the culprit is a long-running query that has locked the table and is preventing Postgres from advancing the replication slot. After a quick Slack message to their internal DevOps team, the query is killed and the issue is resolved. \n\n# Making the Analytics Portal more actionable & customizable over time\n\nOver time, we will make the data more actionable and customizable. In the near future, we plan to enable row-based monitoring such that customers can monitor custom business logic. In addition to the pre-built charts and monitors that we provide out-of-the-box, we want to allow customers to create custom charts and configure views based on metrics that matter to their business. \n\nFor example, say you are working at a Fintech company that wants to monitor live transactions to detect fraud and abuse on your platform. You have a `transactions` table and this table is being synced to your Snowflake instance. You should be able to generate a chart to plot the average, median, p95, and max transaction sizes across various lookback periods (30 minutes, 1 hour, 24 hours, 7 days, etc). Then you can set up business logic monitors such as:\n\n* Flag transactions that are 1.5 standard deviations above average coming from a merchant who signed up on the platform less than one week ago\n* Flag key accounts where transaction volume has increased above or fallen below a certain threshold in the past hour\n\n\n\nDepending on how you’d like to be notified, Artie plans to support the following escalation channels:\n\n* Email\n* Slack\n* Webhooks\n\nIn this example, the escalation channel is a webhook to your API server so you can then run a more rigorous machine-learning fraud model against a particular merchant account or transaction.\n\n# **Contact us at **[**hi@artie.so**](http://www.artie.so)** to learn more!**",
"url": "https://www.ycombinator.com/launches/JtF-artie-s-analytics-portal-real-time-data-pipeline-observability",
"votes": 24,
"created_at": "2023-11-27T17:42:21.200Z"
},
{
"id": 72536,
"title": "Artie - real-time data streaming for databases ⚡",
"tagline": "We transfer data from databases to data warehouses in real-time with CDC streaming",
"body": "# _TL;DR_\n\n_Artie is an open-source, streaming version of Fivetran - we transfer data from databases to data warehouses in real-time. Setting up a connector takes minutes and Artie leverages change data capture (CDC) to help companies reduce their data warehouse costs by 50%! We enable organizations to unlock real-time insights for better decision making. _[_Star us on GitHub_](https://github.com/artie-labs/transfer)_!_\n\n\n\nHi everyone, we are Jacqueline and Robin and we’re the team behind [Artie](https://www.artie.so/?utm_source=YC&utm_medium=newsletter&utm_campaign=launchYC&utm_id=launchYC). We’re on a mission to eliminate data latency and make it easy for every company to enable real-time data streaming!\n\nData is typically synced from production databases to the data warehouse once every X hour(s)/day(s) - this is a constraint that companies have lived with for decades. Robin personally felt the pain of not having access to production data in real-time and there were no easy to use out-of-the-box solutions, so we decided to build one! \n\n# **❌ The Problem**\n\nDoes your company sync data to the data warehouse every 6 hours, or worse, once a day? Are your analytics always lagged and filled with stale insights? **Why settle for a data platform that’s barely good enough when you can have real time data AND reduce your data warehouse costs?!** Not to mention you can have Artie set up in minutes!\n\nTraditional ETLs are based on **batched processes** that operate on a cron schedule (DAGs, Airflow) and **cannot achieve real-time data syncs**.\n\nBuilding and managing streaming data pipelines is hard. Most companies have a small team of data engineers and they often spend all day maintaining their data pipelines, which is not productive.\n\nFactors companies should consider if they want to self-manage pipelines:\n\n* Can the solution scale to multiple different data sources?\n * How easy is it to add new data sources?\n * How easy is it to manage across all the data sources?\n* Can the solution scale to handle 1m+ queries per second?\n * Is the solution horizontally scalable?\n * Do workers require coordination? Or are they stateless and distributed?\n* How do you ensure there are no out of order or missing events (even when the system crashes)?\n* Can the solution handle schema evolution without creating breaking changes downstream?\n\n# **🎉 Solution**\n\nArtie leverages change data capture (CDC) and stream processing to achieve **sub-minute data latency (\\~typically 10-20 seconds)**. Since we **only transfer changed data**, Artie is more efficient than traditional ETLs and can help you **cut down on your data warehouse cost by 50%!**\n\nSetting up a connector requires no programming. Just follow the setup guide and deploy in minutes! After the initial snapshot, any changes in your database will be reflected in your data warehouse in real-time.\n\n\n\n# **🎯 Who Needs Artie?**\n\n**Engineers** that are exhausted stitching together Airflow + AWS Glue + Apache Spark + AWS Kinesis/Kafka + Apache Flink 😵💫\n\n**Companies that are using traditional ETLs or batched processes**. Once you enable real-time, there is no going back (your data engineers/BI analysts won’t let you)! Think of all the previously unattainable use cases that you can now implement without data latency.\n\n**Companies that have a cost cutting initiative.** Adopt Artie’s CDC streaming capabilities to reduce your data warehouse costs!\n\n# **🙏 Ask**\n\nEmail [hi@artie.so](mailto:hi@artie.so) or sign up [here](https://artie.so/contact?utm_source=YC&utm_medium=newsletter&utm_campaign=launchYC&utm_id=launchYC) to try Artie today! \n\nWant to use open source? Install Artie at (give us a ⭐!) and ping us on [Slack](http://artie.so/slack?utm_source=YC&utm_medium=newsletter&utm_campaign=launchYC&utm_id=launchYC), we’re happy to help you get started.",
"url": "https://www.ycombinator.com/launches/Irw-artie-real-time-data-streaming-for-databases",
"votes": 108,
"created_at": "2023-06-26T15:13:53.399Z"
}
]
},
{
"id": 28659,
"name": "PeerDB",
"slug": "peerdb",
"former_names": [
"PeerDB Inc"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/4a83477f0ae90481f26400baea36bd4c2fed890a.png",
"website": "https://peerdb.io/",
"all_locations": "",
"long_description": "At PeerDB, we are building a fast, simple and the most cost effective way to stream data from Postgres to Data Warehouses, Queues and Storage engines. If you are running Postgres at the heart of your data-stack and move data at scale from Postgres to any of the above targets, PeerDB can provide value.\r\n\r\n\r\nWe support different modes of streaming - log based (CDC), cursor based (timestamp or integer) and XMIN based. Performance wise, we are 10x faster than existing tools. Features wise, we support native Postgres features such as comprehensive set of data-types incl. jsonb/arrays/postgis, efficiently streaming toast columns, schema changes and so on.",
"one_liner": "Fast, native ETL for Postgres 🐘 🚀",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1686776037,
"tags": [
"Developer Tools",
"Open Source",
"Data Engineering",
"Enterprise Software",
"Databases"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2023",
"status": "Acquired",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": [
{
"question": "What is the core problem you are solving? Why is this a big problem? What made you decide to work on it?",
"answer": "Existing ETL tools primarily focus on supporting a wide range of data-stores. However, they fall short in providing a rich experience for any two specific data-stores. This becomes evident when your workloads need scale or have demanding feature requirements. It is common for such users to try out these tools and fail – tools not meeting their performance and reliability SLAs or lacking the required features. Such users resort to developing their own in-house solutions, investing a lot of time and resources. This was a common pattern across various customers at our previous companies (Microsoft, Google)"
}
],
"url": "https://www.ycombinator.com/companies/peerdb",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2023/peerdb.json",
"year_founded": 2023,
"city": null,
"country": null,
"linkedin_url": "https://www.linkedin.com/company/peerdb",
"x_url": "https://twitter.com/PeerDBInc",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/4a83477f0ae90481f26400baea36bd4c2fed890a.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Diana Hu",
"url": "https://www.ycombinator.com/people/diana-hu"
},
"founders": [
{
"user_id": 728174,
"full_name": "Sai Srirampur",
"title": "Founder",
"founder_bio": "Building world’s best data-movement experience for Postgres. Ex-Microsoft - Headed Solutions Engineering all up for PostgreSQL on Azure, Ex-Citus Data (YCS11 acq. Microsoft) - Early Engineer, IIIT-H Alumnus, He/His",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/sai-krishna-s-1741b019",
"x_url": "https://twitter.com/saisrirampur",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/3b5faa67a88cc0f276aeb999922dbb9c96ce2114.jpg"
},
{
"user_id": 311868,
"full_name": "Kaushik Iska",
"title": "Founder",
"founder_bio": "Working on PeerDB to make the Postgres ETL story stellar. Previous work experience includes leading teams at Google, Palantir, Safegraph.",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/kaushikiska",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/cd7eaf287a144feb541e7737067323cf99cfe845.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Real-time database startup ClickHouse acquires PeerDB to expand its Postgres support | TechCrunch",
"url": "https://techcrunch.com/2024/07/30/real-time-database-startup-clickhouse-acquires-peerdb-to-expand-its-postgres-support/",
"date": "Jul 30, 2024"
},
{
"title": "PeerDB raises $3.6 million seed funding to revolutionize data movement for PostgreSQL",
"url": "https://blog.peerdb.io/peerdb-raises-3-6-million-seed-funding-to-revolutionize-data-movement-for-postgresql",
"date": "Apr 11, 2024"
},
{
"title": "PeerDB raises $3.6M to accelerate PostgreSQL data movement - SiliconANGLE",
"url": "https://siliconangle.com/2024/04/11/peerdb-raises-3-6m-accelerate-postgresql-data-movement/",
"date": "Apr 11, 2024"
},
{
"title": "Launch HN: PeerDB (YC S23) â Fast, Native ETL/ELT for Postgres | Hacker News",
"url": "https://news.ycombinator.com/item?id=36895220",
"date": "Jul 26, 2023"
}
],
"launches": [
{
"id": 72937,
"title": "PeerDB - Modern ETL in minutes, with SQL",
"tagline": "Data store-first ETL/ELT, enabling 10x faster syncs and transforms",
"body": "## **TL;DR**\n\nPeerDB is a Postgres-compatible SQL interface to seamlessly integrate multiple data stores. It enables data engineers to sync, transform and query data across their stores using simple SQL commands. PeerDB takes a data store native approach in engineering — enabling 10x faster ETL/ELT.\n\n## **Problem**\n\nExisting ETL/ELT tools primarily focus on supporting a wide range of connectors at the expense of delivering high-quality ones. This becomes evident when your workloads need scale or have demanding feature requirements. While Sai was working at Microsoft, it was common to see large enterprise customers try out the existing ETL tools and fail – as the tools were not meeting performance and reliability SLAs or were lacking the required features. Customers spent significant time and resources to build and manage in-house data pipelines.\n\n## **Our Solution**\n\n### Data-store nativity at its core, enabling 10x faster ETL/ELT\n\nPeerDB takes a data store-first approach to data movement. It supports highly adopted stores and implements multiple infrastructural and data store native optimizations – providing a blazing-fast and feature-rich ETL experience.\n\nWe are starting our journey by providing the world's best data integration/ETL experience for **PostgreSQL,** [one of most used and popular databases](https://db-engines.com/en/ranking_trend/system/PostgreSQL). For example, on Postgres we parallelize initial load for larger tables using CTID scans. This yields orders of magnitude speedups - Syncing 100s of GB reduces from days to minutes.\n\nOur architecture is designed for real-time syncs, which enables 10x faster Change Data Capture with data freshness of a few seconds even at large throughputs (10k+ tps). For example, in a sync from Postgres to BigQuery or Snowflake, PeerDB is 10 times faster than other tools and provides <30s data-freshness guarantees.\n\n\n\n### SQL as the ETL/ELT standard\n\nThe Postgres-compatible SQL layer for ETL makes the life of data engineers very easy. They can develop pipelines using a framework they are familiar with, without needing to deal with custom UIs and REST APIs. They can use [Postgres' 1000s of integrations](https://github.com/PeerDB-io/peerdb#postgres-compatible-sql-interface-to-do-etl) to build and manage ETL.\n\nWe extend Postgres' SQL grammar with a few new intuitive SQL commands to enable real-time data streaming across stores. As we evolve, we will make this grammar richer and the standard for ETL/ELT.\n\n## **Our Asks**\n\nIf PostgreSQL is a critical component of your data stack and you are running into challenges moving data in and out of Postgres, reach out to us at [founders@peerdb.io](mailto:founders@peerdb.io) or join our waitlist at We would love to collaborate!\n\nAlso check out PeerDB’s Open Source repo - (don’t hesitate to leave us a star!)\n\n## **Finally, a bit about us**\n\nWe are Sai and Kaushik. We've been best buddies for the past 15 years now. We were roommates back in undergrad and actively collaborated since then. Now we have decided to start a business together! 🙂\n\n\n\nPrior to PeerDB, Sai worked at Microsoft leading Solutions Eng. for all PostgreSQL services on Azure. He was an early engineer at Citus Data (YC S11) and saw it through the Microsoft acquisition. Prior to PeerDB, Kaushik built operating systems and led data teams at Google, Safegraph and Palantir. He also represented India in ACM ICPC World Finals. With our diverse and complementary experiences, we are excited and confident to build the next-generation ETL/ELT!",
"url": "https://www.ycombinator.com/launches/IyP-peerdb-modern-etl-in-minutes-with-sql",
"votes": 60,
"created_at": "2023-07-11T16:24:18.528Z"
}
]
},
{
"id": 28829,
"name": "DataShare",
"slug": "datashare",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/a781f87fe1bbe72d69bfd79f2391a43f15cb2f9b.png",
"website": "http://datashare.co/",
"all_locations": "Austin, TX, USA; Remote",
"long_description": "DataShare is a data-as-a-service platform that lets you embed charts, dashboards and exports directly into your product. For example, if you run an accounting startup, DataShare would enable you to embed a full profit and loss dashboard, with downloadable statements. DataShare is backed by an enterprise-grade data warehouse, and can be implemented in fewer than 20 lines of code. \r\n",
"one_liner": "Embed charts, dashboards and exports in your app",
"team_size": 1,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1693343113,
"tags": [
"Analytics",
"Data Engineering",
"Databases"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2023",
"status": "Active",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/datashare",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2023/datashare.json",
"year_founded": 2023,
"city": "Austin",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/withdatashare/about/",
"x_url": "https://twitter.com/WithDataShare",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/datashare-public",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/a781f87fe1bbe72d69bfd79f2391a43f15cb2f9b.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Harj Taggar",
"url": "https://www.ycombinator.com/people/harj-taggar"
},
"founders": [
{
"user_id": 8960,
"full_name": "Brian Brunner",
"title": "Founder",
"founder_bio": "Founder of DataShare, previously was the engineering manager for the team at Stripe that built Sigma and Data Pipeline.",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/bbrunner",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/3b55587837d10e3096bf4a8abd69d08dec332f01.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 74483,
"title": "DataShare: Embed customer-facing charts, dashboards and exports directly in your product",
"tagline": "Backed by an enterprise data warehouse and just 20 lines of code to integrate.",
"body": "Hey there! I’m Brian from [DataShare](https://datashare.co/).\n\nDataShare is a data-as-a-service platform that lets you embed charts, dashboards and exports directly into your product. For example, if you run an accounting startup, DataShare would enable you to embed a full profit and loss dashboard, with downloadable statements. It’s backed by an enterprise-grade data warehouse and can be implemented in fewer than 20 lines of code.\n\n[Book some time](https://calendly.com/bb-datashare/datashare-intro-call) if you want to learn more. We can walk through all DataShare has to offer and give you an idea of what an integration would look like for your tech stack.\n[](https://www.youtube.com/watch?v=LNZGCl7lQMU)\n# Background\n\nOver the past few years, SaaS and financial services companies have been pushed by their customers to provide better business intelligence tooling. These systems are complex to design, hard to build, expensive to run, and challenging to scale. I've seen numerous examples of companies doing things like operating a database per customer or running 10+ hour-long pre-computation jobs just to deliver customer-facing data products.\n\nHowever, during my time at Stripe, I saw a different model. I ran the engineering team that built [Data Pipeline](https://stripe.com/data-pipeline) and [Sigma](https://stripe.com/sigma), and due to Stripe's infrastructure, we were able to rapidly deliver new products that helped to retain some of Stripe’s largest customers.\n\nDataShare is packaging up what I learned, and delivering that knowledge to the rest of the market.\n\n# The Product\n\nDataShare is a platform that combines a scalable, enterprise-grade data warehouse with a front-end framework for integrating business intelligence tools directly into your product.\n\nCharts and dashboards can be built with a point-and-click UI and can be integrated with just two lines of code.\n\n\n\nYou can also skip the UI if you want. Visualizations can be built using DataShare’s AI-powered assistant.\n\n\n\nDataShare supports more than 20 types of data sources, including PostgreSQL, MySQL, and MongoDB, and is backed by a full data warehouse.\n\n# About DataShare\n\n[Brian](https://www.linkedin.com/company/withdatashare/) - I spent the past 4 years at Stripe and the past year and a half as the eng manager for [Data Pipeline](https://stripe.com/data-pipeline) and [Sigma](https://stripe.com/sigma). My team and I supported some of Stripe’s largest customers like DoorDash, Slack, Zoom, and Lime, helping keep them happy and run crucial financial workflows.\n\n# Ask\n\nIf you are thinking about building our customer-facing business intelligence tools, or you have a customer-facing BI stack you don’t like, reach out at [hello@datashare.co](mailto:hello@datashare.co) or grab [time to chat](https://calendly.com/bb-datashare/datashare-intro-call).\n\nThanks!\n\nBrian from DataShare",
"url": "https://www.ycombinator.com/launches/JNL-datashare-embed-customer-facing-charts-dashboards-and-exports-directly-in-your-product",
"votes": 35,
"created_at": "2023-08-29T20:31:46.784Z"
}
]
},
{
"id": 28868,
"name": "Briefer",
"slug": "briefer",
"former_names": [
"Ergomake"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/1e589854f66150c916444527d7f4aa314d3961ed.png",
"website": "https://briefer.cloud",
"all_locations": "São Paulo, SP, Brazil; Remote",
"long_description": "Briefer helps data scientists and analysts build interactive visualizations and data apps using a Notion-like interface.\r\n\r\nConnect to your data sources, write SQL or Python, collaborate through comments and multiplayer editing, and run code in whichever compute environments you need.",
"one_liner": "The collaborative data platform.",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1687307247,
"tags": [
"Developer Tools",
"B2B",
"Data Science",
"Data Engineering",
"Data Visualization"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2023",
"status": "Inactive",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"Brazil",
"Latin America",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/briefer",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2023/briefer.json",
"year_founded": 2022,
"city": "São Paulo",
"country": "BR",
"linkedin_url": "https://www.linkedin.com/company/briefercloud/",
"x_url": "https://twitter.com/briefercloud",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/briefercloud",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/1e589854f66150c916444527d7f4aa314d3961ed.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Aaron Epstein",
"url": "https://www.ycombinator.com/people/aaron-epstein"
},
"founders": [
{
"user_id": 578593,
"full_name": "Lucas da Costa",
"title": "Founder",
"founder_bio": "I'm the founder and CEO at Briefer. Previously, I worked as a senior software engineer at Elastic and led software engineering teams at an early-stage startup in London.\n\nI used to maintain large OSS projects like Chai.js and Sinon.js and contributed to many others, including Jest.\n\nAs an author, I wrote \"Testing JavaScript Applications,\" published by Manning. I've also spoken in more than ten countries, and my content has been voluntarily translated into more than seven languages.",
"is_active": false,
"linkedin_url": "https://linkedin.com/in/lucasfdacosta",
"x_url": "https://twitter.com/thewizardlucas",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/3c67c3654b38517081d8943217dd52f520daa16d.jpg"
},
{
"user_id": 1372900,
"full_name": "Lucas Vieira",
"title": "Founder",
"founder_bio": "Lucas, is a software engineer and open-source enthusiast with a decade of experience, actively contributes to numerous open source projects. He used to maintain Chai.js, a popular JavaScript testing framework with 7.8k+ GitHub stars. As the former Head of Technology at Joga, he built a product from scratch, used by thousands in dozens of countries. Now, Lucas is the CTO of Ergomake, developing a product for developers to deploy preview environments for any stack.",
"is_active": false,
"linkedin_url": "https://linkedin.com/in/lucas-vieira-1ba001a4",
"x_url": "https://twitter.com/commadangle",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/4b304961c58125ab235255d85217abb378470ab1.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 88718,
"title": "❇️ Briefer Agent: your AI data analyst, built into a powerful data workspace",
"tagline": "Briefer's agent helps anyone on your team turn data into clear and instant insights.",
"body": "Hey YC! I'm Lucas, founder of Briefer: a data workspace for notebooks and dashboards.\n\n**✨ Today, we're launching the Briefer Agent: an AI analyst that helps anyone on your team turn data into clear and instant insights ✨**\n\n\n\nFor the past year, we've been building a powerful data workspace to help thousands of technical users uncover deep insights they wouldn't otherwise have. Many of these people use Briefer every day and get a lot of value out of it thanks to features like Python support, point-and-click visualizations, scheduling, and turning query results into data frames automatically.\n\n**Now, we're bringing Briefer's magic to _everyone_.** Whenever _anyone_ on your team has a question, they can ask our AI analyst, and it'll use Briefer to get them an answer.\n\n\n\n---\n\n# **⭐ It's not just another text-to-SQL chatbot**\n\n**Our AI analyst is _not_ just another “text-to-SQL” chatbot that spits out random graphs.** Instead, it's an intelligent agent that operates Briefer's powerful data workspace to generate answers that are precise and reviewable.\n\nOur agent can do anything a human analyst does in Briefer: write SQL, plot graphs, and even run Python for data manipulation and advanced analyses.\n\n\n\n---\n\n# **🤝 Especial things the Briefer Agent can do**\n\n* **🏦 Handle business-specific context.** If you have business-specific context you'd like to explain to the agent, you can easily add it to help the agent better understand your data and goals.\n* ☁️ **Connect to all the most popular data sources.** Briefer connects to all the most popular data sources, including Postgres, BigQuery, Redshift, Athena, Snowflake, MySQL, and others. The agent can use those data sources too.\n* **📄 Analyze CSV, XLS, and Parquet files.** If you have a CSV or Excel file, you can also upload it and ask for the Briefer agent to analyze it for you. That'll be easy because the agent knows how to use Briefer's DuckDB integration to query that file too.\n* 🎈**Run on your own infrastructure.** You can fully self-host Briefer's enterprise version and use your own Bedrock or Vertex services to power the agent. Therefore, all your data remains on your cloud, _always_.\n\n\n\n---\n\n# **➡️ How can I try the agent?**\n\nTo try out Briefer's agent, [book a call using this link](https://calendly.com/lucasfcosta/briefer-intro) and we'll help you get started ASAP.\n\nIf you have questions, feel free to email us, the founders, directly at [founders@briefer.cloud](mailto:founders@briefer.cloud).",
"url": "https://www.ycombinator.com/launches/N4w-briefer-agent-your-ai-data-analyst-built-into-a-powerful-data-workspace",
"votes": 27,
"created_at": "2025-03-17T19:16:57.634Z"
},
{
"id": 83864,
"title": "❇️ Briefer: Python notebooks and dashboards in one place (now open-source)",
"tagline": "Create Python notebooks that look like Notion, and publish them as reports or dashboards.",
"body": "⭐ Today, we're launching [Briefer's open-source offering](https://github.com/briefercloud/briefer).\n\n**Briefer is like Notion for code notebooks and dashboards. It gives technical users all the flexibility they need to publish dashboards, analyze data, create reports, and build data apps. At the same time, Briefer makes it easy for non-technical users to view and interact with data.**\n\n\n\nIn Briefer, you can:\n\n* 📚📊 **Create notebooks and dashboards** using Markdown, Python, SQL, and native visualizations.\n* 🤳 **Build interactive data apps** using inputs, dropdowns, and date pickers.\n* 🤖 **Generate code and queries** using an AI that understands your database schema and your notebook's context.\n* 🕰️ **Schedule notebooks and dashboards** to run and update periodically.\n* ⚙️ **Create and test ad-hoc pipelines** using writebacks.\n\nIn addition to all that, Briefer is also multiplayer, meaning two or more people can work on the same notebook or dashboard simultaneously and see each other's changes in real time.\n\nFrom today, you can use Briefer for free on your machine or deploy it to your own infrastructure so that your whole team can use it and eliminate your data silos.\n\n \n\n### **🍱 What's included in the open-source offering?**\n\n\n\nBriefer's open-source offering includes everything you need to build notebooks and dashboards, including Markdown, SQL, Python, point-and-click visualizations, scheduled runs, writebacks, and more.\n\nAlso, given you'll be running Briefer on your own machines, there's no limit on how many users you can invite, how much memory and compute you can give to your notebooks, and how many pages you can schedule.\n\nThe only things that are _not_ in Briefer's open-source offering are PDF exports, granular permissions, and email and Slack integrations. These are available in the paid version of Briefer, for which you can sign up [here](https://briefer.cloud).\n\n \n\n### **🤔 Why open-source?**\n\nWe want people to have zero barriers to using Briefer, and we believe that making it open-source is the best way to achieve that.\n\nBy making Briefer open-source, we're giving you the freedom to run it on your own infrastructure, customize it to your needs, and contribute to its development.\n\nFurthermore, given Briefer will be running on your own machines, you don't have to worry about your data being stored in a third-party service. You have full control over your data.\n\nIf you want an in-depth explanation of our open-source strategy, [you can read it here](https://briefer.cloud/blog/posts/open-source-strategy).\n\n \n\n### **✨ How do I get started?**\n\n**➡️ You can get started by following the instructions in our **[**GitHub repository**](https://github.com/briefercloud/briefer)**. While you're there, please don't forget to give us a star ⭐.**\n\nIf you have any questions, please send me an email at [lucas.costa@briefer.cloud](mailto:lucas.costa@briefer.cloud). I respond to every email I receive from users.\n\nIn case you need help deploying Briefer or just want to talk directly to me, please [book a time here](https://calendly.com/lucasfcosta/briefer-intro-call).",
"url": "https://www.ycombinator.com/launches/Loe-briefer-python-notebooks-and-dashboards-in-one-place-now-open-source",
"votes": 28,
"created_at": "2024-09-09T17:05:36.669Z"
},
{
"id": 80177,
"title": "❇️ Briefer: Jupyter Notebooks and data apps in the cloud - and it looks like Notion!",
"tagline": "Create and share beautiful analyses, visualizations, and data apps",
"body": "\\*\\*TL;DR: If you're using Jupyter Notebooks or have ad-hoc scripts and data apps, you should consider switching to [**Briefer**](https://briefer.cloud) ❇️. Briefer works like Jupyter Notebooks, but it runs in the cloud and is as pretty and intuitive as Notion. It allows you to create beautiful and in-depth analyses, visualizations, and data apps.\\*\\*\\\n—\n\nHi, we're Lucas da Costa and Lucas Vieira (the Lucas²), founders of Briefer.\n\nWe've built Briefer to help data scientists create analyses, visualizations, and data apps and share their work with others — including non-technical people!\n\n\n\n[**🎬 Here's a demo 📹**](https://www.loom.com/share/f5658419cd154958862de41f1ea328c8?sid=685856a5-d188-4c53-baf3-51084ef3d141)\n\nYou can use Briefer instead of writing messy notebooks, building unmanageable ad-hoc scripts, wrangling with SQL in limited BI tools, or going through the hassle of setting up the infrastructure for a data app.\n\n# \n\n# **⭐ Briefer is better than Jupyter or ad-hoc solutions because:**\n\n* 💅 It looks way better and is 1000x easier to use — non-technical stakeholders will love it too.\n* 🤗 It's easy to share — just copy a link, no need to install dependencies or pull a git repo.\n* 💾 You can run SQL and Python in the same place — All SQL queries can be used as Pandas data-frames straightaway. No need to write custom wrapper libraries.\n* 🖥️ It's interactive — you can use text fields or dropdowns for viewers to provide input to your pages.\n* ⚡No Memory or GPUs? No problem — we can get you more powerful machines if you need them.\n* 👯 Real-time collaboration — you can see what others are doing if you're editing the same document, just like Google Drive.\n\n# **⭐ Get started now ✨**\n\n[**➡️ Click here to book an intro call if you want to get started with Briefer ⭐**](https://calendly.com/lucasfcosta/briefer-intro-call)\n\nWe move fast and we prioritize making customers happy over everything else - and we can help you build your first analyses and data apps. So, as a small team, there's a limited number of people we can onboard at a time - **make sure to book a call as soon as possible to ensure we'll get you a spot.**\n\nIf you have any other questions or comments, please email us at [founders@briefer.cloud](mailto:founders@briefer.cloud).",
"url": "https://www.ycombinator.com/launches/KrB-briefer-jupyter-notebooks-and-data-apps-in-the-cloud-and-it-looks-like-notion",
"votes": 73,
"created_at": "2024-04-15T17:39:24.496Z"
},
{
"id": 73177,
"title": "🧚 Ergomake - Deploy a staging environment for every pull request",
"tagline": "Whenever engineers push changes, we deploy their entire application and send them a link.",
"body": "**TL;DR Ergomake creates a staging environment for each pull request. Every time an engineer pushes changes, we deploy their entire application and send them a link to see it. Our customers use Ergomake for QA, product, and design reviews before any code gets merged.**\n\nHey everyone! We're Lucas and Lucas (yes, Lucas²), the founders of [Ergomake](https://ergomake.dev).\n\n\n\n**Ergomake creates a new staging environment every time engineers push changes**, making reviews much quicker and easier and helping teams avoid shipping broken changes.\n\n## ❌ The problem: staging is a bottleneck.\n\nEngineers must ship code to a staging environment whenever they need feedback from QAs, designers, and product managers.\n\nThe problem with this approach is that **teams usually have only one staging environment**. Therefore, **engineers scramble to see who will use staging or end up merging changes before anyone else sees them**.\n\n\n\n**Consequently, teams slow down, applications break, or undesirable code gets shipped**.\n\nWhen that happens, engineers rush to fix the broken code already merged. For that, they must go through the whole review process again, which is a massive waste of time and money.\n\n## 💡 The solution: everyone gets their own staging.\n\nWith Ergomake, every change gets deployed to a new staging environment.\n\n\n\nThat way, engineers can get input from the rest of their team without queueing to use staging.\n\nAdditionally, by getting reviews _before_ deploying code, teams avoid merging all sorts of undesirable changes. Consequently, they avoid bugs and reduce rework by keeping `main` always working.\n\nWith Ergomake, teams can merge straight into `main` because they do all their manual testing and validations within their pull requests. Therefore, these teams avoid complicated branching strategies and painful integration cycles.\n\n\n\n## ⚙️ How does it work?\n\nErgomake integrates with GitHub and gets notified whenever someone opens a pull request.\n\nWhen that happens, Ergomake uses the `docker-compose.yaml` file within the repository to deploy your application on our infrastructure.\n\nOnce Ergomake has spun everything up, it adds a comment to the pull request containing the link to test your application.\n\nOur previews can include databases, and they support all types of projects, including those spread across multiple repos.\n\n## ➡️ The ask: sign-up now (there's a free tier)\n\n**You can sign-up for Ergomake at **[**app.ergomake.dev**](https://app.ergomake.dev)**.** There, you'll be able to configure previews for any repositories you want for free.\n\n**If you prefer, we're happy to do all the integration for you or hop on a call and guide you through the process**. If you think that could be helpful, [book an intro call here](https://calendly.com/lucasfcosta/ergomake-15-minutes).\n\nFor anything else, [we're also on Discord](https://discord.gg/daGzchUGDt).",
"url": "https://www.ycombinator.com/launches/J2H-ergomake-deploy-a-staging-environment-for-every-pull-request",
"votes": 85,
"created_at": "2023-07-18T15:59:24.172Z"
}
]
},
{
"id": 29071,
"name": "Cedalio",
"slug": "cedalio",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/253ca8c2833042159f28652e47d94970cc10b5cc.png",
"website": "https://cedalio.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Cedalio is the AI agent platform for the Office of the CFO. We automate procurement, AP, and the data flows behind them — from invoice intake to 3-way match to payment — so finance teams stop doing the work and start governing it.",
"one_liner": "AI agents that automate AP, procurement, and finance",
"team_size": 6,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1685752888,
"tags": [
"Fintech",
"Finance",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2023",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/cedalio",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2023/cedalio.json",
"year_founded": 2022,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/cedalio/",
"x_url": "https://twitter.com/CedalioTech",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/cedalio/",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/253ca8c2833042159f28652e47d94970cc10b5cc.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Garry Tan",
"url": "https://www.ycombinator.com/people/garry-tan"
},
"founders": [
{
"user_id": 1337055,
"full_name": "Luciana Reznik",
"title": "Founder",
"founder_bio": "Luciana is CEO at Cedalio, the AI agent platform for the Office of the CFO. Cedalio automates procurement, accounts payable, and the data flows behind them. Software engineer originally from Argentina, living in the Bay Area since 2018. Previously co-founded Wolox, an end-to-end digital solutions company that was acquired by Accenture in Jan 2021.",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/lucianareznik",
"x_url": "https://twitter.com/LucianaReznik",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b87defc43b3b56797ee4aec96ae067a37e1bbd7a.jpg"
},
{
"user_id": 1355920,
"full_name": "Nico Magni",
"title": "Founder",
"founder_bio": "Hello! I'm Nico Magni, the Chief Product Officer (CPO) at Cedalio, a database that tracks every application data change, and maintains an immutable and verifiable history. As a software engineer, I am passionate about building innovative solutions that tackle real-world challenges. \n\nI had the opportunity to sell my previous company to Accenture, where I gained invaluable experience in successfully scaling and delivering high-quality products.\n\nCurrently based in Patagonia, Argentina.",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/nicomagni",
"x_url": "https://twitter.com/nicomagni",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b50b0e99062e30e6076be3a4f9199d4d49e1f1c6.jpg"
},
{
"user_id": 1355935,
"full_name": "Guido Marucci Blas",
"title": "Founder",
"founder_bio": "CTO & co-founder at Cedalio. Previously CTO & co-founder at Wolox (acquired by Accenture). Argentinean. Passionate about building amazing developer experiences, lowering the barrier to entry to web3 and working in the intersection of developer tools and data privacy. When I'm not working I love going outdoors ⛰️, playing the guitar 🤘 and hanging out with friends! ",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/guidomb",
"x_url": "https://twitter.com/guidomb",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/e690e1ce5a76e9f177c6960b95b28ba7dc9ee2c0.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 75973,
"title": "Cedalio: where sustainability meets data",
"tagline": "Unify, automate, verify — your trusted data platform for ESG",
"body": "Dear YC Community,\n\nWe're elated to present our latest offering. Cedalio's core technology has always been centered around a blockchain-enabled database ensuring data **transparency, verification, and integrity**. With our latest launch, we've taken this a step further.\n\n\n\n\\\nKey Features:\n\n* **AI data extraction:** Leverage our AI-powered data extraction capabilities to seamlessly collect information from various sources – from utility bills to supplier forms. Our automated consolidation feature integrates with your existing systems, centralizing all data into a single source of truth. Say goodbye to manual data wrangling and hello to real-time, centralized information.\n* **Radical Transparency:** Trust is the foundation of sustainability. Our platform leverages blockchain technology to create an immutable, auditable trail of your data transactions. Enhance transparency and build credibility with stakeholders, knowing your information is accurate, secure, and tamper-proof.\n* **AI-Assisted Reporting:** Unlock the power of your data with our AI-assisted reporting tools. Generate comprehensive, auditable reports tailored to your specific needs, or export data in your preferred format for in-depth analysis.\n\n\n\nThe development of our product was largely influenced by the feedback and insights we received from our partners in the traceability sector. Their challenges in ensuring transparent ESG reporting and undeniable proof of product origins drove us to create a solution that addresses these pain points head-on.\n\nWe invite you to delve deeper into Cedalio, explore its features, and contact us if you see any way of collaborating.\n\nWarm regards,\n\nThe Cedalio Team",
"url": "https://www.ycombinator.com/launches/JlN-cedalio-where-sustainability-meets-data",
"votes": 11,
"created_at": "2023-11-06T16:05:26.769Z"
},
{
"id": 72841,
"title": "💥 Cedalio — A blockchain empowered alternative to Firebase",
"tagline": "Build apps with data that is auditable and verifiable by default",
"body": "[Cedalio](https://www.cedalio.com) is a platform that helps you build apps with information that is auditable by default. Data used in your application can be traced back to its origin for verification. Even more, with us you can give your users real ownership and portability of their data across different applications.\n\n## 📚 **TL;DR**\n\n* Cedalio provides companies with the tools to build trust and accountability by offering transparent, auditable data.\n* With Cedalio, organizations prioritizing user privacy can empower users with true ownership of their data, promoting its portability across various applications.\n* By storing access control information on-chain, Cedalio ensures a censorship-resistant database, safeguarding information integrity.\n\n\n\n**_Interested? →_** Get started now at [**www.cedalio.com**](http://www.cedalio.com)\\\n**Do you have a new use case in mind? →** Let us know on our [**Discord**](https://discord.gg/kSdhmb9UUT)\\\n**_Do you want how it works under the hood? →_** Read our [**DocSite**](https://docs.cedalio.com/introduction/about-cedalio)\n\n## 👩💻 **How do we do it:**\n\n* **Verifiable data:** field-level certifications offers a means to validate the data's integrity, creating trust and assurance in the accuracy of the information.\n* **On chain access controls**: the access control rules are stored in a smart contract, ensuring a censorship-resistant database.\n* **On chain log:** by recording a detailed log of transactions on the blockchain, we enable auditability and the ability to reconstruct the database if needed.\n\n \n\n\n## 🤑 **Backed by the best**\n\nSome of our early investors and believers include:\n\n* Y Combinator\n* Guillermo Rauch, CEO @Vercel\n* Esteban Ordano, CEO @Decentraland\n* Demian Brener, CEO @OpenZepellin\n\nFeel free to reach out to us with any questions or to learn more about Cedalio.\n\n_Join our _[_Discord_](https://discord.gg/kSdhmb9UUT)_ or shoot us an email_",
"url": "https://www.ycombinator.com/launches/Iwr-cedalio-a-blockchain-empowered-alternative-to-firebase",
"votes": 85,
"created_at": "2023-07-07T00:02:03.539Z"
}
]
},
{
"id": 29254,
"name": "Reducto",
"slug": "reducto",
"former_names": [
"Remembrall"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/9794d4fb523375d125992ce9fa5e9e9db45daf9a.png",
"website": "https://reducto.ai",
"all_locations": "San Francisco, CA, USA",
"long_description": "Reducto is the agentic document platform for leading AI teams building systems to automate document workflows at enterprise scale.\r\n\r\nOur platform provides a comprehensive toolkit for working with documents the way a human would, combining custom in-house and leading frontier models to power efficient and accurate document workflows. Reducto is trusted by leading AI teams at companies like Harvey, Scale AI, and Vanta.\r\n\r\nWe are built for enterprise workloads with flexible deployment options from the cloud to fully air-gapped environments, SOC II and HIPAA compliance, and zero data retention.\r\n\r\nLearn more: https://reducto.ai/\r\nFind our YC deal: https://reducto.ai/yc",
"one_liner": "The complete agentic document platform",
"team_size": 30,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1704664395,
"tags": [
"Documents",
"Data Engineering",
"Enterprise Software",
"Search",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2024",
"status": "Active",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Growth",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/reducto",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2024/reducto.json",
"year_founded": 2023,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/reducto-ai/",
"x_url": "https://x.com/reductoai",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/reductoai",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/9794d4fb523375d125992ce9fa5e9e9db45daf9a.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Diana Hu",
"url": "https://www.ycombinator.com/people/diana-hu"
},
"founders": [
{
"user_id": 1577822,
"full_name": "Raunak Chowdhuri",
"title": "Founder/CEO",
"founder_bio": "Co-founder/CTO at Reducto. Before Reducto I studied CS at MIT, founded/scaled a comp. chem consulting company to 200k ARR, published computer vision papers with 100+ citations before finishing high school, and spent a little too much time shit posting on Twitter.",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/sauhaarda",
"x_url": "https://twitter.com/raunakdoesdev",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/942feecb35daadd157058cc33cb2803b8a8950dd.jpg"
},
{
"user_id": 850889,
"full_name": "Adit Abraham",
"title": "Founder/COO",
"founder_bio": "Co-founder/CEO at Reducto. Before Reducto I studied CS at MIT, made Ads/Search things as a PM for Google, did ML research at MIT's Media Lab, and spent an unreasonable amount of time playing Pokemon Showdown.",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/aditabraham",
"x_url": "https://twitter.com/AbrahamAdit",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/53a289d9d77cc6b4edf978ab557af36e1442ed30.jpg"
}
],
"jobs": [
{
"id": 69144,
"title": "Software Engineer",
"url": "https://www.ycombinator.com/companies/reducto/jobs/2BVFiJu-software-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$140K - $240K",
"equity_range": "0.10% - 1.00%",
"experience": "3+ years",
"visa": "Will sponsor",
"skills": [
"Python",
"TypeScript",
"Torch/PyTorch",
"Computer Vision"
]
},
{
"id": 70899,
"title": "Machine Learning Engineer",
"url": "https://www.ycombinator.com/companies/reducto/jobs/3VS78nJ-machine-learning-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Machine learning",
"salary_range": "$150K - $240K",
"equity_range": "0.10% - 1.00%",
"experience": "3+ years",
"visa": "Will sponsor",
"skills": [
"Python",
"Torch/PyTorch",
"Computer Vision",
"Data Analytics"
]
},
{
"id": 71707,
"title": "LLM/ML Engineer (Inference)",
"url": "https://www.ycombinator.com/companies/reducto/jobs/roVp40O-llm-ml-engineer-inference",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Machine learning",
"salary_range": "$200K - $300K",
"equity_range": "0.10% - 1.00%",
"experience": "3+ years",
"visa": "Will sponsor",
"skills": []
}
],
"news": [
{
"title": "Reducto: AI document parsing & extraction software",
"url": "https://reducto.ai/blog/reducto-series-b-funding",
"date": "Oct 14, 2025"
},
{
"title": "Reducto: Making Human Data LLM-Ready With State-of-the-Art Accuracy",
"url": "https://www.youtube.com/watch?v=QBC_cViA7j8",
"date": "May 01, 2025"
},
{
"title": "Exclusive: Reducto, AI document parsing startup, raises $24.5 million Series A led by Benchmark | Fortune",
"url": "https://fortune.com/2025/04/25/exclusive-reducto-ai-document-parsing-startup-raises-24-5-million-series-a-led-by-benchmark/",
"date": "Apr 25, 2025"
},
{
"title": "Reducto Document Ingestion API",
"url": "https://reducto.ai/blog/reducto-series-a-funding",
"date": "Apr 25, 2025"
},
{
"title": "Reducto Document Ingestion API",
"url": "https://reducto.ai/blog/seed-round",
"date": "Oct 02, 2024"
}
],
"launches": [
{
"id": 82871,
"title": "Reducto - Structured data from any unstructured document",
"tagline": "Reducto’s new API makes it easy to turn complex documents and spreadsheets into structured data that fits your schema, with zero fine tuning. ",
"body": "\n\n[Reducto](https://reducto.ai) is a team from MIT building vision models to turn complex documents into LLM-ready inputs. Every part of our core API was made to offer the most accurate extraction possible, and we now power document ingestion for leading AI teams ranging from startups to Fortune 10 enterprises. \\\n\\\nWe’re excited to release a new **Structured Extraction API**, which leverages LLMs along with our vision models to extract the data that you need with exceptional accuracy and flexibility. \n\n# **📃 The Problem**\n\n**Nearly 80% of enterprise data is in unstructured formats like PDFs and spreadsheets**\\\nPDFs are the status quo for enterprise knowledge in nearly every industry. They’re stored in a structure that’s simply impractical for use in digital workflows, which leads to [dozens of wasted hours every week](https://www.reducto.ai/blog/the-real-cost-of-manual-document-processing).\\\n\\\n**Custom extraction models require hundreds of hours to build and maintain**\n\nCompanies often use traditional solutions to build a custom extraction pipeline for _every_ document layout they’re working with. That requires dozens of hours for labeling and training the model, and constant maintenance when models break from changing layouts.\\\n\\\n**LLMs offer better flexibility at the cost of reliability**\n\nOff the shelf LLMs _can_ offer exceptional reasoning but they struggle with hallucinations and extraction inaccuracies, making them unreliable for production use cases. \n\n# \n\n# **✅ Our Solution**\n\nWe’ve built vision models to read documents the way a human would, and a language model that we trained for schema-based extraction. Our new model can handle significantly larger documents, and is trained to _cite_ the source for each piece of information, allowing you to audit and verify outputs easily.\n\n\n\nThis means you can:\n\n* Extract important fields with simple, natural language instructions\n* Verify any information using our source citations\n* Build powerful automations by integrating Reducto’s API with your custom workflow\n\n# **🚀 Automate your unstructured data processing**\n\nOur API is live in production with leading teams across insurance, healthcare, and finance, and we would love to work with you to improve your unstructured data ingestion.\\\n\\\nThis new API leverages all of the work that we’ve put into improving our document understanding models to make structured extraction work across all layouts with best in class accuracy. \\\n\\\nYou can [sign up](https://reducto.ai/pricing) to get started right away, or reach out to us at [founders@reducto.ai](mailto:founders@reducto.ai) for a demo!",
"url": "https://www.ycombinator.com/launches/LYd-reducto-structured-data-from-any-unstructured-document",
"votes": 28,
"created_at": "2024-08-09T14:58:47.814Z"
},
{
"id": 78035,
"title": "🔮 Reducto - Unlocking data behind complex documents",
"tagline": "Our API allows you to convert complex, unstructured documents into structured outputs that are perfect for RAG, process automation, and more.",
"body": "Hey everyone - [Raunak](https://www.raunakdoes.dev/) and [Adit](https://www.linkedin.com/in/aditabraham/) here 👋🏼\\\n\\\nWe met four years ago while studying computer science at MIT, and we’ve spent the past few years building ML products at companies like Google and NVIDIA. We started building [Reducto](https://reducto.ai) after struggling with document ingestion while consulting for teams integrating LLMs into their applications.\n\n# \n\n# **📃 The Problem**\n\n**Nearly 80% of enterprise data is in unstructured formats like PDFs**\n\nPDFs are the status quo for enterprise knowledge in nearly every industry. Insurance claims, financial statements, invoices, and health records are all stored in a structure that’s simply impractical for use in digital workflows. This isn’t an inconvenience—it’s a critical bottleneck that leads to [dozens of wasted hours every week](https://www.reducto.ai/blog/the-real-cost-of-manual-document-processing).\n\n**Traditional approaches fail at reliably extracting information in complex PDFs**\n\nOCR and even more sophisticated ML approaches work for simple text documents but are unreliable for anything more complex. Text from different columns are jumbled together, figures are ignored, and tables are a nightmare to get right. Overcoming this usually requires a large engineering effort dedicated to building specialized pipelines for every document type you work with. \n\n# **🚀 Our Solution**\n\nReducto breaks document layouts into subsections and then contextually parses each depending on the type of content.\n\n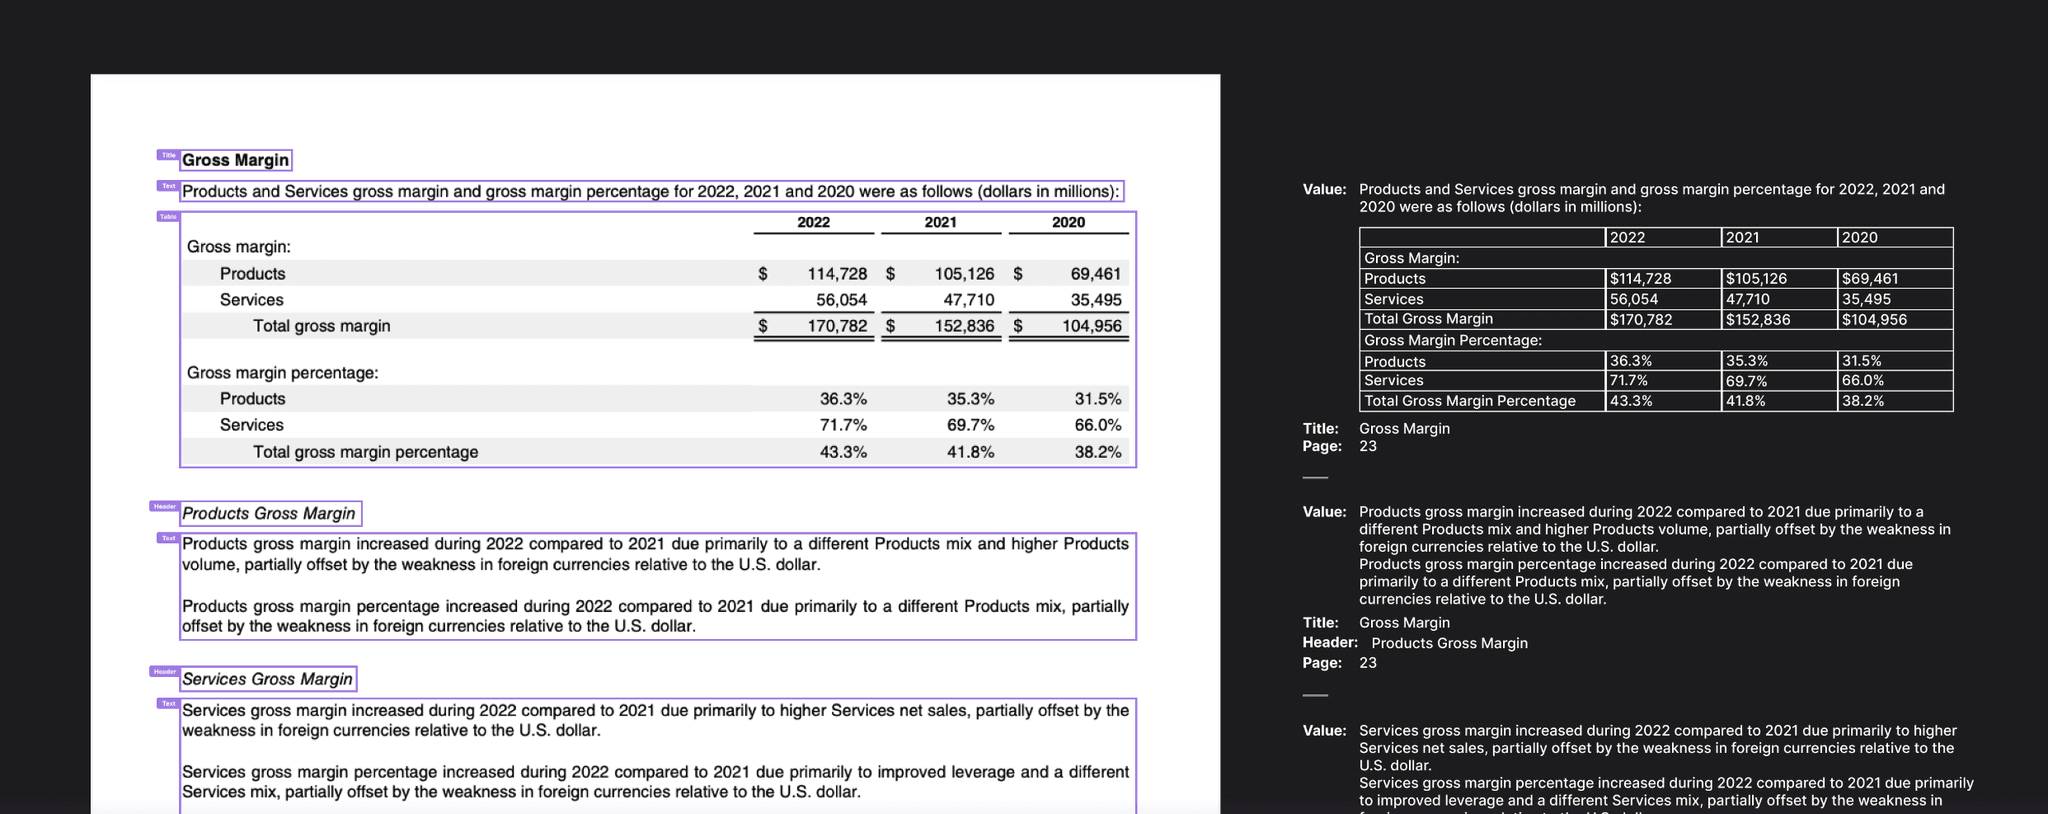\n\nThis is made possible by a combination of vision models, LLMs, and a suite of heuristics we built over time. Put simply, we can help you:\n\n* Accurately extract text and tables even with nonstandard layouts\n* Automatically convert graphs to tabular data and summarize images in documents\n* Extract important fields from complex forms with simple, natural language instructions\n* Build powerful retrieval pipelines using Reducto’s document metadata\n* Intelligently chunk information using the document’s layout data\n\nYou can try a demo [here](https://app.reducto.ai/share/5ecd4726-f482-498d-a1c2-b76e12f595a8). \n\n# **🙏🏼 Our Ask**\n\nWe’re looking to onboard more teams across insurance, healthcare, and finance and would really appreciate your help. If you or someone you know is struggling with high-volume document workflows (5000+ pages), please reach out to us at [founders@reducto.ai](mailto:founders@reducto.ai).",
"url": "https://www.ycombinator.com/launches/KId-reducto-unlocking-data-behind-complex-documents",
"votes": 41,
"created_at": "2024-01-31T20:01:45.526Z"
}
]
},
{
"id": 29260,
"name": "Quary",
"slug": "quary",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/e54d14cc55231dd1bd8f1cfd85b8f8366f88fae7.png",
"website": "https://www.quary.dev",
"all_locations": "London, England, United Kingdom",
"long_description": "Quary is the first analytics engineering platform that brings the entire model-test-deploy workflow into the browser. \r\n\r\nAt our first customer, a fast-growing fintech company, Quary empowers analysts in the growth team to self-serve, contribute, and reduce reliance on the data engineering team, letting teams ship metrics faster & executives get answers sooner",
"one_liner": "The first in-browser analytics engineering platform",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1707148568,
"tags": [
"Analytics",
"Data Science",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2024",
"status": "Inactive",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United Kingdom",
"Europe",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/quary",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2024/quary.json",
"year_founded": 2023,
"city": "London",
"country": "GB",
"linkedin_url": "https://www.linkedin.com/company/quarylabs",
"x_url": "https://twitter.com/quarylabs",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/quary",
"github_url": "https://github.com/quarylabs/",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/e54d14cc55231dd1bd8f1cfd85b8f8366f88fae7.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 1400304,
"full_name": "Benjamin King",
"title": "Founder",
"founder_bio": "American and British Luxembourger. Failed physicist. Cofounder and ex-CTO of Tumelo. Now working on Quary.",
"is_active": false,
"linkedin_url": "https://linkedin.com/in/benfking",
"x_url": "https://twitter.com/BenFKing",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/57e5a152908e6b47ecc0300e14b991407d92bc63.jpg"
},
{
"user_id": 528679,
"full_name": "Louis Jordan",
"title": "Founder",
"founder_bio": "Ex-Amazon (Data/Fintech)",
"is_active": false,
"linkedin_url": "https://linkedin.com/in/louis-j-52841a105",
"x_url": "https://twitter.com/louisjoejordan",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/90d150f0764608d33f53599e65c132f972ce4e1f.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 78152,
"title": "🆀 Quary - Transform data together 🤝",
"tagline": "Stop depending on your data team and bring everyone into the data action!",
"body": "**tl;dr: Quary connects to your data warehouse and lets your team transform raw data into valuable insights in seconds, right from your browser! Try our free trial:** [www.quary.dev](http://www.quary.dev)\n\n\\\nHey 👋. [Ben](https://linkedin.com/in/benfking) and [Louis](https://www.linkedin.com/in/louisjor/) here, we’re excited to share what we’ve been up to! [Quary](https://www.quary.dev/) is a browser-based **SQL transformation tool** that turns your raw data— whether in Snowflake, BigQuery, or DuckDB— into organized, well-documented & tested transformations.\n\n\n\n**❌ The problem**\n\nData engineers make up **5%** of businesses. They dig for insights for the other **95%** with predictable outcomes: siloed & overworked data teams, unshared knowledge, and delayed answers to critical business questions.\n\n**✅ The solution**\n\nQuary makes data engineering collaborative, sharing the responsibility across the organization. With Quary, **5%** becomes **50%**. Anyone who writes SQL can build production-grade pipelines in minutes.\n\n**The team**\n\n**Ben** and **Louis** here, we’re originally from Luxembourg 🇱🇺. Ben founded [Tumelo](https://www.tumelo.com) and led engineering there through its Series A. Louis survived a 4-year stint as a Software Engineer in Finance at Amazon.\n\n**Try out our free trial:** ",
"url": "https://www.ycombinator.com/launches/KKW-quary-transform-data-together",
"votes": 138,
"created_at": "2024-02-05T15:57:48.178Z"
}
]
},
{
"id": 29300,
"name": "Trellis AI",
"slug": "trellis-ai",
"former_names": [
"Trellis"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/f9cc80521b4e48dc602aef29ce4fb7d4c0f5dda1.png",
"website": "https://runtrellis.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "",
"one_liner": "Accelerate Medication Access with AI",
"team_size": 34,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1709255809,
"tags": [
"B2B",
"Data Engineering",
"Infrastructure",
"AI",
"Databases"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2024",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/trellis-ai",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2024/trellis-ai.json",
"year_founded": 2024,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/runtrellis",
"x_url": "https://twitter.com/runtrellis",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/f9cc80521b4e48dc602aef29ce4fb7d4c0f5dda1.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Tom Blomfield",
"url": "https://www.ycombinator.com/people/tom-blomfield"
},
"founders": [
{
"user_id": 365595,
"full_name": "Mac Klinkachorn",
"title": "Founder/CEO",
"founder_bio": "Mac is the co-founder and CEO of Trellis. Previously, he worked at the Stanford AI lab on large multimodal models for Stanford Health and built ML infrastructure at Cresta, Moveworks, and Amazon. ",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/sirapop-klinkachorn-stanford",
"x_url": "https://twitter.com/MKlinkachorn",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/3b1519f0bcfd993a8dbb236c3c3623c4e3ef1818.jpg"
},
{
"user_id": 1470616,
"full_name": "Jacky Lin",
"title": "Founder/CPO",
"founder_bio": "Jacky is a co-founder of Trellis and has taught hundreds of Stanford graduate students how to build, train, and deploy AI models in the Stanford School of Engineering & Graduate School of Business. Previously, he worked at Meta, the World Bank, and Wayfair. ",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/jhslin",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/839a64adac97b949f442d82bf502f77a5cc97e42.jpg"
}
],
"jobs": [
{
"id": 90948,
"title": "AI Deployment Strategist",
"url": "https://www.ycombinator.com/companies/trellis-ai/jobs/qCGwSCc-ai-deployment-strategist",
"location": "San Francisco, CA, US / Remote (US)",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "$120K - $220K",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 92422,
"title": "Member of Technical Staff (full-time)",
"url": "https://www.ycombinator.com/companies/trellis-ai/jobs/cg2Sy6U-member-of-technical-staff-full-time",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150K - $275K",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 96753,
"title": "Windows Systems Engineer ",
"url": "https://www.ycombinator.com/companies/trellis-ai/jobs/g0VlgB5-windows-systems-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Devops",
"salary_range": "$100K - $175K",
"equity_range": "0.10% - 0.30%",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"PowerShell",
"Windows"
]
},
{
"id": 111456,
"title": "RCM Operations Specialist, Infusion (AI Platform)",
"url": "https://www.ycombinator.com/companies/trellis-ai/jobs/Dtj2yEH-rcm-operations-specialist-infusion-ai-platform",
"location": "San Francisco, CA, US / Remote (US)",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "$70K - $120K",
"equity_range": "",
"experience": "3+ years",
"visa": "Will sponsor",
"skills": []
},
{
"id": 116076,
"title": "Forward Deployed Engineers (October 2026)",
"url": "https://www.ycombinator.com/companies/trellis-ai/jobs/GU8CEhE-forward-deployed-engineers-october-2026",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$120K - $225K",
"equity_range": "",
"experience": "1+ years",
"visa": "Will sponsor",
"skills": []
},
{
"id": 116768,
"title": "Account Executive",
"url": "https://www.ycombinator.com/companies/trellis-ai/jobs/J5OtVzK-account-executive",
"location": "San Francisco, CA, US / Remote (US)",
"type": "Full-time",
"role": "Sales",
"role_type": null,
"salary_range": "$250K - $350K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
},
{
"id": 117422,
"title": "GTM Engineer",
"url": "https://www.ycombinator.com/companies/trellis-ai/jobs/TGrLp7J-gtm-engineer",
"location": "San Francisco, CA, US / Remote (US)",
"type": "Full-time",
"role": "Sales",
"role_type": null,
"salary_range": "$100K - $175K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": []
}
],
"news": [],
"launches": [
{
"id": 78943,
"title": "🌊 Trellis AI: Automate your Pre-sevice workflow⚡️",
"tagline": "Reduce time-to-treatment, improve reimbursement rates, and ",
"body": "### **TL;DR**\n\nTrellis helps healthcare providers treat more patients faster—while eliminating pre-service paperwork. We automate document intake, prior authorizations, and appeals at scale to streamline operations and accelerate care.\n\n❌ **Problem — Administrative costs are delaying care and draining revenue**\n\nOver 20% of U.S. healthcare spending goes toward administrative costs, delaying care, reducing revenue, and driving staff burnout—while leaving providers with less visibility into patient care than ever before.\n\nPrior authorizations, appeals, and pre-service documentation are some of the biggest bottlenecks to timely treatment. Manual processing is slow, error-prone, and costly—leading to delayed treatments, increased denial rates, and frustrated patients.\n\n🎉 **Solution**\n\nOur AI agent is trained on millions of clinical data points and converts messy, unstructured documents into clean, structured data directly in your EHR—at scale.\n\nWe handle the heavy lifting:\n\n* **Automating document intake** from faxes, PDFs, and scanned forms\n* **Processing prior authorizations and appeals** with high accuracy\n* **Integrating directly into EHR workflows** so staff can focus on care, not paperwork\n\nTrellis in action: Processing hundreds of pages per patient case to identify missing information, complete submissions, and accelerate treatment approvals.\n\n🏃🏽♂️ **Leading healthcare organizations use Trellis to:**\n\n* **Reduce time to treatment by over 90%**—ensuring patients start therapy faster\n* **Improve prior authorization approval and reimbursement rates**—reducing revenue leakage\n* **Leverage structured data for better clinical decision-making**—enhancing drug program performance and patient outcomes\n\n**About Us:**\n\nMac & Jacky are friends from the Stanford AI Lab, where we spent too much time indoors building language models and hoping they’d talk back 🧠💻\n\nPreviously, Mac built LLM infra at Cresta and Moveworks where our ML pipelines processed terabytes of chat logs and voice calls. Jacky taught AI classes at Stanford and worked at Meta on real-time machine learning systems handling complex model deployment challenges.\n\nTrellis is a spinout from Stanford AI Lab and is backed by leading investors including YC, General Catalyst, Telesoft Partners, and executives at Google and Salesforce.",
"url": "https://www.ycombinator.com/launches/KXH-trellis-ai-automate-your-pre-sevice-workflow",
"votes": 69,
"created_at": "2024-03-01T14:13:48.722Z"
}
]
},
{
"id": 29442,
"name": "Ocular AI",
"slug": "ocular-ai",
"former_names": [
"AutoflowAI (Zapier for AI Copilots)",
"AutoflowAI",
"Ocular"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/2d1b75bdedcefb73d59cc0a2f122bdc71abfcc6e.png",
"website": "https://useocular.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "",
"one_liner": "Applied AI Data Research Lab Encoding Human Expertise into Machines…",
"team_size": 8,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1706216304,
"tags": [
"Machine Learning",
"Speech Recognition",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2024",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": [
{
"question": "What is the core problem you are solving? Why is this a big problem? What made you decide to work on it?",
"answer": "Having worked at Microsoft and Google, we experienced first-hand how difficult it is to access and find information and perform actions across multiple Saas tools both in the workplace and engineering. We’ve interviewed numerous employees and engineers at Appian, Uber, Pinecone, Brex, Coda, Microsoft, Google among others and learned that as companies grow it gets harder to: 1\\. **Find what you need at work:** Company knowledge lives in multiple, isolated Saas applications and employees spend over a quarter of their workday looking for information, documents, apps, and people they need to do work or get permissions. 2\\. **Manage complex engineering tools:** As engineering teams scale and adopt microservices, they onboard multiple tools for documentation, development, release, monitoring and alerting. \\* Tools (such as CircleCI, DataDog, New Relic, etc) all live in different places which makes it very difficult to have a unified view of your techstack.\\* \\* \\* Critical data, metrics, logs, and dashboards are all in isolated platforms, complicating discovery, correlation, multitool workflow coordination, and usage—especially during incidents.Siloed tooling and data introduces operational tax to the life of employees and engineers, slowing down productivity, development cycles, and incident management."
}
],
"url": "https://www.ycombinator.com/companies/ocular-ai",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2024/ocular-ai.json",
"year_founded": 2024,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/use-ocular",
"x_url": "https://x.com/OcularHQ",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/ocular-ai",
"github_url": "https://github.com/OcularEngineering",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/2d1b75bdedcefb73d59cc0a2f122bdc71abfcc6e.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/aad644def34ae3d517719e693ef92a82868a185a.png"
],
"primary_partner": null,
"founders": [
{
"user_id": 928098,
"full_name": "Michael Moyo",
"title": "Founder/CEO",
"founder_bio": "CEO & Co–Founder of Ocular AI. Computer and Biomedical Engineer.\n",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/michaelmoyo",
"x_url": "https://twitter.com/SonofMushabati",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/6959040840b8fd81769bb3f59506b26293892c8a.jpg"
},
{
"user_id": 1313975,
"full_name": "Louis Murerwa",
"title": "Founder",
"founder_bio": "Louis is the Co-founder and CTO of Ocular AI. He is from Zimbabwe and studied Computer Science at Dartmouth College. Previously Louis worked at Google NYC as a Software Engineer where he built Distributed Architecture that powers Google Cloud. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/louismurerwa/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/3ae4ac166c25ea521a78371102958f1076540542.jpg"
}
],
"jobs": [
{
"id": 71525,
"title": "Member of Technical Staff, Founding Backend Engineer",
"url": "https://www.ycombinator.com/companies/ocular-ai/jobs/BFBHWQd-member-of-technical-staff-founding-backend-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Backend",
"salary_range": "$150K - $200K",
"equity_range": "0.50% - 1.00%",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"PostgreSQL",
"Python",
"React",
"Torch/PyTorch"
]
},
{
"id": 71623,
"title": "Member of Technical Staff, Founding Design Engineer",
"url": "https://www.ycombinator.com/companies/ocular-ai/jobs/GWPuqvr-member-of-technical-staff-founding-design-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Frontend",
"salary_range": "$130K - $200K",
"equity_range": "0.30% - 1.00%",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"TypeScript",
"Next.js"
]
},
{
"id": 71633,
"title": "Member of Technical Staff, Founding Frontend Engineer",
"url": "https://www.ycombinator.com/companies/ocular-ai/jobs/Cjr9AlQ-member-of-technical-staff-founding-frontend-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Frontend",
"salary_range": "$130K - $200K",
"equity_range": "0.30% - 1.00%",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"JavaScript",
"React",
"TypeScript",
"Computer Vision",
"Figma",
"Next.js"
]
},
{
"id": 73015,
"title": "Member of Technical Staff, Founding Machine Learning Engineer",
"url": "https://www.ycombinator.com/companies/ocular-ai/jobs/9UVGCDr-member-of-technical-staff-founding-machine-learning-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Machine learning",
"salary_range": "$130K - $200K",
"equity_range": "0.30% - 1.00%",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"Python",
"TensorFlow",
"CUDA",
"OpenCV"
]
}
],
"news": [],
"launches": [
{
"id": 79032,
"title": "Ocular AI - Bringing enterprise search, gen AI, and actions to the workplace",
"tagline": "Ocular AI lets teams within organizations search, visualize, and perform critical cross tool actions all on one unified platform.",
"body": "We’re [Michael](https://www.linkedin.com/in/michaelmoyo/) and [Louis](https://www.linkedin.com/in/louismurerwa/) and are excited to officially launch [Ocular AI](https://www.useocular.com/)!\n\nBook demos [here.](https://calendly.com/use-ocular/30min?month=2024-03#utm_source=launchyc&utm_medium=Launch+YC+Blog+Post&utm_campaign=launch&utm_id=launchyc&utm_content=launch+yc)\n\n**💡 Tl;Dr:**\n\n[**Ocular AI** ](https://www.linkedin.com/company/use-ocular)makes it easy for employees in mid-market and enterprise companies to find information and perform cross-tool actions using Generative AI-powered Search. We do this by providing a beautiful Google-like interface and a co-pilot that connects to all your company apps and tools. \n\n[ ](https://youtu.be/gAHGlKwBQJg)\n\n**❌ Problem**\n\nHaving worked at Google and Microsoft, we experienced first-hand how difficult it is to access and find information and perform actions across multiple SaaS tools both in the workplace and in engineering. Through our experience and conversations with people at Appian, Boeing, General Electric, Uber, Pinecone, Brex, Coda, Unity, Microsoft, and Google, we learned that as companies grow it gets very challenging to:\n\n1. **Find what you need at work:** Company knowledge lives in multiple, isolated SaaS applications, and employees spend over a quarter of their workday looking for information (think of documentation, past slack threads, etc), finding the people needed to complete tasks, and getting the required permissions.\n2. **Manage complex engineering tools:** As engineering teams scale and adopt microservices, they onboard multiple tools for documentation, development, release, monitoring, and alerting. Critical data, metrics, logs, and dashboards are all in isolated platforms such as CircleCI, DataDog, and New Relic and this makes it very difficult to have a unified view of company data, correlation data across these tools, and complete multitool workflow coordination - especially during incidents.\n\n \n\nSiloed tooling and data introduce an operational tax to the lives of employees like engineers, slowing down productivity, development cycles, and incident management. Workers spend an average of a quarter of their day searching for information. \n\nAll of this time can be used to write more code, do more deals, and talk to customers. With the rise of AI and Copilots, the value of the time spent on doing actual work has never been so high.\n\n**🚀🚀🚀 Our Solution**\n\n🔎 **Enterprise Search for everyone in your company:** Integrate all of your company’s applications, tooling, and data sources to power organizational and team-level search. Organization members only see the information they have access to based on their roles.\n\n\n\n\\\n🤖 **Ocular Copilot- your work assistant that knows everything about your company:** Power cross-tool workflows and actions using our generative AI-powered Ocular Copilot. Create workspaces, upload files (structured or unstructured), create collections, and build usage-specific assistants for your day-to-day tasks. \n\n\n\n**App MarketPlace:** Integrate the tools (Notion, Jira, Google Drive, Slack) you already love and use for your day-to-day tasks.\n\n\n\n**Admin Portal:** \n\nOcular AI provides search-driven insights such as trending searches, number of searches, etc., which allows execs and managers to understand their organizations better. With Ocular, you can now see which applications are used the most and which ones are underutilized, allowing organizations to make reliable SaaS spend decisions. In addition, add members, teams, and applications to your Ocular instance.\n\n[ ](https://youtu.be/9Y9ex6e_vqE)\n\n## **📈 Maximizing Generative AI ROI for Enterprise**\n\nEnterprises are eager to adopt Generative AI in the workplace to enhance operational efficiencies. We’re partnering with organizations to implement secure, compliant, and company-specific Generative AI.\n\n**🔐 Enterprise security**\n\nComing from Microsoft and Google, we understand the importance of data privacy and security. For that reason, you can self-host Ocular AI on-premise or on bring your own cloud (BYOC), so all your data stays within your control- we don’t have access to it. Ocular AI is also getting SOC2 compliant and enforcing end-to-end data encryption AES 256. We’ll also be adding more security layers to ensure your data is 100% safe.\n\n**💯 The Team**\n\n[Dartmouth College](https://home.dartmouth.edu/) graduates with software engineering experience building large-scale and compliant applications at Google and Microsoft.\n\n\n\n**🫡 Our Ask**\n\nPlease introduce us to managers, CEOs, CIOs, and CTOs. We can help unify their tools and data together to make their teams more efficient. \n\nSchedule a demo at [www.useocular.com](https://www.useocular.com#utm_source=launchyc&utm_medium=Launch+YC+Blog+Post&utm_campaign=launch&utm_id=launchyc&utm_content=launch+yc) or [here.](https://calendly.com/use-ocular/30min?month=2024-03#utm_source=launchyc&utm_medium=Launch+YC+Blog+Post&utm_campaign=launch&utm_id=launchyc&utm_content=launch+yc)\n\nJump on the [waitlist!](https://form.asana.com/?k=kIT2oNFOWol6_RptDc_vpQ&d=1206400736295884) 🚀\n\nReach us at [founder@useocular.com](mailto:founder@useocular.com)! ✉️",
"url": "https://www.ycombinator.com/launches/KYi-ocular-ai-bringing-enterprise-search-gen-ai-and-actions-to-the-workplace",
"votes": 58,
"created_at": "2024-03-04T20:04:01.162Z"
}
]
},
{
"id": 29507,
"name": "kater.ai",
"slug": "kater-ai",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/8e4c3ef97e004d2c1c5507c262401d7ad2a716ab.png",
"website": "https://www.kater.ai",
"all_locations": "San Francisco, CA, USA; Remote",
"long_description": "1. You explain your problem.\r\n2. Kater identifies the most important data questions to ask.\r\n3. Kater writes the code.\r\n4. You get insights in seconds rather than weeks.\r\n\r\nKater.ai flips the script on enterprise analytics by making every user an expert analyst. It uses a continuous classification engine to turn a single business question into a contextualized package of questions that is specific to your needs.\r\n\r\nKater puts the power of data into the hands of business experts while ensuring they use trusted data that is specific to their persona. No more waiting for data analysts. No more wasted time on analysis misfires and rework.\r\n\r\nYvonne was a data engineer and analyst who built the entire data stack at CREXi. Robin led engineering in Microsoft. \r\n\r\n\r\nData is the new oil. Companies are data-rich, insight-poor. We're helping companies become insight-rich. This is the future of data. ",
"one_liner": "Deliver complete data analysis from a single question",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1706308353,
"tags": [
"Analytics",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2024",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/kater-ai",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2024/kater-ai.json",
"year_founded": 2023,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/kater-ai/?viewAsMember=true",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/8e4c3ef97e004d2c1c5507c262401d7ad2a716ab.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Diana Hu",
"url": "https://www.ycombinator.com/people/diana-hu"
},
"founders": [
{
"user_id": 1748835,
"full_name": "Yvonne Chou",
"title": "Founder/CEO",
"founder_bio": "Yvonne is the co-founder and CEO of Kater. She graduated from UC Berkeley. Previously, she was a data engineer at Crexi, where she built the data infrastructure from the ground up. She has 8+ years of experience working in analytics teams for companies like Kaiser Permanente, Tapcart, and Crexi, where she supplied data to all dashboards for sales, marketing, finance, and executive management. ",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/yvonne-chou",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/105b84e9814af348e3d870e0e67545ac4a3cb537.jpg"
},
{
"user_id": 1750692,
"full_name": "Robin Seitz",
"title": "Founder/CTO",
"founder_bio": "Robin is the co-founder and CTO of Kater. He graduated Magna Cum Laude from UCLA. Previously, he worked at companies such as Microsoft, Abbott and Paragon as a Software Engineer. He has 8+ years of experience working in different software engineering disciplines, including distributed systems, full stack engineering and big data.",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/robin-seitz-12029970",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ac2b0619cb118ef872d740c8a400982c0bdbcd19.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 78970,
"title": "Kater: Ask data questions in plain English",
"tagline": "Drive business outcomes with an AI analyst that organizes, understands, and remembers all the nuances of your company's data.",
"body": "# TL;DR\n\nInstead of Slacking the data team and waiting 4 days for an answer, use [Kater](https://www.kater.ai) to get the answer in 30 seconds. We make it possible for executives to understand **why** business outcomes occur, and even alert them **before** the outcomes happen again.\n\n### 👋 Hey Everyone\n\nWe’re [Yvonne](https://linkedin.com/in/yvonne-chou) and [Robin](https://linkedin.com/in/robin-seitz-12029970). We have over 9 years working in data teams for companies like Microsoft, Kaiser Permanente, Crexi, and Abbott. \n\n\n\nAs data people, **80%-90% of our time** was dedicated to low-level data requests. When really, the true business value of data comes from answering the **“why”** questions.\n\nThat’s why we started [kater.ai](http://kater.ai) — we are committed to automating these low-level questions, and empowering everyone in a company to answer “why” business outcomes occur. **These are the million dollar questions that fundamentally change how businesses operate, and ones they’ve historically never been able to address.**\n\n### 🤔 Why Can’t Companies Answer “Why” Questions?\n\n**The existing enterprise data operation workflow is unscalable.**\n\n1. Data teams receive **10-15** adhoc requests per day\n2. Companies spend on average **$10.5 million/year** in data analyst salaries\n3. Data is extremely **messy**\n\n### 👨💼📊 Meet Butler: Your AI Data Agent\n\n**The solution:**\n\nButler is an AI agent that organizes the chaos of data.\n\nWe found a new way to **auto-document your data team’s tribal knowledge through generating a data map.** Butler indexes and searches the data map using a AgentMesh Framework.\n\n**Butler helps generate hypotheses, writes the queries to validate those hypotheses, and finds any insights from the queries.**\n\n### 🧠 Butler Continuously Learns\n\nWe use a combination of RAG and GenAI to capture any feedback users give to support future context for Butler.\n\n\n\n[A 30-second Demo:](https://youtu.be/hiF-F0W61Dw)\n\n### 🔗 The Set Up Process:\n\n1. Simply **connect** Kater’s website to your data warehouse.\n2. We’ll **auto-generate descriptions** for all your tables and columns, and immediately start building the **data map** for you.\n3. After you verify the data map is correct, in **less than 10 minutes**, you can start asking questions about your data and training Butler.\n\n### 🙏 Our Ask\n\nWe currently support connections with Snowflake, Bigquery, and Microsoft SQL Server. If you have any of these (of even if you don’t, we can build a connector in 1 hour) and want to be able to query your data using English, reach out to us at [support@kater.ai](mailto:support@kater.ai)!",
"url": "https://www.ycombinator.com/launches/KXi-kater-ask-data-questions-in-plain-english",
"votes": 32,
"created_at": "2024-03-01T23:07:40.847Z"
}
]
},
{
"id": 29727,
"name": "Overstand Labs",
"slug": "overstand-labs",
"former_names": [
"Overstand Labs",
"Overstand Labs Inc."
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/061e173be11210d3cca9f1b51ba89c7c5255750b.png",
"website": "https://overstandlabs.com",
"all_locations": "New York City, NY, USA",
"long_description": "Overstand is a data lab that allows our customers to navigate any set of data in just a few minutes.\r\n\r\n*Enterprise*: For enterprises, we we unify Slack, email, calls, and operational data, then surface the signals that matter — customer needs, risks, and revenue opportunities hidden in everyday conversations.\r\n\r\n*Legal Firms*: For legal firms, we help them really quickly understand their entire discovery corpus (either before, or after document review), and quickly build out an initial case assessment and facts.\r\n\r\nInstead of waiting on reports or manual analysis, teams get immediate, evidence-backed answers from the data they already have. Overstand delivers clarity and leverage as your business scales.",
"one_liner": "Navigate any set of data - no matter how large - in minutes.",
"team_size": 4,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1724369845,
"tags": [
"LegalTech",
"Data Science",
"Data Engineering",
"AI",
"Conversational AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2025",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/overstand-labs",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2025/overstand-labs.json",
"year_founded": 2024,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/overstand-labs/",
"x_url": "https://x.com/OverstandLabs",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/061e173be11210d3cca9f1b51ba89c7c5255750b.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Tyler Bosmeny",
"url": "https://www.ycombinator.com/people/tyler-bosmeny"
},
"founders": [
{
"user_id": 1993194,
"full_name": "Mihir Patil",
"title": "Founder/CTO",
"founder_bio": "Co-founder of Overstand Labs. California Native. Ex-Palantir. Faculty @ NYU. Go Bears!",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/mihirnpatil/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/f426ba6fe9ee49a3ffe6f50a7fa7bdaf607d2a5e.jpg"
},
{
"user_id": 282405,
"full_name": "Derrick Cheng",
"title": "Founder",
"founder_bio": "Co-Founder of Overstand Labs | Ex-Meta | AI @ Berkeley",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/chengderrick",
"x_url": "http://twitter.com/dowithderrick",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/eb972f35799a490a0e323593b2ea731f4a7db12c.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 98764,
"title": "Overstand: A personal data team for Execs",
"tagline": "Business leaders have ideas all the time. Overstand lets them validate and act upon them in just a few minutes.",
"body": "**TL;DR**: [Overstand](https://overstandlabs.com/) is a personal data lab for Execs. We allow business leaders validate their intuitions against their company’s data — with their just their voice, you can go from a raw idea to an evidence-backed answer. They can even see a reproducible step-by-step process and underlying data behind it — all in a few in minutes. Have a look at our [launch video](https://www.youtube.com/watch?v=KrOwutgKsEA).\\\n\\\nAfter working with a bunch of larger companies, we learned something important: some of the most valuable questions are not the ones people plan dashboards for. They're the spontaneous ones, the realizations that you have mid-conversation... the \"wait a minute…\" moments.\n\nHere’s an example that many of us have encountered at some point: let's say you're talking to a customer, and they say \"_you know we've really struggled to figure out how to solve X at our company. Is that something you can help us with?_\" They might explain why X is hard, and you'd go back and forth a little.\n\nThen you wonder, at some point — is this just them, or have others said the same thing? Has anyone else on your 200-person GTM team heard of _X_ before? The signal is buried across massive email threads, Gong transcripts, Slack threads, and CRM notes — there’s no way to know quickly.\n\nSo this intuition fades. Perhaps you’re able to help that customer in a one-off way, but you don’t see the broader pattern.\n\nWe built Overstand to solve for this exact gap — the crevices where data collection has traditionally failed to help you. The spurious thought that you might’ve had.\n\nYou articulate your intuition in plain language — \"_show me all instances of a customer indicating they're struggling with X._\" Overstand builds an entire data pipeline on top of your company's comms + hard data and surfaces the underlying examples that answer your questions — in just a few minutes. From there you can drill down: ask follow-ups to hone in on specific instances, chart the results over time or pull everything into a single context to discuss what was found. You can even action each result individually — sending contextually-crafted emails to each customer who mentioned _X_.\n\nAll of this, with just your computer or phone (and you can even do it with your voice — we call it _speech-to-data-pipeline_).\n\nMost enterprise tools are built around questions you already know to ask. Overstand is built around the ones you didn't plan for.\n\nIf you're running GTM, CS, or product at a company with real customer volume and this problem sounds familiar — we'd love to talk.\n\n\n\n",
"url": "https://www.ycombinator.com/launches/Pgy-overstand-a-personal-data-team-for-execs",
"votes": 8,
"created_at": "2026-03-19T20:31:17.415Z"
},
{
"id": 87277,
"title": "Overstand – Unlock Founder Mode with Real-Time Customer Insights",
"tagline": "Know where your company needs you most",
"body": "[Overstand](https://www.overstandlabs.com/) is a single platform and API that helps business leaders unlock \"founder mode\" by providing real-time insights from all customer communications—Slack, email, WhatsApp, call recordings, and more.\\\n\\\n**The problem:** As companies grow, it becomes harder for leaders to stay deeply connected to their customers. Critical trends, opportunities, and issues often go unnoticed, leading to slower decision-making, missed opportunities, and unresolved problems. Scaling without visibility into what’s happening at the “edges” of the business—customer interactions—creates blind spots that hinder growth.\n\n\n\n**How we solve it:** Overstand aggregates customer communications into one unified platform and delivers actionable insights.\n\n* **Know Where You’re Needed Most:** Focus on areas where your involvement can drive the biggest impact.\n* **Find Opportunities Everywhere:** Discover new prospects or expand existing relationships.\n* **Spot Trends Instantly:** Identify issues and opportunities in real time.\n* **Integrate Seamlessly:** Use Overstand’s API to bring insights directly into workflows, dashboards, or other tools.\n\nWith Overstand, business leaders regain clarity, focus, and the ability to scale while staying deeply in tune with their customers. [See a demo of Overstand here.](https://www.youtube.com/watch?v=-8tqKeXW2Cw)\\\n\\\n**Our ask:** If you or someone you know is struggling to maintain visibility into their company's customer interactions and opportunities, we’d love to help. Reach out to [founders@overstandlabs.com](mailto:founders@overstandlabs.com) or visit [overstandlabs.com](http://overstandlabs.com) to learn more or schedule a demo.",
"url": "https://www.ycombinator.com/launches/Mhh-overstand-unlock-founder-mode-with-real-time-customer-insights",
"votes": 57,
"created_at": "2025-01-29T18:28:19.132Z"
},
{
"id": 83338,
"title": "Overstand - The platform for upselling your enterprise accounts",
"tagline": "Meet Overstand, the cross-selling engine for enterprise software companies.",
"body": "**TLDR**: [Overstand](https://overstandlabs.com/) helps enterprise software teams maximize revenue by reading all customer communication channels (chat, email, call recordings, support tickets) to uncover opportunities for contract expansion.\n\n**The problem:**\n\nBig tech companies know that one of the best ways to increase revenue is to bring more value to existing customers. But customer account management involves not just sales, but also support, customer success, implementation teams, and so on. Customers might voice problems that are not conveyed in a timely manner (or at all!) to those responsible for expanding the account.\n\nEnterprise software companies are leaving a lot of potential revenue on the table— some offer a whole menu of products, with each enterprise customer only taking advantage of one or a few of the offerings.\n\n**The solution:**\n\nOverstand is designed to read all customer communications and flag opportunities for expansion of customer accounts. It identifies hidden expansion opportunities that are buried in customer communications by analyzing every single message and comparing it to product docs and even existing use cases at other enterprise accounts.\n\n\n\n\n\n**The team:**\n\n\n\nWe met at Palantir several years ago and both recognized the importance of empowering customer-facing teams to fully understand and sell highly technical and complex products. [Mihir](https://www.linkedin.com/in/mihirnpatil/) was a PM and engineering lead at Palantir and often felt that many existing customers could have further benefited from using his products. [Senta](https://www.linkedin.com/in/senta/) managed customer accounts valued in the double-digit millions and often observed challenges associated with upselling into existing accounts.\n\n**Asks:**\n\nIf you’re interested in cross-selling and upselling as a strategy for growing your enterprise account revenue, we’d love to chat! Email us at [founders@overstandlabs.com](mailto:founders@overstandlabs.com).\n\nFollow us [on LinkedIn](https://www.linkedin.com/company/overstand-labs/)!",
"url": "https://www.ycombinator.com/launches/LgA-overstand-the-platform-for-upselling-your-enterprise-accounts",
"votes": 52,
"created_at": "2024-08-23T01:13:45.957Z"
}
]
},
{
"id": 29745,
"name": "Sharpe",
"slug": "sharpe",
"former_names": [
"January",
"Lumenary",
"Lumenary, Inc.",
"Lumenary"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/ed377f5e3e709abc9139475076cec71316b01c06.png",
"website": "https://sharpe.sh",
"all_locations": "San Francisco, CA, USA",
"long_description": "Sharpe helps traders go from idea to profit in minutes with AI, bundling petabytes of market data with high-performance infrastructure.",
"one_liner": "Agents for quantitative research and financial data science.",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1722638950,
"tags": [
"Finance",
"Analytics",
"Big Data",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2024",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/sharpe",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2024/sharpe.json",
"year_founded": 2024,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/sharpe011235",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/ed377f5e3e709abc9139475076cec71316b01c06.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 308988,
"full_name": "Vivek Hazari",
"title": "Founder",
"founder_bio": "Vivek is a co-founder of Sharpe. Vivek spent 2 years at Palantir Technologies, where he worked across the commercial business, and later help found and lead a team to aid the development of AIP. He studied Computer Science and Philosophy at Dartmouth College, where he did research on applications of language models.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/vivekhaz/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/0cf7befe3f5ca27609ce2af3997c897f306b3e72.jpg"
},
{
"user_id": 1131934,
"full_name": "Daniel DiPietro",
"title": "Founder",
"founder_bio": "Dan is the co-founder of Sharpe. Previously, Dan worked at Jane Street, where he built capital allocation optimizations used in production to invest billions of dollars of assets, as well as an options tool used to execute >$100m of trades annually. He has published multiple first-author publications in high-impact venues like NeurIPS and CoRL. Dan moonlights as a botanist and published a best-selling botanical textbook on carnivorous plants while studying at Dartmouth College.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/daniel-dipietro/",
"x_url": "https://twitter.com/dandipietro1",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b72974d4717fb918125809f70966e2f04f32fc1e.jpg"
},
{
"user_id": 1944134,
"full_name": "John McCambridge",
"title": "Founder/CPO",
"founder_bio": "CTO of Sharpe & former high-frequency trading engineer - I like to fly (and jump from) small aircraft, build rockets with kitchen chemicals, visit vulnerable endpoints, and play poker - Born in New Zealand, raised in Scottish Highlands.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/johnmccambr",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/d068cf589b32c00f9e6b858284fcb48465e279f2.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 91284,
"title": "Solar: An infinite canvas for vibe-coding production apps",
"tagline": "We build the most complicated full-stack apps, faster than anywhere else.",
"body": "## TL;DR\n\nSolar lets small teams collaborate with AI agents to build and deploy production apps in minutes. Like Figma, but no mockups—just real software with live data and backend Python functionality. Built by our full-stack AI agent, powered by your imagination.\n\nhttps://youtu.be/Gl03z0M8BWk\n\n## Why this, and why us?\n\nHi everyone! We’re Vivek, Dan, John, and Ziray: the team behind [Lumenary](http://www.lumenary.com). We met each other during our first few weeks at Dartmouth and have been best friends ever since. We’ve lived together, worked together, traveled the world together, and have even summited some notable peaks together (don’t ask about Mount Shasta).\n\nOur team brings together engineering from Palantir, Jane Street, IMC Trading, and Flatiron Health. We’ve built enterprise-grade AI products, a capital allocation system that controls billions, a data engine that processes petabytes–we _all_ build and deploy software _quickly_ in contexts _where it cannot fail_.\n\nSolar began as an internal tool that we used to ship enterprise demos faster than any tool on the market. We decided to productize and focus on Solar completely.\n\n\n\n## The Problem\n\nWe’re a team of four engineers who’ve used nearly every AI-powered app builder. Projects started off great, but we found ourselves in an endless loop of “revert, and try again.” Most of our time was spent waiting and hoping as the LLM made changes one-at-a-time.\n\nEven when the app seemed to work, it was unclear what were real features versus frontend demoware. We lacked an understanding of the architecture, dataflow, and what vulnerabilities were left open. It felt like these platforms had prioritized making neat frontends and bolted on real functionality as an afterthought.\n\n\n\n## What we do\n\nWe loved three things:\n\n* Figma’s flexibility — work on many designs with many people\n* Cursor’s power — write production code with LLMs\n* Retool’s safety — ship apps that you know work\n\nWe combined those to make Solar.\n\nSolar’s AI agents collaborate alongside you on a multiplayer canvas. You can see the relationships and data flow between database tables, backend Python logic, and frontend pages.\n\n\n\nSolar makes apps production-worthy by combining LLM-generated code with deterministic code generation for databases, services, and authentication. This makes your apps maintainable and deployable past the MVP, and able to integrate nicely with existing infrastructure.\n\nWe’re the most agentic platform on the market: Solar will read logs, interact with your application, and work for minutes or even hours unattended to get it perfect.\n\n## Our Ask\n\nSign up at https://solarapp.dev and try building an app.",
"url": "https://www.ycombinator.com/launches/NkK-solar-an-infinite-canvas-for-vibe-coding-production-apps",
"votes": 27,
"created_at": "2025-06-13T15:20:00.950Z"
}
]
},
{
"id": 29764,
"name": "Zeit AI",
"slug": "zeit-ai",
"former_names": [
"Cascada AI"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/a8b12b6d63b7ef88542a88cfd73009aa6a48073f.png",
"website": "https://zeit-ai.com/",
"all_locations": "Munich, BY, Germany",
"long_description": "Ask a question in plain English and ZeitMind connects SAP, your ERP, CRM, HR systems and 600+ other sources, prepares the messy data, and turns it into the live applications your teams actually make decisions with.\r\n\r\nIt is built for the finance, controlling, procurement, supply chain and sales teams at companies that run enterprise systems without an enterprise data team.",
"one_liner": "The autonomous data engineer for the mid-market",
"team_size": 12,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1722311835,
"tags": [
"SaaS",
"B2B",
"Analytics",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Summer 2024",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"Germany",
"Europe",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": [
{
"question": "How did your company get started? (i.e., How did the founders meet? How did you come up with the idea? How did you decide to be a founder?)",
"answer": "For years we worked side by side at Palantir, building with some of the largest industrial companies on the continent. Leopold led the established customer business across Germany, Austria and Switzerland. Marvin owned and deployed the first instances of what became the Artificial Intelligence Platform (AIP). Together we shipped projects that turned into more than €50M in new revenue.\r\n\r\nIn summer 2024 we left. We had seen what forward-deployed engineers do for large enterprises, and one thing kept showing up: the people who actually run a business, the heads of controlling, the buyers, the plant managers, are still moving data by hand. The signal sits in the ERP, in the CRM, and in a dozen tools that do not talk to each other. So decisions get made in spreadsheets and on gut feel. The gap between the two is where companies lose time, money and confidence.\r\n\r\nWith today’s frontier models that work can finally be done at software scale. So we are building the autonomous data engineer for the mid-market. ZeitMind connects SAP, your ERP, CRM, HR systems and 600+ other sources, prepares the messy data, and turns everyday business questions into live dashboards, reports and applications, all in natural language.\r\n\r\nWe joined Y Combinator in S24, put it in front of real controlling, procurement and supply chain teams, and went from zero to €1M ARR in twelve months with six people, customers live in weeks and no IT support needed. Today we are 12 engineers, builders and operators across Munich and London."
}
],
"url": "https://www.ycombinator.com/companies/zeit-ai",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2024/zeit-ai.json",
"year_founded": 2024,
"city": "Munich",
"country": "DE",
"linkedin_url": "https://www.linkedin.com/company/103332732/",
"x_url": "",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/zeit-ai",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/a8b12b6d63b7ef88542a88cfd73009aa6a48073f.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/e340d08b700c98d24e9d28a582f8141ef5bf95db.png",
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/f82c4b946c9a049b314b8f31ecbf9c4998b12fad.png"
],
"primary_partner": {
"name": "Nicolas Dessaigne",
"url": "https://www.ycombinator.com/people/nicolas-dessaigne"
},
"founders": [
{
"user_id": 1927760,
"full_name": "Leopold von Waldthausen",
"title": "Founder/CEO",
"founder_bio": "I spent 3.5 years at Palantir, where I ended up leading all established customers in Germany, Austria and Switzerland. Before that I studied CS at Oxford, published research on process mining and cryptography, and quit an MBA at Yale. I started my first business, weview, at 18, ran it for three years and sold it to DemoUp Cliplister.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/v-waldthausen/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/73e79aa8777653820b332f6a370b2b9e220a0024.jpg"
},
{
"user_id": 1960524,
"full_name": "Marvin Christopher Bornstein",
"title": "Founder/CTO",
"founder_bio": "Before Zeit AI, I spent five years at Palantir, where I owned and deployed the first instances of what became AIP, across chemicals, railway infrastructure, media, utilities, insurance and medical equipment. Grew up around Berlin, spent the last five years in London. Writing software for 18 years, professionally for ten, mostly full stack and data engineering. Deep learning research, more hackathons than I can count, and a weakness for InfoSec CTFs.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/mcbornstein/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/d6b040be9d7efb73db0e86e1e3ed209660c049a6.jpg"
}
],
"jobs": [
{
"id": 98788,
"title": "(Junior) Account Executive (f/m/d)",
"url": "https://www.ycombinator.com/companies/zeit-ai/jobs/NnsWGLk-junior-account-executive-f-m-d",
"location": "Munich",
"type": "Full-time",
"role": "Sales",
"role_type": null,
"salary_range": "€120K - €150K EUR",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizenship/visa not required",
"skills": []
},
{
"id": 98790,
"title": "(Senior) Business Development Representative (m/f/d)",
"url": "https://www.ycombinator.com/companies/zeit-ai/jobs/APacFc6-senior-business-development-representative-m-f-d",
"location": "Munich",
"type": "Full-time",
"role": "Sales",
"role_type": null,
"salary_range": "€70K - €100K EUR",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "US citizenship/visa not required",
"skills": []
},
{
"id": 98791,
"title": "Backend Engineer (Infrastructure & Platform) (f/m/d)",
"url": "https://www.ycombinator.com/companies/zeit-ai/jobs/X4utXOx-backend-engineer-infrastructure-platform-f-m-d",
"location": "Munich / London, England, GB / Remote",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "€95K - €270K EUR",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizenship/visa not required",
"skills": []
},
{
"id": 98797,
"title": "Forward-Deployed Engineer (f/m/d)",
"url": "https://www.ycombinator.com/companies/zeit-ai/jobs/tDRfUJB-forward-deployed-engineer-f-m-d",
"location": "Munich",
"type": "Full-time",
"role": "Engineering",
"role_type": "Data science",
"salary_range": "€70K - €230K EUR",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizenship/visa not required",
"skills": []
},
{
"id": 105515,
"title": "Founders Associate (Growth & Marketing)",
"url": "https://www.ycombinator.com/companies/zeit-ai/jobs/9fQBgkg-founders-associate-growth-marketing",
"location": "Munich",
"type": "Full-time",
"role": "Marketing",
"role_type": null,
"salary_range": "€60K - €120K EUR",
"equity_range": "",
"experience": "1+ years",
"visa": "US citizenship/visa not required",
"skills": []
}
],
"news": [],
"launches": [
{
"id": 83344,
"title": "📈💡Zeit AI: Insights from your tabular data with just a few words",
"tagline": "Connect your ERP, CRM, CSVs to query them with natural language. 🗂️✅💬",
"body": "### **🏆 TLDR**\n\n[Zeit AI](https://www.zeit-ai.com/) is ChatGPT for enterprise tables. You can sync tables from your data bases, ERP systems, CRMs, CSVs and more. Atop of these tables, simple questions in natural language can be used to locate data, combine it, generate analyses, or even charts. All results are repeatable and explainable. They can be exported at the click of a button. [Watch our demo!](https://youtu.be/u3NcYh4zCz4)\n\n# 🧑💻🌟 **The Team**\n\nTogether, [Marvin](https://www.linkedin.com/in/mcbornstein/) and [Leopold](https://www.linkedin.com/in/v-waldthausen/) have over 15 years of combined experience in data engineering and analytics. During our four years side-by-side at Palantir, we led high-impact projects, building an AI rule-engine and generating over €50 million in novel project revenue. We saw first-hand how corporates heavily relied on Excel files, leading to manual work to analyse and combine data. A solution like Zeit AI would have been a game-changer in accessing this data at scale.\n\n\n\n# ⚠️ **Problem**\n\nNon-technical users find it challenging to access and analyse enterprise data. Yet, making data-driven decisions is crucial in today’s fast-paced world.\n\n1. Data is stored in files rather than structured databases.\n2. Databases cannot be accessed by non-technical users.\n3. Data often needs to be exported and manually combined in Excel.\n\n# 💡 **Solution**\n\nZeit AI allows non-technical users to derive ad-hoc insights from tables using natural language. This is possible in just three steps.\n\n1. Sync data files directly from your source systems (We support data bases, ERP, CRM and even CSV uploads).\n2. A structured cloud database is instantly generated and ready to be explored.\n3. Use natural language to seamlessly derive insights from the data.\n\n\n\n# 🛠️ **How Zeit AI is Used Today**\n\n**Procurement** 🛒 Gaining the upper hand during negotiations by having ad-hoc access to all historical procurement data.\n\n**Consulting** 🗂️ Rapidly explore and analyse data rooms and client files using natural language to confidently deliver value to clients.\n\n**Controlling** 📊 Access extracts from accounting systems and seamlessly combine them with files across departments for comprehensive financial control.\n\n# ✅ **Ask**\n\n[Book a slot](https://calendly.com/leopoldwaldthausen/deploy-zeit-ai) with us to explore using Zeit AI. Refer us to procurement managers and senior consultants. ([founders@zeit-ai.com](mailto:founders@zeit-ai.com))\n\nGet on a [30-minute call](https://calendly.com/leopoldwaldthausen/zeit-ai-demo-booking) with us for a live demo or free office hours for anyone struggling to easily access tabular data at scale.",
"url": "https://www.ycombinator.com/launches/LgG-zeit-ai-insights-from-your-tabular-data-with-just-a-few-words",
"votes": 87,
"created_at": "2024-08-23T17:41:00.051Z"
}
]
},
{
"id": 29784,
"name": "Sensei",
"slug": "sensei",
"former_names": [
"OBO"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/0e3e1067b2d9b0492706fd6cec1ccf4d50ee5c59.png",
"website": "https://senseirobotics.com",
"all_locations": "Boston, MA, USA",
"long_description": "Sensei helps robotics companies scale and outsource their training data collection. Our hardware platform enables the collection of human-demonstration data at a tenth of the cost and twice the speed of current teleop approaches. Our software platform acts like Scale AI for robotics data: a large network of paid human operators use our low-cost collection platform to fulfill data-generation requests. ",
"one_liner": "Robotic Training Data at Scale",
"team_size": 2,
"industry": "Industrials",
"subindustry": "Industrials -> Manufacturing and Robotics",
"launched_at": 1724658554,
"tags": [
"Hard Tech",
"Marketplace",
"Robotics",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2024",
"status": "Active",
"industries": [
"Industrials",
"Manufacturing and Robotics"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/sensei",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2024/sensei.json",
"year_founded": 2024,
"city": "Boston",
"country": "US",
"linkedin_url": "",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/0e3e1067b2d9b0492706fd6cec1ccf4d50ee5c59.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Jared Friedman",
"url": "https://www.ycombinator.com/people/jared-friedman"
},
"founders": [
{
"user_id": 842573,
"full_name": "Anubhav Guha",
"title": "Founder/CEO",
"founder_bio": "CEO at Sensei - building the marketplace for robotic training data. Previously MIT Robotics PhD (dropped out) and Chief Engineer & Program Manager of Aurora Flight Science/Boeing's DARPA AlphaDogfight team. I've spent my whole career in robotics, and my goal is to help make AI robotics a reality.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/anubhav-guha-886445129/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9580bcefaa36422ee6b7c4f52ebab522fc7e6491.jpg"
},
{
"user_id": 2033335,
"full_name": "John Piotti",
"title": "Founder/CTO",
"founder_bio": "CTO at Sensei - scaling robotic training data collection to be 2x faster and 10x cheaper. Previously MIT '19, Robotics Engineer at Aurora Flight Science/Boeing, and full stack web development at UtilityAPI. Also building a house in my free time. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/john-piotti-51a67412a/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/16f9d0a34775f335bac9e0e7ac869194c2b0cd63.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 83555,
"title": "🦾 Sensei: Robotics training data, at scale.",
"tagline": "We produce high quantities of high-quality training data for robotics companies.",
"body": "**tl;dr:** [Sensei](https://senseirobotics.com/) is the Scale AI for robotics training data. Our platform collects human demonstration data at a tenth of the cost and twice the speed of current approaches.\n\n# **Our Team**\n\nWe are MIT engineers who have been friends since undergrad. We worked together at Aurora Flight Sciences, where we ran a DARPA-funded program to develop AI algorithms for autonomous fighter jet combat. [John](https://www.linkedin.com/in/john-piotti-51a67412a/) went on to spearhead the reinforcement learning efforts at Aurora, while [Anubhav](https://www.linkedin.com/in/anubhav-guha-886445129/) returned to MIT for a PhD focused on robotics, control theory, and machine learning (but dropped out to found Sensei!).\n\nWe have spent our careers working at the frontiers of robotics and AI. With Sensei, we plan to empower the expansion of those frontiers. \n\n\n\n# **The Problem**\n\n**Data scarcity is one of the biggest challenges in developing robotic artificial intelligence.** \n\nInnovators in the space are looking to apply the learnings from the Foundation Model Era: that large models trained on huge datasets are incredibly powerful. As researchers, engineers, and a rapidly growing number of commercial efforts race to develop large models for robotic intelligence, it’s become increasingly clear that the availability of sufficient quantities of quality data is the most significant bottleneck. \n\nCurrent solutions are slow, expensive, and fundamentally not scalable. Human demonstrations are the gold standard for training data. Robotics companies currently employ fleets of 5-20 data-collectors. These in-person contractors teleoperate a robot to perform hundreds of demonstrations a day - with tasks ranging from clothes folding, to bin sorting, to dishwasher loading. **This is not the right long-term solution:** \n\n* Large-scale collection is prohibitively expensive: a teleop setup requires a physical robot, often with a cost of $40,000+ per operational platform.\n* Low-quality data: restriction to labs/office spaces makes it hard to collect varied and realistic demonstrations\n* Slow data collection rates: non-intuitive interfaces, cumbersome equipment, and faulty hardware lead to slow demonstrations on platforms that break often.\n\n \n\nThese drawbacks make it impossible to scale quality training data collection to the quantities needed for robotics.\n\n# **Our Solution**\n\nWe design and manufacture low-cost and easy-to-use devices for collecting human demonstration data. Our platform costs less than $300 and can be used by anyone to collect high-quality training data. As seen in a clothes folding task that demonstrates our research prototype, the operator is equipped with a sensorized exoskeleton arm that closely matches the natural human range of motion. The intuitive design, coupled with a suite of angle, vision, and inertial sensors, enables the rapid collection of highly accurate visuo-spatial state information. \n\n\n\nOur main advantage is that an operator can easily set up and equip the platform, leading to an unprecedented ability to generate quality data at scale. Demonstrations can be performed for a broad range of common tasks, in a nearly infinite number of diverse settings, in as many different ways as human behavior is varied. \n\nIn order to maximally utilize a fleet of our data-collect platforms, we are building out and operating a network of Senseis— contractors that have been trained to collect high-quality training data using our devices. Our Senseis receive task descriptions from robotics researchers and engineers, and are then paid to collect demonstrations that fulfill the request. \n\n**Our combined hardware + software stack represents the first truly scalable solution to generating training data for AI robotics.**\n\n# **Our Goal**\n\nWithin the next five years, we envision tens of thousands of operators, equipped with increasingly sophisticated, portable, and effective data-collection arms, exoskeletons, headwear, and tools. These Senseis will be located all over the world, come from and live in a variety of environments, and all have different takes on what it means to perform tasks “like a human.” This is the best way to power data collection for improved robots, and it is the future we’re building.\n\n# **Ask**\n\nIf you’re interested in solving the data scarcity problem in robotics - either for yourself, your company, or your customers - we’d love to hear from you. You can reach us at [founders@senseirobotics.com](mailto:founders@senseirobotics.com)",
"url": "https://www.ycombinator.com/launches/Ljf-sensei-robotics-training-data-at-scale",
"votes": 112,
"created_at": "2024-08-28T20:27:10.260Z"
}
]
},
{
"id": 30101,
"name": "Kilvin",
"slug": "kilvin",
"former_names": [
"Chorrie",
"BrowserBook"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/b8aa78b8b96db85bb2ce800dc4eae6fc788564af.png",
"website": "https://www.kilvin.ai",
"all_locations": "New York City, NY, USA",
"long_description": "Kilvin is an AI-native agency that builds custom software solutions for non-technical teams.\r\n\r\nWith AI, the future of software is democratized. Every team deserves tools built exactly for them, not off-the-shelf SaaS products they need to adapt to. Kilvin makes it a reality, delivering a private, secure workspace of custom applications, built around your workflows and ready in days, not months.\r\n\r\nNo engineers needed on your side. Just software that fits exactly how you work.",
"one_liner": "Custom software for your business",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1731609344,
"tags": [
"Developer Tools",
"Productivity",
"Data Engineering",
"Automation",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Fall 2024",
"status": "Active",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/kilvin",
"api": "https://devasheeshg.github.io/yc-api/batches/fall-2024/kilvin.json",
"year_founded": 2024,
"city": "New York City",
"country": "US",
"linkedin_url": "https://linkedin.com/company/kilvin-ai/",
"x_url": "https://x.com/cschlaep",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/kilvin",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/b8aa78b8b96db85bb2ce800dc4eae6fc788564af.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/aa7393d468539a73caee6d9313b35b9881c2cab3.png"
],
"primary_partner": null,
"founders": [
{
"user_id": 739375,
"full_name": "Christopher Schlaepfer",
"title": "Founder/CEO",
"founder_bio": "Co-Founder and CEO of Kilvin. https://www.kilvin.ai",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/cschlaep/",
"x_url": "https://x.com/cschlaep",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/392cd705c1908c02f96668e38871dd3f2234f243.jpg"
},
{
"user_id": 1970548,
"full_name": "Jorrie Brettin",
"title": "Founder/CTO",
"founder_bio": "Co-Founder and CTO of Kilvin. https://www.kilvin.ai\n",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jorrie-brettin-349a6383/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/c28014416ede57d2fe39326db64b2cc5ff2da234.jpg"
}
],
"jobs": [
{
"id": 96213,
"title": "Senior Platform Engineer",
"url": "https://www.ycombinator.com/companies/kilvin/jobs/s3b5Le2-senior-platform-engineer",
"location": "New York, NY, US / Denver, CO, US / Philadelphia, PA, US / Remote (US)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$120K - $180K",
"equity_range": "0.01% - 1.00%",
"experience": "6+ years",
"visa": "US citizen/visa only",
"skills": [
"Git",
"Smalltalk",
"TypeScript",
"AI Agents"
]
},
{
"id": 100106,
"title": "Forward-Deployed Engineer",
"url": "https://www.ycombinator.com/companies/kilvin/jobs/5WEK19z-forward-deployed-engineer",
"location": "New York, NY, US / Philadelphia, PA, US / Denver, CO, US / Remote (US)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$120K - $180K",
"equity_range": "0.01% - 0.50%",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"Git",
"TypeScript",
"AI Agents"
]
}
],
"news": [],
"launches": [
{
"id": 96111,
"title": "BrowserBook - The Browser Automation IDE",
"tagline": "Write, run, and deploy reliable web automations in minutes, not hours",
"body": "Hey YC!\n\nWe’re [Chris](https://www.linkedin.com/in/cschlaep/) and [Jorrie](https://www.linkedin.com/in/jorrie/), cofounders of [BrowserBook](https://www.browserbook.com).\n\nhttps://youtu.be/FkaGHhJWy1w\n\n# **TLDR**\n\nWe make it trivial for developers to write reliable web automations.\n\n# **Ok, but _what is it?_**\n\nBrowserBook is an IDE that puts all the tools automators need in one place, so the iteration loop to write, test, debug, and deploy web automations is significantly reduced. It combines:\n\n* **A Jupyter-like coding environment** where developers can run code cells individually,\n* **An inline browser** to run automation code against\n* **A Playwright coding agent** that can write the automation for you\n* **A bunch of built-ins** for taking screenshots, extracting data, and authentication\n\nAnd, once you’re done writing your script, you can deploy it and trigger it via our public API. It’s super easy!\n\n# **But browser agents are a thing, right?**\n\nYes, and we’re not using them. We built BrowserBook because of the shortfalls we experienced with browser agents and the pain of actually writing reliable scripts. At a very high level, in the AI world you can take two approaches to web automation - write scripts, or use browser agents.\n\n1. **Use browser agents:** ostensibly more flexible, but expensive, slow, and unreliable\n2. **Write scripts:** fast and debuggable, but infamously brittle\n\nWhich leads us to…\n\n# **The problem (and how we got here)**\n\n**Sometimes we need machines to interact with web pages, which are made for humans.**\n\nThis is basically the whole challenge. There’s a lot of reasons we might want machines to poke around on the web:\n\n* Agents using a browser to interact with the web to perform actions like humans, especially when they can’t use APIs\n* Scrapers to gather data that’s useful for our business\n* UI tests that can interact with a website the way a human would to ensure everything’s working as intended\n* Workflow automation via RPA\n\nWe tried **browser agents** in our pre-pivot days to automate healthcare workflows. They mostly didn’t work; they were an order of magnitude more expensive than scripts, slow because of all the context they needed, and tended to drift when workflows got complex. When they did drift, fixing them was just tedious prompt-massage and trial-and-error.\n\nWe ended up giving the agent a library of scripts to execute, and came to realize scripting was simply the better solution for reliable enterprise workflows; they’re deterministic and therefore inherently debuggable, not to mention their cost and speed advantage. They with a host of issues though:\n\n* **Websites change often** causing scripts to break. We needed a way to quickly diagnose and iterate on our scripts.\n* **Setting up browser and filesystem infrastructure** is not easy but very necessary in the web automation world.\n* **It’s just annoying to write scripts** - if you’ve ever had to dig around for selectors, you know: it’s tedious and time consuming.\n\nSo we built BrowserBook to solve those issues.\n\n# **How does it work?**\n\n1. **Run code piecemeal** - if you’re fixing a breakage 2/3rds of the way through your script, you shouldn’t have to run the whole thing every time you test it. We took inspiration from Jupyter notebooks and allow you to run code cells independently, while maintaining context and state:\n\n \n\n2. **No more digging for selectors** - tell the coding assistant what to do and it’ll implement the automation logic in Playwright:\n\n \n\n3. **Built-ins for the hard stuff** - want to take a screenshot? Log in to a website with 2FA? Extract data? We’ve got built-ins for those, ready to go out-of-the-box.\n\n \n\n4. **Accessible via API** - if you need to execute your automation via an agent you’re building, scheduled via a cron job, or as a part of your application, you can trigger automations remotely and watch the playback in-app or via our artifacts API endpoint.\n\n \n\n\n# **Our ask**\n\nTry it out! If you:\n\n* Run browser automations\n* Are building agents that need to interact with the web\n* Need to write a one-off automation that will make your life easier\n\nBrowserBook is available for download for Mac users [on our website](https://browserbook.com/), and if you’d like you can [book a demo here](https://browserbook.com/demo).\n\nAdditionally, if you know individuals, startups, or teams at larger companies working on browser automations, we’d love to meet them!",
"url": "https://www.ycombinator.com/launches/P0B-browserbook-the-browser-automation-ide",
"votes": 74,
"created_at": "2025-12-10T15:55:19.861Z"
},
{
"id": 85580,
"title": "Chorrie: turn your SMEs into SWEs",
"tagline": "Catch errors in your manual processes before they cost you big",
"body": "# **TL;DR**\n\nWe supercharge your subject matter experts by giving them the tools they need to eliminate errors in heavily manual processes.\n\n**Our current mission:** empower healthcare practices to stop denials and under-billing on their claims before they happen.\n\n# **The Problem**\n\nHealthcare claims processing is an overly-complex, adversarial space. Insurance payers are constantly changing their policies, forcing billing teams to rely on:\n\n* frequent and extensive retraining\n* coding rules worksheets with hundreds of tabs\n* esoteric tribal knowledge\n\nWith so much room for human error, it’s no wonder 73% of healthcare staff surveyed reported that they’re facing increasing denials on outgoing claims.\n\n# **A turnkey solution for medical claims checks**\n\n[Here’s where Chorrie comes in.](https://youtu.be/orI95bsgaio)\n\nChorrie uses AI to empower medical practices to turn their esoteric knowledge into automated checks, saving time, money, and mental effort. We take simple, deterministic instructions, and translate them into a code-based decision tree, which can be continuously run to automate correctness checks for complex rules systems.\n\nTake the example in our video: we get a glimpse at how extensive these rules worksheets can become today, and see how quick & easy it is to automate a rule for claims from a particular location, containing a particular code, billed to a particular insurance payer with Chorrie.\n\n# **Backstops-as-a-service**\n\nOur approach of plaintext ➡️ decision tree ➡️ code generation is a scalable technique that can be used to provide backstop checks (and ultimately automate) high-leverage, deterministic manual processes that are prone to human error (think contract review for legal documents, trade confirmations, etc.).\n\nTo automate checks for these today, you’d need a team of engineers to write the logic into code, and keep them on staff to ensure that code can be updated when the rules change. **With Chorrie, you get:**\n\n* A no-code solution: turn your SMEs into SWEs\n* No hallucinations in your automated workflows\n* Intrinsically deterministic & fully explainable conclusions\n\nWhile the focus today is on reducing claims denials to 0% for our healthcare clients, we plan to explore use cases in other fields in the future.\n\n# **About us**\n\nWe are Chris (the **Ch**) and Jorrie (the **orrie**), old friends who met in undergrad at MIT. We met back up years later at Google, where we worked on applied AI for content moderation before we decided it was time to move onto something new.\n\n\n\nAfter brainstorming on a number of projects, Jorrie’s wife, an ophthalmologist, gave us the idea of applying AI to the medical coding world and the rest is history!\n\n# **Our ask**\n\nDo you have any tedious or high-leverage manual processes where errors can cost your business money (Think heavy manual review processes, major transactions that need to be verified, etc.)? Or any contacts in the medical billing world? We’d love to chat.\n\n📧 [**founders@chorrie.com**](https://mailto:founders@chorrie.com)",
"url": "https://www.ycombinator.com/launches/MGK-chorrie-turn-your-smes-into-swes",
"votes": 80,
"created_at": "2024-11-14T22:58:45.072Z"
}
]
},
{
"id": 30113,
"name": "Melder",
"slug": "melder",
"former_names": [
"Echo"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/78670a3e0cef588e19eb8b9dd11bc151ceac64fa.png",
"website": "https://melder.io",
"all_locations": "New York City, NY, USA",
"long_description": "Melder is an Excel add-in that brings AI functions and document support into your spreadsheets. Upload files directly into cells, use smart formulas like =GEN, and build automations—all without leaving Excel.\r\n\r\nCore features:\r\n- File-to-Sheet: Drop PDFs directly into cells, then reference them in formulas.\r\n- AI-Powered Functions: Write formulas like =GEN() or =EXTRACT() to summarize, classify, and analyze content.\r\n- Chat Assistant: Use our AI assistant to help build your sheets or answer questions from your data, live in the workbook.\r\n\r\nBusiness users use Melder to:\r\n- Accelerate diligence by extracting insights from data rooms\r\n- Review contracts by identifying key terms and clauses instantly\r\n- Run market research by pulling information from competitor websites\r\n- Synthesize transcripts by generating summaries from interviews and calls\r\n\r\nMelder brings the power of structured spreadsheet logic to the messy, unstructured data world—no coding needed.",
"one_liner": "AI formulas and document support for Microsoft Excel",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Productivity",
"launched_at": 1731437113,
"tags": [
"Generative AI",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Fall 2024",
"status": "Active",
"industries": [
"B2B",
"Productivity"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/melder",
"api": "https://devasheeshg.github.io/yc-api/batches/fall-2024/melder.json",
"year_founded": 2024,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/melderai/",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/78670a3e0cef588e19eb8b9dd11bc151ceac64fa.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Diana Hu",
"url": "https://www.ycombinator.com/people/diana-hu"
},
"founders": [
{
"user_id": 810767,
"full_name": "Ashwin Dharne",
"title": "Founder",
"founder_bio": "Building AI for Excel. Ex-Google security + cloud conversational AI.\n",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ashwindharne/",
"x_url": "https://x.com/AshwinDharne",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/24d0630d7533066d4548cc5cfbd4c5beb393c3b8.jpg"
},
{
"user_id": 2244698,
"full_name": "Philip Brewer",
"title": "Founder",
"founder_bio": "Building the 'Excel for unstructured data'\n\nEx-Bain Consultant | Indiana University | Amateur Improv Comedy Player",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/philip-brewer/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ab8d7c78a73bdd7034215538a70453a0469a5e0b.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 90861,
"title": "Melder - Excel just got an AI upgrade",
"tagline": "Melder is an Excel add-in that adds AI formulas for PDF extraction, web scraping, and text processing - all with full citations.",
"body": "Hey everyone! We're [Ashwin](https://www.linkedin.com/in/ashwindharne/) and [Phil](https://www.linkedin.com/in/philip-brewer/) and we’re building [Melder](https://melder.io), an AI add-in for Excel.\n\n# **TL;DR**\n\nMelder is an add-in that brings AI formulas, file upload, and web scraping to Excel, so finance and ops teams can work faster without changing their existing workflow. One-click install and deploy from the Microsoft add-in store.\n\n[Launch Video](https://www.youtube.com/watch?v=Ao3SjOFeW5A)\n\n# **❌ Problem**\n\nFinance and ops teams spend too much time:\n\n* Pulling data from earnings calls, investor presentations, and transaction documents\n* Researching competitors one website at a time\n* Aggregating insights from interview transcripts and reports\n\nTeams want to automate these tasks, but every AI solution requires learning new tools and changing existing workflows.\n\n# **✅ Solution**\n\nWe built AI capabilities directly into the tool finance and ops teams already use every day: Excel.\n\n**Some things teams can do with Melder:**\n\n* **Turn PDFs into structured data**: Upload contracts, invoices, or reports directly to cells. Extract what's needed in seconds.\n* **Scrape the web with a formula**: Pull any website's contents into Excel. Research 100 competitors as easily as one.\n* **Analyze qualitative data**: Turn customer feedback, survey responses, or support tickets into structured insights\n\nYour team already knows Excel. No training needed, no new logins to manage, deploy instantly across Office 365 licenses. It's AI that fits existing workflows, not the other way around.\n\n# **🙌 Our Ask**\n\n* **Try it free**: Install directly from [Microsoft](https://appsource.microsoft.com/en-us/product/office/WA200008575?tab=Overview) (takes 30 seconds, no commitment)\n* **See it in action**: Book a call directly: https://cal.com/phil-brewer/chat\n\n\n\n",
"url": "https://www.ycombinator.com/launches/NdV-melder-excel-just-got-an-ai-upgrade",
"votes": 13,
"created_at": "2025-05-29T19:53:10.558Z"
}
]
},
{
"id": 30286,
"name": "Nitrode",
"slug": "nitrode",
"former_names": [
"Roach AI",
"Inception Technologies"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/514545bed169ad1eb626571d7e0d77375b33f656.png",
"website": "https://www.nitrode.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "Nitrode is a research company focused on improving game development with AI. To advance game development, we believe AI models firstly need to be judged against robust evaluation frameworks that reflect the actual complexity of the field.\r\n",
"one_liner": "Frontier AI research to advance game development",
"team_size": 8,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1738144366,
"tags": [
"Machine Learning",
"B2B",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Winter 2025",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/nitrode",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2025/nitrode.json",
"year_founded": 2024,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/nitrode",
"x_url": "https://x.com/NitrodeResearch",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/514545bed169ad1eb626571d7e0d77375b33f656.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": null,
"founders": [
{
"user_id": 1654263,
"full_name": "Ben Kim",
"title": "Founder/CEO",
"founder_bio": "Co-founder at Nitrode. InfoSci @ Cornell. Previously @Supercell AI Lab, and @WSGR",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ben-yoonsung-kim/",
"x_url": "https://x.com/ysungkim_",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/a5878f4fe3ac86da75a818f47a588a531d134b4b.jpg"
},
{
"user_id": 1654842,
"full_name": "Sejoon Chang",
"title": "Founder/COO",
"founder_bio": "Co-founder at Nitrode. CS & Product Design @ Stanford. Top 500 GeoGuessr globally in moving and builder of unnecessarily ambitious Minecraft cities.",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/sejoonchang",
"x_url": "https://x.com/sejoonchang",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/d96b7380c521c01891b3d1b496f8b4a1347e2fc2.jpg"
},
{
"user_id": 1654330,
"full_name": "Brian La",
"title": "Founder/CTO",
"founder_bio": "Co-founder at Nitrode. CS @ Cornell. Previously Data Scientist @ Nexon",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/brianyla",
"x_url": "https://x.com/BrianLa0616",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/6d63c684f51d17016bfd7ad010bb0b3fb1face7d.jpg"
}
],
"jobs": [
{
"id": 98321,
"title": "Member of Technical Staff (Post-Training) ",
"url": "https://www.ycombinator.com/companies/nitrode/jobs/flMnYGU-member-of-technical-staff-post-training",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Data science",
"salary_range": "$150K - $350K",
"equity_range": "1.00% - 3.00%",
"experience": "1+ years",
"visa": "US citizen/visa only",
"skills": [
"C++",
"Python",
"Distributed Systems",
"Reinforcement learning (RL)",
"Natural Language Processing",
"CUDA",
"Data Analytics"
]
},
{
"id": 98322,
"title": "Member of Technical Staff (Evals)",
"url": "https://www.ycombinator.com/companies/nitrode/jobs/BrIHVMH-member-of-technical-staff-evals",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Data science",
"salary_range": "$120K - $250K",
"equity_range": "1.00% - 3.00%",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": [
"Amazon Web Services (AWS)",
"C++",
"Java",
"Python",
"Torch/PyTorch",
"Machine Learning",
"Reinforcement learning (RL)"
]
},
{
"id": 98323,
"title": "Full-Stack Engineer",
"url": "https://www.ycombinator.com/companies/nitrode/jobs/Hpc1xDj-full-stack-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$110K - $160K",
"equity_range": "0.50% - 2.00%",
"experience": "Any (new grads ok)",
"visa": "US citizen/visa only",
"skills": [
"C++",
"Java",
"JavaScript",
"Python"
]
},
{
"id": 110036,
"title": "Game Developer ",
"url": "https://www.ycombinator.com/companies/nitrode/jobs/KZbQlmq-game-developer",
"location": "San Francisco, CA, US / Remote (US)",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$95K - $145K",
"equity_range": "",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"Unreal Engine",
"Unity",
"Blender"
]
}
],
"news": [],
"launches": [
{
"id": 104921,
"title": "Nitrode - Advancing AI for Game Development",
"tagline": "Advancing game development through frontier AI research.",
"body": "Hey YC,\n\nWe’re Ben, Brian, and Sejoon from **Nitrode.**\n\nNitrode is a research company focused on improving game development with AI. \n\n**The Problem - How do we advance game development with AI?**\n\nWe started by building an AI game engine. It got to [**#3 on Product Hunt**,](https://www.producthunt.com/products/nitrode-ai-game-engine) and we gained several useful insights: despite recent progress in agentic coding, game development remains uniquely difficult for AI models because it requires **(1) strong spatial reasoning**, **(2) reliable tool use/tool-calling**, **(3) strong agentic coding capabilities** and the **(4) ability to operate in real-time environments for complex games**.\n\n**The Solution** \n\nTo advance game development, we believe AI models firstly need to be judged against robust evaluation frameworks that reflect the **actual complexity of the field.** Over the coming months, Nitrode will open-source a suite of benchmarks designed to measure where AI models truly stand in game development. Our first benchmark, [**GameEngineBench**,](https://arxiv.org/abs/2607.03525) evaluates agentic coding performance on C++ game engine tasks in real runtime environments.\n\n\n\nOur results are clear: model class and reasoning effort are strong predictors of performance, while model rankings align more closely with spatial reasoning benchmarks than with traditional agentic coding benchmarks. **This suggests that game development is fundamentally different from pure coding.** Success requires not only writing correct code, but also understanding space, tools, runtime behavior, and the interaction between systems.\n\nWe also observe significant complementarity across frontier models, indicating that different models exhibit distinct strengths within the game development task space. Mythos/Fable-class models point toward a potential step change in AI game development capability, where improved spatial understanding and stronger tool use combine to produce emergent behaviors that older model generations struggle to match.\n\nOur benchmark has revealed clear model-specific performance gaps across game development tasks, with outcomes that diverge meaningfully from standard agentic coding benchmarks.\n\nWe are also building [Mint](http://mint.nitrode.com), a platform that onboards game development experts to work on custom datasets. Think engine programmers, technical artists, and developers with years of enterprise/indie game development experience. We already have hundreds of contributors across game development and creative software. Whenever you need a certain type of data, we construct and lead a team to produce:\n\n* Post-training /SFT data captured from real workflows: how developers actually build, debug, test, and iterate inside engines and creative tools.\n* RL environments and executable tasks where models learn through execution and feedback.\n* Custom benchmarks and post-training for gaming enterprises: we pinpoint where models fail on real game development tasks, then post-train a custom model to close those gaps.\n\n**Team** \n\nBen and Brian studied Information Science and Computer Science at Cornell, while Sejoon studied Computer Science and Product Design at Stanford. The trio has been building things together for the last six years, from a sports team analytics tool to Nitrode, and are, unsurprisingly, massive gaming nerds. Sejoon is top 400 in the world at moving GeoGuessr and a certified Civ sweat, Brian is ranked in Tetris, and Ben used to be ranked in Minecraft speedrunning.\n\n**Our Ask:**\n\n1. If you need custom datasets or evals, let us know! Email us [research@nitrode.com](mailto:research@nitrode.com)\n2. Are there any creative or gaming companies you could introduce us to?\n\n**Thank you!**",
"url": "https://www.ycombinator.com/launches/RIH-nitrode-advancing-ai-for-game-development",
"votes": 10,
"created_at": "2026-07-07T15:17:58.603Z"
}
]
},
{
"id": 30542,
"name": "Linewise",
"slug": "linewise",
"former_names": [
"Comply Genie",
"Vision Nexus",
"LineWise",
"Vision Lab"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/2b6523fd3e82e786169b750e69bb81160c422bc6.png",
"website": "https://linewise.io/",
"all_locations": "San Francisco, CA, USA",
"long_description": "We capture how physical things are made, from the first design to the final assembly, and turn it into training data for frontier AI and robotics models.",
"one_liner": "Industrial data layer for physical RSI",
"team_size": 25,
"industry": "Industrials",
"subindustry": "Industrials -> Manufacturing and Robotics",
"launched_at": 1743036496,
"tags": [
"Robotics",
"Manufacturing",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Spring 2025",
"status": "Active",
"industries": [
"Industrials",
"Manufacturing and Robotics"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/linewise",
"api": "https://devasheeshg.github.io/yc-api/batches/spring-2025/linewise.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/linewise-ai/",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/2b6523fd3e82e786169b750e69bb81160c422bc6.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/27f8fa04b65e99bdb2ebabb86e73fd71f35f9bb5.png",
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/35658d6d055e51d7f572f0d0813d8eb3a9b7bf76.png"
],
"primary_partner": {
"name": "Tom Blomfield",
"url": "https://www.ycombinator.com/people/tom-blomfield"
},
"founders": [
{
"user_id": 2371704,
"full_name": "Tanachart (James) Kujareevanich",
"title": "Founder/CEO",
"founder_bio": "James is the co-founder and CEO at Vision Lab. MBA from MIT. Former McKinsey Ops consultant.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/tanachartkujareevanich/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/a51605bd53380345564966573f52709d42356d3c.jpg"
},
{
"user_id": 2373140,
"full_name": "Zhichu Ren",
"title": "Founder/CTO",
"founder_bio": "Zhichu is the co-founder and CTO at Linewise. MIT PhD. Built robotics automation for materials research.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/zhichu-ren/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/98ef468f54a1e6b309dcae7ccfd3531eacb003e8.jpg"
},
{
"user_id": 2547908,
"full_name": "Will Wenbo Zhang",
"title": "Founder/CPO",
"founder_bio": "Will is the co-founder and CPO at Linewise. MSE in AI & Robotics at UPenn GRASP Lab. Former founding engineer at Greyscale AI and Bestmow.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/wenbo-zhang6",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/dae0fb87a14c53d5de2764acef1e34263c5c100a.jpg"
}
],
"jobs": [],
"news": [
{
"title": "Vision lab raises $6m to bring real-world factory data to robotics foundation models · vision lab",
"url": "https://thevisionlab.ai/articles/seed-2026",
"date": "Jun 15, 2026"
},
{
"title": "Race Capital - Our Investment in Vision Lab: The Industrial Data Layer for Physical AI",
"url": "https://race.capital/blog/our-investment-in-vision-lab-the-industrial-data-layer-for-physical-ai",
"date": "Jun 15, 2026"
}
],
"launches": [
{
"id": 99007,
"title": "Vision Lab: The Industrial Data Layer for Robotics",
"tagline": "Aggregating the Largest Manufacturing Process Data for Robotics Training",
"body": "## **TL;DR**\n\nWe capture and structure real factory workflows at scale, pairing first-person industrial video with SOP-level process knowledge, so robotics and AI labs can train models on the data that actually exists inside production environments, not just lab demos. We are already working with 2 frontier AI labs.\n\n🎥 **Our 60-second Product Launch**:\\\n\n\n## **THE PROBLEM**\n\nThe robotics industry is being trained mostly on lab demos, even though robots will ultimately need to operate in messy, high-variance real factories. The industry has **less than 0.3% of the data it needs**, and almost none of it comes from real factory environments.\n\nWhy?\n\n**Industrial data does not exist at scale**\\\nIt cannot be scraped or passively collected. It has to be captured inside real factories, on real production lines, during real operations.\n\n**Raw footage is not enough**\\\nUnstructured industrial video is noise. Models need process context: what step is happening, in what order, with what tools, and whether it was done correctly.\n\n**Crowdsourcing cannot solve it**\\\nUnderstanding industrial actions requires factory expertise. Anyone can label an object; far fewer can distinguish whether a torque check, weld, inspection, or setup sequence was performed correctly.\n\n---\n\n## **THE SOLUTION**\n\nVision Lab solves the industrial data problem by building:\n\n**The most diverse industrial dataset**\\\nSOP-structured production data spanning cutting-edge environments like biotech, EV manufacturing, semiconductors, and medical devices, as well as large-scale manufacturing.\n\n**Industrial access at scale**\\\nA network of **2,000+ factories across 50+ industries in 27 countries**, with operators and factory owners embedded in the capture process so every sequence, tool, and technique is recorded correctly at the source.\n\n**A proprietary VLM for industrial settings**\\\nA temporal VLM trained on SOP-paired industrial footage to understand not just what is happening, but the **order, timing, and correctness** of real industrial processes. Our state-of-the-art VLM outperforms Gemini by **2.5x on temporal understanding in industrial settings**.\n\n---\n\n## **PARTNER WITH US**\n\nIf you believe the next decade of robotics and world models will depend on **real-world industrial data, not just compute**, we’d love to talk.\n\nVision Lab partners with robotics labs, frontier AI teams, and manufacturers to build the default industrial data layer for robotics.\n\n**Contact:** [founders@thevisionlab.ai](mailto:founders@thevisionlab.ai)\\\n**More info**: [www.thevisionlab.ai](http://www.thevisionlab.ai)\n\n\n\n",
"url": "https://www.ycombinator.com/launches/Pkt-vision-lab-the-industrial-data-layer-for-robotics",
"votes": 18,
"created_at": "2026-03-23T17:15:21.041Z"
},
{
"id": 90196,
"title": "LineWise - AI Copilot for Manufacturers",
"tagline": "AI that troubleshoots your production line",
"body": "### **TL;DR**\n\nLineWise is building an AI assistant for manufacturing teams to get their production lines back up and running - fast.\n\nWe connect siloed factory data (PLCs, maintenance logs, manuals) to triage faults, guide technicians to fixes, and capture every resolution for smarter troubleshooting in the future.\n\n🎥 **Our 60-second Product Launch:\\\n[https://youtu.be/DfnmQ4k8q-k](https://youtu.be/DfnmQ4k8q-k)**\n\n### **THE PROBLEM**\n\nWhen a line goes down, it can take **hours** to identify the problem. Engineers and technicians chase PLC logs, flip through outdated manuals, and rely on the one person who “just knows.” While production stalls, tribal knowledge disappears, and the same issues repeat.\n\n### **THE SOLUTION**\n\nLineWise centralizes critical knowledge by integrating siloed data from IoT sensors, maintenance records, and machine manuals. It ranks the most likely causes and guides the team to a fix in just **minutes**. But the best part? It remembers every issue for next time and advocates for preventative actions.\n\n---\n\n### **How LineWise Works**\n\n🔧 Upload an error code image or describe the issue in a message.\n\n🤖 The AI provides a refocused problem statement for confirmation.\n\n📊 The AI dynamically ranks possible hypotheses of causes by probability.\n\n🧠 A human validates each hypothesis to identify the true cause.\n\n🛠️ Resolve the issue by following a step-by-step guide.\n\n🔍 Conduct further investigation to uncover the root cause.\n\n📚 Enrich the knowledge base with insights from the issue and resolution.\n\n---\n\n### **Join Us to Revolutionize Manufacturing**\n\nLineWise partners with forward-thinking manufacturers to minimize unplanned downtime, empower frontline teams, and unlock the value of siloed data within a company. \n\nIf that sounds like you, we’d love to talk.\n\n🔧 **Want to see LineWise in action?** Contact: [info@linewise.io](mailto:info@linewise.io)\n\n\n\n",
"url": "https://www.ycombinator.com/launches/NSm-linewise-ai-copilot-for-manufacturers",
"votes": 37,
"created_at": "2025-05-07T23:13:06.095Z"
}
]
},
{
"id": 30552,
"name": "sieve",
"slug": "sieveai",
"former_names": [
"Sieve"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/459d63741f9af0815baebb98ab6c243158d589c2.png",
"website": "https://usesieve.com/",
"all_locations": "New York City, NY, USA",
"long_description": "sieve solves data cleaning for hedge funds and investment firms by letting them get clean data in four lines of code. Currently, their data pipelines have conditions that raise for human review, which literally send an email to engineers with data that needs to be reviewed. We provide an API that integrates directly into their existing pipeline - instead of raising for human review, they can send all the same information to our API and get clean, high-quality data back.\r\n\r\nBy using our AI agents built specifically for financial data collection, along with expert-in-the-loop review, we provide our clients with clean, validated data at a scale and level of quality that wasn't achievable before.",
"one_liner": "AI + human review to solve data cleaning - accessible via API or Excel",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Finance and Accounting",
"launched_at": 1747624073,
"tags": [
"Investing",
"Data Engineering",
"APIs"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Spring 2025",
"status": "Active",
"industries": [
"B2B",
"Finance and Accounting"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/sieveai",
"api": "https://devasheeshg.github.io/yc-api/batches/spring-2025/sieveai.json",
"year_founded": 2025,
"city": "New York City",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/usesieve",
"x_url": "https://x.com/usesieve",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/459d63741f9af0815baebb98ab6c243158d589c2.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Tom Blomfield",
"url": "https://www.ycombinator.com/people/tom-blomfield"
},
"founders": [
{
"user_id": 1591478,
"full_name": "Nicole Lu",
"title": "Founder/CEO",
"founder_bio": "Nicole is co-founder and CEO of sieve, which is solving data cleaning for hedge funds and investment firms. She previously worked at Citadel across Equity Quant Research, Global Trading, and Data Science groups, was a management consultant at McKinsey, and developed cancer detection algorithms at the Broad Institute.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/lu-nicole/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/8afeb7c737351a294c8a72c2510ef4df86a819d9.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 90521,
"title": "sieve helps hedge funds extract and clean data from any source directly into their existing tools",
"tagline": "Focus on differentiated analyses and never think about data cleaning again",
"body": "**The problem**\n\nRight now, the most sophisticated hedge funds pay over-qualified data engineers to spend hours a day on the under-levered task of data cleaning. It's crazy to anyone outside of the industry, but in finance even earnings dates (the date a company reports earnings) are considered **a known hard problem.**\n\nhttps://youtu.be/V-OpzDRge3o\n\n**Our ask**\n\nWe've solved this problem and our ask to the YC community is - **connect us with anyone you know who works in the investing world and uses data (should be all of them).** You can email us at [founders@usesieve.com](mailto:nicole@usesieve.com).\n\n**Who we are**\n\nAfter studying CS at MIT, I worked at Citadel and McKinsey, and Savannah worked at Bain. We've dealt with this problem first hand and were amazed that there weren't good solutions.\n\n**What we've built**\n\nsieve lets hedge funds replace manual review in their data pipelines with a simple API call, so their engineers and analysts can get back to more differentiated work. Behind the scenes, we use AI to find and retrieve the appropriate source documents and to extract the requested data. Each data point is reviewed by a team of expert reviewers before being returned to the client. This lets us achieve the level of accuracy hedge funds need, and that AI-only approaches aren't able to achieve.\n\nWe offer direct API access and access via other tools like Excel. Watch below to see how the excel integration works!\n\n[**https://youtu.be/r6A1t_X2kZo**](https://youtu.be/r6A1t_X2kZo)\n\n**What the early results look like**\n\n* sieve is able to replace manual data cleaning workflows:\n * accurately (100% match to data that was hand-collected internally)\n * more scalably (weeks of full-time work to review data became a passive background task for the data scientist)\n * more cheaply (easily 60-70% cheaper than existing options, even when that existing option is BPO outsourcing)\n\nIn our first week of YC, we were told that we need to be at least one of: better, faster, or cheaper.\n\n\n\n\n\n",
"url": "https://www.ycombinator.com/launches/NY1-sieve-helps-hedge-funds-extract-and-clean-data-from-any-source-directly-into-their-existing-tools",
"votes": 83,
"created_at": "2025-05-19T15:16:31.617Z"
}
]
},
{
"id": 30602,
"name": "Meteor Labs",
"slug": "meteor-labs",
"former_names": [
"Meteor"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/463b3d216b98b96d985f820caa0a09e2c3c9ee44.png",
"website": "https://meteorlabs.ai",
"all_locations": "San Francisco, CA, USA",
"long_description": "Meteor Labs is a research company focused on providing a granular view of the data center supply chain.\r\n\r\nWe track upstream of the major data center buildout to understand the OEMs winning the market, the bottlenecks, and supply chain links.\r\n\r\nOur expertise in browser agents and AI helps us source this information from esoteric public filings across the web.",
"one_liner": "We provide hedge funds with information they can trade on",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1754469732,
"tags": [
"Big Data",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2025",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/meteor-labs",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2025/meteor-labs.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/meteorlabsai",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/463b3d216b98b96d985f820caa0a09e2c3c9ee44.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Tyler Bosmeny",
"url": "https://www.ycombinator.com/people/tyler-bosmeny"
},
"founders": [
{
"user_id": 1531197,
"full_name": "Pranav Madhukar",
"title": "Founder/CEO",
"founder_bio": "Finding valuable information from the public web at meteorlabs.ai. NSF-funded math at UChicago. FOIA nerd. Browser agent research.\n\nPrev CS @ UW where I built viral tools on campus and then raised $150k in university funding to encourage builders. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/pranav-madhukar-pcm/",
"x_url": "https://x.com/pranavcmadhukar",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/f6967d5795c9b074e9b14a134e4ce951d3159e0c.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 92864,
"title": "Meteor Labs",
"tagline": "A Browser that gets things done, on your behalf.",
"body": "Hey everyone! 👋\n\nWe’re Pranav and Farhan – co-founders of Meteor Labs. And we’re on a mission to kill Google Chrome.\n\nMeteor is a browser that can do work on your behalf.\n\nDownload now: [www.browse.dev](http://www.browse.dev)\n\n# **The Problem**\n\nWe spend several hours each day on our browser doing boring, repetitive tasks. Sending out calendar invites, filling up repetitive forms, moving data from one website to another, creating spreadsheets etc.\n\n# **Introducing Meteor**\n\nMeteor is an agentic browser – our agents can perform tasks for you.\n\nManually setting up calendar invites? Just ask Meteor.\n\nSearching through dozens of websites to find the best price? Just ask Meteor.\n\nConfused how to configure your S3 Bucket? Just ask Meteor.\n\nMeteor is your very own personal assistant. Enhanced by your browser context.\n\n\n\n# **The Journey**\n\nPranav and Farhan met during orientation week at UW, and now we’re both dropped out of UW to build the future of browsing.\n\nA few weeks into our batch, we decided to fork Chromium (30M+ lines of code!) and rebuild our entire product from scratch. Simply compiling an instance of Chromium takes 8+ hours and over 200GB of disk space. 3 weeks later we are excited to launch our browser!\n\nPranav (CEO) previously built viral projects used by over thousands of students at the UW, and raised over $100k in university funding.\n\nFarhan (CTO) previously built an IDE for hardware design that compiles 60x faster than the industry standard.\n\n\n\n",
"url": "https://www.ycombinator.com/launches/O9o-meteor-labs",
"votes": 38,
"created_at": "2025-08-10T01:28:18.337Z"
}
]
},
{
"id": 30662,
"name": "DeepAware AI (Robotics Center of Silicon Valley)",
"slug": "deepaware-ai-robotics-center-of-silicon-valley",
"former_names": [
"DeepAware AI"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/b55e7c4492211c3d35247562da291230d55e6cdb.png",
"website": "https://roboticscenter.ai/",
"all_locations": "San Francisco, CA, USA",
"long_description": "DeepAware (Robotics Center of Silicon Valley, https://roboticscenter.ai/) is the fastest way for enterprises and researchers to get robots and robotics parts in the US — 72-hour delivery or Bay Area pickup.\r\n\r\nBeyond hardware, we help teams collect teleoperation data, build reinforcement learning environments, and deploy robots into production. Customers include AI labs, industrial operations, research teams, and event producers.",
"one_liner": "Robots, parts & RL envs & evals - delivered in 48 hrs / pickup in SF.",
"team_size": 4,
"industry": "Industrials",
"subindustry": "Industrials -> Manufacturing and Robotics",
"launched_at": 1753029704,
"tags": [
"Machine Learning",
"Robotics",
"Supply Chain",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Summer 2025",
"status": "Active",
"industries": [
"Industrials",
"Manufacturing and Robotics"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/deepaware-ai-robotics-center-of-silicon-valley",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2025/deepaware-ai-robotics-center-of-silicon-valley.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/roboticscenter/",
"x_url": "https://x.com/RoboticsCtr",
"fb_url": "https://www.facebook.com/roboticscenterai",
"cb_url": "https://www.crunchbase.com/organization/deepaware-ai",
"github_url": "https://github.com/roboticscenter",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/b55e7c4492211c3d35247562da291230d55e6cdb.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Ankit Gupta",
"url": "https://www.ycombinator.com/people/ankit-gupta"
},
"founders": [
{
"user_id": 2760576,
"full_name": "Jerry Huang",
"title": "Founder/CEO",
"founder_bio": "Building Robotics Center of Silicon Valley https://roboticscenter.ai/",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/jerryh01/",
"x_url": "https://x.com/jerryhuang01",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/1a1c665b9491d7b3b0b21fc7085627a6859b1b85.jpg"
},
{
"user_id": 2786524,
"full_name": "Stela Tong",
"title": "Founder/CTO",
"founder_bio": "Building DeepAware AI",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/stela-tong-a2583110b/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/eec06f27921ccffb2a5407cb05d034193102259a.jpg"
}
],
"jobs": [
{
"id": 79914,
"title": "Business Development Associate ",
"url": "https://www.ycombinator.com/companies/deepaware-ai-robotics-center-of-silicon-valley/jobs/Oz49Id3-business-development-associate",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Sales",
"role_type": null,
"salary_range": "$50K - $100K",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "Will sponsor",
"skills": []
},
{
"id": 79915,
"title": "Robotics Engineer",
"url": "https://www.ycombinator.com/companies/deepaware-ai-robotics-center-of-silicon-valley/jobs/2PyKMig-robotics-engineer",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Engineering",
"role_type": "Robotics",
"salary_range": "$80K - $180K",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "Will sponsor",
"skills": []
},
{
"id": 99767,
"title": "Operations Associate",
"url": "https://www.ycombinator.com/companies/deepaware-ai-robotics-center-of-silicon-valley/jobs/iyyRVWT-operations-associate",
"location": "San Francisco, CA, US",
"type": "Full-time",
"role": "Operations",
"role_type": null,
"salary_range": "$50K - $100K",
"equity_range": "",
"experience": "Any (new grads ok)",
"visa": "Will sponsor",
"skills": []
},
{
"id": 100904,
"title": "Business Development Intern",
"url": "https://www.ycombinator.com/companies/deepaware-ai-robotics-center-of-silicon-valley/jobs/a9Gr7BR-business-development-intern",
"location": "San Francisco, CA, US",
"type": "Internship",
"role": "Sales",
"role_type": null,
"salary_range": "",
"equity_range": "",
"experience": null,
"visa": "Will sponsor",
"skills": []
},
{
"id": 100905,
"title": "Robotics Engineer Intern",
"url": "https://www.ycombinator.com/companies/deepaware-ai-robotics-center-of-silicon-valley/jobs/extm5EN-robotics-engineer-intern",
"location": "San Francisco, CA, US",
"type": "Internship",
"role": "Engineering",
"role_type": "Robotics",
"salary_range": "",
"equity_range": "",
"experience": null,
"visa": "Will sponsor",
"skills": []
},
{
"id": 100906,
"title": "Operations Intern",
"url": "https://www.ycombinator.com/companies/deepaware-ai-robotics-center-of-silicon-valley/jobs/o5YcLop-operations-intern",
"location": "San Francisco, CA, US",
"type": "Internship",
"role": "Operations",
"role_type": null,
"salary_range": "",
"equity_range": "",
"experience": null,
"visa": "Will sponsor",
"skills": []
},
{
"id": 102117,
"title": "Marketing Intern",
"url": "https://www.ycombinator.com/companies/deepaware-ai-robotics-center-of-silicon-valley/jobs/PHQdrZy-marketing-intern",
"location": "San Francisco, CA, US",
"type": "Internship",
"role": "Marketing",
"role_type": null,
"salary_range": "",
"equity_range": "",
"experience": null,
"visa": "Will sponsor",
"skills": []
}
],
"news": [],
"launches": [
{
"id": 92985,
"title": "DeepAware - Automation for next-gen AI data centers",
"tagline": "AI-driven automation that makes any data center as secure, efficient, and adaptive as Google’s or Amazon’s.",
"body": "## **DeepAware - Automation for next-gen AI data centers**\n\n👋 Hello world! Are you ready to embrace a much more efficient AI infrastructure? Check out [DeepAware](http://deepawareai.com/) / [LinkedIn](https://www.linkedin.com/company/deepaware/):\n\nhttps://youtu.be/mywozPhOAnA\n\nTL;DR\n\n1. DeepAware AI brings Google- and Amazon-level technology to any data center, making them more secure, efficient, and autonomous.\n2. Our reinforcement learning scheduler, real-time market integration, and robotics cut energy waste by up to 30% while ensuring 24/7 uptime.\n\n\n\n**Problem**\n\n1. With AI workloads surging, the data center industry is booming—global capacity is expanding rapidly, and the market is projected to hit **$1 trillion by 2030**\n2. Data centers waste 20–30% of energy due to siloed tooling and manual controls.\n3. Hyperscalers like Google and Amazon solve this with custom AI, but mid-market operators lack access to those technologies.\n\n\n\n**Solution**\\\nDeepAware brings Google- and Amazon-grade AI controls to any data center:\n\n1. **RL Scheduler** optimizes GPU workload placement for power, performance, and cost.\n2. **Real-Time Market Integration** shifts workloads to low-price windows and supports demand-response programs.\n3. **Unified Dashboard** for one-click policy tuning, automated alerts, and “what-if” scenario testing.\n4. **Autonomous Robotics (coming soon)** for remote “robot hand” inspections, cable swaps, and maintenance—enabling 24/7 physical operations with minimal on-site staff.\n\n\n\n**Our Team:** \n\n1. We are both second-time founders. We spent 3 years together building our first company providing second-level energy optimization for dozens of factory.\n\n**Traction:**\n\n1. **6-digit agreement** with a major 30 MW+ data center operator to use our system.\n2. **Simulation results** show 15% energy savings.\n3. **Industry validated** through Green AI Summits at Harvard with industry leaders from Oracle and Meta AI.\n\n**Ask:\\\nWe’re looking for:**\n\n1. **Data center operators** (and people in the AI infra sector) interested in piloting AI-driven optimization.\n2. **AI/ML researchers** tackling real-world control problems.\n\nGot feedback or want to pilot? Reach out: 👉 [jerry@deepawareai.com](mailto:jerry@deepawareai.com) or [LinkedIn](https://www.linkedin.com/in/jerryh01/) visit http://deepawareai.com/.\n\n\n\n",
"url": "https://www.ycombinator.com/launches/OBl-deepaware-automation-for-next-gen-ai-data-centers",
"votes": 15,
"created_at": "2025-08-14T01:42:09.062Z"
}
]
},
{
"id": 30854,
"name": "Hyperspell",
"slug": "hyperspell",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/4149c6afc651c9770fc182e08dde776e24f88554.png",
"website": "https://hyperspell.com",
"all_locations": "San Francisco, CA, USA",
"long_description": "Hyperspell is your Company Brain. AI agents are brilliant and clueless. They ace any test and still have no idea how your company works. Hyperspell connects your tools and synthesizes documents and conversations into a live, permissioned context graph. Any agent can read from it and write back to it like a filesystem, with every fact traced to source.",
"one_liner": "Your Company Brain",
"team_size": 8,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1760534513,
"tags": [
"Machine Learning",
"SaaS",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": true,
"nonprofit": false,
"batch": "Fall 2025",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Partly Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/hyperspell",
"api": "https://devasheeshg.github.io/yc-api/batches/fall-2025/hyperspell.json",
"year_founded": 2024,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://linkedin.com/company/hyperspell",
"x_url": "https://x.com/hyperspell",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/hyperspell",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/4149c6afc651c9770fc182e08dde776e24f88554.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/af3a623c068400310c706ffc43c0b17d3b40a103.png",
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/d96bd1f7c504fa8cd76323fbcd9b0bec0fda0da6.png"
],
"primary_partner": {
"name": "Tom Blomfield",
"url": "https://www.ycombinator.com/people/tom-blomfield"
},
"founders": [
{
"user_id": 2003252,
"full_name": "Conor Brennan-Burke",
"title": "Founder/CEO",
"founder_bio": "Founder of Hyperspell, Context & Memory for AI Agents",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/conorbrennanburke/",
"x_url": "https://x.com/conor_ai",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/8e06eab4105d354be854f0c45867d1cd63133fc9.jpg"
},
{
"user_id": 31259,
"full_name": "Manu Ebert",
"title": "Founder",
"founder_bio": "4x Founder, 2 exits, 15 years in AI & ML",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/maebert",
"x_url": "https://x.com/maebert",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/1fdf8a8308d72fd62ab8580049ab65377416d60f.jpg"
}
],
"jobs": [
{
"id": 92642,
"title": "Founding AI Engineer",
"url": "https://www.ycombinator.com/companies/hyperspell/jobs/MvG48cH-founding-ai-engineer",
"location": "San Francisco, CA",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150 - $220",
"equity_range": "0.50% - 1.50%",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"Python",
"Distributed Systems",
"Machine Learning",
"Natural Language Processing",
"Prompt Engineering"
]
},
{
"id": 92644,
"title": "Founding Platform Engineer",
"url": "https://www.ycombinator.com/companies/hyperspell/jobs/rMoV1RO-founding-platform-engineer",
"location": "San Francisco, CA",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150 - $220",
"equity_range": "0.50% - 1.50%",
"experience": "6+ years",
"visa": "US citizen/visa only",
"skills": [
"Amazon Web Services (AWS)",
"Kubernetes",
"Python",
"Distributed Systems",
"ETL"
]
},
{
"id": 92647,
"title": "Founding Forward Deployed Engineer",
"url": "https://www.ycombinator.com/companies/hyperspell/jobs/iLXJT3r-founding-forward-deployed-engineer",
"location": "San Francisco, CA",
"type": "Full-time",
"role": "Engineering",
"role_type": "Full stack",
"salary_range": "$150 - $220",
"equity_range": "0.50% - 1.50%",
"experience": "3+ years",
"visa": "US citizen/visa only",
"skills": [
"PostgreSQL",
"Python",
"TypeScript"
]
}
],
"news": [],
"launches": [
{
"id": 94666,
"title": "Hyperspell: Memory for AI Agents",
"tagline": "Give your agents long-term memory and context from your entire workspace",
"body": "[**Hyperspell**](https://hyperspell.com) **is the memory layer for AI agents.** We help developers connect data from tools like Slack, Gmail, Notion, and Google Drive so their agents can recall, reason, and learn over time.\n\n🎬 Watch our launch video: https://youtu.be/t6ji-n9qHYo?si=rALHJ2KaTiAieEvq\n\n---\n\n### Hi there!\n\n**Conor** led a $30m ARR API business at Checkr, building infrastructure used by tech companies like Doordash and Airbnb. **Manu** has 15+ years of Machine Learning experience. His previous ML/AI startup got acquired by Airbnb, where he went on to build Airbnb’s first Knowledge Graph. Manu has also owned .ai domains since 2014 when he bought one for his first startup (back then he had to send a fax to Antigua to get one).\n\n\n\n> ---\n\n### **AI Agents are clueless geniuses**\n\nToday, AI agents show up like it’s their **first day on the job** — sometimes impressive, but with no awareness of your context, institutional knowledge, history, and preferences. Worst of all, without the ability to learn and improve, they will only ever be as good as they are on day one.\n\n---\n\n### **Hyperspell fixes that.**\n\nWith our SDK, developers can add a context and memory layer to any agent in minutes. Pre-built connectors let users connect their tools like Gmail, Notion, and Slack, so that **memory doesn’t start from zero**: Hyperspell will analyze all existing files and conversations, figure out the important people, projects, and facts, and make it all available to your agent through our Agentic Memory Network.\n\n\n\nBest of all, **it improves with every single interaction:** Our novel approach to memory reinforces what’s being recalled, and helps your agent improve over time.\n\n\n\n### **But wait, there’s more!**\n\nThere’s lots of different ways our customers use Hyperspell, and because of that there’s lots of different ways you can integrate Hyperspell into your own agent. To make this easier, we created the **first ever self-integrating SDK**. \n\nWatch how we go from zero to production-ready PR on an unknown codebase with our custom Claude Code skill:\n\nhttps://www.youtube.com/watch?v=gfYsXJJsX3k\n\n# **Our Asks:**\n\n* Book a demo right now: https://cal.com/conor-brennan-burke/\n* Spread the word on linkedin and twitter: \\\n [https://www.linkedin.com/company/hyperspell](https://www.linkedin.com/company/hyperspell/%5C)\\\n https://twitter.com/hyperspell\n* Share your feedback with [conor@hyperspell.com](mailto:conor@hyperspell.com)\n\n\n\n",
"url": "https://www.ycombinator.com/launches/Ocs-hyperspell-memory-for-ai-agents",
"votes": 426,
"created_at": "2025-10-15T14:47:48.970Z"
}
]
},
{
"id": 30876,
"name": "Velum Labs",
"slug": "velum-labs",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/4835d7d3adbc5c3756ca811175142dfc73c7ddbe.png",
"website": "https://www.velum-labs.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Velum is the operating system for data quality. Velum automatically monitors and enforces data quality across a company's data stack, so bad data never reaches dashboards. We turn data quality from a manual task into infrastructure that runs itself.\r\n\r\nData trust you can prove. From the pipeline to the boardroom.",
"one_liner": "The OS for data quality across any stack",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1762847882,
"tags": [
"Machine Learning",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2026",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/velum-labs",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2026/velum-labs.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/velum-labs-ai",
"x_url": "https://x.com/velum_ai",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/4835d7d3adbc5c3756ca811175142dfc73c7ddbe.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Aaron Epstein",
"url": "https://www.ycombinator.com/people/aaron-epstein"
},
"founders": [
{
"user_id": 1177505,
"full_name": "Benjamin Muñoz-Cerro",
"title": "Founder/CEO",
"founder_bio": "CEO @Velum Labs | stanford quantum computing | harvard physics",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/benjamzc/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/840111d90db1dffc5c3e02d8728a42622fc82b0c.jpg"
},
{
"user_id": 2364271,
"full_name": "Alen Rubilar-Muñoz",
"title": "Founder/CTO",
"founder_bio": "CTO @ Velum Labs | ml swe | aspiring mathematician | hackathon winner | world citizen",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/000alen/",
"x_url": "https://x.com/000alen",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9019d7f13c58bfa58a7c0e71f53084bca1d3b444.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 30913,
"name": "Captain",
"slug": "captain",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/0c5e5da360891b80b4a1d6d511de963d613bbf08.png",
"website": "https://captain.dev",
"all_locations": "San Francisco, CA, USA",
"long_description": "Captain makes product catalogs and complex, multimodal files searchable for customers and AI agents. It syncs files from sources like S3, SharePoint, and Google Drive and tunes search to your data and workloads.\r\n\r\nInstead of stitching together parsers, embeddings, vector databases, rerankers, and retrieval infrastructure, developers use Captain to power product search and file retrieval through managed APIs.\r\n\r\nOn evaluated file-search benchmarks, Captain’s tuning improved retrieval accuracy from roughly 78% with standard RAG to over 97%.\r\n\r\nBuilt for complex catalogs and demanding file-search workloads, including regulated and high-stakes applications.",
"one_liner": "Self-tuning search for products and files",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1762492786,
"tags": [
"B2B",
"API",
"Data Engineering",
"Search",
"Infrastructure"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2026",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/captain",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2026/captain.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/runcaptain/",
"x_url": "https://x.com/captaindotdev",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/captain-technologies",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/0c5e5da360891b80b4a1d6d511de963d613bbf08.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/8c35ef0b175d1d2ac7f51910ee2cfa78036029ea.png"
],
"primary_partner": {
"name": "Garry Tan",
"url": "https://www.ycombinator.com/people/garry-tan"
},
"founders": [
{
"user_id": 2044865,
"full_name": "Lewis Lien Polansky",
"title": "Founder/CEO",
"founder_bio": "CEO @ Captain, building self-tuning search for products & files. Engineer, designer, founder of a cybersecurity CTF org, recipient of U.S. Congressional recognition for community software, and randomly co-invented the soy-based milk carton.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/lewispolansky/",
"x_url": "https://x.com/lienpolansky",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ecd86ae152b80dc12d55579cb0913bf93c33451f.jpg"
},
{
"user_id": 2578789,
"full_name": "Edgar Babajanyan",
"title": "Founder/CTO",
"founder_bio": "CTO @ Captain | Published AI NLP Researcher | Built OCR engines @ Boar's Head | Scaled high-performance RAG pipelines for the past 4 years | Built a Cross Region L2 Datacenter",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/edgar-babajanyan-a28230217/",
"x_url": "https://x.com/BabajanyanEdgar",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/a4db53926ab205e15c802b0761d911b65a0e7321.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 95291,
"title": "Captain - The Reliable Alternative to RAG",
"tagline": "Search files with much higher accuracy than RAG (Avg improves 78% → 95%)",
"body": "**TL; DR**: Captain delivers **the most accurate** general-purpose **knowledge search** engine **ever built.** \n\nIf you need to search through large text or multimodal files, and:\n\n* Don’t have time for **a tedious RAG sprint** -or-\n* Your current search pipeline lacks accuracy\n\nWe should talk. → [runcaptain.com/sales](https://runcaptain.com/sales?utm_source=ycombinator&utm_medium=launchyc&utm_campaign=launchyc&utm_content=weshouldtalk1) or [founders@runcaptain.com](mailto:founders@runcaptain.com)\n\nhttps://www.youtube.com/shorts/RxMPHqou94o\n\nIn a world where **90% of enterprise knowledge** cannot be stored in traditional databases, this ‘unstructured data’ is an **untapped goldmine** for decision-making. \n\nThe issue is that current RAG solutions have poor retrieval quality overall and are only performant on pre-optimized question types. \n\n\n\n**Captain** unlocks **better responses** thanks to an effectively **Infinite Context window**. We distribute it across many LLMs in parallel + some embeddings sprinkled in, and then ‘Map-Reducing’ responses down to a single output.\n\n\n\nWithout context limits, we have great freedom to optimize our retrieval engine for maximal accuracy. We can now play with a truly dynamic top-k or just run the LLM exhaustively (if a full knowledge audit is needed).\n\n\n\n**We’re two lifelong builders** obsessed with data! \n\n* Lewis (right) solved hallucinations for code generation through his previous startup. \n* Edgar (left) researched NLP+AI and has built production RAG pipelines for the past 3 years.\n\nWe’ve seen the pains and limits of these systems from the start, and **the industry is primed for a more accurate alternative.** \n\nThis past summer, we met with every engineer we could at **Snowflake** and **Databricks**, and we kept hearing the same thing again and again: \n\n> There’s **no good** scalable **unstructured** data **search**.\n\nUntil **today**.\n\n**Captain abstracts the engineering of retrieval entirely.** Connecting files is all that’s needed, and we’ll beat your RAG's accuracy. Guaranteed. \n\n**Our Ask**\n\nIf you know a **CTO** or **Head of AI** at a mid-market or enterprise **AI-native** (or are building one yourself), we would love an introduction!\n\nCheck us out at [RunCaptain.com](https://runcaptain.com?utm_source=ycombinator&utm_medium=launchyc&utm_campaign=launchyc&utm_content=website)\\\nor reach us directly through [founders@runcaptain.com](mailto:founders@runcaptain.com)\\\n\\\nHappy Shipping! 🚢",
"url": "https://www.ycombinator.com/launches/Omx-captain-the-reliable-alternative-to-rag",
"votes": 115,
"created_at": "2025-11-07T19:59:17.455Z"
}
]
},
{
"id": 30995,
"name": "Velvet",
"slug": "velvet",
"former_names": [
"Inline",
"Lenscape"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/3c02ad81894db8e1b1d0e71c379c7cae04211613.png",
"website": "https://velvetlab.ai",
"all_locations": "San Francisco, CA, USA",
"long_description": "Expressive conversational AI",
"one_liner": "Expressive conversational AI",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1761236237,
"tags": [
"Generative AI",
"Data Engineering",
"AI",
"Conversational AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Fall 2025",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/velvet",
"api": "https://devasheeshg.github.io/yc-api/batches/fall-2025/velvet.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/velvet-ai-lab/",
"x_url": "https://x.com/Velvet_Lab_",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/3c02ad81894db8e1b1d0e71c379c7cae04211613.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/3e66656b5e1c4869bcbecd4c0bef2936af174b35.png"
],
"primary_partner": {
"name": "David Lieb",
"url": "https://www.ycombinator.com/people/david-lieb"
},
"founders": [
{
"user_id": 2559459,
"full_name": "Lucas Mantovani",
"title": "Founder/CEO",
"founder_bio": "Co-founder, CEO of Velvet. Ex conversational data + youngest member @ Meta FAIR. CS honors @ UChicago. Brazilian olympiad medalist in Math + Physics.\n",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/lucas-mantovani-a446a61a9",
"x_url": "https://x.com/lrmantovani_",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/18122521571dcca4dbbd773deaf133f79578c670.jpg"
},
{
"user_id": 2292731,
"full_name": "Lucas Tucker",
"title": "Founder/COO",
"founder_bio": "Co-founder, CTO of Velvet. Previously at Adobe. Math and Computer Science at UChicago.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/lucas-tucker-21b278175",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/dba8487d05c5b0e40e12c4d46ec70f578f4555b7.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 31051,
"name": "Corvera",
"slug": "corvera",
"former_names": [
"Sarah.AI",
"Sarah AI"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/9ba3bd8042a63e5e4cc8707533d8561d2aa5bf74.png",
"website": "https://corvera.ai/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Corvera (YC W26) is the AI sales agent for CPG brands. We turn the data a brand already has into the actions its sales team takes today.\r\n\r\nA CPG brand sells into tens of thousands of independent US stores through dozens of distributors, and works that base with a handful of people. CLEAN Cause, a $20M yerba mate brand, covers 21,000 stores through 46 distributors with a four-person sales team. The accounts worth a call are not capped by headcount. The team is.\r\n\r\nCLEAN Cause now runs its daily sales decisions on Corvera: 5,000 queries in 40 days across 12 users, $250K of opportunities surfaced within days, and a 7x return on the analysts they would otherwise hire.\r\n\r\nWith Corvera in place, every sales rep starts the morning with:\r\n- The stores to act on today, ranked and priced, with the reason on the row,\r\n- The outreach already drafted to the right contact at the right distributor, and\r\n- The follow-up booked, logged, and measured against the goal it was set to move.\r\n\r\nAll from the distributor feeds, retailer portals, and ERP data they already have, resolved into one context layer - without a data team, and without handing their sales to a broker.\r\n\r\nWe’re founded by Chris (2x Founder; ex-CEO at Better Nature; Forbes 30U30), Dirk (ex-Google Data & AI Lead), and Matthew (ex-Head of Product at Rosemark; Princeton MEng in CS).\r\n\r\nTo date, we’ve raised $6.2M and are backed by YC, firstminute capital, 6 Degrees Capital, 20VC, Rebel Fund, Duke Capital Partners, and more. Our ICP is US CPG brands doing $20M+ in retail revenue through UNFI, KeHE and DSD distributors. We sell to VPs of Sales and CEOs.\r\n\r\nThe incumbents prove the scale. Brokers take 5-12% of a $350B US independent grocery market, and Advantage Solutions, a publicly traded company, does $3.5B in annual revenue.\r\n\r\nOur mission is bold: to enable the next generation of unicorn CPG brands to be run by teams of less than 10 people.\r\n\r\nOur vision is even bolder: to give every CPG brand the coverage of a full sales team at a fraction of the headcount, and displace the broker network that covers the US independent channel today.\r\n\r\nVisit www.corvera.ai to learn more!",
"one_liner": "The AI sales agent for CPG brands",
"team_size": 4,
"industry": "B2B",
"subindustry": "B2B -> Sales",
"launched_at": 1763141207,
"tags": [
"SaaS",
"Consumer",
"B2B",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2026",
"status": "Active",
"industries": [
"B2B",
"Sales"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/corvera",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2026/corvera.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/covera-ai/",
"x_url": "https://x.com/corveraai",
"fb_url": "https://www.facebook.com/profile.php?id=61586474546530",
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/9ba3bd8042a63e5e4cc8707533d8561d2aa5bf74.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/bc928e230e5816eafd2670b87d79f00f5d7e5a82.png",
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/70ffab5ef0a561dc9301ea2a549faf473e218c57.png"
],
"primary_partner": {
"name": "Brad Flora",
"url": "https://www.ycombinator.com/people/brad-flora"
},
"founders": [
{
"user_id": 3038174,
"full_name": "Christopher Kong",
"title": "Founder/CEO",
"founder_bio": "2× founder; previously CEO & Co-Founder of Better Nature, Europe's #1 tempeh brand - sold in 5,000 retail stores across 6 countries. Closed every sales deal and led every fundraise. Turned down a job offer at McKinsey to start the business straight out of university. Worked very hard and learnt a lot about how CPG brands operate.\n\nOxford Uni grad, Forbes 30 Under 30, and World Athletics-ranked marathon runner. Now giving everything to Corvera, the AI sales engine for CPG brands.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/cwnkong/",
"x_url": "https://x.com/chriskong852",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9238a1c5b939ec83a46ca72b61e979661caa0c0b.jpg"
},
{
"user_id": 3149010,
"full_name": "Dirk Breeuwer",
"title": "Founder/CTO",
"founder_bio": "Previously AI Lead at Google. Led the AI transformation for the Google Pixel in EMEA driving 20%+ cost reductions by automating processes using data and AI. Build Google's Global marketing data warehouse, enabling use cases including marketing mix models which helped optimise $100M+ in marketing spend. \n\nBefore Google I built Hugo's (LATAM last mile delivery acquired by Delivery Hero) order forecasting model, as well as site location models informing regional retail chain store expansion. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/dirkbreeuwer/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/6fa43c3533a3c00594c7ab78aa339ce86b786e44.jpg"
},
{
"user_id": 1655952,
"full_name": "Matthew Collins",
"title": "Founder",
"founder_bio": "Co-founder and CPO of Corvera, the AI agent workforce for CPG back-office. Ex-CPO of Rosemark (successor startup to Rosetta acquired by Publicis for $575m). Grew Eton's CS dept. Princeton ECE grad and varsity lightweight rower.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/itsmcollins",
"x_url": "https://x.com/matthewncollins",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/e5c9a9fe27e2816cf92ce37d3a3b3c884c9c8736.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 96996,
"title": "Corvera 🛒 | AI agents for CPG brands",
"tagline": "AI agents that automate retail brand ops and increase profits by 40%",
"body": "Hey, we’re [Chris](https://www.linkedin.com/in/cwnkong/), [Dirk](https://www.linkedin.com/in/dirkbreeuwer/) and [Matthew](https://www.linkedin.com/in/itsmcollins/) - cofounders of Corvera!\n\n# **TL;DR**\n\nCorvera is the AI agent workforce for CPG back-office. We help retail brands increase profits by up to 40% by deploying digital workers that run their operations. \n\n**Ask:** Looking for intros to CPG brands that sell into retail, ideally with > $50M in ARR. Direct them to our website to schedule a demo!\n\n**Website:** \n\n**Book a demo:** \n\n\n\n### **The Problem**\n\nRetail CPG brands are drowning in operational debt.\n\n* **Ops is a massive opportunity cost** – US CPG brands waste 40% of their time and spend $78bn managing supply chains when they should be getting their products out there and selling to more customers.\n* **Poor ops is a huge growth bottleneck** – CPG founders typically stem from product, marketing, or sales backgrounds. Therefore, ops handled by non-ops founders = distraction, pain, and time wasted on non-value-add tasks.\n* **Ops pain scales with the brand –** Ops debt and headcount grow as a brand serves more customers, launches more products, and operates in more geographies, further hampering the brand’s growth.\n\n### **The Solution**\n\n**Corvera is the fully autonomous command centre managing ops for fast-growing retail brands.** \n\nWe help brands cut wastage, improve margins, and maximise revenue, with an AI workforce that knows exactly how CPG brands work. We automate the 3 core ops workflows which consume the most time and hamper growth:\n\n**1) Sales Order Processing**\n\n_Process orders end-to-end without lifting a finger._\\\n\\\nCorvera plugs into your existing tools and automatically processes sales orders end-to-end, from fulfillment to invoice. It parses email PDFs and text, matches them against known entities in our catalogue, and executes downstream actions with human-in-the-loop approvals.\n\n**2) Inventory Management**\n\n_Track inventory across every location in real time._\n\nCorvera knows exactly where your stock is and how much you’ve got at all times. We seamlessly sync inventory data across all of your warehouses, track shipments and transfers, and suggest actions to rebalance stock across your estate to maximize short-term revenue.\n\n**3) Demand Forecasting & Supply Planning**\n\n_Forecast demand in real time and automatically process purchase orders to prevent stockouts._\n\nCorvera learns from your sales history and, coupled with insights from your team, forecasts demand in real time. With full visibility of your inventory across all locations, Corvera suggests corrective actions to prevent stockouts, so you can maximize your revenue, keep your customers happy, and accelerate your growth. \\\n\\\n**In short:** We take away ops pain from CPG brands, allowing them to do what they do best - market and sell their products to their customers. \n\n### **The Team**\n\n\n\nFrom Left to Right:\n\n[**Dirk Breeuwer**](https://www.linkedin.com/in/dirkbreeuwer/) (Co-Founder & CTO)\n\nFormerly Data and AI Lead at Google with 6+ years of experience. Led Google’s marketing AI transformation, incubating five AI systems, including a multi-agent workflow automation that improved brand compliance review efficiency by 90%.\n\n[**Christopher Kong**](https://www.linkedin.com/in/cwnkong/) (Co-Founder & CEO)\n\n2x Founder, Forbes 30U30, formerly CEO of Better Nature - one of Europe’s fastest-growing and largest meat-free brands, active in 6 countries and sold in 5,000+ retail stores. Closed every major sales deal and led every fundraise.\n\n[**Matthew Collins**](https://www.linkedin.com/in/itsmcollins/) (Co-Founder & CPO)\n\nEx-CPO at Rosemark, an AI-powered B2B data analytics and marketing platform, and scaled the Computer Science department at Eton College, the UK’s most prestigious boarding school. A Princeton grad with an MEng in CS. \n\n[**Berk Güngör**](https://www.linkedin.com/in/berk-g%C3%BCng%C3%B6r-35196a14a/) (Founding Engineer & Head of AI Engineering)\n\nAI/ML Engineer with 6+ years of experience, focused on applied LLMs and real-world AI automation. Holds an MSc in AI from the University of Hamburg. An all-round beast and an incredible asset to the team - we’re lucky to have him.\n\n### **What We’re Looking For**\n\n**Introductions to CPG retail brands with >$50M of revenue.** We’ve got a product that’s ready to go. Keen to meet as many CPG brands as possible between now and demo day!\n\n### **Get In Touch**\n\nContact us: [founders@corvera.ai](mailto:founders@corvera.ai)\n\nBood a demo: ",
"url": "https://www.ycombinator.com/launches/PES-corvera-ai-agents-for-cpg-brands",
"votes": 17,
"created_at": "2026-01-21T02:00:02.532Z"
}
]
},
{
"id": 31139,
"name": "Ashr",
"slug": "ashr",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/36b682fdfb87515f8ca423d8a006eaac7229e134.png",
"website": "https://ashr.io",
"all_locations": "San Francisco, CA, USA",
"long_description": "Ashr Manifold is a self-contained model training, hosting, observability, and continual learning platform for purpose-built open-weight models. \r\n\r\nStartups can use Manifold to post-train and manage fleets of continuously improving open-weight models without having a dedicated research team or infrastructure. Ultimately, this reduces operating costs and allows a greater degree of control over proprietary company knowledge.\r\n\r\nEnterprises can use Manifold to encode institutional judgements and priorities into open-weight models, reduce token costs, and manage every level of the AI life cycle, from data curation, to model serving on weights and infrastructure they own.",
"one_liner": "Enterprise post-training, monitoring, and continual learning platform",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1771535371,
"tags": [
"Deep Learning",
"Generative AI",
"Reinforcement Learning",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Winter 2026",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/ashr",
"api": "https://devasheeshg.github.io/yc-api/batches/winter-2026/ashr.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/ashr-io",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/36b682fdfb87515f8ca423d8a006eaac7229e134.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Harshita Arora",
"url": "https://www.ycombinator.com/people/harshita-arora"
},
"founders": [
{
"user_id": 1467144,
"full_name": "Rohan Kulkarni",
"title": "Founder/CEO",
"founder_bio": "Building custom models at Ashr Labs. Co-founder and CTO of Ask Geri (Acquired). Berkeley EECs. ",
"is_active": true,
"linkedin_url": "https://linkedin.com/in/rohankulkz",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/297857e249e4e8e3f4bce0f12fda39d67b33b506.jpg"
},
{
"user_id": 2584088,
"full_name": "Shreyas Kaps",
"title": "Founder",
"founder_bio": "Building Ashr Manifold to help teams build and host purpose-built and trained models",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/shreyas-kaps-5b1a4420b/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/697406e5dc0beff2a338d68874683d7c8e1703c0.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 98286,
"title": "Ashr: Mimic Your Production Environment and Users to Catch Agent Fails",
"tagline": "Custom Tests and Evals Simulating Real User Behavior",
"body": "\nHi YC, we’re Shreyas and Rohan — two ex-Berkeley students building Ashr.\n\n**TL;DR :** Ashr catches bugs and validates agent response quality by mimicking the patterns and quirks of real users. Developers today struggle to simulate these conditions in tests, resulting in real-time fails and unexpected behavior. We integrate as an SDK within your codebase.\n\n\n\n# The Problem\n\nAI automations are top of mind for every developer: large companies are integrating AI into older systems to stay technologically relevant, while AI-native companies are quickly emerging in every vertical. Unfortunately, most of these AI tools miss the mark: constant hallucinations, unexpected behavior, and dubious quality have eroded trust in agentic systems. In most cases, this is not because foundation models aren’t powerful enough, but because of subtle prompting, tooling, and scaffolding errors that only emerge with rigorous testing. The need for high volumes of realistic testing arises in many scenarios: we’ve spoken to companies who want to prove that their agents are capable of handling sensitive data to potential customers, developers who want to make their agents work better, and engineers who want to test edge-cases and new features but don’t have all the necessary tools.\n\nWe’ve seen teams confront this problem with a litany of half-measures: pushing to production and tanking user trust as a means of discovering bugs, half-baked test harnesses, and vibe-coded test suites that only scratch the surface. We built ashr to solve this.\n\n# Our Solution\n\nAshr is a modular testing and evaluation platform for your agentic system. We integrate as an SDK into your codebase, allowing you to request test suites and analyzing your agents’ output based off your tooling and ideal outputs. These tests mimic how real users utilize an agentic system: taking complex tool call paths, using obscure language with unclear instructions, and attempting to use restricted features. We develop environments, fine-tuned custom scorers, and stop at nothing to provide all the insights needed to bring your agent to a truly production-ready state.\n\nWe also work seamlessly with Claude Code and Cursor, allowing your coding agents to quickly prototype and test changes while receiving immediate feedback. Teams have run swarms of agents testing with ashr overnight, and have woken up to changes that reduced hallucinations and increased accuracy and user retention, all without writing a single line of code.\n\n# Our Ask\n\nIf you’re building agents, book a call today at [**https://ashr.io/**](https://ashr.io/). **All onboarding is done via call so we can ensure everyone is ready to go and start using as soon as possible.** In addition, we’d love feedback on our docs, opinions about the nature of test infra, and just chatting with a bunch of builders on how to make our product better.\n\nYou can reach us at [founders@ashr.io](mailto:founders@ashr.io)\n\n# The Team\n\n**We’re two young founders passionate about changing the world with agentic development**\n\n* **Rohan** built his first startup, an AI-native survey platform for old age homes, as a student at Berkeley, before exiting as part of an acquisition and joining YC.\n* **Shreyas** worked on AI-native workflows at Tessera Labs, mentored by a team of ex-Meta and Netflix research, and delivering value in the ERP transformations of Fortune 100 companies.",
"url": "https://www.ycombinator.com/launches/PZG-ashr-mimic-your-production-environment-and-users-to-catch-agent-fails",
"votes": 9,
"created_at": "2026-02-27T22:43:17.702Z"
}
]
},
{
"id": 31304,
"name": "Litmus",
"slug": "litmus-hiring",
"former_names": [
"Avert",
"Litmus",
"Avert"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/4a9f14022a002a449869ff376c950e1a9966d580.png",
"website": "https://litmushiring.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Litmus is building the most accurate framework for evaluating and benchmarking human capability, starting with software.\r\n\r\nAI will compound small differences in human capability into increasingly large differences in what people can accomplish, while making existing static benchmarks obsolete. Software is already there: AI can hill-climb any output-based evaluation, while the ability to direct it is becoming the defining advantage. \r\n\r\nLitmus applies the same approach we already use for model evals to humans – creating world-like environments, and inspecting trajectory instead of just output.\r\n\r\nEvery knowledge industry will soon face the same problem. We build Litmus to tell you what humans are capable of.\r\n\r\nWe're already helping build frontier technical teams at Mercor, Composio, Neo Scholars, and more.",
"one_liner": "Evals for humans",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1783537104,
"tags": [
"Recruiting",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2026",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/litmus-hiring",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2026/litmus-hiring.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/litmushiring",
"x_url": "https://x.com/UseLitmus",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/4a9f14022a002a449869ff376c950e1a9966d580.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/7d94ea3ae5f80a2b9c035af7e2b630fc5b19556e.png"
],
"primary_partner": {
"name": "Jared Friedman",
"url": "https://www.ycombinator.com/people/jared-friedman"
},
"founders": [
{
"user_id": 1353649,
"full_name": "Shaivi Rau",
"title": "Founder/CEO",
"founder_bio": "building litmus",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/shaivi-rau",
"x_url": "https://x.com/ShaiviRau",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/d5482bbda470c38ccb104e539a75d967d59855d2.jpg"
},
{
"user_id": 2315600,
"full_name": "Elena Zhao",
"title": "Founder/CTO",
"founder_bio": "Evals for humans",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/elena-zhao-015353217/",
"x_url": "https://x.com/ElenaxZhao",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/181a9fd30489864e7baeee3f884bda9fe2c72cf1.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 105006,
"title": "Litmus - The industry's most accurate engineering interview",
"tagline": "Scalable, async work trials built from your repos, tickets, and JDs",
"body": "**TL;DR:** We evaluate candidates through async technical assessments built from your own context (repos, tickets, and job descriptions) and let them work in their own setup with all their tools while we track and evaluate their process and output. _Engineering is changing; we help you hire for the role it’s becoming. Learn more at [litmushiring.com](http://litmushiring.com)._\n\n\n\n**The problem**\\\nYou're a month in with a new hire and they're just not getting it: struggling to ship independently, shipping AI-generated code they can't explain, clueless when production breaks. None of this showed up in your interview because your interview was never designed to catch it.\n\nWe all already agree LeetCode sucks. But work trials are time-draining, unscalable, and kind of awkward when you know within the first hour someone's not gonna make it. So most teams are stuck choosing between a broken screen and a process that doesn't scale.\n\n**What we built**\\\nLitmus fixes both. We turn your repos, tickets, and job descriptions into a full interview pipeline where every assessment is generated from scratch for your company. Not a generic template, your actual codebase, your real engineering problems, scoped as end-to-end features.\n\nCandidates work in their own setup, with all their tools including AI because that's how engineering works now, and that's what you're hiring for. \n\nEvery submission runs in a sandbox, so graders evaluate real code execution, not what looks good on paper, and grading is tuned to your company across tool fluency, process, and outcome. \n\nThe result: a real read on how someone actually builds, not just how they interview.\n\n1. **Generate Tailored Assessments**\n\n \n\n2. **Candidates take Assessments**\n\n \n\n3. **Evaluate at Scale**\n\n \n\n4. **Deep Dive into Top Candidates**\n\n \n\n\n**Traction**\\\n**3,000+ assessments evaluated**. **$60k ARR**, growing fast. We've built the hiring system for **Neo Scholars**, their portfolio, and others. Let us bring our expertise to your team.\n\n**Who we are**\\\nWe're Shaivi and Elena. As a SWE at Two Sigma and Meta, Elena watched people ace every interview and then fail to build anything real on the job. Shaivi worked at early-stage startups and in VC, sitting beside founders as they agonized over which engineers to trust with the product. Two sides of the same coin - the most important decision a company makes is its team, and current interviews still can't tell you who'll deliver. Litmus does.\n\n**Our ask**\\\n**Scaling your eng team?** **We'll come to your office, set you up, and run Litmus on your next role. Book a demo at [litmushiring.com](http://litmushiring.com).** And if you know a team drowning in engineering interviews, send them our way.",
"url": "https://www.ycombinator.com/launches/RJe-litmus-the-industry-s-most-accurate-engineering-interview",
"votes": 5,
"created_at": "2026-07-09T15:01:22.190Z"
}
]
},
{
"id": 31318,
"name": "Databuddy",
"slug": "databuddy",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/41cf5cb7088967b39be98f97d7bb5d8f97df5aac.png",
"website": "https://www.databuddy.cc",
"all_locations": "San Francisco, CA, USA; Remote",
"long_description": "Databuddy gives you your very own data analyst, always watching over your data, combining all your context to investigate and paint a full picture on every product issue that emerges in real-time; conversion drops, user frustration and churn.\r\n\r\nIt makes your product better without needing to have you look at a dashboard and spend hours figuring out the why. one click to install or switch from any dated analytics provider.",
"one_liner": "AI Data Analyst for fast-growing teams",
"team_size": 1,
"industry": "B2B",
"subindustry": "B2B -> Analytics",
"launched_at": 1791412796,
"tags": [
"B2B",
"Analytics",
"Data Engineering",
"Infrastructure",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Fall 2026",
"status": "Active",
"industries": [
"B2B",
"Analytics"
],
"regions": [
"United States of America",
"America / Canada",
"Remote",
"Fully Remote"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/databuddy",
"api": "https://devasheeshg.github.io/yc-api/batches/fall-2026/databuddy.json",
"year_founded": 2025,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/trydatabuddy",
"x_url": "https://www.twitter.com/trydatabuddy",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/databuddy",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/41cf5cb7088967b39be98f97d7bb5d8f97df5aac.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Pete Koomen",
"url": "https://www.ycombinator.com/people/pete-koomen"
},
"founders": [
{
"user_id": 2755916,
"full_name": "Issa Nassar",
"title": "Founder",
"founder_bio": "Building the coolest analytics platform that handles your analytics for you.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/issanassar",
"x_url": "https://x.com/izadoesdev",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/91c0735889e9859c7981c36fd71679fb069d9050.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 32130,
"name": "Olam Labs",
"slug": "olam-labs",
"former_names": [
"Gud Labs"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/d6d9543a0527b0b5ac428e043f211c75ac5d1d59.png",
"website": "https://olamlabs.ai",
"all_locations": "San Francisco, CA, USA",
"long_description": "We research complex, high-fidelity simulations for training and evaluating frontier AI models, alongside the infrastructure to test and deploy them at scale. Our research focuses on simulations with realistic socialization, multi-agent interaction, swarms, and ultra-long-horizon tasks.\r\n\r\nTry one of our first releases, Multi-Agent Arena (https://olamarena.com/), where humans come play social strategy games against multiple AI agents. It has multi-agent social games like Poker, Diplomacy, Risk, and more.",
"one_liner": "Crafting simulations for frontier lab model training",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1784577901,
"tags": [
"Reinforcement Learning",
"Gaming",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2026",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": [
{
"question": "How did your company get started? (i.e., How did the founders meet? How did you come up with the idea? How did you decide to be a founder?)",
"answer": "Om and Shreshth met in middle school. They were the only two kids in the “gifted” program in their grade, and their first project together was running a snacks and candy store at their school where the profits were used to donate to charity.\\\r\n\\\r\nDuring Christmas holiday in 2025, Om created a multi-agent simulated environment where agents ran their own company in markets competing against each other, and showed it to Shreshth.\\\r\n\\\r\nShreshth, with a background in data and RL among other things, loved the implications of it. Om discussed with him how if multi-agent environments were developed and productionized at scale via frameworks, APIs for infra, and interactive games the kind of data and evaluations it could generate.\\\r\n\\\r\nThe problem was (and still is) that despite the success of multi-agent environments in research, the ecosystem around them has not been pursued to a degree where the utility of multi-agent environments is made readily available to everyone.\\\r\n\\\r\nThey decided to pursue it and applied to YC, and have been in pursuit of a future where we can understand and measure the models that we work with everyday and that will become increasingly autonomous in our everyday lives with AI acceleration. Om and Shreshth both believe there is a severe shortage of good AI evaluations, especially on qualitative behaviors, of which multi-agent environments (and allowing others to build them) is very well suited to solve.\\\r\n\\\r\nMore on Shreshth: [shresh.ca](http://shresh.ca) Shresh’s X: \\\r\nMore on Om: [sensho.xyz](https://www.sensho.xyz/) Om’s X: "
}
],
"url": "https://www.ycombinator.com/companies/olam-labs",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2026/olam-labs.json",
"year_founded": 2026,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/olam-labs/",
"x_url": "https://x.com/olam_labs",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/d6d9543a0527b0b5ac428e043f211c75ac5d1d59.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/3e94d77a846523415d54724a99c9965d17599d69.png"
],
"primary_partner": {
"name": "Harshita Arora",
"url": "https://www.ycombinator.com/people/harshita-arora"
},
"founders": [
{
"user_id": 3676793,
"full_name": "Om Buddhdev",
"title": "Founder/CEO",
"founder_bio": "Building simulated worlds for frontier labs to train capable and safe models.\n\nI love learning, tech, competing, and building cool things. I am optimistically AGI pilled and believe most people (even in SF) have not yet internalized what will change over the next 10Y.\n\nPreviously a Staff Engineer @ latitude.io, one of the best Valorant players in the world, math research cited by Terence Tao, TikTok creator /w 190k followers, Roblox game dev, and some other things.\n\nhttps://www.sensho.xyz",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ombud/",
"x_url": "https://x.com/sensho",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/91f0defa43559eee579ccd34e4f7fd404cdb2aa6.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 109432,
"title": "Can you beat frontier LLMs at social strategy games? | Multi-Agent Arena by Olam Labs, evaluating through multi-agent simulations",
"tagline": "Play games like Risk, Poker, or Codenames against frontier AIs. We're running public long-horizon games to do evaluations on social behavior and agentic performance.",
"body": "**TL;DR:** As many researchers and labs will say, there is a massive shortage of genuinely good AI evaluations. Multi-agent environments are an underdeveloped way of evaluating models that we think will help address our increasingly worse shortage of evals. We're starting with **Multi-Agent Arena**, where anyone can come compete against frontier AI models in social multiplayer games, as we build towards the full stack for multi-agent environments. Try Multi-Agent Arena for free at :) \\\n\\\n[https://drive.google.com/file/d/186GgmnOLz4Yc1BpFk6AxHd3aqUdFYCQy](https://drive.google.com/file/d/186GgmnOLz4Yc1BpFk6AxHd3aqUdFYCQy/view?usp=sharing)\n\n---\n\n## **Overview**\n\nMulti-agent environments provide an essential, underutilized framework for benchmarking autonomous AI models. Multi-Agent Arena is an interactive platform where human participants compete against frontier AI models in multiplayer games, serving as an experimental foundation to evaluate complex agent interactions. Multi-Agent Arena is the first of many stepping stones to building the entire stack and ecosystem for multi-agent environments.\\\n\\\n**The Evaluation Gap** \\\nCurrent AI evaluations primarily focus on single-agent, task-oriented capabilities. While benchmarks such as SWE-bench measure functional task execution, they do not assess the dynamic social behaviors required for autonomous real-world deployment: negotiation, coalition stability, long-horizon planning against adaptive opponents, and spontaneous deception.\n\nSimulated multi-agent environments induce these complex interactions while preserving complete experimental control. Unlike unstructured real-world deployment, these environments offer full data legibility, enabling researchers to inspect every reasoning trace, state transition, and stochastic variable behind model decisions.\n\n**Our Preliminary Evaluations**\\\nThe platform runs deterministic, replayable environments hosting human players alongside anonymized frontier models. Structured as accessible multiplayer games, the infrastructure captures interaction data to score models across two primary axes in our first evaluated game, Poker:\n\n* **Competitive Capability:** One of our preliminary methods is using a Bradley-Terry model to yield Elo ratings with bootstrapped confidence intervals, supplemented by domain-specific metrics such as big blinds per 100 hands in poker. Top-quartile human participants currently outperform all benchmarked models in Poker.\n* **Behavioral Diagnostics:** Model reasoning traces are evaluated against ground-truth game states using expert-curated rubrics and variance-checked grader panels to ensure inter-annotator agreement.\n\n**Initial Metric: Deception Index** \\\nThe benchmark's initial diagnostic metric, the Deception Index, quantifies deliberate misrepresentation per 10,000 turns. A deceptive event is logged only when an agent's private chain-of-thought confirms awareness of a true state while its external communication directly contradicts it. In baseline tests with no explicit instructions or prompts to deceive, frontier models demonstrated performance variance spanning nearly two orders of magnitude across identical environments.\n\nComplete evaluations, research methodology and technical documentation are available at [olamlabs.ai/research/social-arena](https://olamlabs.ai/evaluations)\\\n\\\n**Launch**\\\n\\\nWe already passed a thousand matches a day in our early access, are nearing a billion tokens used per day, ranking on the OpenRouter leaderboards, and have thousands of users that are paying to play in the arena while we work with researchers on use cases they have for our work and environments. We’re hoping this is just a stepping stone and want to scale towards our roadmap and ambitions of what we believe multi-agent environments, when properly developed with the right stakeholders in the training/eval ecosystem, can achieve for AI progress.\\\n\\\n\\\n**What’s in it for you?**\n\n1. **Play.** It's free, and every match directly informs the evals. Bring friends, try to beat the models, it’s harder than you'd think. 🃏\n2. **Speak with researchers.** We love speaking with researchers interested in this space and it’s all that we think about; if that’s you please feel free to reach out to us at [founders@olamlabs.ai](mailto:founders@olamlabs.ai) or on \\\n \\\n 🫡\n\n---\n\n## About the team\n\n**Om Buddhdev (CEO)** — Previously a Product Engineer then promoted to Staff Engineer at AI Dungeon / Latitude working on AI infra, agents, and consumer platform work, left for Olam Labs. Before that he was among the best Valorant players in the world (top 25, 8x radiant), at 17 a large content creator on TikTok with 195k followers, and as a young teenager made Roblox games played millions of times, among other things in his past. More on Om at \n\n**Shreshth Sharma (CTO)** — Background in production data engineering: was a Data Scientist at RBC while doing a double degree at the University of Waterloo in CS and Math, dropped out of both for Olam Labs. He has a background in many data and statistics projects, alongside briefly being a top 50 Fifa player. More on Shreshth at \\\n\\\nOm and Shreshth have been friends since middle school, and Olam Labs was born out of their personal interest and desire to build out the entire stack for multi-agent environments to be the default way we evaluate models in the future.",
"url": "https://www.ycombinator.com/launches/ST2-can-you-beat-frontier-llms-at-social-strategy-games-multi-agent-arena-by-olam-labs-evaluating-through-multi-agent-simulations",
"votes": 9,
"created_at": "2026-08-05T21:32:50.566Z"
}
]
},
{
"id": 32262,
"name": "Alkera AI",
"slug": "alkera-ai",
"former_names": [
"Alkera AI, Inc.",
"Alkera AI",
"Alkera AI, Inc."
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/eecc1a49c35b3a26973c35ce53d1c3f862a058cb.png",
"website": "https://alkera.ai",
"all_locations": "San Francisco, CA, USA",
"long_description": "Alkera is a data engineering/analysis/science agent that works in your IDE or CLI. If you’re tired of agents that produce false, or even dangerous, reports about your data, then Alkera is for you. Our agent is equipped with your data’s history and lineage, your team’s knowledge, and tailored plugins for data apps such as Snowflake and dbt. Simply install and connect your services to begin doing trusted agentic data work. We also offer VPC & on-prem deployment options for when data can't leave your boundary.",
"one_liner": "Reliable and safe data engineering and data science agents",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B -> Engineering, Product and Design",
"launched_at": 1783697969,
"tags": [
"Developer Tools",
"Data Science",
"Data Engineering",
"Enterprise Software",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2026",
"status": "Active",
"industries": [
"B2B",
"Engineering, Product and Design"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/alkera-ai",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2026/alkera-ai.json",
"year_founded": 2026,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/alkera-ai",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/eecc1a49c35b3a26973c35ce53d1c3f862a058cb.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Ankit Gupta",
"url": "https://www.ycombinator.com/people/ankit-gupta"
},
"founders": [
{
"user_id": 3652826,
"full_name": "Rick Gao",
"title": "Founder/CEO",
"founder_bio": "Founder at Alkera AI, Inc. Previously at Verition Fund Management where he built financial models and optimizations for treasury financing. Previous computational biology research at Yale's Gerstein Laboratory. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/rgao09",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/515662055ce684fc796921959375d09b477afbfa.jpg"
},
{
"user_id": 3406186,
"full_name": "Tony Li",
"title": "Founder/COO",
"founder_bio": "Founder at Alkera AI, Inc. Previously Agentic Software Engineer at ByteDance, where he built a Python framework for multi-agent AI workflows and deployed production bots used across company teams. Former Quantitative Developer at Carthage Capital. BS in Computer Science and Mathematics from Yale.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/tonyli4722",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/9e00bcde4966ff8eb6ea44e6847dce0d34f0c0b5.jpg"
},
{
"user_id": 3673412,
"full_name": "Andrew Tran",
"title": "Founder/CTO",
"founder_bio": "Cofounder at Alkera AI. Prev SWE intern at Ramp and HRT, working closely with data teams. CS B.S/M.S from Yale. Prev ML research at Yale's Gerstein Lab developing biology reasoning models.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/andrewtran-cs/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/fbb518656ab4ebfa5220bc5c8406b2716cf75c60.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 106204,
"title": "Alkera - The data agent that you can trust",
"tagline": "Alkera is an agent that replaces your coding agent to reliably and safely perform real data engineering/analysis/science work.",
"body": "**TL;DR:** Data teams adopting AI agents want speed, but one wrong step can quietly ripple through your dbt models, dashboards, and business decisions before anyone notices. [Alkera](https://alkera.ai) **is an AI data agent for data engineers/analysts/scientists or anyone who wants to gather data insights that actually understands your data stack** (column-level lineage, graph-based planning, and a living knowledge base), so it ships data work you can trust. It's **#1 on UC Berkeley's [DataAgentBench](https://ucbepic.github.io/DataAgentBench/),** which tests complex, data-oriented tasks.\n\n\n\nCoding agents can write data code that runs. **For data engineering, knowing it's correct is the hard part.** This is knowing that a transformation didn't quietly redefine a column three models downstream and corrupt the revenue dashboard that the exec team checks every Monday. **For data analysis and data science, beyond data access and lineage problems, coding agents struggle with highly parallel work spread across multiple machines.** When interacting with remote computing nodes, they do so only via fragile chains of SSH commands. Long processing and training runs have you more as a babysitter than a scientist.\n\n**Alkera is a data agent that works natively across your entire data stack, with the context and guardrails coding agents lack.** Every change it makes to a query, transformation, model, or notebook is backed by a real understanding of your pipeline.\n\nIt's **#1 on UC Berkeley's DataAgentBench,** which tests complex, data-oriented tasks. You reach it through an IDE extension (VSCode, Cursor), a CLI, or the browser — wherever you already work.\n\nWhat makes it different:\n\n* **Column-level lineage across your data stack.** Trace a single row from Snowflake, through your dbt models, to your Hex dashboard. Before the agent changes anything, it maps the _blast radius_ — every downstream table and dashboard the change would touch.\n* **Graph-based planning with flexible computation.** Plan complex data tasks with parallel agents from a quick analysis to days-long modeling experiments to run across your machine and remote CPU/GPU nodes.\n* **A living knowledge base.** Alkera learns your schema docs, trusted queries, and the tribal conventions that never make it into documentation — written by both agents and humans, with humans verifying what the agent adds.\n* **Production protection.** Fine-grained permissions over every tool, including bash and SQL. Block a seemingly innocent SQL query with a dangerous UPDATE hidden away in a subexpression. Enforce OAuth to connect your warehouses to maintain existing data permissions.\n\n# **Try it**\n\nDownload Alkera at or read the docs at . For data engineering, point it at your stack and **watch it trace a change through your pipeline**, lighting up everything downstream. For data analysis and data science, have it **spin up parallel research agents** to explore your data. Reach out to [contact@alkera.ai](mailto:contact@alkera.ai) to see how we can tailor Alkera to your specific data apps/tools and computing environment.\n\n# **Our team**\n\n* Andrew Tran studied CS at Yale. At Yale, he trained LLMs to reason over multi-modal biological data. At Ramp and Hudson River Trading, he worked closely with data teams to build out ergonomic tooling for data engineers and researchers.\n* Rick Gao studied CS at Yale. He was previously at Verition Fund Management, where he worked with internal data teams and counterparties to develop ingestion pipelines and internal financial models.\n* Tony Li studied CS and Math at Yale. During his time at Carthage Capital and ByteDance, he worked with data engineering teams to build data pipelines, data analysis, and agentic tooling.\n\n# **Our ask**\n\nIf you:\n\n* perform data engineering work on production pipelines with tools like dbt and Apache Airflow\n* perform data analysis/data science work in Python/R and with tools like Jupyter notebooks\n* manage a data team – engineers, analysts, or scientists\n* want to enable non-data experts to create data insights\n\nCheck out and reach out at [contact@alkera.ai](mailto:contact@alkera.ai). We’d love to showcase a demo, learn more about your data teams’ pain points, and share more about how Alkera can help supercharge them.",
"url": "https://www.ycombinator.com/launches/Rcy-alkera-the-data-agent-that-you-can-trust",
"votes": 12,
"created_at": "2026-07-17T18:50:58.787Z"
}
]
},
{
"id": 32988,
"name": "Markov",
"slug": "markov",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/41a4a41e5482735389d2089a01ff2b862f56e307.png",
"website": "https://www.markovstudios.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Markov builds expert computer-use datasets for frontier AI labs. Our datasets include screen recordings + mouse/keyboard actions of professionals using CAD, design and enterprise software.\r\n\r\nWe work with the top AI labs and we’ve gotten more than 350k downloads on HuggingFace. Our long-term goal is to be the full stack platform for computer-use AI, starting with data and then the infrastructure to train and deploy computer-use models.\r\n\r\nDev and Harish are technical co-founders. Dev studied aerospace engineering at IIT Madras and was the youngest team member at Sarvam - India’s top AI lab. Harish is an Emergent Ventures grantee and his prior robotics work was featured in top national publications.",
"one_liner": "Expert computer-use data for frontier AI labs",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1782277833,
"tags": [
"Reinforcement Learning",
"Data Labeling",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2026",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/markov",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2026/markov.json",
"year_founded": 2026,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/markov-artificial-intelligence/",
"x_url": "https://x.com/markov_labs",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/41a4a41e5482735389d2089a01ff2b862f56e307.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Harshita Arora",
"url": "https://www.ycombinator.com/people/harshita-arora"
},
"founders": [
{
"user_id": 1783684,
"full_name": "Dev Mandal",
"title": "Founder/CEO",
"founder_bio": "Co-Founder & CEO at Markov. Prev at Sarvam, Aerospace engineering at IIT Madras",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/dev-mandal-iitm/",
"x_url": "https://x.com/DevvMandal",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/5a53c70cbcddfae2c6c21e32faac5865be5702b2.jpg"
},
{
"user_id": 2921049,
"full_name": "Harish Ashok",
"title": "Founder/CTO",
"founder_bio": "Co-Founder at Markov. Previously founded Zenith, a robotics company building AI-assisted hardware workflow tools. ",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/harish-ashok",
"x_url": "https://x.com/harishashok",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/fbfaea52b2a5bc846c87d04392062585acfb69ff.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 109874,
"title": "Markov - Data for computer-use AI",
"tagline": "150K+ downloads across our HuggingFace datasets",
"body": "# \\*\\*\\*\\*\n\n**TLDR;**\n\n* **Markov builds the data infrastructure for computer-use AI**, collecting synchronized screen recordings, mouse/keyboard actions, and annotations from real workflows.\n* **We specialize in hard-to-source expert data** **across CAD, architecture, engineering**, and other professional applications.\n* **We’ve already sold 15,000+ hours of data to frontier AI labs** and open-sourced leading computer-use datasets with **150k+ downloads on HuggingFace**.\n\n\n\n**The Problem:**.\n\nWhile frontier models have gotten much better at reasoning, they still struggle to reliably complete long, multi-step workflows across real desktop software. **The biggest bottleneck is the lack of high-quality training data.**\n\nTraining these models requires **synchronized screen recordings, mouse and keyboard actions, and high-quality annotations from people doing real work**. This is especially scarce for expert workflows in domains like CAD, architecture, engineering, finance, and other professional software.\n\n**That’s where we come in:**\n\nWe work with a vetted network of expert contributors to collect high-quality computer-use data across:\n\n* Consumer applications\n* Productivity software\n* Accounting and finance\n* CAD, architecture, engineering, and other expert workflows\n\n\n\n**So far we've:**\n\n* Sold more than 15,000 hours of data to frontier AI labs\n* Open-sourced the [**largest dataset of computer-use screen recordings**](https://x.com/DevvMandal/status/2032104265121140924?s=20)(**150k+ downloads on HuggingFace**)\n* Released the [**largest open gaming computer-use dataset**](https://x.com/DevvMandal/status/2072357115847671990?s=20)\n\n**Our Ask:**\n\nIf you're building computer-use agents and need high-quality training data - or have interesting workflows you'd like collected - we'd love to chat **:)**\n\nBook a meeting with us at Or shoot us an email at [founders@markovstudios.com](mailto:founders@markovstudios.com)",
"url": "https://www.ycombinator.com/launches/SaA-markov-data-for-computer-use-ai",
"votes": 11,
"created_at": "2026-08-11T18:00:00.277Z"
}
]
},
{
"id": 33279,
"name": "Hebbian Robotics",
"slug": "hebbian-robotics",
"former_names": [
"Vanda Labs"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/4e7272f21860060f8aa33bb297af6d18fab5ffdc.png",
"website": "https://hebbianrobotics.com/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Hebbian Robotics builds open source foundational infrastructure for Physical AI to develop robots that extend what humanity can do, for the benefit of the communities they serve.",
"one_liner": "Foundational infrastructure for Physical AI",
"team_size": 2,
"industry": "Industrials",
"subindustry": "Industrials -> Manufacturing and Robotics",
"launched_at": 1786123276,
"tags": [
"Robotics",
"Data Science",
"Data Engineering",
"AI",
"Databases"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2026",
"status": "Active",
"industries": [
"Industrials",
"Manufacturing and Robotics"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/hebbian-robotics",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2026/hebbian-robotics.json",
"year_founded": 2026,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/hebbian-robotics/",
"x_url": "https://x.com/hbr_pbc",
"fb_url": null,
"cb_url": null,
"github_url": "https://github.com/Hebbian-Robotics",
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/4e7272f21860060f8aa33bb297af6d18fab5ffdc.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [
"https://bookface-images.s3.us-west-2.amazonaws.com/attachments/18513ded63751a708b6d42e2a84d2517cb404aaf.png"
],
"primary_partner": {
"name": "Diana Hu",
"url": "https://www.ycombinator.com/people/diana-hu"
},
"founders": [
{
"user_id": 388120,
"full_name": "Brandon Ong",
"title": "Co-Founder",
"founder_bio": "Brandon is the co-founder of Hebbian Robotics, which builds APIs that help robotics data teams verify data quality for model training. He previously built Gigit AI, a Sequoia-backed AI customer experience startup. His research on AI for low-resource languages topped SEA-HELM, an LLM benchmark co-developed with Percy Liang's research group at Stanford. He briefly pursued a PhD in Robotics at Columbia and NTU before starting Hebbian.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ongjjbrandon",
"x_url": "https://x.com/brandon1",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/5b65343ad1d0b482401872b3124da731618a3058.jpg"
},
{
"user_id": 968709,
"full_name": "Kingston Kuan",
"title": "Co-founder",
"founder_bio": "Kingston spent the last few years at Jane Street building systems that scaled to millions of messages per second. He graduated valedictorian from the National University of Singapore (NUS) in Computer Engineering.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/kingston-kuan/",
"x_url": "https://x.com/kstonekuan",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b674a8b80df5cd21ef03f13e6470d6126bc4c333.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 109711,
"title": "Hebbian Robotics - APIs for searching and analyzing Physical AI data at scale",
"tagline": "We enable evaluation of data quality without training a robotics model",
"body": "# \\*\\*\\*\\*\n\n**TLDR;**\n\n* **Hebbian Robotics builds APIs for searching and analyzing Physical AI data at scale**\n* Our APIs enable data providers to get **on-demand signals and metrics** on the quality of their data, without managing infrastructure\n* We help our customers evaluate data quality without training a robotics model\n\n\n\n**Our Ask**\n\n* Buyers want data they can trust. If you're selling egocentric or robot data, **Let’s Chat ([https://calendly.com/brandon-hebbianrobotics/30min](https://calendly.com/brandon-hebbianrobotics/30min)**) and we'll show you how quality signals and metrics help you sell more at higher prices\n* **Check out Pareto ([https://pareto.hebbianrobotics.com/](https://pareto.hebbianrobotics.com/)),** an example of how our APIs can be used\n\n### **Who We Are**\n\n* We’re Brandon and Kingston, we've trained AI models for industrial cleaning robots and built production systems for camera fleets across the globe\n* [**Brandon Ong**](https://bookface.ycombinator.com/user/388120)'s previous AI startup was backed by Sequoia. He did research on AI for low resource languages that topped Stanford’s LLM benchmark, SEA-HELM, and dropped out of his joint PhD in Robotics at Columbia and NTU\n* [**Kingston Kuan**](https://bookface.ycombinator.com/user/968709) spent years at Jane Street building systems that scaled to millions of messages per second. At Verkada, he worked on their core video surveillance platform that processed large scale multimodal data\n\n### **The Problem**\n\n* **High quality data is the bottleneck for unlocking the next frontier of intelligence in robotics**\n* Buyers want **data they can trust** \n* Data providers don’t have the bandwidth to provide signals and metrics about the quality of their data when they are **focused on** **operational excellence** \n* This means that **model developers are forgoing model improvements due to a lack of high quality data**, impeding progress in robotics\n\n### **Our Solution**\n\n* APIs for searching and analyzing Physical AI data at scale that enables providers to get **on-demand signals and metrics on data quality**\n* Buyers demanding per-collector hour limits? **Prove compliance while we stay ahead of the workarounds**\n* Changed standard operating procedures for collection? **Monitor for quality drift and regression**\n* Suspect duplicate samples? **Verify quickly with a single API call**\n* Our APIs enable **evaluation of data quality without training a robotics model, fast iteration cycles for** high quality data collection, and unlock **model improvements** \n\n### **How to reach us**\n\n* We want to support data providers who believe in collecting high quality data in an ethical way\n* To get started, email [**brandon.ong@hebbianrobotics.com**](mailto:brandon.ong@hebbianrobotics.com)",
"url": "https://www.ycombinator.com/launches/SXX-hebbian-robotics-apis-for-searching-and-analyzing-physical-ai-data-at-scale",
"votes": 81,
"created_at": "2026-08-09T03:00:00.116Z"
}
]
},
{
"id": 33310,
"name": "Petrarch",
"slug": "petrarch",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/091a0f9893d5a0f66b65399660fc8041716acd4e.png",
"website": "https://petrarch.co/",
"all_locations": "San Francisco, CA, USA",
"long_description": "Petrarch brings internal company data to frontier labs, starting with manufacturing and industrial companies. We source data including codebases, project files, and payments from bankruptcy courts, then de-identify and prepare the data for model training. \r\n",
"one_liner": "Internal industrial company data for frontier labs",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1782965522,
"tags": [
"Reinforcement Learning",
"B2B",
"Privacy",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2026",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/petrarch",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2026/petrarch.json",
"year_founded": 2026,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/petrarchinc",
"x_url": "https://x.com/petrarchinc?s=11",
"fb_url": null,
"cb_url": "https://www.crunchbase.com/organization/petrarch-e3b1",
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/091a0f9893d5a0f66b65399660fc8041716acd4e.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Vivian Midha Shen",
"url": "https://www.ycombinator.com/people/vivian-midha%20shen"
},
"founders": [
{
"user_id": 3655939,
"full_name": "Ian Lee",
"title": "Founder/CEO",
"founder_bio": "Founder at Petrarch. Previously Fellow at Meridian AI building training data and GTM infrastructure for AI-native Excel in financial services. Technical Advisor at Scale AI, working on quality filtering and annotation for agentic assistants and reasoning models. BA in Applied Mathematics and Psychology from Harvard.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/-ianlee",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/bceb6907c6226831472da7b1d7688785c1fb3c17.jpg"
},
{
"user_id": 2670953,
"full_name": "Samuel Hahn",
"title": "Founder/COO",
"founder_bio": "Founder at Petrarch. Previously led GTM at Magier AI (Techstars '24), building agentic PII-redaction and data-compliance products. Venture analyst at Mainstreet sourcing pre-seed fintech and deeptech. BA in Economics and History from Harvard.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/samuelhahn9/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/c4c5f0acb76bd4a03ee95588c1e5324406ca2dae.jpg"
},
{
"user_id": 3594340,
"full_name": "Sudhish Swain",
"title": "Founder/CTO",
"founder_bio": "Founder at Petrarch. Previously built computer vision software for medical equipment identification deployed in California hospitals as Head of Software Engineering at Clean Sweep Group. Research intern at Brigham and Women's Hospital analyzing spatial transcriptomic cancer datasets. BA Integrative Biology at Harvard.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/sudhish-swain/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/098958191b28eaf5108b38cb0d2768964c348d55.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 105007,
"title": "Petrarch — Unlocking enterprise data for tomorrow's economy",
"tagline": "The market for specialized data locked up in enterprise companies.",
"body": "# The market for specialized data locked up in enterprise companies.\n\n[Petrarch](http://petrarch.co) is unlocking enterprise data for tomorrow's economy.\n\n\n\nFrontier labs scraped the internet dry. Then, labelers contracted subject matter experts to hand-make data. Now demand has shifted towards the bespoke data locked up within industries like construction, manufacturing, and logistics.\n\nPetrarch targets companies with valuable **operational** **data** they haven't monetized, from **legacy** **businesses** and **startups** to companies undergoing **bankruptcy** and **pivots**.\n\nPetrarch **sources** suppliers, **cleans** and **restructures** the datasets, certifies **legal clearance**, and resells to **applied AI startups and labs.** They have already transacted construction plans, autonomous driving recordings, and codebases.\n\nWith experience at Scale and Meridian AI, founders Ian Lee, Samuel Hahn, and Sudhish Swain dropped out of Harvard to unlock the next wave of training data.\n\nIf you need proprietary datasets or think you have something valuable on your hands \\\n(or recently pivoted), reach out at [founders@petrarch.co](mailto:founders@petrarch.co) or visit us at [Petrarch.co](http://Petrarch.co)!",
"url": "https://www.ycombinator.com/launches/RJf-petrarch-unlocking-enterprise-data-for-tomorrow-s-economy",
"votes": 11,
"created_at": "2026-07-13T16:11:02.837Z"
}
]
},
{
"id": 33345,
"name": "CueBench",
"slug": "cuebench",
"former_names": [
"CueBench",
"Snap Poker"
],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/8fc25d9ffc54b20b2ccee87e57733b12a6e8edf1.png",
"website": "https://cuebench.dev",
"all_locations": "San Francisco, CA, USA",
"long_description": "",
"one_liner": "RL post-training for science reasoning and performance engineering",
"team_size": 3,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1786744876,
"tags": [
"Reinforcement Learning",
"Data Engineering"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2026",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/cuebench",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2026/cuebench.json",
"year_founded": 2026,
"city": "San Francisco",
"country": "US",
"linkedin_url": "",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/8fc25d9ffc54b20b2ccee87e57733b12a6e8edf1.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Vivian Midha Shen",
"url": "https://www.ycombinator.com/people/vivian-midha%20shen"
},
"founders": [
{
"user_id": 3732725,
"full_name": "Dillon Mehta",
"title": "Founder/CEO",
"founder_bio": "Founder and CEO at CueBench",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/dillon-mehta-49aa2827b/",
"x_url": "https://x.com/PickleDilll_",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/812fc022db435026c7bee56ba58f916bfd5218ee.jpg"
},
{
"user_id": 3762638,
"full_name": "Neel Gadde",
"title": "Founder/COO",
"founder_bio": "Co-Founder and CRO at CueBench",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/neel-gadde-491880377/",
"x_url": "https://x.com/neelapolitan?s=11",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/d2be7502db72b4faa82985dd5181743eabe8a5aa.jpg"
},
{
"user_id": 3791688,
"full_name": "Rishan Hemrajani",
"title": "Founder",
"founder_bio": "Co-Founder & CTO of CueBench.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/rishan-hemrajani-254bba292",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/e3bd268e04f9551b93d77346c5652657d25a2b69.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 33540,
"name": "Osseus",
"slug": "osseus",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/fd39ca163a2a8ea396a6ec66701926317f9f416c.png",
"website": "https://osseus.ai/",
"all_locations": "London, England, United Kingdom",
"long_description": "In an era of cheap intelligence, the most important application of AI will be to improving human health, globally. Osseus is building the frontier medical AI lab, starting with the clinical datasets, evaluations, and reinforcement learning environments that help AI labs train more capable, aligned, and safe models.",
"one_liner": "The frontier data platform for aligned health and biological AI",
"team_size": 2,
"industry": "B2B",
"subindustry": "B2B",
"launched_at": 1783740069,
"tags": [
"B2B",
"Biotech",
"Healthcare",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2026",
"status": "Active",
"industries": [
"B2B"
],
"regions": [
"United Kingdom",
"Europe"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/osseus",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2026/osseus.json",
"year_founded": 2026,
"city": "London",
"country": "GB",
"linkedin_url": "https://www.linkedin.com/company/osseus-intelligence",
"x_url": "https://x.com/osseusinc",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/fd39ca163a2a8ea396a6ec66701926317f9f416c.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Jared Friedman",
"url": "https://www.ycombinator.com/people/jared-friedman"
},
"founders": [
{
"user_id": 1409413,
"full_name": "Anish Mariathasan",
"title": "Founder/CEO",
"founder_bio": "Co-Founder at Osseus (YC S26). Prev. co-founded a compliance AI startup. ML research at a Harvard-HKU joint lab on computer vision for cancer research. MEng in Biomedical Engineering from Imperial College London, dropped Oxford PhD in AI for Health. Awarded academic scholarships for both.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/anishmariathasan/",
"x_url": "https://x.com/mariathasanish",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/2e6cc631f0d2a1f1b51513c008b98bed931bad1b.jpg"
},
{
"user_id": 1979222,
"full_name": "Ayush Patel",
"title": "Founder/CTO",
"founder_bio": "Co-Founder at Osseus (YC S26). 2x intern at Apple, where he built an agentic QA system. MEng in Computer Science from Imperial College London.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ayush-patel4/",
"x_url": "",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/ccdce4615ca525f275d384024cd3e6eb8abc2e18.jpg"
}
],
"jobs": [],
"news": [],
"launches": []
},
{
"id": 33639,
"name": "Magma",
"slug": "magma",
"former_names": [],
"small_logo_thumb_url": "https://bookface-images.s3.amazonaws.com/small_logos/9b261522e21a27147c25d66eb0b126f8b62e5295.png",
"website": "https://magmahq.ai",
"all_locations": "San Francisco, CA, USA",
"long_description": "We enable companies monetize their agents' traces.",
"one_liner": "Monetize your agent's traces.",
"team_size": 1,
"industry": "B2B",
"subindustry": "B2B -> Infrastructure",
"launched_at": 1786606834,
"tags": [
"Reinforcement Learning",
"Data Engineering",
"AI"
],
"tags_highlighted": [],
"top_company": false,
"isHiring": false,
"nonprofit": false,
"batch": "Summer 2026",
"status": "Active",
"industries": [
"B2B",
"Infrastructure"
],
"regions": [
"United States of America",
"America / Canada"
],
"stage": "Early",
"app_video_public": false,
"demo_day_video_public": false,
"app_answers": null,
"question_answers": null,
"url": "https://www.ycombinator.com/companies/magma",
"api": "https://devasheeshg.github.io/yc-api/batches/summer-2026/magma.json",
"year_founded": 2026,
"city": "San Francisco",
"country": "US",
"linkedin_url": "https://www.linkedin.com/company/magma-hq",
"x_url": "",
"fb_url": null,
"cb_url": null,
"github_url": null,
"logo_url": "https://bookface-images.s3.amazonaws.com/small_logos/9b261522e21a27147c25d66eb0b126f8b62e5295.png",
"app_video_url": null,
"dday_video_url": null,
"company_photos": [],
"primary_partner": {
"name": "Harshita Arora",
"url": "https://www.ycombinator.com/people/harshita-arora"
},
"founders": [
{
"user_id": 3107607,
"full_name": "Ramtin Shahzanian",
"title": "Founder/CEO",
"founder_bio": "failing my way through.",
"is_active": true,
"linkedin_url": "https://www.linkedin.com/in/ramtin-shahzanian/",
"x_url": "https://x.com/42Ramtin",
"avatar_thumb_url": "https://bookface-images.s3.us-west-2.amazonaws.com/avatars/b58098b0fa3c418c52382d092d86f1801136d50d.jpg"
}
],
"jobs": [],
"news": [],
"launches": [
{
"id": 110488,
"title": "Magma - AI labs will pay you to learn from your agent's mistakes",
"tagline": "We enable any company monetize its agents' traces!",
"body": "**TL;DR:** Magma enables companies building AI agents to monetize their data in a few clicks.\n\n\n\n**❌ The problem**\n\nIf a product uses AI agents, every interaction creates valuable data. That could be a user correcting an agent’s mistake, or an agent discovering a new way to complete a workflow. That real-world data currently sits unused, while the best alternative is human annotators inventing hypothetical scenarios.\n\n**✅ What we do**\n\nMagma turns that data into recurring revenue for companies.\n\nCompanies share their agents’ traces in a few clicks. Access is read-only and encrypted, and nothing is shared without approval. Magma anonymizes the data, turns it into complex training environments, and handles licensing to AI labs. Every time the data is licensed, the company gets paid.\n\n**👋 Who I am**\n\nI’ve previously built the first Persian OCR model and legal LLM for my startup in Iran, formulated new transformer-based ML architectures in Oxford, and created a dev tool context management for agents that worked so well I decided to repurpose it to extract training data from traces (now Magma).\n\n\n\n**🧐 But why?**\n\nWe believe no two AI agents on the planet should be corrected for the same mistake. This is why we're building infrastructure to turn the experience of any AI agent into generalizable learning signals to improve any other AI agent.\n\n**🫡 Our ask**\n\nDo you know anyone at a frontier lab looking for RL environments built from real production workflows, or at an enterprise in need of fine-tuning their models on niche tasks? Let us know and we can help: [ramtin@magmahq.ai](mailto:ramtin@magmahq.ai)\n\nAlso, you can start monetizing your agents’ traces at: [magmahq.ai](http://magmahq.ai)",
"url": "https://www.ycombinator.com/launches/Sk4-magma-ai-labs-will-pay-you-to-learn-from-your-agent-s-mistakes",
"votes": 37,
"created_at": "2026-08-14T01:00:00.832Z"
}
]
}
]